 Xenonstack Glossary
XenonStack GlossaryWhat Is Model Compression? Methods Explained
Key takeaway
- Model compression shrinks machine learning models while preserving performance. Compare pruning, quantization, distillation and low-rank decomposition.
Model compression is the set of techniques that reduce the size and complexity of a machine learning model, such as pruning, quantization and distillation, while preserving its performance as far as possible. The goal is a model that needs less memory and compute, so it runs faster and fits on limited hardware.
This page is for machine learning and platform teams. It covers what model compression is, the four main techniques, how to choose between them and how compression relates to AI agents.
What is model compression?
The survey A survey of model compression techniques: past, present, and future in Frontiers in Robotics and AI states the goal as significantly reducing the number of parameters. The aim is to improve inference speed and lower latency while preserving generalisation performance.
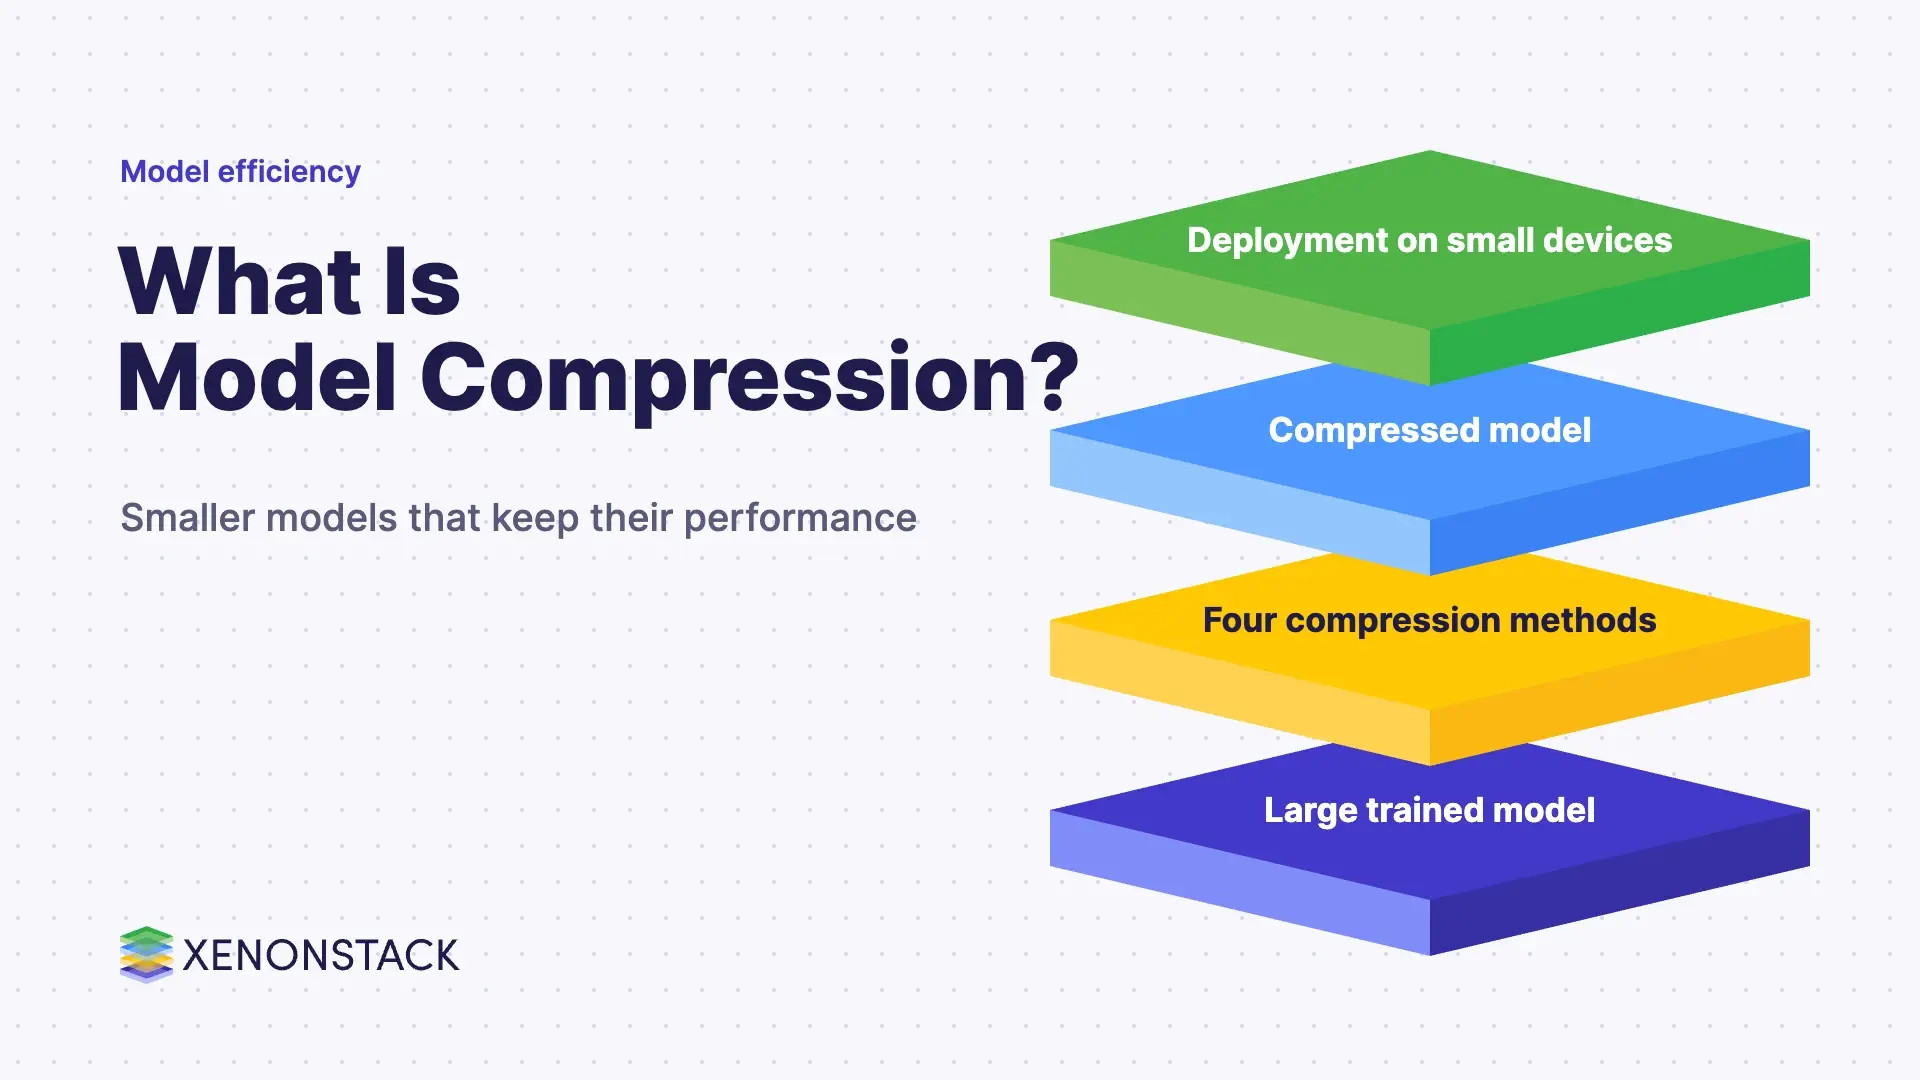
In practice, a team starts with a large trained model and produces a smaller one that fits the memory, compute and response time of the place where it will run, such as a phone, a camera or a shared server.
Why does model compression matter?
- Smaller storage and memory footprint: a compressed model takes less space to store and load.
- Faster inference and lower latency: fewer or cheaper operations per prediction suit real-time services.
- Wider deployment: models can run on resource-constrained and edge devices.
- Lower serving cost: a smaller model can need less hardware for the same traffic.
Each gain has a cost, because compression can reduce accuracy. Always measure the compressed model on your own test data before you ship it.
What are the main model compression techniques?
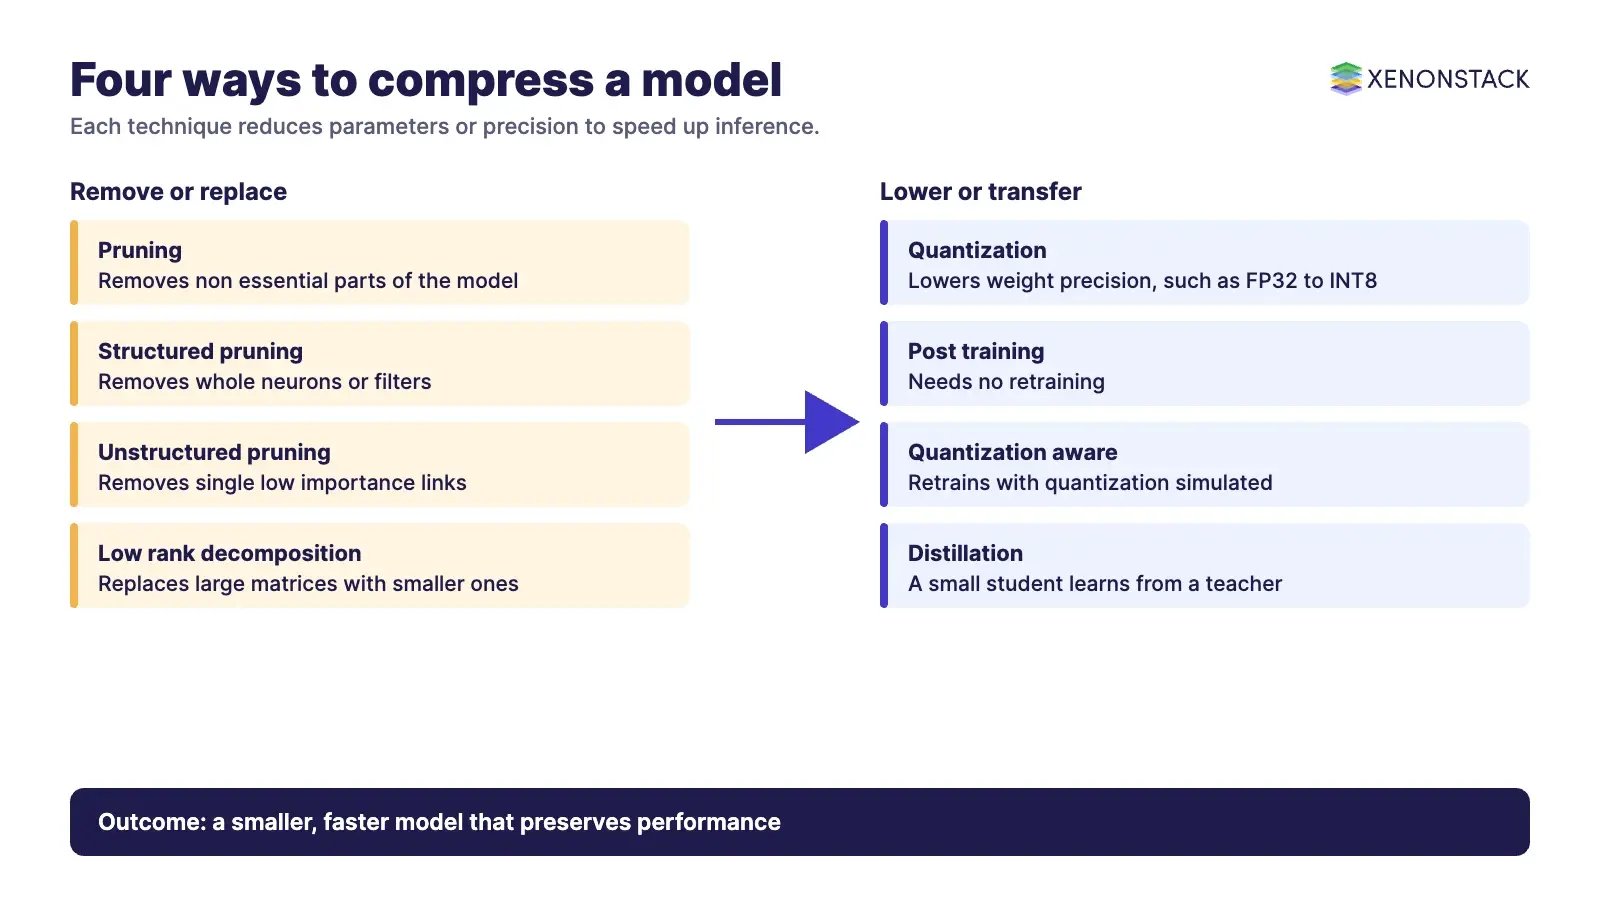
The Frontiers survey groups compression into four categories. The table summarises each in its wording.
| Technique | What it does | Variants named in the survey |
|---|---|---|
| Pruning | Removes non-essential components from over-parameterised models | Unstructured pruning removes individual low-importance connections; structured pruning removes whole neurons or convolutional filters |
| Low-rank decomposition | Uses matrix or tensor decomposition to replace a large weight matrix or kernel with smaller ones that approximate it | Matrix and tensor methods |
| Quantization | Reduces the precision of weights and activations from formats such as FP32 to lower-bit formats such as INT8 or INT4 | Post-training quantization, which needs no retraining, and quantization-aware training |
| Knowledge distillation | Trains a smaller network to learn from the original model and replicate its performance | Black-box distillation uses only the teacher's predictions; white-box distillation also uses its parameters |
How do you choose a technique?
Start from the constraint you must meet. If memory is the limit, quantization and pruning reduce what is stored. If a smaller architecture is acceptable, distillation lets a compact student model learn from a larger teacher. If a single layer is the bottleneck, low-rank decomposition targets it. The techniques can be combined, and each combination needs its own accuracy check.
How does model compression relate to AI agents?
AI agents call models many times inside a workflow, so the speed and cost of each call add up. A compressed model can serve a narrow step, such as classification or extraction, while a larger model handles harder reasoning. Teams building agents on ElixirClaw, the AI agents computing platform from XenonStack, face the same trade-off between model size, speed and accuracy.
What should you do first?
- Write down the target: memory limit, latency budget and minimum accuracy.
- Measure the full-size model on those three numbers as a baseline.
- Try post-training quantization first, because it needs no retraining.
- Move to pruning or distillation only if the target is still missed.
- Re-test on real data and keep the original model available for comparison.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is model compression?
Model compression is a set of techniques that reduce the size and complexity of a machine learning model, mainly by cutting parameters or precision, while preserving its performance as far as possible.
What are the four main compression techniques?
Pruning, low-rank decomposition, quantization and knowledge distillation, as grouped in the Frontiers in Robotics and AI survey.
What is the difference between pruning and quantization?
Pruning removes non-essential connections, neurons or filters. Quantization keeps the structure but lowers the numeric precision of weights and activations.
Does model compression reduce accuracy?
It can. The aim is to preserve generalisation performance, so you should test the compressed model on your own data and compare it with the original.
What is knowledge distillation?
Knowledge distillation trains a smaller network to learn from the original model and replicate its performance.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE