 Xenonstack Glossary
XenonStack GlossaryAdam Optimizer Explained: How Adaptive Moments Work
Key takeaway
- Adam is a first-order optimiser that adapts step sizes from gradient moments. See how it works, how it differs from SGD and AdamW, and where to start.
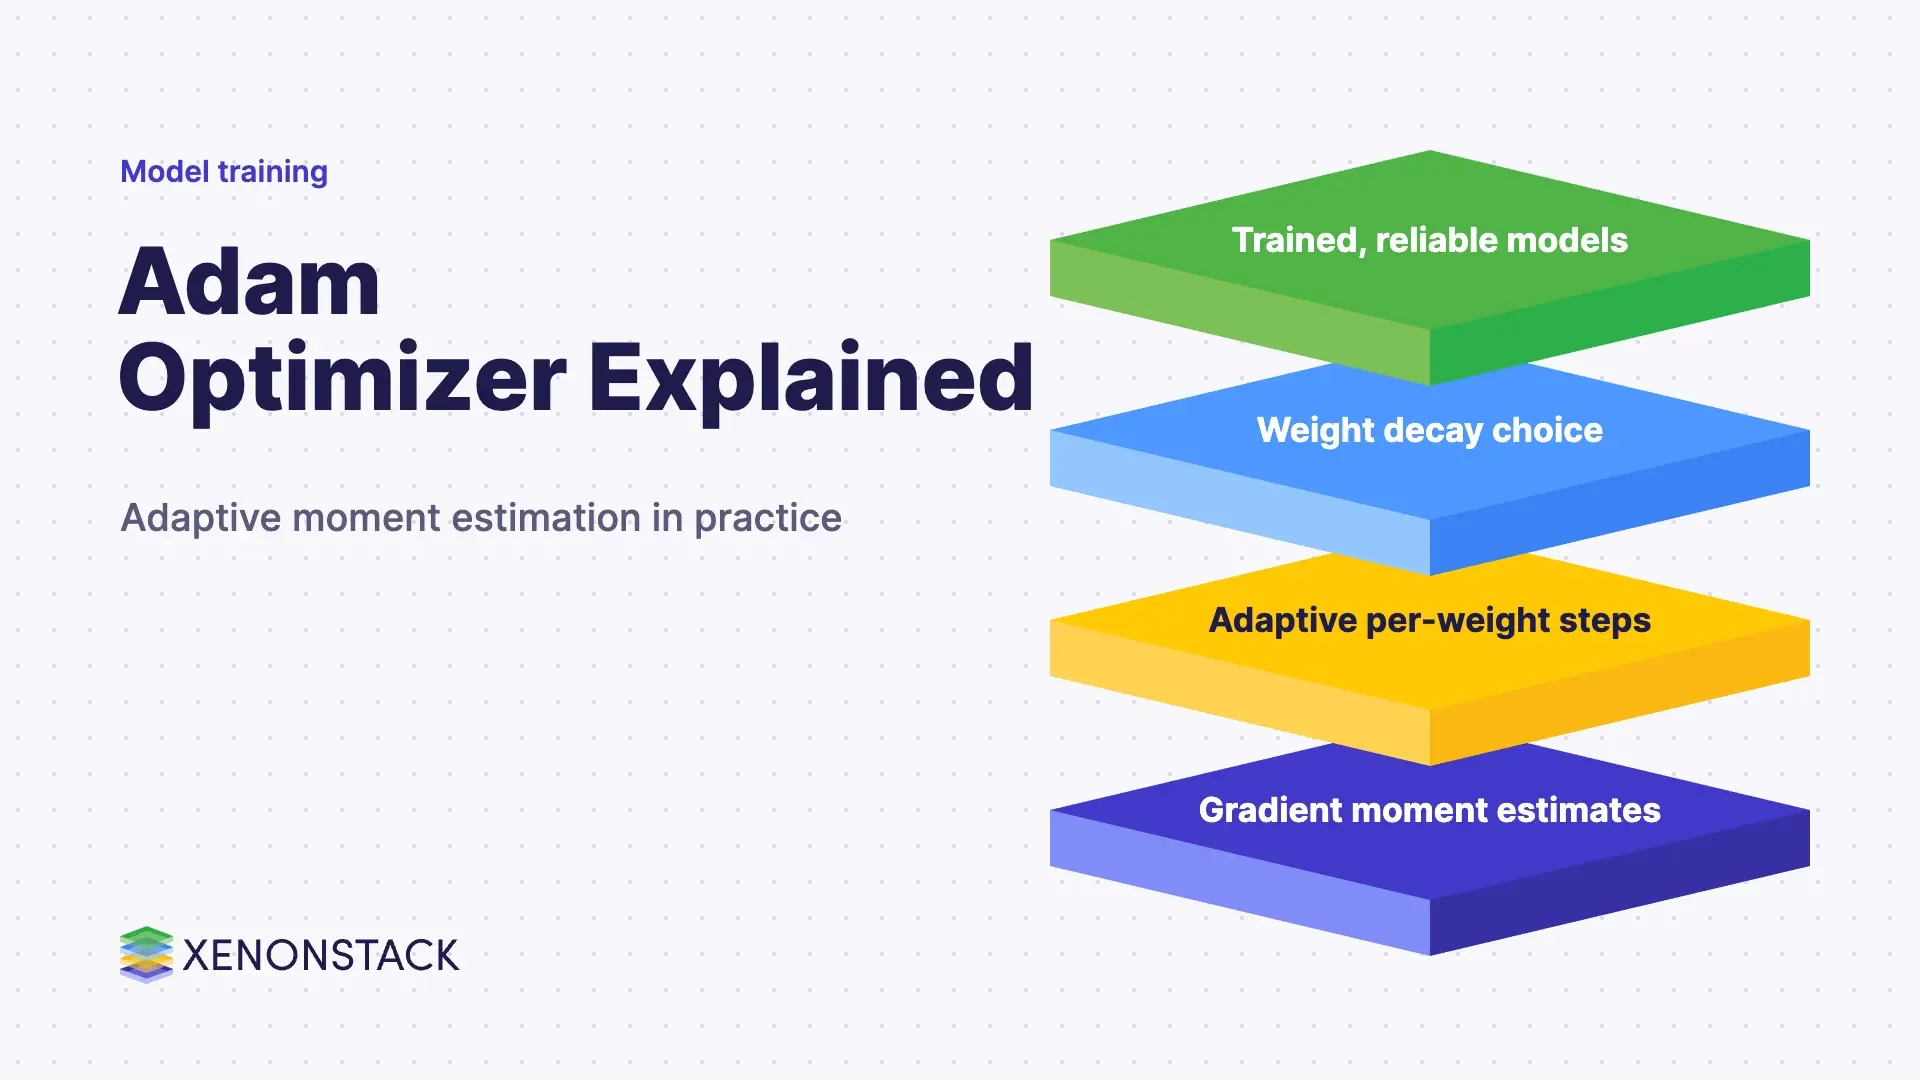
Adam optimization is a first-order, gradient-based method for training models that adapts its step sizes from running estimates of the lower-order moments of the gradients. The name comes from adaptive moment estimation. It is a common default optimiser for deep learning.
This page is for engineers and data leaders who want a clear picture of what Adam does, how it differs from plain stochastic gradient descent and AdamW, and how it fits into the training of AI agents and models.
What is the Adam optimizer?
In their paper Adam: A Method for Stochastic Optimization, Diederik Kingma and Jimmy Ba describe Adam as a method for stochastic objective functions that uses first-order gradients and adapts to them through running moment estimates. The preprint appeared in December 2014 and the work was published at ICLR 2015.
Each weight is updated using its own adaptive step instead of one fixed learning rate. That makes training less sensitive to how the problem is scaled, which is why the method became a common default.
Why does Adam matter for training?
The paper lists the properties that made Adam popular. It is simple to implement, computationally efficient and has modest memory requirements. It is invariant to diagonal rescaling of the gradients, and it suits problems that are large in data or parameters, objectives that change over time, and gradients that are very noisy or sparse.
The authors also state that the hyperparameters have intuitive interpretations and typically need little tuning. The paper adds a convergence analysis with a regret bound, and presents AdaMax, a variant based on the infinity norm. For wider tuning choices, see our entry on hyperparameter tuning.
How does Adam work?
Adam keeps running estimates of the gradient and of its square, which are the lower-order moments the paper refers to. It uses both to set a separate step size for every parameter at every iteration.
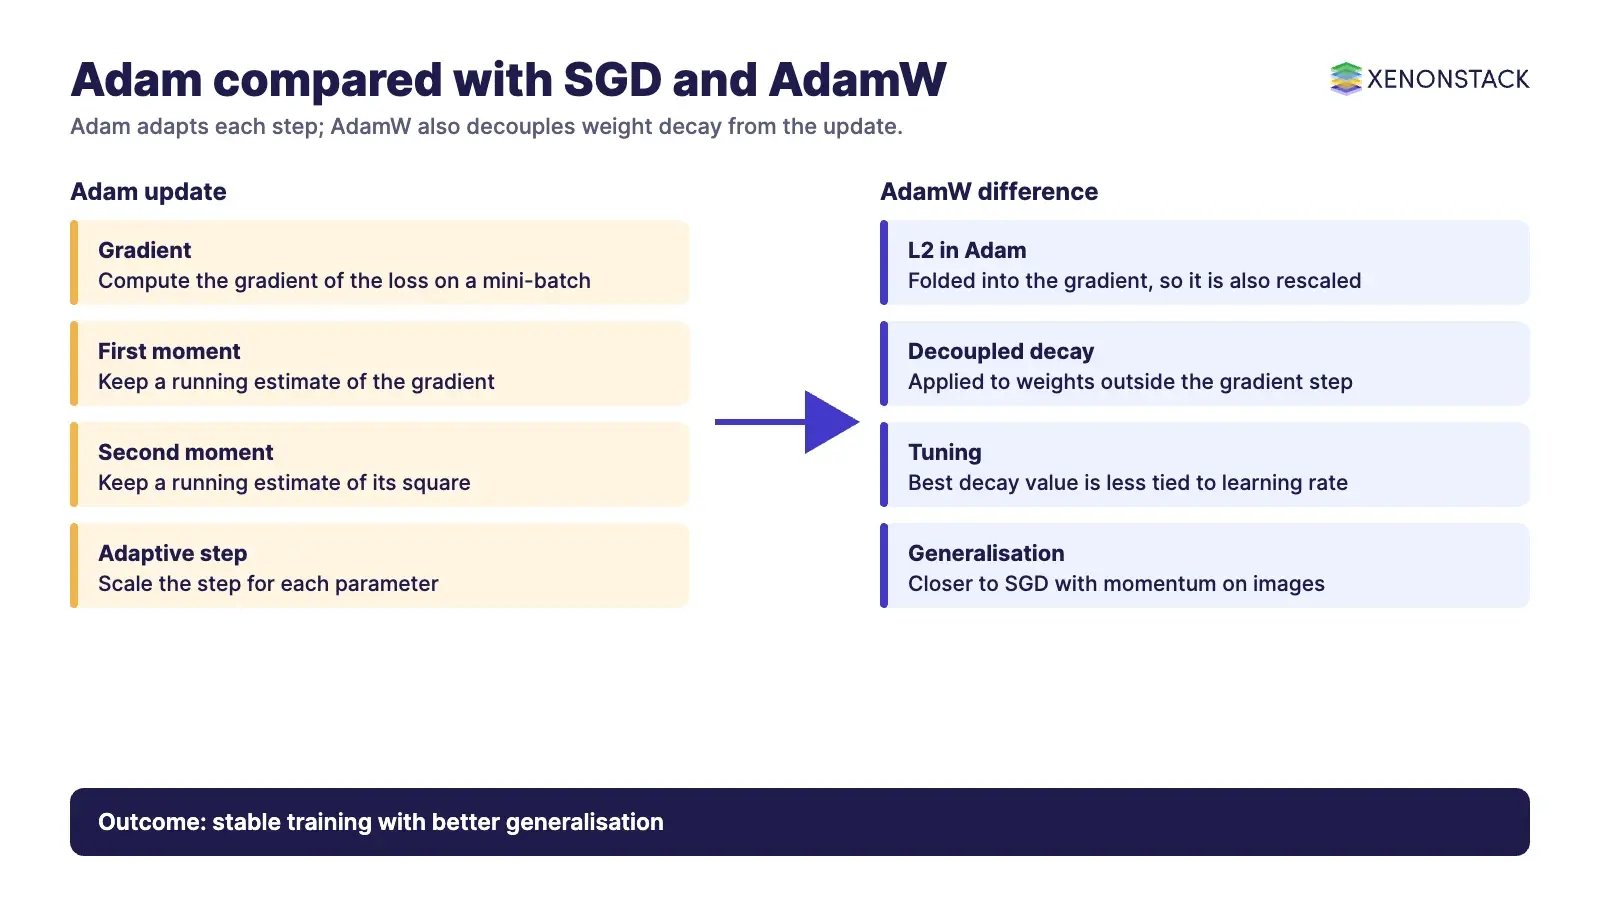
The settings you will meet are the learning rate, two decay rates for the moment estimates and a small constant for numerical stability. Of these, the learning rate is usually the one worth tuning first, and your framework documentation lists the defaults it ships with.
How does Adam differ from SGD and AdamW?
The difference that matters most in practice is regularisation. Decoupled Weight Decay Regularization by Ilya Loshchilov and Frank Hutter explains that for plain SGD, L2 regularisation and weight decay are equivalent, but that this breaks for adaptive methods such as Adam.
| Method | Step size | Weight decay note |
|---|---|---|
| SGD | One learning rate for all weights | L2 regularisation and weight decay are equivalent |
| Adam | Adaptive step per parameter from moment estimates | Common implementations apply L2 and call it weight decay, which the paper says is misleading |
| AdamW | Same adaptive steps as Adam | Weight decay is decoupled from the gradient step; the paper reports a large gain in generalisation, close to SGD with momentum on image classification |
The paper says this decoupling has been adopted by many researchers and is implemented in TensorFlow and PyTorch.
How does Adam relate to AI agents?
Agents are only as reliable as the models behind them, and the optimiser is one of the choices that shapes how those models train. Teams that build and operate agents on ElixirClaw, the AI agents computing platform from XenonStack still need to decide how the underlying models are trained and tuned, and Adam or AdamW is a frequent starting point.
What should you do first when using Adam?
- Start with the default settings from your framework before changing anything.
- Tune the learning rate first and keep a log of each run.
- Use the decoupled weight decay variant when you rely on weight decay.
- Compare against SGD with momentum if final accuracy on image models matters.
- Record the optimiser, settings and data version with every trained model.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What does Adam stand for?
Adam stands for adaptive moment estimation. It is a first-order, gradient-based optimisation method for stochastic objective functions, introduced by Kingma and Ba and published at ICLR 2015.
Why does Adam need little tuning?
The original paper says its hyperparameters have intuitive interpretations and typically need little tuning. The learning rate is still the setting most worth adjusting for a new problem.
What is the difference between Adam and AdamW?
AdamW decouples weight decay from the gradient-based update. Loshchilov and Hutter show that L2 regularisation and weight decay are not equivalent for Adam, and that decoupling them improves generalisation.
When is Adam a good choice?
The paper describes Adam as well suited to problems that are large in data or parameters, to non-stationary objectives and to very noisy or sparse gradients.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE