Agentic AI with Amazon Redshift means software agents that watch incoming data, run governed SQL against the warehouse and trigger actions in business systems, while Redshift supplies the storage, query engine and its own auto-tuning. Redshift is not the agent. It is the analytical store the agent reads from and writes to, so the design question is where the agent sits and what it may do alone.
This guide is for data and analytics leaders. It shows which Redshift features support near-real-time work, where agents add value, what to govern and how to sequence a rollout. For the wider pattern, see our guides to agentic analytics and real-time analytics services on AWS.
Key Takeaways
- Redshift already offers streaming ingestion, zero-ETL integrations, Spectrum, concurrency scaling and automatic table optimisation. Agents orchestrate and act on top of these; they do not replace them.
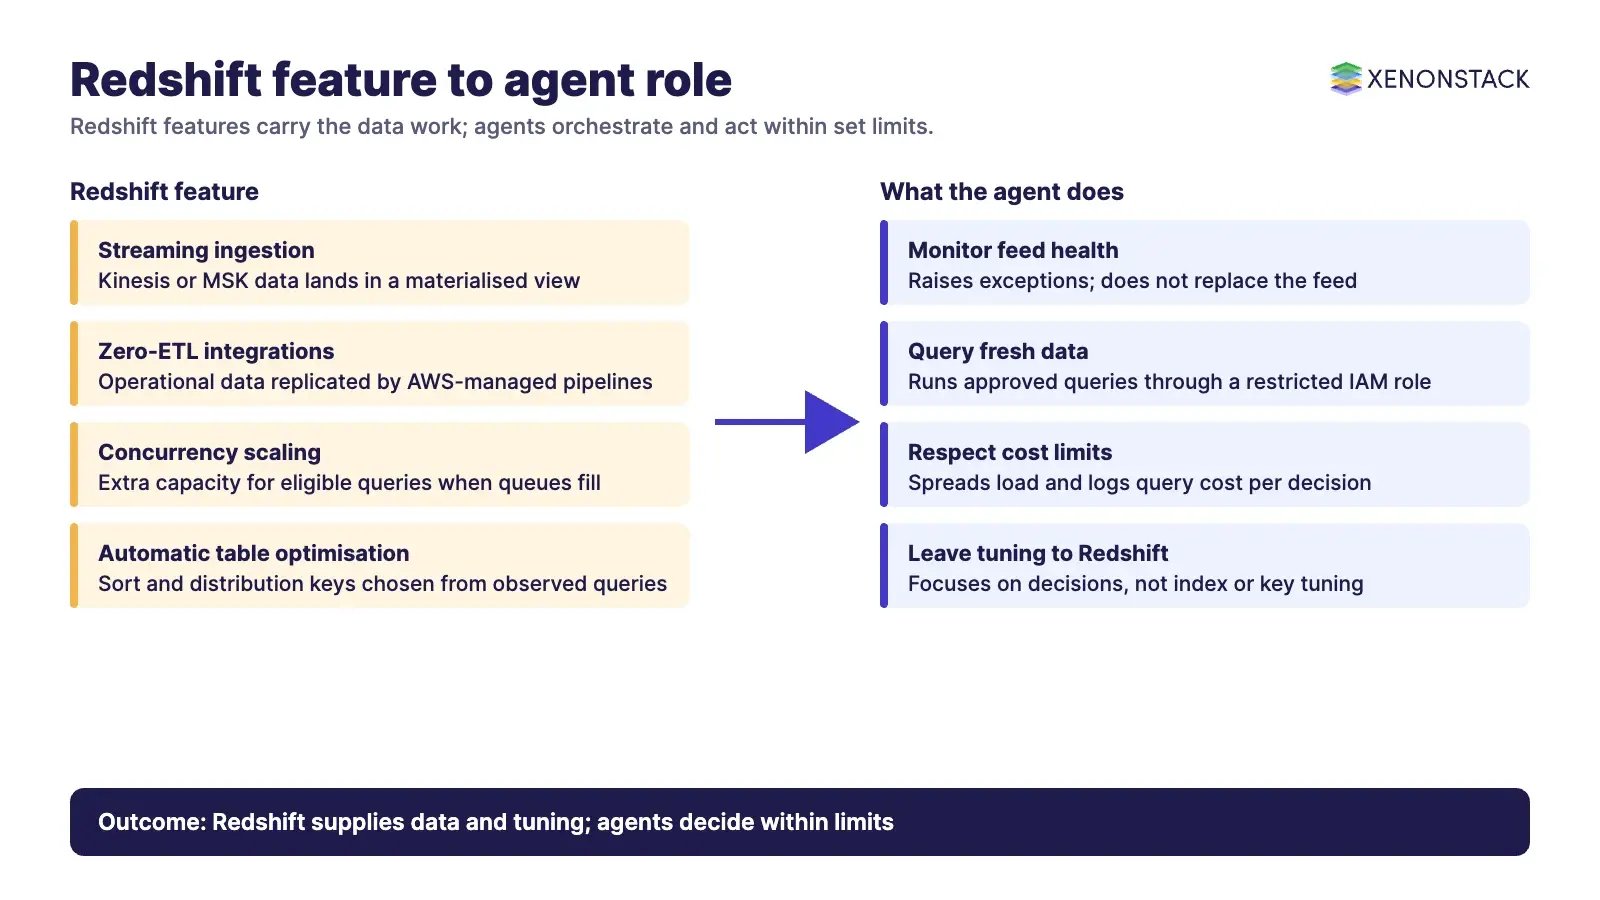
- Redshift has no indexes to tune. Automatic table optimisation applies sort and distribution keys, so agents should not be sold as index tuners.
- Streaming ingestion lands data in a materialised view with near-real-time freshness, not instant freshness, and it has documented limits.
- Give agents read access and narrow write access first, and keep a human approval step for actions that change money, customers or equipment.
What does agentic AI add to Amazon Redshift analytics?
| Dimension | Scheduled analytics | Agentic analytics |
|---|---|---|
| Workflow | Fixed pipelines and dashboards | Agents choose which query or check to run next within set limits |
| Human role | Reviews each report | Approves defined decisions and reviews exceptions |
| Data freshness | Batch loads | Streaming or zero-ETL feeds, so agents see recent data |
| Anomalies | Found in the next report | Flagged when the check runs, with a proposed action |
| Output | Insight | Insight plus a logged action in an operational system |
Which Redshift features support real-time agent workloads?
The AWS pages for Amazon Redshift describe streaming ingestion from Kinesis and MSK, zero-ETL integrations, Redshift Serverless, SQL access to machine learning and an integration with Amazon Bedrock. The same page refers to "autonomous agentic AI workloads" and to the lakehouse in Amazon SageMaker. The table summarises what each feature does and where it stops, from the AWS documentation read on 12 November 2026.
| Feature | What it does | When it fits | Limits to plan for |
|---|---|---|---|
| Streaming ingestion | Reads from Kinesis Data Streams or MSK into a materialised view, with no S3 staging; auto refresh keeps loading as data arrives | Telemetry, clickstream and event feeds | No direct joins on the streaming view; one view per stream; oversized records are skipped |
| Zero-ETL integrations | Replicates transactional data from sources such as Aurora, RDS, DynamoDB and several applications, with AWS managing the pipeline | Operational data needed for analytics without hand-built ETL | No latency figure published on the page; billed across Redshift, the source and AWS Glue |
| Redshift Spectrum | Queries structured and semi-structured files in S3 without loading them | Historical data next to warehouse tables | Check region and Serverless support for your set-up |
| Concurrency scaling | Adds capacity for eligible read and some write queries when queues fill | Unpredictable query spikes from many agents or users | Not all query types qualify; billed for active time |
| Automatic table optimisation | Chooses sort and distribution keys from observed queries | Mixed or changing workloads | Applies to tables set to AUTO; it is Redshift's own feature, not an agent's |
| Redshift ML and Bedrock | Trains models through SageMaker AI from SQL and calls foundation models through Bedrock | Prediction or text tasks near the data | Review how Bedrock handles your data; verify model output |
How should an agent integrate with Redshift?
- Ingest: use streaming ingestion for event streams and zero-ETL for operational databases. Agents monitor the health of these feeds and raise exceptions; they do not need to replace them.
- Prepare: keep transformation logic in versioned SQL, AWS Glue or your existing pipeline tool. An agent can propose a change, but a person should approve changes to shared transformations.
- Query: the agent calls the warehouse through a restricted IAM role and a defined set of queries or views. Redshift's automatic table optimisation handles sort and distribution keys.
- Act: validated results go to ERP, CRM or ticketing systems through an approval step, with each action logged against the query that triggered it.
Our AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights. ElixirData keeps governed context, versioned policy and decision traces in one decision layer above AI agents, which is where the approval and audit record for step four belongs.
What has changed in Redshift that affects agent design?
- Python UDFs: the Redshift ML page states that Amazon Redshift will stop supporting Python UDFs after 30 June 2026, with enforcement in phases. Move agent logic that relied on them to Lambda, SQL or the agent runtime. Concurrency scaling also excludes Python and Lambda UDFs.
- Natural-language SQL: the AWS Redshift page lists Amazon Q generative SQL in the Query Editor. Treat generated SQL as a draft that needs review before an agent runs it unattended.
- Lakehouse naming: AWS now describes a unified lakehouse in Amazon SageMaker alongside Redshift. Check current names when you read older architecture diagrams.
Where does agentic analytics on Redshift fit by industry?
| Industry | Agent task | Data feed | Keep human approval for |
|---|---|---|---|
| Financial services | Flag suspicious transaction patterns | Transaction stream | Blocking a customer or payment |
| Retail | Refresh recommendation signals from clickstream | Event stream plus purchase history | Pricing or offer changes |
| Manufacturing | Raise maintenance requests from sensor anomalies | IoT telemetry | Stopping a line |
| Healthcare | Surface device readings that need clinical review | Device data | Any clinical decision |
What do governance, security and cost look like?
- Access: give each agent its own IAM role with the minimum schemas and views it needs. Zero-ETL integrations have encryption set at the source, the integration and the warehouse, so check all three.
- Model data handling: the AWS page on Redshift ML advises reviewing how Amazon Bedrock handles your data and deciding whether to apply an AI services opt-out policy.
- Cost: concurrency scaling is charged only for the time clusters actively run queries. Streaming views create a consumer per shard or partition, so AWS advises one view per stream to avoid throttling and duplicate ingestion cost.
- Audit: log the query, the result and the action for every agent decision so a reviewer can trace it.
When is this not the right approach?
Do not add agents where data quality is unmeasured, where a nightly batch already meets the business need, or where an action cannot be reversed and no one reviews it. Streaming ingestion gives near-real-time data in the warehouse, and it is not a substitute for a transactional system that must respond in milliseconds.
How should you sequence the rollout?
- Pick one decision with a clear owner, such as flagging duplicate payments for review.
- Connect one feed by streaming or zero-ETL, and measure freshness.
- Run read-only first: the agent proposes, a person approves.
- Add narrow actions with logged approvals and a rollback path.
- Review cost and exceptions monthly before adding another decision.
For governed orchestration of the agents themselves, ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. See also our guide to agentic AI for data management and warehousing and the wider agentic AI overview.
To map one Redshift analytics decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently Asked Questions (FAQs)
What is agentic AI with Amazon Redshift?
It is the use of AI agents that monitor data in Redshift, run governed queries and trigger actions in business systems, with Redshift acting as the analytical store.
Does Redshift support real-time ingestion?
Yes, through streaming ingestion from Kinesis Data Streams and MSK into materialised views, and through zero-ETL integrations for operational databases. AWS describes streaming as low-latency but publishes no specific latency figure.
Can agents tune Redshift with indexes?
Redshift does not rely on indexes. Automatic table optimisation sets sort and distribution keys from observed queries, so agents should focus on orchestration and decisions.
How does Redshift handle spikes in query load?
Concurrency scaling adds capacity for eligible queries when queues fill, and it is billed for the time clusters actively run queries. Some query types and table features are excluded.
What should be governed first?
Start with least-privilege IAM roles, a log of every query and action, and human approval for actions that affect money, customers or equipment.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE