Key takeaway
- Choose GPU, CPU or NPU for computer vision inference by latency, batching, quantisation and cost per inference, with a decision table and 3-5 year outlook.
Use a GPU for computer vision inference when you run large or many models, need high throughput, or can batch requests. Use a CPU when models are small, traffic is light or bursty, the pipeline is mostly pre- and post-processing, or you already own the servers. Use an NPU or other edge accelerator when power, heat, privacy or connectivity rule out a server. In every case, the right answer comes from your latency target, your cost per inference and a benchmark on your own model, not from the chip alone.
What decides GPU vs CPU for computer vision inference?
Inference is the step where a trained model makes predictions on new images or video. It runs every day, for as long as the product lives, so it usually costs more over time than training. Five measures decide the hardware choice.
| Measure | What it means | Why a leader should care |
|---|---|---|
| Latency | Time from frame in to answer out, usually tracked at the 95th or 99th percentile | Sets whether a defect is caught before the part leaves the line, or an alert fires in time |
| Throughput | Images or frames processed per second | Sets how many cameras or requests one server can serve |
| Cost per inference | Hardware, energy, licences and operations divided by useful inferences | The number finance will ask for, and the one that changes most with utilisation |
| Power and footprint | Watts, cooling and space at the site | Often the hard limit at the edge: in a camera, a vehicle or a factory cabinet |
| Accuracy after optimisation | Model quality once it is quantised, pruned or compiled for the target | A faster model that misses defects or misreads labels is a business risk, not a saving |
In short: GPUs give the most throughput for heavy models, but only when kept busy. CPUs are already in every server and often good enough for light models. Edge accelerators give the best performance per watt for supported models, with a narrower software stack.
How do CPUs, GPUs and NPUs handle a vision inference pipeline?
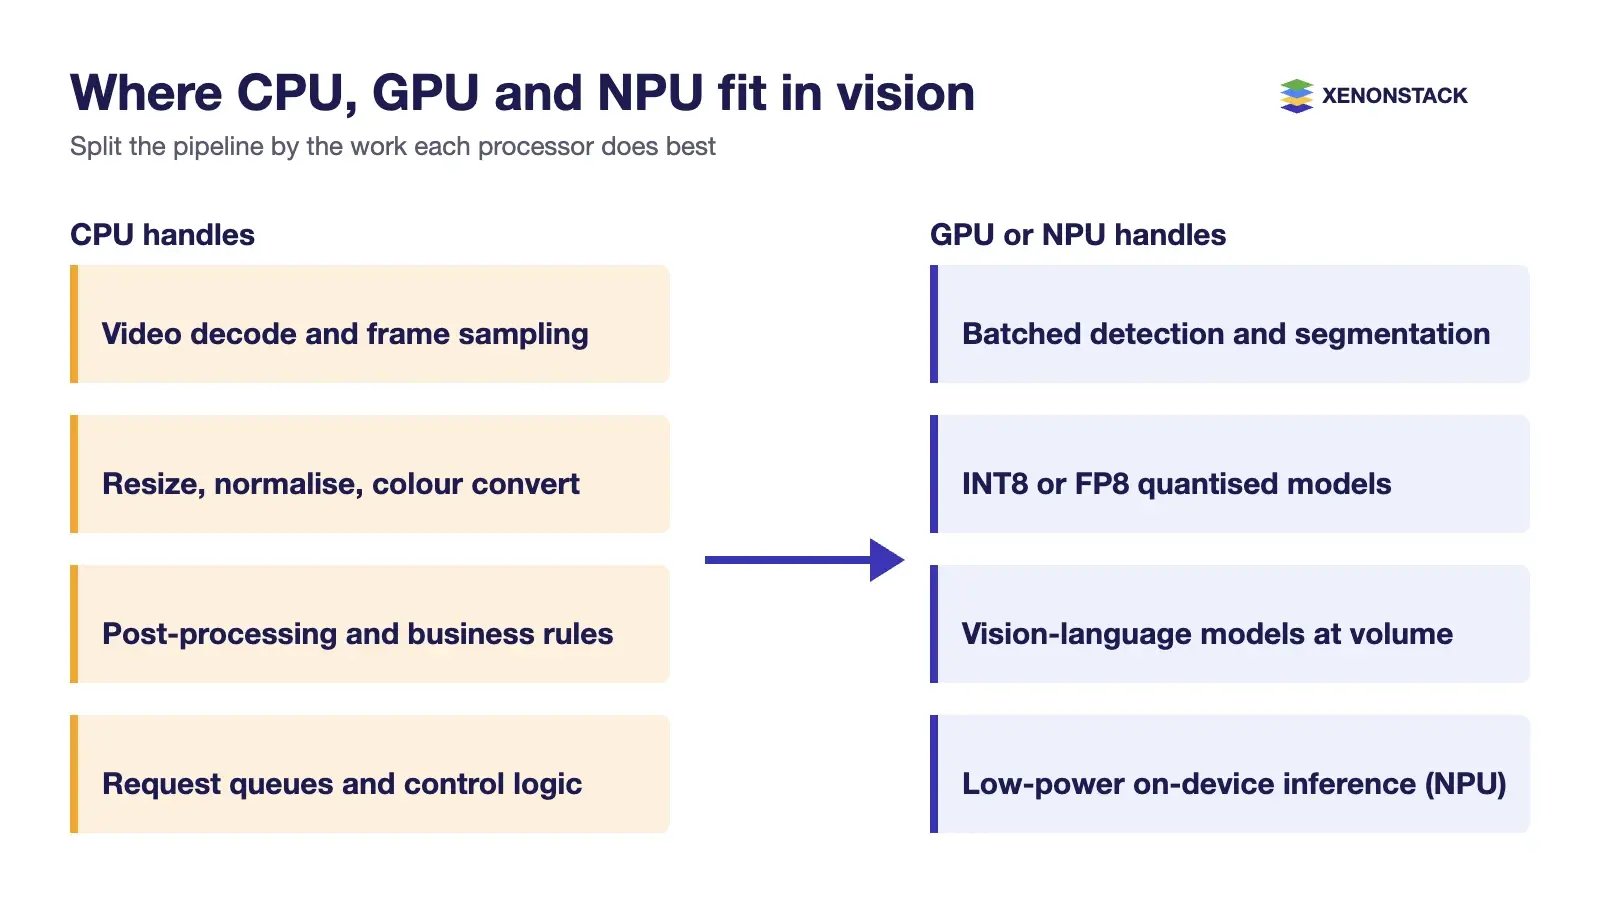
A vision pipeline is more than the model. Most production pipelines have five layers, and each one has a natural home.
| Layer | What happens | Typical home | Where it breaks |
|---|---|---|---|
| Capture and decode | Camera streams, video decode, frame sampling | CPU, or the media engine on a GPU or system-on-chip | Decoding many high-resolution streams can saturate the CPU before the model runs |
| Pre-processing | Resize, crop, normalise, colour conversion | CPU (OpenCV, NumPy) or GPU for high volumes | Copying frames between CPU and GPU memory adds latency |
| Model execution | Detection, segmentation, classification, vision-language models | GPU for heavy or batched models; CPU for small ones; NPU at the edge | Unsupported layers fall back to a slower device |
| Post-processing | Non-maximum suppression, tracking, business rules | CPU, sometimes GPU | Easily ignored in benchmarks, but it adds real latency |
| Serving and control | Request queues, batching, routing, monitoring | CPU, with an inference server such as NVIDIA Triton | Poor batching settings waste the accelerator or break the latency budget |
CPUs
CPUs have a small number of powerful cores, large caches and direct access to system memory. They suit control logic, pre- and post-processing, and small or sparse models. Toolkits such as Intel OpenVINO and ONNX Runtime use their int8 instructions for quantised models.
GPUs
GPUs have thousands of simpler cores and high-bandwidth memory, which suits the matrix maths in convolutions and attention. The catch is data movement and utilisation: a GPU serving one small image at a time is often idle. NVIDIA TensorRT compiles a model for a specific GPU. Its documentation says the builder removes dead computations, folds constants and combines operations, then times different kernel implementations to pick the fastest. By default an engine is tied to the TensorRT version and GPU it was built on, so plan to rebuild when either changes.
NPUs and other edge accelerators
Neural processing units (NPUs) and other application-specific chips run common neural network operations at low power. OpenVINO can split a model across CPU, GPU and NPU. These chips give the best performance per watt when your model's layers are supported. When they are not, those layers run elsewhere, and the gain can disappear.
For the trade-offs between running vision on site and in the cloud, see our guide to cloud vs edge AI hardware for vision workloads.
Which hardware should you choose for which vision workload?
Use this table as a starting point. Confirm the choice with a benchmark on your own model, data and latency target.
| Factor | Choose CPU when… | Choose GPU when… | Choose NPU / edge accelerator when… |
|---|---|---|---|
| Model size | Small classifiers or lightweight detectors | Large detectors, segmentation, vision transformers, vision-language models | Compact models whose layers the accelerator supports |
| Traffic pattern | Light, bursty or occasional requests | Steady, high volume that keeps the device busy | A fixed number of local cameras or sensors |
| Batching | Batch size of one is acceptable | Requests can be grouped within the latency budget | Single-stream, frame-by-frame processing |
| Quantisation | INT8 on CPUs with int8 instructions | FP16, INT8 or FP8 through TensorRT on supported GPUs | Often required: INT8 or lower for the target chip |
| Latency | Tens of milliseconds are acceptable | Low latency at high throughput | Low, predictable latency without a network round trip |
| Cost per inference | Lowest when servers already exist and load is light | Lowest when utilisation is high | Lowest when bandwidth, cloud fees or power dominate |
| Power and site | Data centre or existing edge server | Data centre or a powered edge server | Cameras, vehicles, robots, cabinets with tight power limits |
| Data rules | Data may leave the site | Data may leave the site, or a GPU sits on site | Images must stay on the device |
Many teams end up with a hybrid: CPUs for decode and business rules, a GPU or NPU for the model, and a central GPU cluster for re-processing and model updates. An agentic platform such as NexaStack, an "Agentic Operating Platform for Physical AI" that runs on-premises, in the cloud or hybrid, can host that split. For a production example, see real-time object detection at the edge.
How do batching and quantisation change the answer?
The same model can be several times faster or slower on the same hardware, depending on how it is served and compiled. Batching and quantisation are the two largest levers.
Batching
Batching groups several images into one model call so the accelerator does more work per pass. The NVIDIA Triton dynamic batcher does this on the server. By default it adds no delay. You can set a maximum queue delay so it waits briefly to fill a batch. Larger batches and longer delays raise throughput but add latency. Triton's guidance is to raise the delay step by step until the latency budget is exceeded, and to measure the effect. For a single camera that needs an answer per frame, batching may not help at all.
Quantisation
Quantisation stores weights and activations in fewer bits, such as INT8 instead of FP32. It cuts memory traffic and uses faster maths units, but it is not free.
- Post-training quantisation (PTQ) needs a representative calibration set and no retraining. NVIDIA's TensorRT documentation notes it may reduce accuracy for complex models or sensitive layers.
- Quantisation-aware training (QAT) simulates low precision during training. It usually recovers more accuracy, but needs the training data and more time.
- Explicit quantisation with quantise and dequantise (Q/DQ) nodes is now the recommended path in TensorRT; implicit INT8 quantisation is deprecated. TensorRT also supports FP8 and FP4 with explicit Q/DQ on supported GPUs.
- ONNX Runtime recommends static quantisation for CNNs and dynamic quantisation for transformer models. Its documentation warns that older processors without int8 instructions may run a quantised model slower, not faster.
- OpenVINO offers post-training quantisation through its Neural Network Compression Framework, including a variant with accuracy control.
The rule for leaders is simple: no quantised model goes live until it has passed the same accuracy tests as the original, on your own images. Portability also matters. ONNX Runtime execution providers let one exported model run on CUDA, TensorRT, OpenVINO, Qualcomm QNN, DirectML or CoreML, falling back to the CPU for any node the chosen provider cannot handle. Check how much of the graph actually lands on the accelerator.
How should you calculate cost per inference and benchmark fairly?
Cost per inference is total cost over a period divided by the useful inferences in that period. Total cost includes the hardware (bought or rented), energy and cooling, software licences, and the engineering time to build, tune and run the stack. The figure that moves it most is utilisation. A GPU that is busy most of the day can have a lower cost per inference than a CPU fleet. The same GPU running at low load usually costs more. Work out the number for your real traffic pattern, including peaks and quiet hours.
Measure throughput while p95 or p99 latency stays inside the budget, time the whole pipeline rather than the model call alone, use watts at the wall under real load, and compare accuracy after quantisation, not before.
What does MLPerf tell you?
MLPerf Inference from MLCommons is the most widely used public benchmark for inference hardware. It tests four scenarios: single stream, multiple stream, server and offline. It also has an optional power track. The April 2026 round, MLPerf Inference v6.0, added an edge object-detection test based on YOLOv11 Large and a vision-language model benchmark. Use MLPerf to shortlist hardware and see which software stacks are mature, not as the final answer: submitters tune heavily, and your model and pre-processing will differ. Run the same scenarios on your own pipeline before you buy.
What governance and risk controls apply to vision inference?
Hardware choices change model behaviour. Quantisation, compilation and a switch from GPU to NPU can each shift accuracy, so they need the same change control as a new model.
- Version everything that changes outputs: model weights, quantisation settings, compiler and runtime versions, and the hardware target.
- Re-validate on every change against a fixed test set from real cameras.
- Keep a decision trace: when a vision result triggers an action, such as rejecting a part or raising an alert, record which model and settings produced it.
- Check regulation: the EU AI Act lists biometrics among high-risk areas. Under the 2026 Digital Omnibus amendment, obligations for stand-alone high-risk systems are now due from 2 December 2027, and for high-risk AI built into regulated products from 2 August 2028. Confirm with your legal team which of your uses are in scope.
When vision outputs feed agents that take action, ElixirData provides governed context, versioned policy and decision traces in one decision layer above the agents, so each action can be explained later.
What will change in GPU vs CPU vision inference over the next 3 to 5 years?
The sources below point in a clear direction. Treat the timing as indicative, not certain.
| Trend | Evidence | What it means for your choice |
|---|---|---|
| Inference becomes the main AI workload | Deloitte's 2026 TMT Predictions expect inference to be two-thirds of AI compute by 2026, and most of it to stay in data centres | Cost per inference, not training cost, will drive hardware budgets; data-centre GPUs remain central |
| NPUs become standard in client devices | Gartner forecasts AI PCs at about 55% of PCs in 2026 and says they will become the norm by 2029 | Light vision tasks can move onto laptops and workstations already in the estate |
| Edge spending keeps growing | IDC expects edge computing spending to reach about $380 billion by 2028, with AI among the fastest-growing segments | More vision inference will run on site; plan for fleets of mixed edge devices |
| Lower precision becomes normal | TensorRT now supports FP8 and FP4 alongside INT8 on supported GPUs | Quantisation moves from optional tuning to a default step, so accuracy testing must be routine |
| Benchmarks shift to modern vision and multimodal models | MLPerf v6.0 added YOLOv11-based edge detection and a vision-language model test; v5.1 saw the first heterogeneous system that balanced load across accelerator types | Compare hardware on current models, and expect pipelines that mix accelerators |
Our view: the question will move from "GPU or CPU?" to "which part of the pipeline runs where?". Expect one model to be compiled for several targets, with a scheduler choosing the device by cost, latency and data rules. Portable models (ONNX and standard runtimes) keep that option open.
How do you adopt this, and what should you measure?
- Set the target. Agree the p95 latency, frames per second, accuracy floor and cost ceiling with the business owner.
- Profile the whole pipeline and fix the largest bottleneck first.
- Export once, test many targets with ONNX Runtime, OpenVINO or TensorRT.
- Quantise and re-validate. Try INT8 (and FP8 where supported). Ship only if accuracy holds on your test set.
- Tune serving. Set batch size and queue delay against the latency budget.
- Run a pilot on real traffic for at least one full business cycle, then compute cost per inference.
- Operate and watch drift. Track latency, throughput, utilisation, energy and accuracy. An observability agent such as AgentSRE can help with incident response across the fleet.
For a worked factory example, see computer vision for automated assembly line inspections.
When is a GPU not the answer?
- Low or bursty traffic. An idle GPU still costs money. Quantised models on existing CPUs may meet the target at lower cost.
- The bottleneck is elsewhere. If decode, pre-processing or the network dominate latency, a faster model device changes little.
- Tight power or space. In cameras, drones and vehicles, an NPU or other edge accelerator is often the only option.
- The model is the problem. A smaller or better-designed model can beat any hardware upgrade. See our guide on when neural architecture search pays off, and on running computer vision on the edge.
Equally, a CPU is not the answer when you serve large detectors or vision-language models at high volume, or when you need low latency across many streams at once. Then GPUs, used well, are usually cheaper per inference.
To map one decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
Is a GPU always faster than a CPU for computer vision inference?
No. A GPU gives the most throughput for large models when it is kept busy and requests can be batched. For small models, light or bursty traffic, or a batch size of one, a quantised model on a modern CPU can meet the latency target at lower cost.
When should I use an NPU or edge accelerator instead of a GPU?
Use an NPU or other edge accelerator when power, heat, space, privacy or connectivity rule out a server, and when your model's layers are supported by the chip. Unsupported layers fall back to the CPU or GPU and can remove the gain.
How does batching affect latency and throughput?
Batching groups several images into one model call. Larger batches and longer queue delays raise throughput but add latency. NVIDIA Triton's guidance is to increase the delay step by step until the latency budget is exceeded.
Does INT8 quantisation reduce accuracy?
It can. Post-training quantisation needs a representative calibration set and may reduce accuracy for complex models or sensitive layers. Quantisation-aware training usually recovers more accuracy. Always re-test the quantised model on your own images before going live.
How do I calculate cost per inference?
Divide total cost over a period, including hardware, energy and cooling, licences and engineering time, by the useful inferences in that period. Utilisation moves the result most, so use your real traffic pattern, not peak load.
Can I use MLPerf results to choose hardware?
Use MLPerf Inference to shortlist hardware and see which software stacks are mature. Its scenarios are single stream, multiple stream, server and offline. Then benchmark your own model and pipeline, because submissions are heavily tuned.
What will change in vision inference hardware over the next few years?
Deloitte expects inference to be two-thirds of AI compute by 2026, Gartner expects AI PCs with NPUs to be the norm by 2029, and lower precisions such as FP8 and FP4 are now supported in TensorRT. Expect pipelines that mix CPUs, GPUs and NPUs.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE