Key takeaway
- A convolutional neural network uses filters, pooling and fully connected layers to classify images. See how CNNs work, train, and where they are used.
A convolutional neural network (CNN) is a type of neural network that uses small learnable filters to find local patterns in grid-like data such as images, and then uses those patterns to classify what it sees. It is the standard starting point for image classification and object recognition.
This guide is for engineers, data scientists and technical leaders who want to understand how a CNN is built and trained, what each layer does, where it is used and where it struggles. It starts from the basic neural network and ends with practical steps. It sits alongside our guides to deep learning, machine learning and neural networks and capsule networks.
What is a neural network before it becomes convolutional?
An artificial neural network has an input layer, one or more hidden layers and an output layer. The input layer receives the data. Each neuron in a hidden layer applies a weight and an activation function, and the output layer produces the result. The network is defined by the weights of its neurons, a learning parameter that controls how weights are updated, and the activation function that transforms each neuron's level.
A feed-forward network passes values in one direction, and a multilayer version is trained with backpropagation. A CNN is a class of feed-forward network. Models like these can be exchanged between tools through formats such as Open Neural Network Exchange, and they are often built into wider virtual network functions and services.
What is a convolutional neural network and how does it work?
The Stanford CS231n notes on convolutional networks explain the design. Instead of connecting every neuron to the whole input, each neuron is connected to only a local region of the input volume. A filter, also called a kernel, is a small set of learnable weights that slides across the input. Each filter produces a two-dimensional activation map, and the maps are stacked to form the output.
Three settings control the output size. The number of filters sets the output depth, the stride sets how far the filter moves each step, and padding adds zeros around the border so you can control the spatial size. The notes also describe parameter sharing: all neurons in one depth slice use the same weights and bias, based on the idea that a feature useful at one position is likely useful at others. This greatly reduces the number of parameters.
What do the layers of a CNN do?
| Layer | What it does | Learnable parameters |
|---|---|---|
| Convolutional | Computes dot products between filters and local regions of the input to produce feature maps. Early layers pick up simple features such as edges, and deeper layers combine them. | Yes, the filter weights |
| Pooling | Downsamples each depth slice to shrink spatial size and control overfitting. Max pooling keeps the largest value in a region, average pooling keeps the mean. | No |
| Fully connected | Connects every neuron to all activations of the previous layer. Usually the last layer, it classifies the extracted features and often outputs class scores. | Yes |
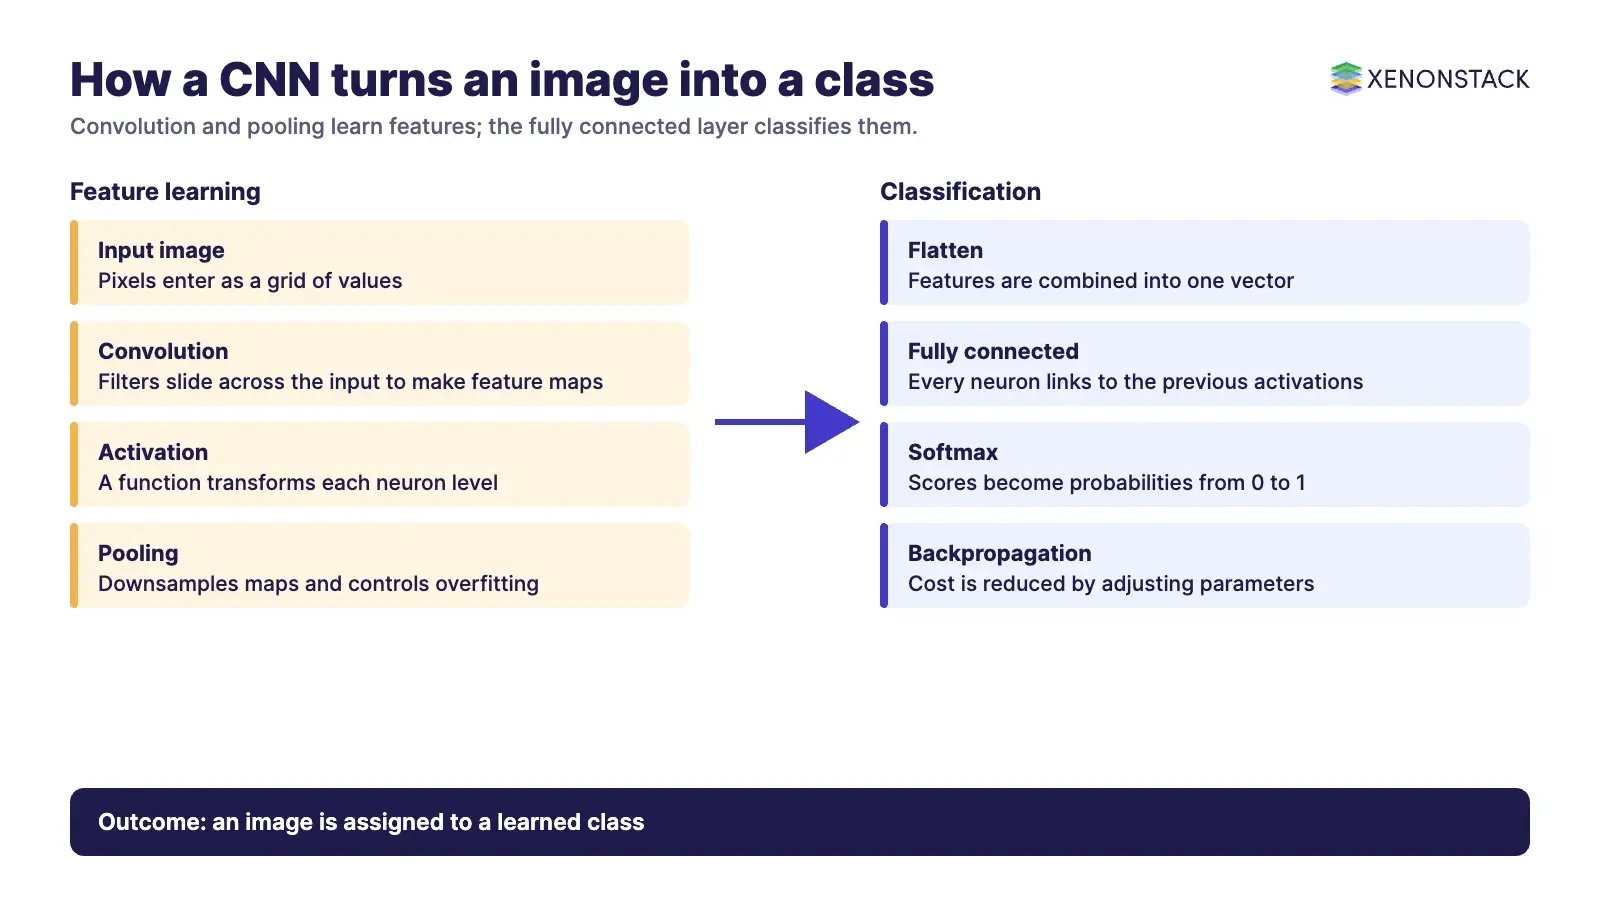
The IBM overview of CNNs describes the same three layers and adds that a softmax function is typically used in the final layer to output probabilities between 0 and 1. In short, the convolutional and pooling layers learn features, and the fully connected layer classifies them.
How is a CNN trained?
Training starts from random parameters. You give the network labelled examples, observe the activation of the output neurons, and compare them with the expected result. A cost function measures how wrong the network was. The network then adjusts its parameters from the output layer back towards the input layer, which is backpropagation, and gradient descent indicates how to change each parameter to reduce the cost. Repeating this over many batches and epochs teaches the network to classify examples correctly.
For a simple task such as deciding whether an image contains a cat, the input layer holds the image, the convolutional and pooling layers extract features, and the output layer has one unit per class. Good results depend on labelled data that matches the images the model will meet later. See our artificial intelligence services page for how teams approach reproducible model training.
Where are CNNs used, and what are their limits?
IBM gives examples across industries: suggesting who appears in a posted photo, helping radiologists spot tumours in scans, visual search in retail, and lane line detection in cars. Well-known CNN families include AlexNet, VGG and YOLO, which build on the same layer ideas.
IBM also lists limits. CNNs can be computationally demanding and may need graphical processing units to train, and pooling discards a lot of information even though it reduces complexity and the risk of overfitting. Choosing the architecture and tuning its free parameters also takes time and experimentation.
How do AI agents change the way CNNs are used?
When a CNN sits inside an AI agent, its output becomes an input to a decision, such as flagging a defect or routing a case. That makes model version, confidence and the action it triggers things you need to track. Running the model reliably in production also calls for inference infrastructure. The NexaStack page describes XenonStack's inference infrastructure for edge, vision and robotics workloads.
What should you do first?
- Define the visual task and the classes the model must tell apart.
- Collect labelled images that match real conditions, then split them for training and testing.
- Start from a small convolutional, pooling and fully connected stack, and measure it.
- Track cost and accuracy during training, and watch for overfitting.
- Decide where the model will run, and plan versioning before agents rely on it.
To map one decision your agents make from visual data, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is a filter in a CNN?
A filter, or kernel, is a small set of learnable weights that slides across the input and produces a two-dimensional activation map.
What does a pooling layer do?
It downsamples each depth slice to shrink the spatial size and control overfitting. Max pooling keeps the largest value in each region and average pooling keeps the mean.
Why do CNNs use fewer parameters than fully connected networks?
Each neuron connects only to a local region, and neurons in a depth slice share the same weights and bias.
How is a CNN trained?
It starts from random parameters, measures error with a cost function, and adjusts parameters through backpropagation and gradient descent.
What are the main limits of CNNs?
They can be computationally demanding, often needing GPUs to train, and pooling discards a lot of information.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE