Key takeaway
- Big data architecture explained: the layers, lambda versus kappa, lakehouse and data mesh, AI-ready design and what to do first for enterprise leaders.
Big data architecture is the design that decides how an organisation collects, stores, processes, governs and serves data that is too large, too fast or too varied for a traditional database. It covers the path from source systems to the dashboards, applications and AI models that use the data, and the controls that keep that path secure and affordable.
This guide is for data and technology leaders who need to choose a reference pattern. It covers the layers, how lambda and kappa differ, where the lakehouse and data mesh fit, how AI agents change the design, and what to do first. For how data moves between layers, see our guides to data pipeline architecture and data orchestration and data ingestion.
What are the layers of a big data architecture?
Microsoft's big data architecture guide says most architectures include "some or all" of eight components. The guide recommends considering one when you must store and process data "in volumes that are too large for a traditional database", transform unstructured data for analysis, or process unbounded streams in real time or with low latency.
| Component | What the guide says it does | Decision for leaders |
|---|---|---|
| Data sources | Application data stores, static files and real-time sources such as IoT devices | Which system is authoritative for each business entity? |
| Data storage | A distributed file store for high volumes of large files, often called a data lake | Do you keep data in open formats you control? |
| Batch processing | Long-running jobs that filter, aggregate and prepare data | What can run on a schedule? |
| Real-time ingestion | Captures messages and acts as a buffer for scale-out processing and reliable delivery | Which use cases truly need real time? |
| Stream processing | Filters, aggregates and prepares streaming data for analysis | How much logic runs continuously? |
| Analytical data store | Serves prepared data in a structured format that analytical tools can query | Which engines may query it? |
| Analytics and reporting | Provides insight through analysis and reporting | Which outcomes justify the platform? |
| Orchestration | Automates repeated processing workflows | How are failures and freshness detected? |
Governance cuts across all of these. Decide who owns each dataset, how access is granted and reviewed, and how quality is checked, as covered in our guide to data veracity. To build these layers on your own stack, see our big data infrastructure services.
Lambda or kappa: which reference pattern fits?
The Microsoft guide describes lambda as two paths for data flow: a batch layer (cold path) that stores all incoming data in raw form, and a speed layer (hot path) that analyses data in real time, "designed for low latency, at the expense of accuracy". Its stated drawback is complexity: "Processing logic appears in two different places", using different frameworks, which "leads to duplicate computation logic".
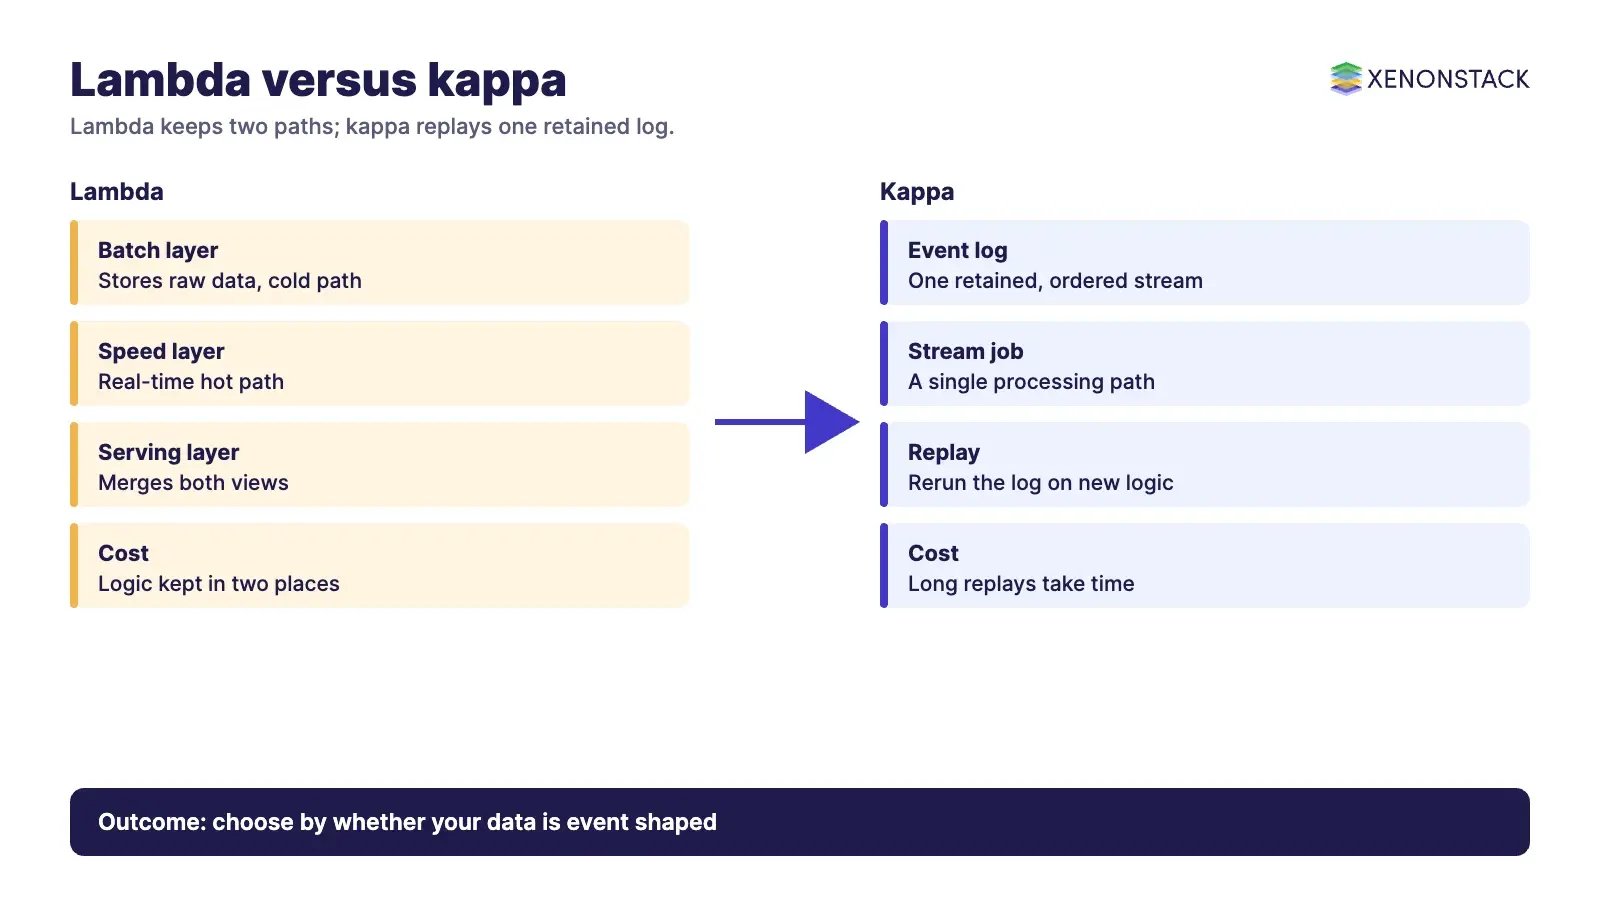
Jay Kreps argued in 2014, in Questioning the Lambda Architecture, that keeping the same code correct in two complex distributed systems is hard. His alternative is to retain the full input log in a system such as Kafka. When the code changes, you start a second instance of the stream job from the beginning of the log, write to a new table, and switch over once it catches up. He suggested calling it the Kappa Architecture.
| Pattern | How it works | When it fits | Watch for |
|---|---|---|---|
| Lambda | Separate batch and speed paths, results merged for queries | An existing batch estate must stay and a few use cases need low-latency views | The same logic maintained twice |
| Kappa | One streaming path; reprocess by replaying the retained log | Most data arrives as events, such as payments or telemetry | Cost and time of replaying long histories |
| Lakehouse | Open table formats on object storage serving BI and machine learning from one copy | Consolidating a separate lake and warehouse | Table maintenance and engine support by format |
| Data mesh | An operating model in which domain teams own data products; see our data mesh architecture guide | A central team has become the bottleneck | Needs product-minded domain teams |
These patterns are not exclusive. A common design pairs a lakehouse for storage and serving with a streaming path for the use cases that need fresh data. Treat the lakehouse and mesh rows as a starting comparison and test them against your estate. For implementation detail on streaming, see stream processing with Apache Flink.
How do AI agents change big data architecture?
Agents move the platform from serving reports to supporting decisions. They need current state, so streaming ingestion matters for the use cases they serve. They need lineage from source to answer, so the catalog must record where data came from. And they need access policy that applies to software as well as people. XenonStack's ElixirData, our Context OS, supplies governed context above the architecture. See also agentic AI for data management and agentic AI with Snowflake.
When should you not follow these recommendations?
- When a single managed warehouse already meets small, steady reporting needs, a multi-layer design adds effort without benefit.
- When decisions are made daily or weekly, real-time pipelines add running cost and operational effort that fresher data will not repay.
- When most processing is large historical recomputation rather than events, replay-based designs can be slow and costly.
- When domains lack data skills, decentralising ownership can stall.
For the wider obstacles, see our overview of big data challenges and solutions, and for help assessing a platform see our managed services for Apache Flink streaming, data pipelines and warehouses.
What should you do first?
- Start from decisions: list the business outcomes and the latency, quality and compliance each one needs.
- Assess the estate: find duplicated pipelines and data held only in proprietary formats.
- Set the storage standard: choose storage, a table format and a catalog, and agree which engines read and write.
- Add governance before scale: ownership, access policy, quality checks and lineage for the first domains.
- Add streaming where the outcome needs it: not for everything.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is big data architecture?
It is the design for collecting, storing, processing, governing and serving data that is too large, fast or varied for a traditional database, from sources through storage and processing to analytics and reporting.
What is the difference between lambda and kappa architecture?
Lambda runs separate batch and real-time paths, which duplicates processing logic. Kappa sends all data through one streaming path and reprocesses by replaying the retained log, an approach Jay Kreps proposed in 2014.
When should an organisation consider a big data architecture?
Microsoft's guidance lists three triggers: data volumes too large for a traditional database, unstructured data that must be transformed for analysis, and unbounded streams to process in real time or with low latency.
How does AI change big data architecture?
AI agents need current data, lineage from source to answer and access policy that applies to software as well as people, so these are added on top of a governed platform.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE