Key takeaway
- Database design vs data warehouse design: grain, star schema, slowly changing history, governance, backup and recovery, with an adoption sequence.
Database design and data warehouse design solve different problems. A transactional database is modelled to record business events accurately and quickly, usually in normalised tables. A data warehouse is modelled to answer questions across those events, usually as fact tables surrounded by dimension tables. Treating the two as one exercise is the most common reason analytics platforms disappoint.
This guide sets out how each is designed, which modelling choices matter, and what enterprise architects should decide first: grain, history, governance and recovery. For the wider platform choice, see data warehouse vs data lake vs data mesh and modern data warehouse architecture.
What is the difference between database design and data warehouse design?
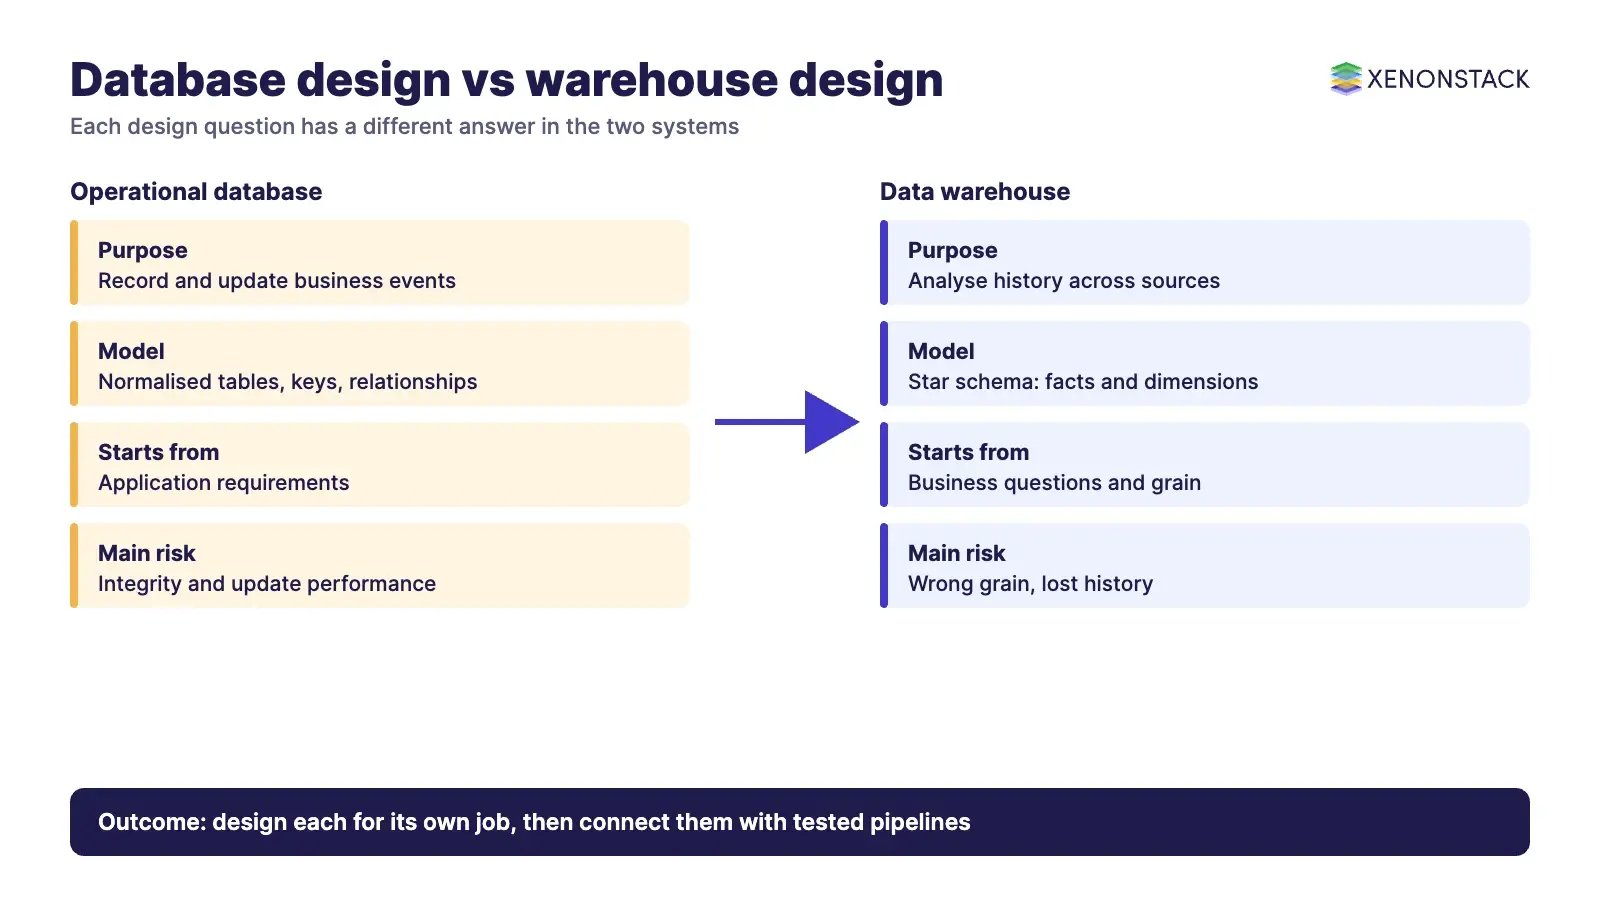
Database design analyses requirements, structure and relationships so that an application can store and change data reliably. Data warehouse design starts from the questions the business will ask and shapes data for filtering, grouping and summarising. The table below compares the two.
| Aspect | Operational database design | Data warehouse design |
|---|---|---|
| Main purpose | Record and update business events | Analyse history across many sources |
| Typical model | Normalised tables, keys and relationships | Star schema: fact and dimension tables |
| Design starts from | Application requirements and entities | Business questions and the grain of each measure |
| Data arrives by | Application writes | Loads from source systems through ETL or ELT |
| Main risk | Integrity and update performance | Wrong grain, lost history, unclear definitions |
Microsoft Learn describes the star schema as "a mature modeling approach widely adopted by relational data warehouses" that classifies each table as a dimension or a fact (Microsoft Learn: star schema, read 13 November 2026). For a comparison written for decision makers, see data warehouse vs database.
How do you design a database?
Database design moves from a logical view to a physical one. Each step has a decision attached.
| Step | What you decide | Why it matters |
|---|---|---|
| Requirement analysis | Who uses the data, in what way, how much, and where it is stored | The more thorough the analysis, the fewer redesigns later |
| Tables and data types | Entities, columns and the most suitable data type for each | Suitable types save storage and help throughput |
| Keys and relationships | Primary keys for uniqueness and foreign keys for links between tables | Keys and relationships define data integrity; keep only the mandatory connections |
| Normalisation | How far to split tables to remove duplication | Apply it to fit the workload; a secondary or reporting structure may not need it |
Before release, test the schema, constraints and migrations. Our guide to database testing covers the checks.
How do you design a data warehouse?
Start with grain. The Kimball Group defines it this way: "The grain establishes exactly what a single fact table row represents" (Kimball Group: grain, read 13 November 2026). It adds that dimensions and facts should be chosen only after the grain is set.
Microsoft Learn explains the split that follows. Dimension tables describe business entities such as products, people, places and time, and support filtering and grouping. Fact tables store observations or events, hold dimension keys and numeric measures, and enable summarisation. The grain of a fact table is set by its dimension key values, and a fact table should load data at a consistent grain.
| Warehouse design step | Decision | Output |
|---|---|---|
| Gather requirements | Which questions, which users, which refresh rate | Agreed business questions and definitions |
| Set the grain | What one fact row represents | Documented grain per fact table |
| Define dimensions and facts | Entities to filter by and measures to summarise | Star schema model |
| Design ETL or ELT | Source mapping, cleansing, load order | Tested pipelines |
| Plan OLAP and queries | Cubes, aggregates and expected query shapes | Tuned query structure |
| Release to production | Access, monitoring, backup | Operating service |
How should a warehouse handle changing history?
Customer addresses, product categories and organisation structures change. The Kimball Group lists several slowly changing dimension techniques, including Type 1 (overwrite), Type 2 (add a new row) and Type 3 (add a new attribute) (Kimball dimensional modeling techniques, read 13 November 2026). The choice is a business decision about whether past reports must keep the values that were true at the time.
| Technique | What it does | When it fits |
|---|---|---|
| Type 1: overwrite | Replaces the old value | Corrections, where history has no value |
| Type 2: add new row | Keeps each version as its own row | Audit, regulated reporting, trend analysis |
| Type 3: add new attribute | Keeps a limited previous value alongside the current one | One known transition, such as a reorganisation |
Where do the lake, lakehouse and modern warehouse fit?
Warehouse design now sits inside wider platform choices. Microsoft describes Fabric Data Warehouse as "an enterprise scale relational warehouse on a data lake foundation", with storage and compute separated and data stored as Delta tables (Microsoft Learn: Fabric Data Warehouse, read 13 November 2026). Other platforms differ, so confirm each vendor's current features on its own documentation. Read our guides to the data lake, warehouse and lakehouse, data lakehouse architecture and Snowflake data warehouse architecture. Existing estates are covered in data warehouse modernisation. Amazon Redshift, Google BigQuery and Microsoft Fabric are examples of managed warehouse services; the model design above applies to all of them.
What do governance, security and cost need from the design?
Design is where these three are cheapest to get right.
| Concern | Design decision | Check |
|---|---|---|
| Governance | Named owner and written definition for every measure and dimension | Two teams reporting the same measure get the same number |
| Security | Row and column access rules planned with the model, not after it | Sensitive columns identified before the first load |
| Cost | Grain no finer than the questions need; retire unused aggregates | Storage and query growth reviewed each quarter |
| Lineage | Every field traced to its source and transformation | Any figure can be explained on request |
Agents that query a warehouse add a further need: the decision layer must know which definition, policy and owner applied. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentAnalyst lets teams ask questions of enterprise data in plain language.
How do you monitor, back up and recover a warehouse or database?
Monitoring means defining the range each metric should stay within, so a breach points to an issue. Watch the whole problem set, not only the current flow, and sample monitoring data over time. Backups are copies of data held in another location for recovery and for building test environments. Recovery restores data to a chosen point, for example from redo logs, checkpoints or replicas.
| Failure type | Example | Design response |
|---|---|---|
| Logical | Software bug, corrupted files, malware | Point-in-time restore, tested regularly |
| Physical | Disk or server failure | Replicas and backups in a separate location |
| Site-level | Fire or flood | Off-site copy and a rehearsed recovery plan |
Agree recovery targets with the business before choosing tools, and rehearse a restore. An untested backup is an assumption.
What is a sensible adoption sequence, and when should you not build a warehouse?
Sequence: agree the business questions; set the grain and definitions; model one subject area as a star schema; load it with tested pipelines; add access, monitoring and backup; then extend to the next subject area. Do not build a warehouse when one application needs only simple operational reports, or when the questions are still unknown. In those cases a reporting view on the operational database may be enough.
To map one analytics decision your agents should make, and the data definitions and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is the main difference between database design and data warehouse design?
Database design models business events for reliable storage and update, usually in normalised tables. Data warehouse design models data for analysis, usually as fact tables linked to dimension tables in a star schema.
What is a star schema?
Per Microsoft Learn, it is a modelling approach widely used in relational data warehouses that classifies tables as dimensions, which support filtering and grouping, or facts, which store events and measures for summarisation.
What is grain in data warehouse design?
The Kimball Group defines grain as what a single fact table row represents. It should be set before dimensions and facts are chosen.
How should a warehouse handle changing data?
Use a slowly changing dimension technique. Type 1 overwrites, Type 2 adds a new row and Type 3 adds a new attribute. Choose by whether past reports must keep the values that applied at the time.
Do I still need normalisation in a warehouse?
Normalisation suits operational databases. A warehouse usually favours dimensional models for query simplicity. Apply it according to the workload.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE