Key takeaway
- A modern data warehouse separates storage from compute and queries lakes in parallel. Compare Azure, AWS and Snowflake and learn best practices.
What is a modern data warehouse?
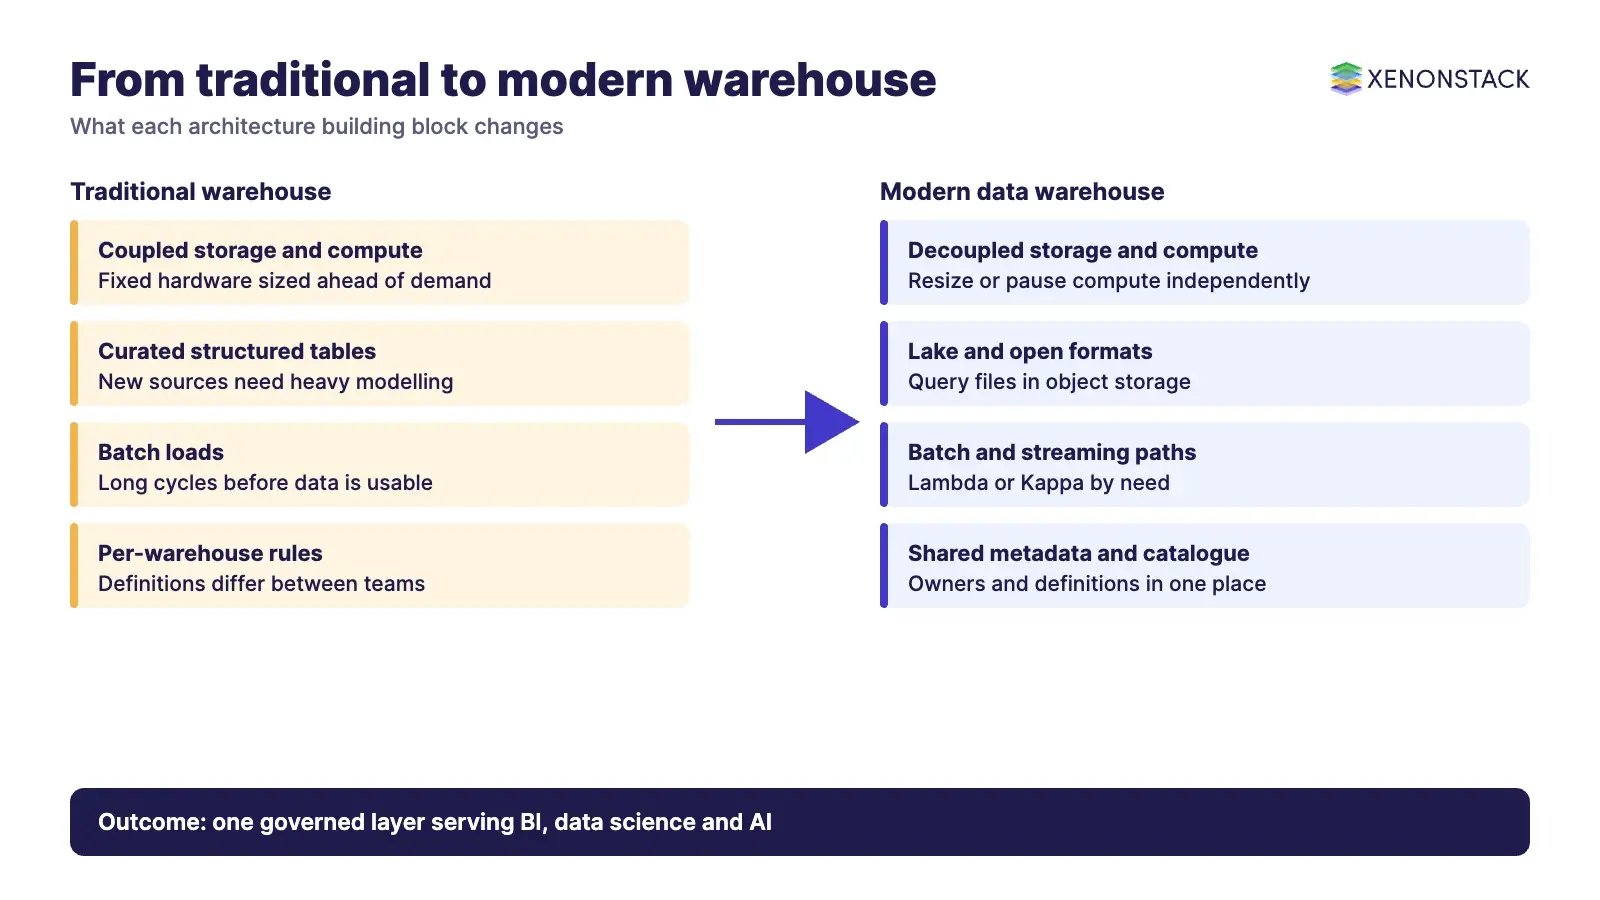
A modern data warehouse is an analytical data platform that scales storage and compute separately, runs queries in parallel across many nodes, and connects to data lakes and semi-structured data, so that one governed layer serves reporting, data science and AI. It replaces the fixed, tightly coupled appliance of the traditional warehouse.
For enterprise leaders the practical question is not which product is newest, but which architecture lets you add sources, control cost and keep one trusted set of definitions. This guide covers the core architecture, how Azure, AWS and Snowflake describe theirs, the real-time patterns, best practices and when not to modernise. For the design side, see data warehouse database design, and for the wider programme, data warehouse modernisation.
How is a modern data warehouse different from a traditional one?
| Aspect | Traditional warehouse | Modern data warehouse |
|---|---|---|
| Storage and compute | Coupled on fixed hardware | Separated and scaled independently, as in Azure Synapse and Redshift Managed Storage, according to their docs |
| Data types | Curated, structured tables | Structured plus semi-structured data, with lake access |
| Scaling | Buy capacity ahead of demand | Add or resize compute, or pause it, as described in vendor docs |
| Delivery | Long batch cycles | Batch and streaming paths, self-service BI and APIs |
| Governance | Per-warehouse rules | Shared metadata, catalogue and access policy across platforms |
How does the architecture work?
Most modern warehouses share four building blocks: massively parallel processing, decoupled storage, a lake or open-format layer, and a metadata and governance layer.
Massively parallel processing
According to Microsoft Learn, the Synapse dedicated SQL pool uses a control node that converts each T-SQL query into queries run in parallel against distributions, with compute nodes doing the work and Azure Storage holding the data. Amazon Redshift documents a leader node that parses queries and distributes compiled code to compute nodes, whose slices work in parallel. Snowflake describes a hybrid of shared-disk and shared-nothing designs, with virtual warehouses as independent MPP compute clusters over a central store.
Decoupled storage and compute
Microsoft Learn states that decoupling lets you size compute independently of storage, resize it without moving data, and pause it while paying only for storage. Amazon Redshift Managed Storage lets you scale and pay for compute and storage independently, according to the Redshift docs.
Lake access and open formats
Microsoft documents Fabric Data Warehouse as a lake warehouse that stores data as Delta tables, which are Parquet files with a transaction log. Amazon Redshift Spectrum queries structured and semi-structured files in Amazon S3 without loading them into Redshift tables. Snowflake lists support for Apache Iceberg tables in storage you manage.
Metadata and governance
Snowflake documents a cloud services layer that handles security, access control and metadata. Whatever the platform, a catalogue with owners and definitions decides whether the extra data is trusted. See enterprise data catalogue tools for how to evaluate one.
How do Azure, AWS and Snowflake compare?
| Platform | Architecture, per its own docs | Fits when | Status note |
|---|---|---|---|
| Azure (Synapse dedicated SQL pool, Fabric Data Warehouse) | Control node, compute nodes and distributions; Fabric stores Delta tables on OneLake with storage and compute separated | You run on Azure and Microsoft BI | Microsoft Learn recommends Fabric Data Warehouse for new users and offers migration for dedicated SQL pools; confirm current guidance |
| Amazon Redshift | Leader node, compute nodes with slices, Redshift Managed Storage backed by Amazon S3, Spectrum for S3 files | You run on AWS and want S3 integration | Check the Redshift docs for current node and serverless options |
| Snowflake | Central storage, virtual warehouses, cloud services layer; Iceberg and hybrid tables supported | You want multi-cloud and isolated compute per workload | Check Snowflake docs for current features |
Which real-time pattern should you use?
Microsoft's architecture guide describes the Lambda pattern as a batch layer for accurate, slower results, a speed layer for low-latency results, and a serving layer that indexes the batch view. It also states the drawback: processing logic appears in two places, which duplicates computation logic and complicates management. The Kappa alternative sends all data through one stream path and recomputes by replaying the stream. Choose Lambda when batch accuracy is essential, Kappa when you can express everything as stream processing. Our agentic AI for data management guide covers how agents sit on top of such pipelines.
What are the best practices?
- Match storage formats to engines. Check that file formats and compression work with every engine that reads them.
- Review the schema against workloads. Verify how data is loaded, processed and analysed, then tune distribution and partitioning. Microsoft Learn notes that hash, round-robin and replicated tables suit different cases.
- Plan multi-tenancy. If one stack serves many business units or customers, isolate compute and access.
- Manage metadata end to end. Capture what is needed to build, use and interpret each warehouse element. IBM documents metadata management in its own docs.
- Control cost. Pause or right-size compute where the platform allows it.
- Use data marts where they help. See data marts for when a subset is worth building.
What are the benefits and trade-offs?
| Benefit | Trade-off or when not to modernise |
|---|---|
| Faster integration of new sources | Migration effort; a stable, small warehouse may not justify it |
| Independent scaling of storage and compute | Cost can rise without governance of idle compute |
| Lake and warehouse in one governed layer | Needs shared catalogue and ownership to avoid duplicate definitions |
| Predictive and AI workloads on the same data | Data quality and access policy become the limiting factors |
What is the adoption sequence?
- Inventory sources, owners and current reports.
- Fix definitions and metadata before moving data.
- Pilot one domain on the target platform and measure load, query and cost.
- Add streaming only where a decision needs it.
- Extend to self-service BI and predictive analytics.
For AI agents that query the warehouse, ElixirData keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights. See also Agentic AI with Snowflake. For modernisation support, see our Data Warehouse Modernization Solutions.
To map one decision your agents should make on warehouse data, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What is a modern data warehouse?
A modern data warehouse is an analytical store, usually cloud-based, that separates storage from compute, scales out with massively parallel processing, and reaches into data lakes and open table formats so that one governed layer serves BI, data science and AI.
How is a modern data warehouse different from a traditional one?
A traditional warehouse couples storage and compute on fixed hardware and loads curated, structured data. A modern one scales each independently, can query data in object storage, and handles semi-structured data. Azure Synapse documentation describes pausing compute while keeping data, so you pay only for storage.
Do I still need a data lake?
Often yes. Microsoft describes Fabric Data Warehouse as a lake warehouse that stores data as Delta tables, and Amazon Redshift Spectrum queries files in Amazon S3 without loading them. Both show the warehouse and the lake converging on shared storage.
Is Lambda architecture still the way to handle real-time data?
It is one option. Microsoft's architecture guide notes that Lambda puts processing logic in two places, which duplicates logic and complicates management, and presents Kappa, with a single stream path, as an alternative. Pick based on how much batch accuracy and replay you need.
Which cloud data warehouse should we choose?
Choose by workload and existing estate, not by feature lists. Check each vendor's own docs for current status. For example, Microsoft's page recommends Fabric Data Warehouse for new warehousing users on Azure, while existing Synapse dedicated SQL pool workloads can migrate.
What should we govern first?
Start with metadata, ownership and access. Without a shared catalogue and agreed definitions, extra data sources increase disagreement rather than insight.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE