Key takeaway
- Data veracity is how far you can trust big data. Learn the sources of uncertainty, quality dimensions, lineage, provenance and EU AI Act Article 10 needs.
Data veracity is the degree to which you can trust a data set: whether it is accurate, consistent, complete and traceable to a known source. IBM lists veracity alongside volume, velocity, variety and value as one of the five Vs of big data, and defines it as "the accuracy and reliability of data" (IBM). Volume, velocity and variety describe how much data arrives, how fast and in what shapes. Veracity describes whether any of it should be believed.
For enterprise leaders the question has moved from dashboards to AI. Gartner predicts that through 2026 organisations will abandon 60% of AI projects unsupported by AI-ready data, and the EU AI Act now sets explicit data governance duties for high-risk AI systems. Veracity is therefore built from four controls you can measure: data quality dimensions, lineage, provenance and observability.
What is data veracity in big data?
Veracity covers the bias, noise, abnormality, gaps and errors in data, and the trustworthiness of the sources and pipelines that produced it. A record can be well formed and still be wrong because the upstream system was misconfigured, a join duplicated rows or a sensor drifted. That is why veracity is a property of the whole supply chain, not only of a single table.
An older version of this guide listed "additional Vs" such as validity, volatility and visualisation. These terms appear in various frameworks, but there is no single standard list beyond the widely used five. The practical point is simpler: veracity is the V that decides whether the other four produce value or risk.
| V | Question it answers | Typical owner |
| Volume | How much data do we store and process? | Platform engineering |
| Velocity | How fast does it arrive and need to be acted on? | Streaming and integration teams |
| Variety | How many formats and sources are involved? | Data engineering |
| Veracity | Can we trust it for this decision or model? | Data governance, data owners and stewards |
| Value | Does it change a business outcome? | Business and product leaders |
For how these characteristics shape platform design, see our guide to big data architecture layers and patterns.
Where does uncertainty in data come from?
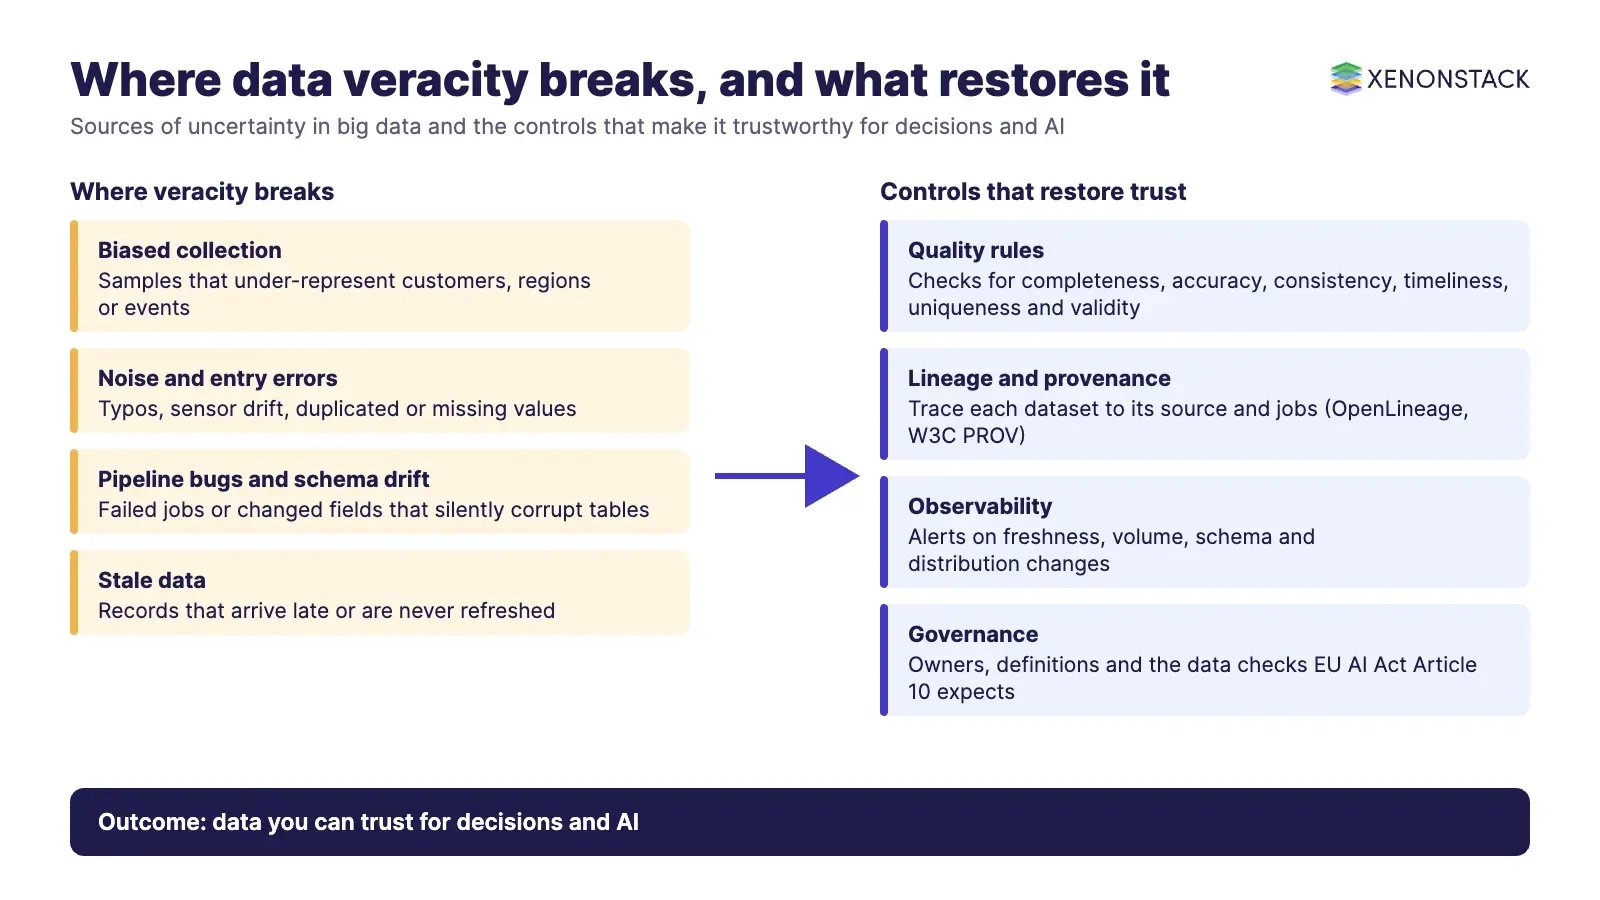
Low veracity rarely has a single cause. The common sources are below, and most enterprises face several at once.
- Bias: some groups, regions or time periods are over or under represented, so calculated values lean one way.
- Software bugs: faulty transformations, unit conversions or joins silently change values.
- Noise: irrelevant or low-value records dilute the signal and increase cleaning effort.
- Anomalies: outliers that are either genuine events (for example a fraudulent card payment) or errors that need removing.
- Ambiguity: the same field means different things in different systems, such as "customer" in billing and in CRM.
- Unknown origin: data arrives without a record of where it came from or how it was changed, so errors cannot be traced back.
Which data quality dimensions measure veracity?
Veracity becomes manageable once it is expressed as measurable quality dimensions with thresholds per data product. Our article on common data quality issues and how to fix them pairs six dimensions with the problems they catch.
| Dimension | Issue it catches | Example check |
| Completeness | Incomplete data | Share of mandatory fields that are populated |
| Accuracy | Inaccurate data | Values reconciled against a system of record |
| Consistency | Inconsistent data | Same entity matches across systems |
| Timeliness | Stale data | Time since last successful refresh |
| Uniqueness | Duplicate data | Duplicate key rate |
| Validity | Invalid data | Values conform to format, range and reference lists |
How do lineage and provenance prove data can be trusted?
Quality checks tell you that something is wrong. Lineage and provenance tell you why, and who is accountable. They are related but not identical.
Data provenance and W3C PROV
The W3C defines provenance as "information about entities, activities, and people involved in producing a piece of data or thing", which can be used to assess quality, reliability or trustworthiness (W3C PROV Overview). The PROV data model, a W3C Recommendation published on 30 April 2013, uses three core types: an entity (a thing such as a data set), an activity (something that acts on entities over time, such as a transformation job) and an agent (something that bears responsibility, such as a team or service). Relations such as wasGeneratedBy, used, wasDerivedFrom and wasAttributedTo link them (PROV-DM).
Data lineage and OpenLineage
Lineage is the operational map of how data flows from source to consumption. OpenLineage, an LF AI and Data Foundation graduate project, describes itself as "an open framework for data lineage collection and analysis" and models lineage as datasets, jobs and runs, with facets that carry extra metadata (OpenLineage). Capturing lineage as an open standard keeps it portable across orchestrators and catalogues. Our guide to data lineage tools and best practices covers implementation in more depth.
| Control | What it records | When it fits | Current status |
| Provenance (W3C PROV) | Who and what produced each entity, and from what | Audit, regulated reporting, research and AI training data records | W3C Recommendation since April 2013 |
| Lineage (OpenLineage) | Dataset, job and run relationships across pipelines | Impact analysis, root cause analysis, change management | LF AI and Data graduate project |
| Quality rules | Pass or fail against defined dimensions | Known, stable expectations per data product | Standard practice in data platforms |
| Data observability | Health signals such as freshness, volume and schema change | Large estates where unknown failures are likely | Established tool category |
What does data observability add?
Quality rules only catch what someone thought to test. Data observability monitors pipelines continuously for unexpected change. Monte Carlo, a vendor in this category, describes five pillars: freshness, quality, volume, schema and lineage, the last used to see which upstream and downstream assets, teams and users are affected when data breaks (Monte Carlo). In veracity terms, observability shortens the time between a data incident and someone knowing about it.
Why does veracity matter more for AI-ready data?
Machine learning models and AI agents act on data at scale, so errors are repeated rather than noticed once on a report. Gartner's February 2025 release, based on a July 2024 survey of 1,203 data management leaders, found that 63% of organisations either lack the right data management practices for AI or are unsure whether they have them, and predicted that through 2026 organisations will abandon 60% of AI projects unsupported by AI-ready data (Gartner).
AI-ready data is not perfect data. It is data whose quality, lineage and limitations are known and documented for a specific use case, so the people approving a model can judge whether it is fit for purpose. For AI agents that act on such data, ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above them.
What does EU AI Act Article 10 require from training data?
Article 10 of Regulation (EU) 2024/1689 turns veracity into a legal duty for high-risk AI systems that are trained on data. Training, validation and testing data sets must be subject to data governance and management practices covering, among other points, design choices, data collection processes and the origin of data, data preparation such as annotation, labelling and cleaning, the assumptions the data is meant to represent, an assessment of availability, quantity and suitability, examination for possible biases and measures to detect, prevent and mitigate them, and identification of data gaps or shortcomings. Article 10(3) adds that these data sets "shall be relevant, sufficiently representative" and "free of errors and complete in view of the intended purpose" (EUR-Lex, Regulation (EU) 2024/1689).
The timing has changed. The Digital Omnibus on AI, Regulation (EU) 2026/1744 of 8 July 2026, entered into force on 27 July 2026. Its recitals set the application date to 2 December 2027 for high-risk systems under Article 6(2) and Annex III, and to 2 August 2028 for those under Article 6(1) and Annex I (EUR-Lex, Regulation (EU) 2026/1744). The extra time is best used to put lineage, provenance and bias examination in place now, because Article 10 evidence is hard to reconstruct after a model has been trained. On the decision side, the ElixirData Audit Agent assembles decision lineage, policies and approvals into audit evidence.
| Article 10 expectation | Veracity control that provides evidence |
| Data collection processes and origin of data | Provenance records and source register |
| Data preparation operations | Lineage of cleaning, labelling and enrichment jobs |
| Examination for possible biases and mitigation | Representativeness and bias checks with documented results |
| Free of errors and complete for the intended purpose | Quality dimensions with thresholds and observability alerts |
| Identification of data gaps or shortcomings | Known-issues log owned by the data product team |
How should enterprises improve data veracity, step by step?
- Pick the decisions that matter. Start with the data products feeding regulated reporting, revenue decisions or AI models, not the whole estate.
- Assign ownership. Each data product needs an accountable owner and a steward, set out in your data governance model.
- Validate at the source. Enforce formats and reference values at input forms, APIs and device gateways, where fixing errors is cheapest.
- Define quality thresholds. Set targets for the six dimensions per data product and publish them with the data.
- Capture lineage and provenance automatically. Emit lineage events from pipelines rather than drawing diagrams by hand.
- Add observability. Monitor freshness, volume and schema change so silent failures surface quickly.
- Document for AI use. For training data, record origin, preparation steps, bias checks and known gaps in line with Article 10.
For a review of tooling options, see data veracity and its tools, and for platform choices, our overview of big data platform features and use cases.
What do governance, security and cost look like?
- Governance: veracity controls only hold if owners act on alerts. Tie thresholds to data contracts between producers and consumers.
- Security: lineage and provenance metadata reveal system structure and sometimes personal data fields, so apply the same access controls as to the data itself.
- Cost: checks and monitoring consume compute. Scale effort to the risk of each data product rather than applying the same depth everywhere.
What are the trade-offs, and when should you not go further?
Exhaustive validation on exploratory or short-lived data sets can cost more than the decisions they support. Strict rules can also reject genuine anomalies, such as a real spike in fraud, that analysts need to see. A sensible approach is tiered: full lineage, provenance, quality thresholds and observability for critical and AI training data; lighter checks for sandbox and exploratory work, with a clear label that the data is not certified.
Industry examples of data veracity
Healthcare
Patient records, lab results, device readings and claims data are combined for diagnostics and operations. Incomplete or biased records can lead to unsafe conclusions, so provenance of each source and bias examination across patient groups are essential before data is used for analytics or AI.
Retail
Retailers combine transactions, browsing behaviour, inventory and loyalty data. Duplicate customers, stale stock levels or mismatched product codes produce wrong recommendations and wasted campaigns. Uniqueness and timeliness checks, plus lineage from point of sale to the analytics layer, keep these decisions reliable.
Financial services
Fraud detection depends on separating genuine anomalies from data errors. Lineage that shows exactly which feeds and transformations produced a flagged transaction lets investigators trust or reject an alert quickly.
To map one data-trust decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is data veracity in simple terms?
It is how far you can trust a data set to be accurate, consistent and traceable to a reliable source. IBM defines it as the accuracy and reliability of data.
What are the 5 Vs of big data?
Volume, velocity, variety, veracity and value, as listed by IBM.
What is the difference between data lineage and data provenance?
Lineage maps how data flows through pipelines, for example as datasets, jobs and runs in OpenLineage. Provenance records the entities, activities and agents responsible for producing data, as defined by W3C PROV.
Which data quality dimensions should we measure first?
Completeness, accuracy, consistency, timeliness, uniqueness and validity cover most veracity issues. Start with the dimensions that most affect your critical decisions.
Does the EU AI Act require data veracity?
For high-risk AI systems trained on data, Article 10 requires data governance practices and training, validation and testing data that are relevant, sufficiently representative, free of errors and complete. Following the Digital Omnibus on AI, these high-risk obligations apply from 2 December 2027 (Annex III) and 2 August 2028 (Annex I).
Is data observability the same as data quality?
No. Data quality rules test known expectations. Observability monitors signals such as freshness, volume and schema change to catch failures nobody anticipated.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE