Key takeaway
- Big data security explained for CISOs and architects: controls to apply first, how five tools compare, trade-offs, and how to govern AI agent access.
Big data security is the set of controls that protect large, distributed data sets and the analytics that run on them. For an enterprise it means five things: knowing where sensitive data is, proving who is allowed to reach it, encrypting it, watching how it is used, and keeping an audit record that stands up to a regulator.
This guide is for CISOs, CDOs, enterprise architects and platform leads. It sets out which controls come first, how the main tool categories differ, where the trade-offs sit, and how AI agents change the access question. For the wider platform picture, see our guide to the big data platform, its features and use cases.
What is big data security and why does it need its own approach?
Big data platforms combine many data types from many sources, usually on clusters of many nodes. That makes the attack surface wider than a single database: more nodes, more interfaces, more people with access, and data that moves between analytics tools. NIST treats this as a distinct area and has published NIST Big Data Interoperability Framework Volume 4: Security and Privacy (SP 1500-4 Rev. 2, October 2019), which describes the security and privacy concerns big data creates and a security and privacy fabric for its reference architecture.
Most enterprises that run big data platforms hold sensitive records such as payment, banking and credential data, so the question is rarely whether to protect the data, but which controls to put where. Our overview of data management services and solutions shows how security fits with the rest of the data estate.
Which controls does a big data platform need, and what is their current status?
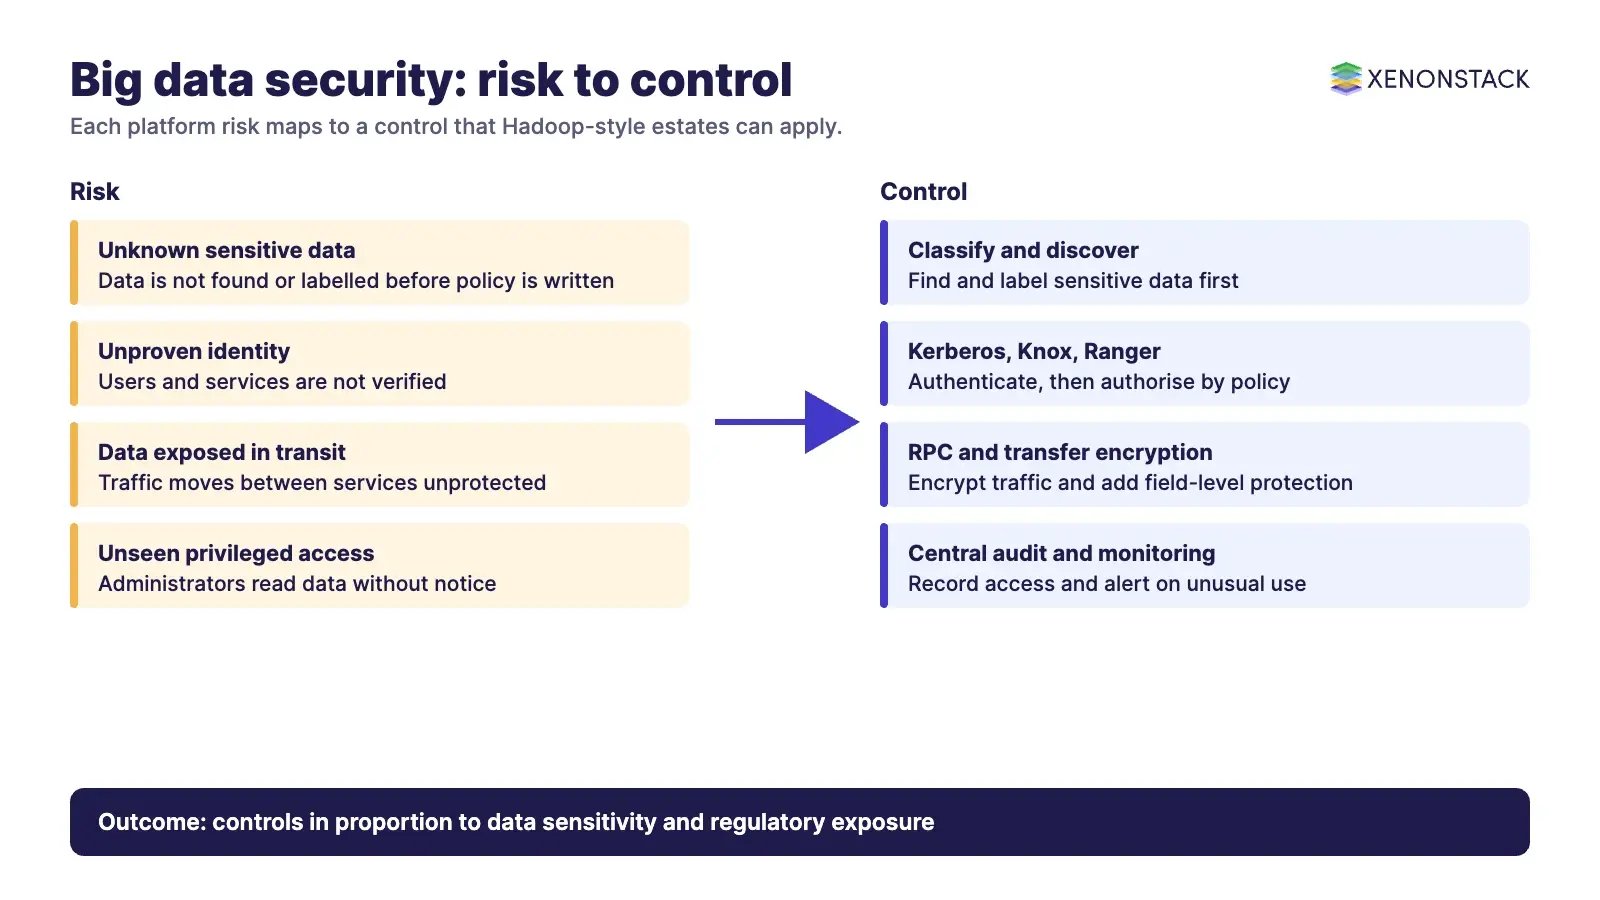
The table maps each control to the open-source or standards-based component that implements it in a Hadoop-style estate, and to the status we confirmed on the project pages on 11 November 2026.
| Control | What it does | Typical component | Status checked |
|---|---|---|---|
| Authentication | Proves that users and services are who they claim to be | Kerberos in Apache Hadoop secure mode; Apache Knox for REST APIs and web UIs | Hadoop secure mode documentation (3.3.5 page); Knox 2.1.0 listed as latest release |
| Authorisation | Limits what an authenticated identity can do | Hadoop service-level authorisation; Apache Ranger policies (role and attribute based) | Ranger 2.9.0 listed as latest release |
| Encryption in transit | Protects data moving between services, clients and DataNodes | Hadoop RPC protection set to privacy; encrypted block data transfer; HTTPS per daemon | Documented settings in Hadoop secure mode |
| Central administration and audit | One place to manage policy and record access and admin actions | Apache Ranger | Described on the Ranger project page |
| Discovery and classification | Finds and labels sensitive data before policy is written | Commercial data security platforms (see tool table below) | Vendor claims, see below |
How do the main big data security tools compare?
The original version of this post listed five commercial products. We have rechecked each against its own site. The descriptions below use each vendor's own wording and are vendor claims, not independent test results.
| Tool | How the vendor describes it | Best fit | Note |
|---|---|---|---|
| BigID | One platform for security controls, privacy automation and AI governance, with discovery and classification across cloud, SaaS, on-premises and mainframe | Estates where finding and cataloguing sensitive data is the first problem | Positions itself as a data security posture management (DSPM) platform |
| Thales CipherTrust | Discovery, classification, data protection and central key and secrets management in one system; finds and classifies data across files, databases and big data | Encryption and key management at scale | The page mentions big data but not Hadoop by name |
| LogRhythm | Listed on Exabeam's site as LogRhythm SIEM and LogRhythm Intelligence, part of the Exabeam LogRhythm platform | Security monitoring and analytics from logs | Now presented under Exabeam, so check the current product name before you buy |
| Varonis | Connects data, AI and threat detection in one security platform | Teams that want data security and threat detection together | Platform also spans AI security and email threat protection |
| Protegrity | AI data security, governance and agentic data protection, with tokenisation, encryption and discovery | Tokenisation and format-preserving protection of sensitive fields | Discovery SDKs cover prompts, logs and unstructured text |
No single tool covers every layer. Most enterprises combine platform-native controls (Kerberos, Ranger, Knox) with one discovery and protection product, and add a log analytics or SIEM tool for monitoring.
What does data security management involve?
Data security management is the process of keeping business data out of the hands of unauthorised people. It focuses on sensitive data such as personal information and intellectual property, and includes writing information security policies, identifying security risks, assessing threats to IT systems, and telling staff what good practice looks like, for example care when opening email attachments.
The point for leaders is that tools enforce policy; they do not write it. Agree data classes, owners and access rules first, then choose tools to enforce them.
How should an enterprise sequence big data security work?
A sequence that works for most estates, from least to most effort:
1. Classify the data
Find out where sensitive data lives and label it by class. Without this, every later control is applied blind. Classification can be rule-based, tool-assisted or, as the earlier version of this post described, driven by a trained classifier that separates normal from sensitive data.
2. Lock down identity and access
Put authentication at the perimeter and between cluster services, then enforce authorisation by policy. In a Hadoop estate that means Kerberos, service-level authorisation and Ranger policies, with Knox as the single entry point for REST and web access.
3. Encrypt data in motion and at rest
Turn on RPC protection, encrypted block transfer and HTTPS for each daemon, then add field-, file- and storage-level protection for the most sensitive classes. Keep key management central.
4. Audit and monitor
Record who accessed what, keep audit data separate from the data it describes, and protect it with its own access controls. Feed logs to a monitoring tool so unusual access, such as an administrator reading data without a business reason, raises an alert.
5. Govern access by agents and analytics tools
As analytics and AI agents read more enterprise data, access decisions need context as well as a role: which task, which policy, which approver. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need. For the data risks that agents introduce, read our guide to agentic AI security, data protection and privacy risks.
What are the main challenges in securing big data?
These issues apply on premises and in the cloud. If a vendor hosts the platform, agree security service levels with them and do not assume the provider covers every item.
| Challenge | Why it is hard | Practical response |
|---|---|---|
| Newer data stores | Non-relational stores such as NoSQL databases have different security models from relational ones | Review each store type separately and apply its native access controls |
| Output paths | Ingest and storage are often well protected, but data leaving to many analytics platforms and locations may not be | Extend encryption and access policy to every output |
| Privileged insiders | Administrators can read data without permission or notice | Monitor and alert on privileged access |
| Scale and clusters | Terabytes to petabytes across many nodes make full manual audits impractical and expose many servers | Automate audit collection and patching |
| Stale protection | Out-of-date environments risk data loss and disclosure | Keep the platform and its security components updated |
| Malware response | Staff must detect and clean infections across systems, databases and web | Use detection tooling and rehearse the response |
Our guide to big data challenges and solutions covers the wider delivery issues.
What are the best practices for securing big data?
Authenticate, authorise and audit centrally
Use Kerberos for service and user authentication and set hadoop.security.authorization to true so service-level authorisation applies, as described in the Apache Hadoop secure mode documentation. Use Apache Ranger to manage fine-grained authorisation and central audit across Hadoop components, and Apache Knox as the gateway for REST APIs and web interfaces.
Encrypt data in transit and at rest
Set hadoop.rpc.protection to privacy to encrypt traffic between services and clients, and set dfs.encrypt.data.transfer to true for DataNode block transfers. Configure HTTPS for each daemon through its HTTP policy setting. Consider protection at field, file and network level for the most sensitive classes.
Protect non-relational and distributed components
Non-relational stores are exposed to injection-style attacks, so validate inputs, hash or encrypt credentials and keep end-to-end encryption in place. Scan worker nodes in cloud or virtual environments for rogue nodes.
Control endpoints and monitor in real time
Only trusted devices should connect to the platform. Collect and review logs continuously, and place security controls at cloud, network and application levels.
Preserve privacy and manage provenance
De-identify personal data where analytics does not need it, train staff on privacy rules, and protect provenance metadata with access control and integrity checks, because it is data too.
Audit with care
Granular auditing matters most after an incident. Keep audit data isolated from the data it describes, protect it with granular access controls, and make sure a complete trail can be reached quickly to cut response time.
Where do big data security solutions apply in the enterprise?
| Use case | What it addresses |
|---|---|
| Cloud security and monitoring | Secures communication and sensitive data hosted on cloud platforms and monitors cloud applications |
| Insider threat detection | Uses analytics over access data to detect and avoid threats from people with legitimate access |
| User behaviour analysis | Tracks and analyses user behaviour to spot unusual patterns before they become a breach |
For audit evidence, the ElixirData Audit Agent gathers a decision's history, the policies in force and its approval records so compliance teams can answer auditor questions without manual searching.
What are the trade-offs, and when is a heavy security stack the wrong choice?
Every added control has a cost in performance, operations and skills. Encryption of all traffic adds processing overhead; central policy tools need administrators who understand them; and a tool bought before data classification is done often protects the wrong things. A smaller estate with a handful of sensitive tables may be better served by native platform controls and good audit than by a full data security platform. Choose controls in proportion to the sensitivity of the data and the regulatory exposure, and revisit the choice as the estate grows.
To map one data access decision your agents and analysts should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is big data security?
Big data security is the set of controls that protect large, distributed data sets and the analytics that run on them: authentication, authorisation, encryption, auditing and monitoring. NIST publishes a dedicated volume on big data security and privacy (NIST SP 1500-4 Rev. 2, October 2019).
Which controls matter first in a Hadoop-style platform?
Start with strong authentication (Kerberos in Hadoop's secure mode), service-level authorisation, encryption in transit, and central policy and audit. The Apache Hadoop secure mode documentation covers the first three, and Apache Ranger covers central administration, authorisation and auditing.
How is data security management different from data security tools?
Data security management is the practice of policies, risk identification, threat assessment and staff guidance. Tools such as discovery, encryption and monitoring platforms enforce those policies; they do not replace them.
Do cloud platforms remove the need for big data security controls?
No. Hosting in the cloud moves some responsibilities to the provider, but the organisation still needs to agree security service levels, control access to its own data and keep audit evidence.
Where do AI agents change the picture?
Agents that read and act on enterprise data add a new path to sensitive data. The control question becomes which agent may use which data, under which policy, with which record. A governance layer such as AgentGRC is built for that audit trail.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE