Key takeaway
- Eight big data challenges, from skills and integration to security and cost, with practical fixes and a governance view for enterprise leaders.
The main big data challenges for enterprises are skills, data growth, tool selection, integration, security, cost and timely insight. Each one is solvable, but only when it is treated as an architecture and governance decision and not as a tooling purchase. This guide sets out the eight challenges leaders meet most often, the first fix for each, and who should own it.
The answers below are written for CTOs, CDOs, architects and platform leads. For the tooling side see our big data tools guide, and for the design side see big data architecture challenges.
What are the main big data challenges for enterprises?
NIST describes big data as data whose volume, velocity and variety strain traditional approaches (NIST SP 1500-1r2, October 2019). The table below turns that into eight working problems and a sensible first move for each.
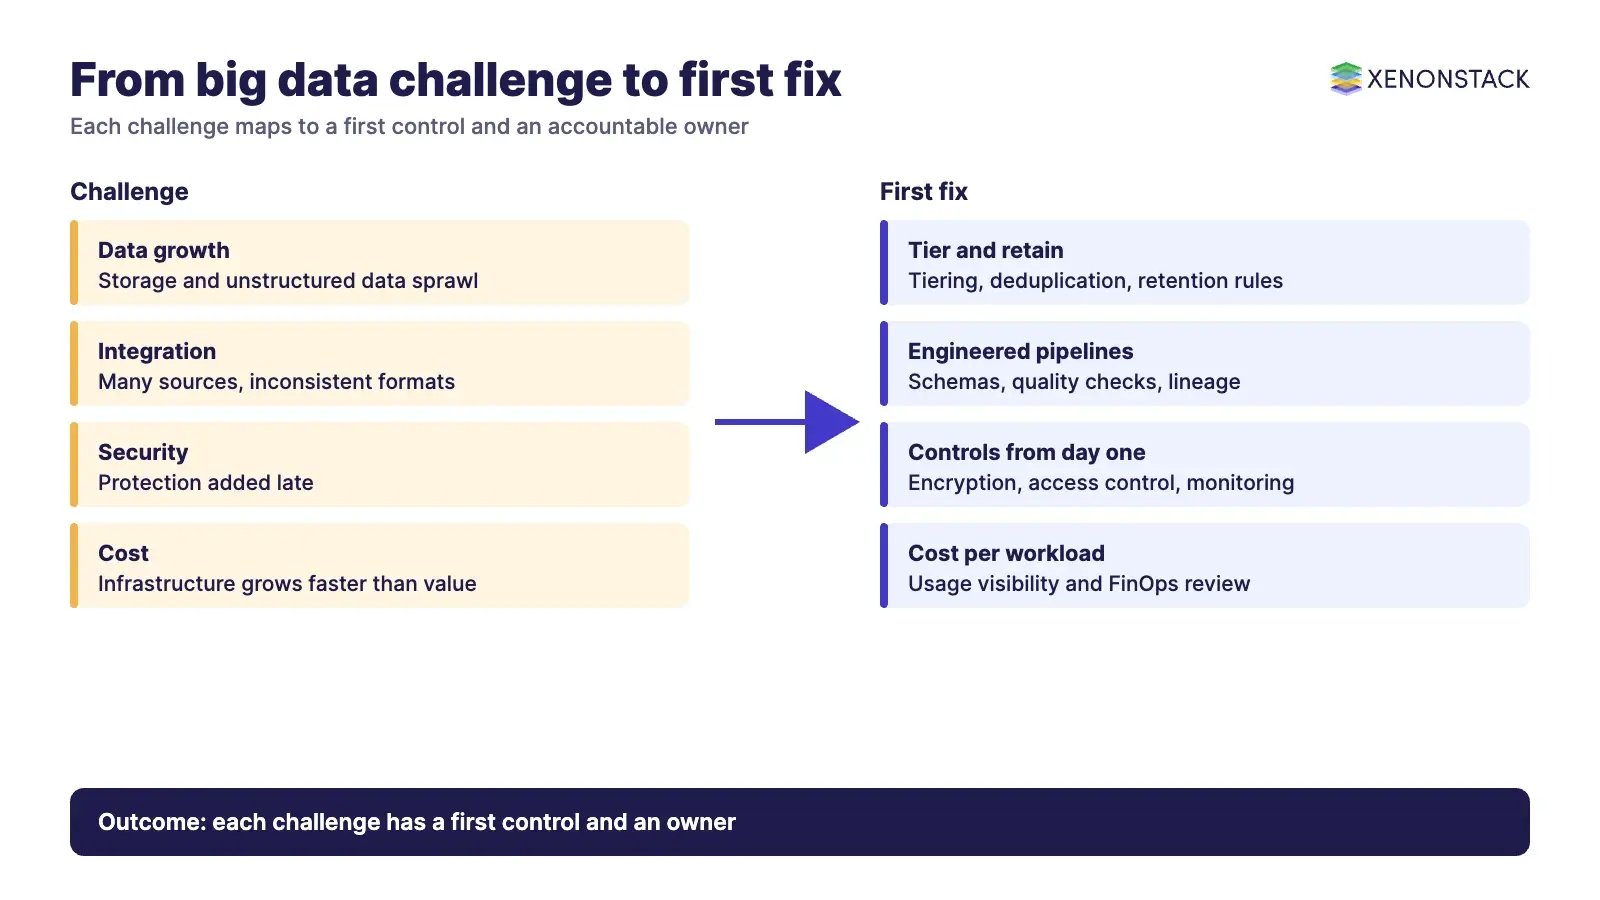
| Challenge | What goes wrong | First fix | Usual owner |
|---|---|---|---|
| Skills gap | Tools evolve faster than teams | Training plus managed or assisted tooling | CDO, Head of Engineering |
| Shared understanding | Business users cannot judge or trust the data | Common definitions and a data catalogue | CDO |
| Data growth | Storage and unstructured data sprawl | Tiering, deduplication, retention rules | Platform lead |
| Tool selection | Wrong engine for the workload | Workload-first evaluation and a pilot | Enterprise architect |
| Integration | Many sources, inconsistent formats | Pipelines with contracts and quality checks | Data engineering |
| Security | Protection added late | Encryption, access control, monitoring from day one | CISO |
| Cost | Infrastructure grows faster than value | Cost visibility per workload, FinOps practice | CIO, FinOps lead |
| Real-time insight | Reports arrive after the decision | Streaming where latency matters, batch elsewhere | Platform lead |
How do you close the skills and understanding gap?
Data engineers, analysts and scientists are hard to hire, and tools change quickly. Fund training for existing staff, and use assisted analytics so that people with domain knowledge can work with data without being specialists. The wider gap is shared understanding: if business teams do not know where data comes from, how it is stored and why backups matter, they cannot retrieve it or trust it when needed. Short role-based workshops and a shared catalogue of definitions do more than a single large training programme. Our guide to why data quality matters covers the controls that make that understanding concrete.
How do you handle data growth and unstructured data?
Most new data is unstructured: documents, audio, video and text that does not fit a relational table. Three techniques keep growth manageable. Compression reduces the size of stored data. Deduplication removes repeated copies. Tiering places data on storage that matches its value and access pattern, for example flash for hot data and cheaper cloud or archive storage for cold data. Pair them with retention rules, so data is archived or deleted on purpose and not forgotten. Engines such as Hadoop and NoSQL databases remain relevant for scale-out storage, but the choice should follow the workload.
How do you choose big data tools without wasting budget?
Teams often stall on questions such as HBase or Cassandra for storage, or MapReduce or Spark for analytics. Start from the workload: data shape, latency, query pattern, scale and who will operate it. Shortlist two or three options, run a time-boxed pilot on your own data, and score the results against cost and operability. Experienced engineers or an independent review help here, because a poor choice wastes months of effort. The same discipline applies to the platform that sits on top of the tools, covered in our agentic AI for data management guide.
How do you integrate data from many sources?
Enterprise data arrives from ERP systems, customer logs, social channels, finance reports, email and spreadsheets. Combining it for reporting is slow when each source has its own format and meaning. Build integration as engineered pipelines: agreed schemas, automated quality checks at ingestion, lineage so that every figure can be traced to its source, and a shared metadata layer. Tool choice matters less than these habits. Our data integration tools guide compares the options, and the open metadata platform guide explains how a catalogue ties sources together.
How do you secure big data?
Security is often pushed to a later phase while teams focus on storing and analysing data, which leaves repositories exposed. According to IBM's site, the global average cost of a data breach in its Cost of a Data Breach Report 2026 is US$4.99 million, a new high. Build these controls in from the start:
- Encryption of data at rest and in transit.
- Identity and granular access control, including inside the platform and not only at the perimeter.
- Data segregation between sensitive and general data sets.
- Data provenance, so that fake or tampered data can be detected.
- Continuous monitoring of access and activity.
The big data security guide covers tools and controls in more depth.
How do you keep big data costs under control?
Big data programmes carry upfront costs and recurring infrastructure costs that grow with volume. Three habits help. First, monitor usage continuously, with DevOps and DataOps practices that show which workloads consume what. Second, consider cost when designing each pipeline: duplicate copies across stores, data kept long after its value has gone, and over-provisioned clusters are common sources of waste. Third, use pay-as-you-go services where the workload is variable, and tier data by business value. Cloud cost practice is a discipline of its own; see our FinOps cost optimisation guide.
How do you get real-time insight from big data?
Data has no value until it informs a decision. First decide what real time means for each use case: seconds for fraud checks, minutes for operations dashboards, hours for finance. Use streaming only where latency changes the outcome, and batch elsewhere. Open table formats can reduce the split: according to the Delta Lake documentation, a Delta table works as a batch table and as a streaming source and sink, with ACID transactions, schema enforcement and time travel for audit and rollback.
Which challenges are specific to healthcare, security teams and cloud governance?
Healthcare
The technical problems are data exchange and interoperability across systems, integrating multi-source data into one analytical platform, and building predictive and prescriptive models clinicians can use. Treat any clinical use as subject to regulator and clinical governance review. Our digital healthcare page describes our work in this area.
Security management
Recurring problems are vulnerability to fake data generation, weak granular access control, strong perimeters but weak protection inside the system, unclear data provenance, and protecting data in real time.
Cloud security governance
Cloud governance has to cover performance management, control and policy, cost management and security together. Treat them as one operating model and not as four separate projects.
What challenges come with moving from Hadoop to Delta Lake?
Teams usually move because of reliability and scalability limits, the time and resource cost of running clusters, blocked projects, weak support and runtime quality issues. The migration itself brings its own risks: rewriting jobs, validating results against the old system, and moving governance and access rules with the data. Run old and new in parallel, reconcile outputs, and migrate by data domain and not all at once. Our Hadoop to Delta Lake migration guide sets out the architecture.
How do big data challenges change when AI agents use the data?
When AI agents query and act on enterprise data, the old challenges sharpen. Poor integration produces wrong answers faster, weak access control lets an agent see what it should not, and missing lineage makes a decision impossible to explain. The answer is governed context: agents should read data under versioned policy and leave a decision trace. ElixirData keeps governed context, versioned policy and decision traces in one decision layer above AI agents. AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights, and ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
In what order should you tackle the challenges?
- Name the business decisions the data must support, and who owns each.
- Fix security, access control and lineage before scaling volume.
- Integrate sources through tested pipelines with quality checks.
- Pick tools by workload after a pilot, not by popularity.
- Add cost visibility per workload and review it monthly.
- Introduce streaming only where latency changes the decision.
- Train teams and publish shared definitions throughout.
When is a big data platform not the right answer?
If your data fits comfortably in a single relational database and your queries are modest, a distributed platform adds cost and operating burden without benefit. Start with the simplest architecture that meets the requirement, and move to a larger one when volume, variety or latency demands it. Our data mesh adoption guide shows the same trade-off at organisation scale.
To map one data decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions about big data challenges
What are the biggest big data challenges?
The most common are skills, data growth, tool selection, integration, security, cost and timely insight. Security and integration usually carry the highest risk, because mistakes there affect every later stage.
How do you solve the big data storage problem?
Combine compression, deduplication and tiering with clear retention rules, and choose storage by workload. Archive or delete data on purpose, not by neglect.
Why is big data security hard?
Data comes from many sources, sits in many stores and is often secured only at the perimeter. Access control, provenance and monitoring need to work inside the platform. According to IBM's site, the global average breach cost in its 2026 report is US$4.99 million.
How do you reduce big data costs?
Monitor usage per workload, avoid duplicate copies, tier data by value and use pay-as-you-go services for variable loads. Add a FinOps review so that cost sits next to value.
Do AI agents change big data challenges?
They raise the stakes. Agents need governed access, quality data and decision traces, so integration, security and lineage become more important, not less.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE