Key takeaway
- Data veracity is the accuracy and reliability of data. See what lowers it, how to check it, and how Spark, KNIME and RapidMiner fit a quality workflow.
Data veracity is the accuracy and reliability of data: how far you can trust a dataset to describe what really happened. It is one of the "V"s of big data, and it decides whether analysis built on that data leads to good decisions or confident mistakes.
This guide is for data engineers, analysts and data leaders who work with data from many sources. It explains where veracity sits among the other big data dimensions, what lowers it, how to test it, which tools help, and how AI agents raise the stakes. For background, see our guides to big data and the big data architecture that carries it.
What is data veracity?
IBM lists five Vs of big data in its big data overview: volume, velocity, variety, veracity and value. It states that "veracity refers to the accuracy and reliability of data," and notes that because big data arrives in large quantities from many sources, it can contain noise or errors that lead to poor decisions. IBM adds that organisations need quality controls, such as tools that scrub, check and confirm information.
Veracity helps separate what is relevant from what is not, so that people can interpret the data and act on it. Social media sentiment is a common example: it is full of ambiguity, so reliable signals have to be told apart from uncertain and imprecise ones.
How does veracity differ from the other Vs?
| Dimension | Question it answers | Example check |
|---|---|---|
| Volume | How much data is there? | Storage and processing capacity |
| Velocity | How fast does it arrive? | Streaming or batch ingestion |
| Variety | How many forms does it take? | Structured, text, image and sensor data |
| Veracity | Can we trust it? | Validation, lineage and bias review |
| Value | Does it help a decision? | Use cases tied to a business question |
The first three describe the shape of the data and are easiest to scale. Veracity is harder because it depends on how the data was captured, moved and changed. Our guides to data intelligence and the big data platform show where it fits in the wider stack.
What lowers data veracity?
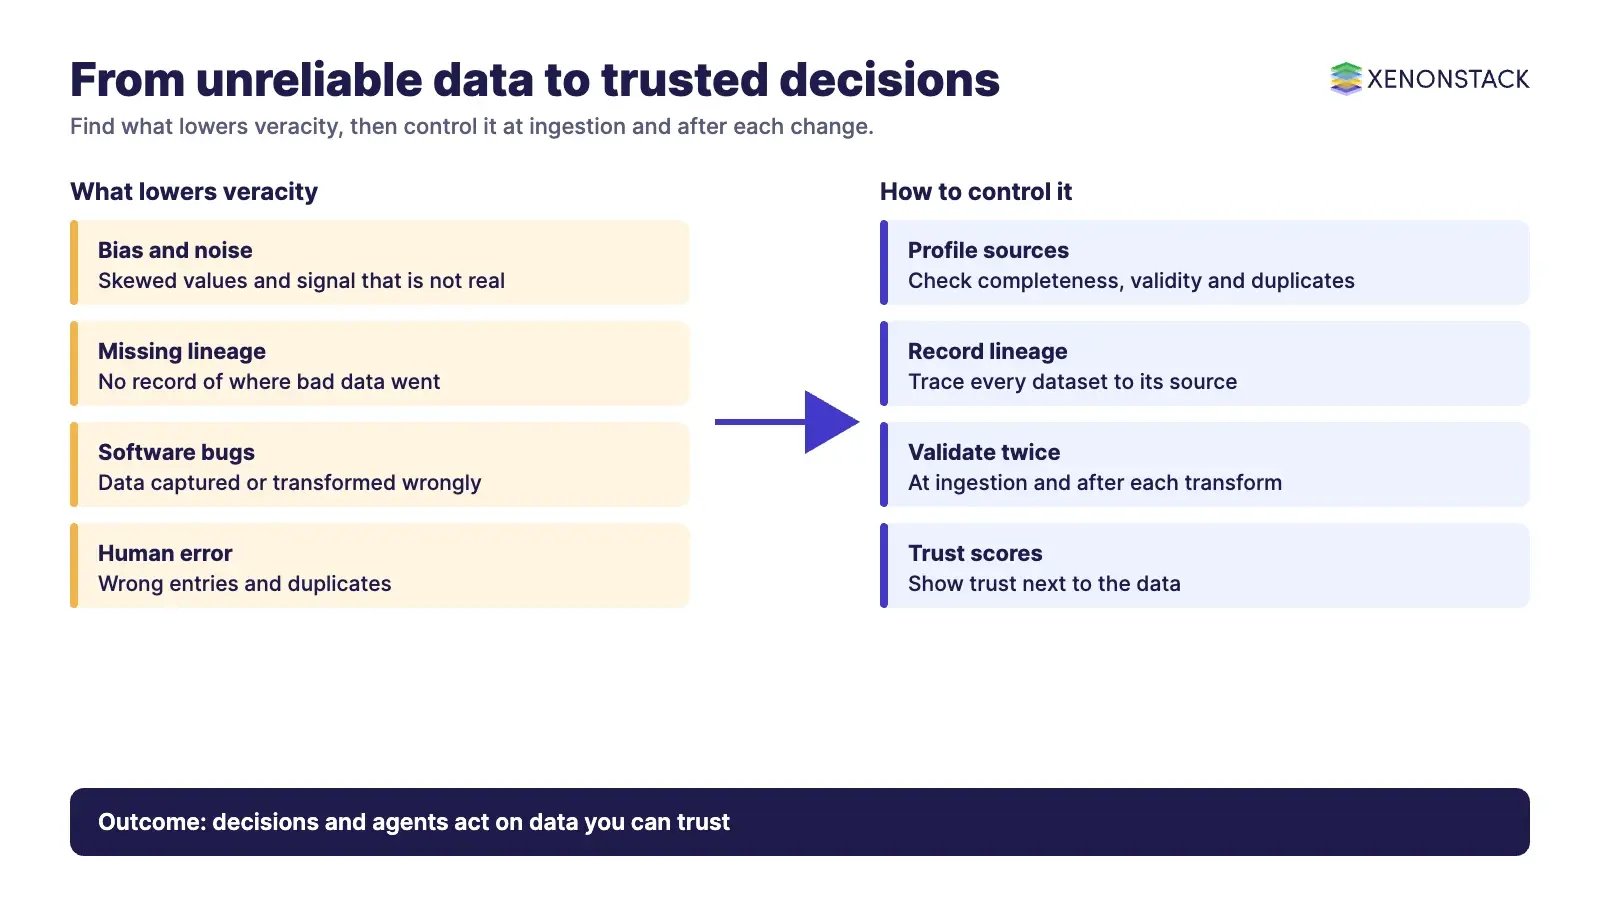
Veracity problems usually trace back to a small set of causes. Each one has a matching control.
| Cause | What it looks like | Control |
|---|---|---|
| Statistical bias | A decision rests on a value that is systematically skewed | Review sampling and how metrics are calculated |
| Noise | A sensor or system reports signal that is not real | Filtering and anomaly checks |
| Missing lineage | One source is found to be wrong, but nobody knows where its data went | Record where every dataset came from and where it flows |
| Abnormal readings | Two sensors next to each other report very different conditions | Cross-check sources and set thresholds |
| Software bugs | Data is captured or transformed wrongly | Test pipelines and compare inputs with outputs |
| Security tampering | An attacker alters stored data | Access control and integrity checks |
| Human error | A phone number is typed wrongly | Validation at entry and de-duplication |
How do you improve and measure veracity?
- Profile each source for completeness, validity and duplicates before you load it.
- Record lineage, so a bad source can be traced to every table and report it touched.
- Validate data at ingestion and again after each transformation.
- Score each source on trust and show that score next to the data.
- Review the score on a schedule, because sources drift over time.
Better discovery helps too: see our guide to advanced data discovery and, for analytics that depend on trusted inputs, augmented analytics. Where data is collected at the edge, the trade-offs in cloud, edge and fog computing affect how early you can clean it.
Which tools help with data veracity?
No single tool creates veracity, but several widely used platforms help you prepare, check and process data at scale. Pick by the checks you need and test with a trial before you commit.
| Tool | Description | Where it helps |
|---|---|---|
| Apache Spark | "A multi-language engine for executing data engineering, data science, and machine learning on single-node machines or clusters", with Python, SQL, Scala, Java and R | Large-scale validation and transformation, in batch or streaming |
| KNIME Analytics Platform | Free and open source, with 300+ connectors to data sources and access to popular ML libraries | Blending data from many sources and building repeatable preparation workflows |
| RapidMiner | Data mining, text mining and predictive analytics software | Preparation and modelling; check current ownership and licensing first |
Sources: Apache Spark and KNIME. At the time of writing, the former Altair address for RapidMiner redirects to a Siemens product page, so confirm the current vendor, edition and licence before you plan around it.
How do AI agents change data veracity?
When an AI agent acts on data, a veracity error is no longer a wrong chart: it can become a wrong action. Agents need to know where a value came from, how fresh it is and how much to trust it, and they need clear rules for what to do when trust is low, such as stopping and asking a person. Governed context and lineage turn that from a hope into a check. XenonStack's ElixirData is its Context OS for governed data and decision context.
What should you do first?
- Pick the one dataset that drives your most important decision.
- Trace its sources and note any with no recorded lineage.
- Add validation at ingestion and a trust score per source.
- Decide what an agent or report should do when trust falls below a threshold.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is data veracity in simple terms?
It is how accurate and reliable your data is, and so how far you can trust it when making decisions.
How is data veracity different from data quality?
Veracity is the big data term for trustworthiness of data from many sources. Data quality is the broader practice of measuring and improving it, and the two overlap heavily.
What causes poor data veracity?
Common causes are statistical bias, noise, missing lineage, abnormal readings, software bugs, tampering and human error.
Which tools help check data veracity?
Platforms such as Apache Spark and KNIME help prepare, validate and transform data, but they need rules and ownership around them.
Why does veracity matter for AI agents?
Agents act on data, so unreliable data can lead to unreliable actions. Lineage and trust scores let an agent know when to stop and ask a person.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE