

Key takeaway
- Fog vs edge vs cloud computing in 2026: where each tier processes data, NIST and IEEE definitions, decision rules, governance and when to skip fog.
Cloud, fog and edge computing differ mainly in where data is processed. Edge computing runs on or beside the device that creates the data. Fog computing adds a shared, layered tier of nodes on the local network between those devices and the cloud. Cloud computing runs in central data centres with the most capacity and the longest path to the device.
Many enterprise architectures now combine all three: the edge for millisecond decisions, the fog tier for site-wide aggregation, control and resilience, and the cloud for training, fleet management and long-term analytics. This comparison explains where each tier fits, what the standards say and when a fog layer is not worth adding.
This post focuses on the three-tier comparison. For edge AI types and use cases, see our guide to the intelligent edge and edge AI. To choose a product for each tier, see the edge computing platform guide, and for the two-way view, edge computing vs cloud computing.
What is the difference between edge, fog and cloud computing?
The quickest way to compare the three is by where the work runs, what each tier is good at and what limits it.
| Tier | Where processing runs | Best at | Main limits |
|---|---|---|---|
| Edge | On the device, sensor, camera, controller or a gateway physically next to it | Millisecond responses, local control actions, filtering raw data before it leaves the device | Small compute and storage; each device is managed separately |
| Fog | Shared nodes on the local network: gateways, industrial PCs, on-site servers or network edge sites | Aggregating many devices, site-wide control, short-term storage, operating when the WAN is down | Extra hardware, patching and security at every site |
| Cloud | Central data centres of a public or private cloud provider | Model training, fleet management, long-term storage, cross-site analytics | Longer network path, bandwidth cost, data residency constraints |
What do the standards say about fog computing?
Two reference documents still define the term. NIST SP 500-325, Fog Computing Conceptual Model (March 2018) describes fog computing as a layered model that gives access to a shared continuum of scalable computing resources, with fog nodes placed between smart end devices and centralised cloud services. It also defines mist computing as a lightweight form of fog computing closest to the devices, running on microcontrollers and microcomputers.
In August 2018 IEEE adopted the OpenFog Reference Architecture as IEEE 1934-2018, which describes moving compute, storage, control and networking functions closer to users along the path from the cloud to connected devices.
How does fog computing differ from edge computing in practice?
NIST's annex on the two terms says edge computing runs specific applications in a fixed logical location and gives a direct transmission service, while fog computing is hierarchical, multi-layered and also covers storage, control and data processing acceleration. In practice the difference shows up in five places.
| Dimension | Edge computing | Fog computing |
|---|---|---|
| Scope | One device or a small group of peripheral devices | Many devices across a site or network segment |
| Structure | Single point of processing | Hierarchy of nodes that can pass work up or down |
| Functions | Mostly application logic and inference | Compute, storage, control, networking and orchestration |
| Ownership | Often the device or machine builder | Usually the site, plant or network operator |
| Typical example | A camera that detects a defect and stops a line | An on-site cluster that combines feeds from every line and applies site rules |
Many teams now call the fog tier the "near edge" or "on-site edge". The label matters less than being clear about which decisions run on the device, which run on shared site infrastructure and which wait for the cloud. Our post on edge data management covers how data is filtered and governed across those tiers.
When does each tier fit?
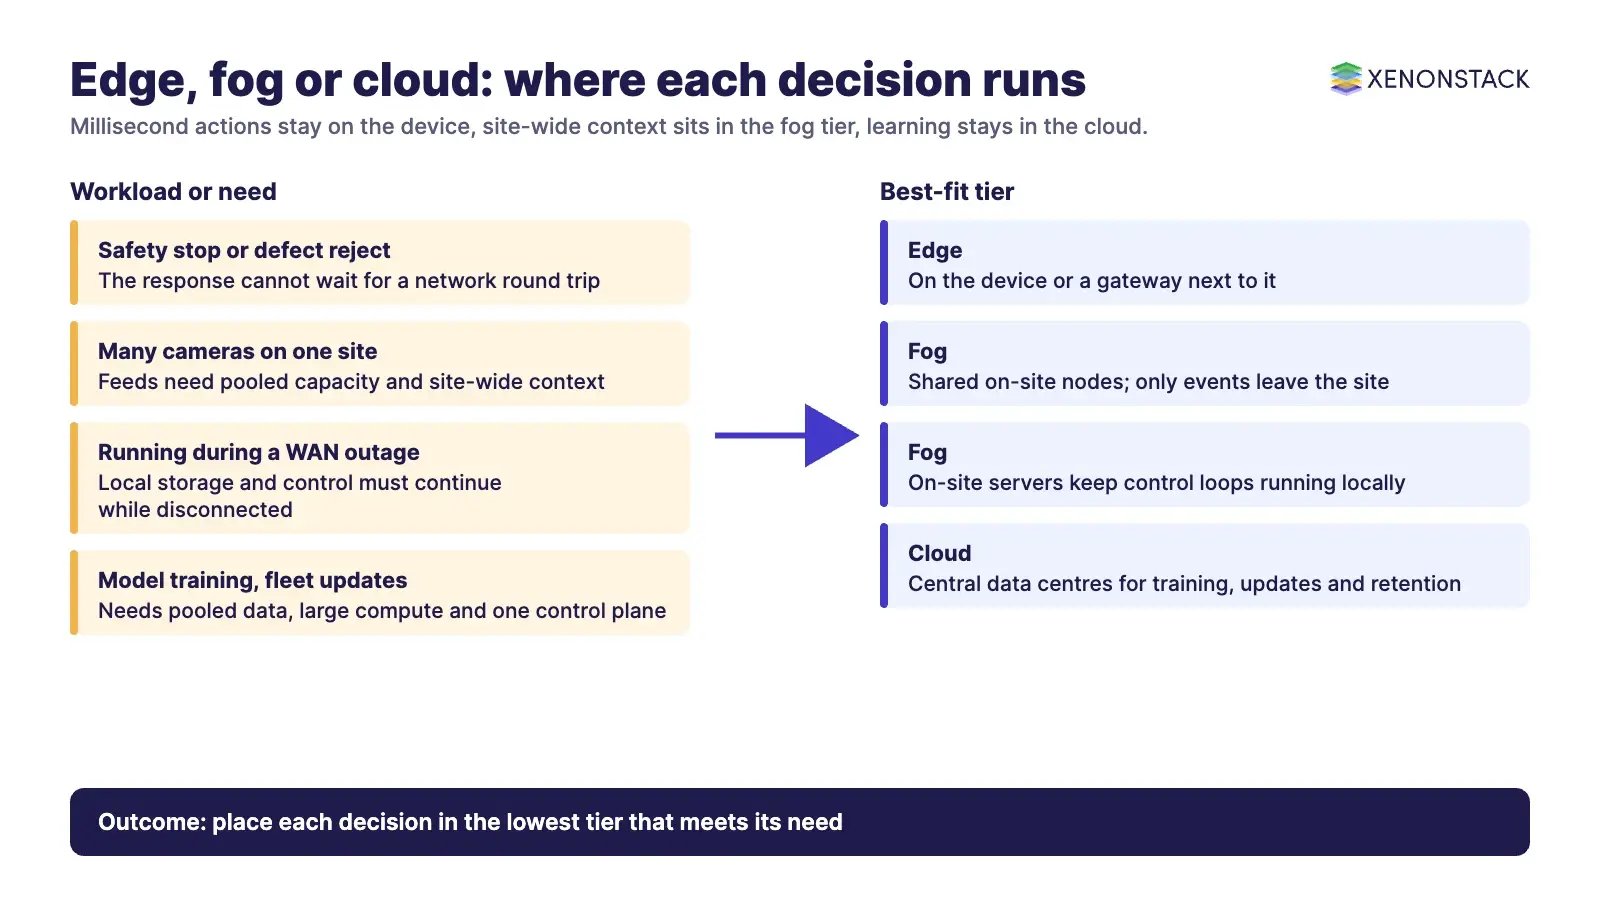
Use the decision rules below as a starting point. Most real systems place different steps of the same workflow in different tiers.
| Workload or need | Best-fit tier | Why |
|---|---|---|
| Safety stop, robot control, defect rejection | Edge | The response cannot wait for a network round trip |
| Video analytics across many cameras on one site | Fog | Pooled GPU capacity and site-wide context; only events leave the site |
| Plant or store keeps running during a WAN outage | Fog | Local storage and control continue while disconnected |
| Mobile or connected-vehicle apps needing low latency | Network edge (5G MEC, Wavelength Zones) | Compute sits in the operator network close to the radio |
| Model training and retraining | Cloud | Needs pooled data and large compute |
| Fleet updates, monitoring and rollback | Cloud | One control plane across all sites |
| Cross-site reporting and long-term retention | Cloud | Central storage and analytics |
Real-time video analytics is a good example of the split: inference runs close to the cameras, the site tier builds one operational picture, and the cloud keeps history and retrains models.
Video: Real-time video analytics, where camera feeds are processed near the site and combined into one live operations picture.
What has changed since fog computing was first defined?
The concept has held up, but the products that deliver it have changed. The table shows the current status of the main options, checked against vendor and standards pages in November 2026.
| Option | What it is | Current status |
|---|---|---|
| Azure IoT Operations | Unified data plane for the edge on Azure Arc-enabled Kubernetes | Microsoft's newer option for site-level (fog tier) workloads |
| Azure IoT Edge | Device-focused runtime for containerised modules | 1.6 LTS supported to 14 November 2028; 1.5 LTS support ended 10 November 2026 |
| AWS IoT Greengrass | Open source edge runtime and cloud service | Version 1 support ended 7 October 2026; use Version 2 |
| Google Distributed Cloud | Managed hardware and software for data centres and edge sites | Connected and air-gapped options |
| KubeEdge | Kubernetes-native edge computing framework | CNCF Graduated on 11 September 2024 |
| ETSI MEC | Standard for edge computing inside operator networks | First Phase 4 specifications released 31 October 2025 |
The other change is the workload. Fog and edge tiers increasingly run AI inference and AI agents rather than simple rules, which raises the stakes on governance. Our guide to 5G edge computing architecture covers the network edge in more depth.
How should you handle governance, security and cost across the three tiers?
Security: every edge device and fog node is a place to patch, harden and monitor. Use signed images, device identity and a single fleet control plane rather than per-site tooling.
Data residency: keep raw personal or sensitive data at the edge or fog tier and send only results or anonymised events to the cloud.
Decision accountability: when an AI model or agent acts locally, record what it saw, which policy applied and what it did, so the action can be reviewed later.
Cost: fog nodes cut bandwidth and cloud processing, but add hardware, power, spares and field support. Compare the full site cost, not only cloud spend.
Resilience: decide what each site must keep doing when disconnected, and for how long, before you size the fog tier.
For local AI decisions, AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need.
How should an enterprise adopt a cloud, fog and edge design?
List the decisions the system must make and the response time each one needs.
Place each decision in a tier using the rules above: edge for millisecond actions, fog for site-wide context and resilience, cloud for learning and oversight.
Decide which data never leaves the site, which leaves as events and which is copied in full.
Choose one control plane for deploying, updating and monitoring every tier.
Pilot on one site with a clear success measure, such as response time, bandwidth saved or uptime during outages.
Add security, logging and rollback before expanding to more sites.
Review the tier placement after the pilot; move work up or down where the numbers show it belongs elsewhere.
For physical AI workloads that span plants, devices and the cloud, NexaStack is an agentic operating platform for physical AI that runs across on-premises, cloud and hybrid environments. Teams building the agents and workflows themselves can use ElixirClaw, an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
What are the trade-offs, and when should you not add a fog layer?
| Choice | You gain | You give up |
|---|---|---|
| Cloud only | Simplest operations, elastic capacity | Latency, bandwidth cost, dependence on the WAN |
| Cloud plus edge devices | Fast local actions without new site servers | Limited local storage and cross-device context |
| Cloud, fog and edge | Site-wide context, resilience, data kept on site | More hardware and operational work at every location |
Skip the fog tier when devices are few, latency is not critical, connectivity is reliable and there is no residency constraint. A direct device-to-cloud design, or devices plus one managed gateway, is easier to secure and cheaper to run.
To map one edge or fog decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is the main difference between edge and fog computing?
Location and scope. Edge computing runs a specific application on or right next to the device, such as a camera, controller or gateway. Fog computing adds a layered tier of shared nodes, usually on the local network, that provide compute, storage, control and networking for many devices at once. NIST describes fog as hierarchical and multi-layered, and edge as limited to a small number of peripheral devices.
Is fog computing still relevant in 2026?
The idea is, even if the label is used less. Vendors now sell the fog tier as edge platforms on site, such as Azure IoT Operations on Azure Arc-enabled Kubernetes, AWS IoT Greengrass V2 or Google Distributed Cloud, and as network edge services such as ETSI MEC and AWS Wavelength. The reference definitions are still NIST SP 500-325 and IEEE 1934-2018.
Does edge or fog computing replace the cloud?
No. In a cloud, fog and edge design, the cloud keeps model training, fleet management, long-term storage and cross-site analytics. Fog and edge tiers handle time-critical decisions, local filtering and operation during network outages.
What is mist computing?
NIST describes mist computing as a lightweight and rudimentary form of fog computing that sits closest to the end devices and runs on microcontrollers and microcomputers. It is optional rather than a mandatory layer.
When should an enterprise not add a fog layer?
When a few devices can talk directly to the cloud or to a single gateway, latency is not critical and connectivity is reliable. A fog tier adds hardware, patching and security work at every site, so it should earn its place through latency, bandwidth, resilience or data residency needs.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE


