Key takeaway
- Data discovery helps business users find, prepare, explore and explain data. See how advanced, AI-assisted discovery works and the controls it needs.
Data discovery is the process business users and analysts follow to find relevant data, prepare it, explore it visually and explain what it shows, so that a question becomes a decision without a long queue for IT or data science. Advanced data discovery adds augmented analytics to that process: machine learning and AI assist with data preparation, insight generation and insight explanation, which is how Gartner defines augmented analytics.
In 2026 the main change is that discovery has become conversational and increasingly agent-led. Power BI Copilot, Tableau Pulse and Databricks Genie now answer plain-language questions, but each one is only as reliable as the semantic model, metrics layer or catalogue permissions behind it. For enterprise leaders, the decision is less about which tool draws the best chart and more about which governed context the answers come from.
This guide covers analytical discovery: exploring data to find patterns and explain them. Finding and registering data assets in a catalogue is a related but separate job, covered in our guides to Azure Data Catalog and Microsoft Purview Unified Catalog and to metadata as a product. The two work together: analytical discovery is only as trustworthy as the catalogue, lineage and glossary it draws on.
What is data discovery, and what makes it advanced?
Traditional reporting gives business users fixed dashboards. When they need to test a hypothesis, change a variable or examine an anomaly, they reach the edge of the dashboard and return to the request queue. Data discovery removes that boundary by letting the person closest to the business question prepare, explore, annotate and share data themselves.
It becomes advanced when the platform does part of the analytical work: it suggests joins, flags data type problems, proposes the visual that best fits the data, detects drivers and outliers, and explains findings in plain language. Gartner's definition of augmented analytics covers exactly this, the use of machine learning and AI "to assist with data preparation, insight generation and insight explanation" so that people can explore and analyse data in analytics and BI platforms. The same definition says it also augments expert and citizen data scientists by automating parts of model development, management and deployment.
| Stage | What the user does | When it fits | Current status |
| Fixed reporting | Reads pre-built dashboards; asks analysts for anything new | Stable, regulated KPIs that must not vary by user | Still needed for statutory and board reporting |
| Visual self-service discovery | Builds and filters visuals, drills into data without code | Trained power users in each function | Mainstream in BI platforms |
| Augmented (advanced) discovery | Gets suggested joins, visuals, drivers, outliers and narrative explanations | Wider business audiences who need insight, not chart building | Built into major platforms, often as paid add-ons |
| Conversational and agent-led discovery | Asks questions in plain language; agents summarise, monitor and suggest actions | Organisations with governed semantic models, metrics and permissions | Mix of generally available and preview features in 2026 |
How does analytical data discovery differ from catalogue discovery?
The term "data discovery" is used for two jobs. Catalogue discovery answers "which data exists, who owns it and can I use it?". Analytical discovery answers "what does this data tell us, and why?". Enterprise customers we work with usually ask for both together: a data catalogue, business glossary, lineage, discovery, observability and quality monitoring, because users stop trusting insights they cannot trace back to a governed source.
| Aspect | Catalogue discovery | Analytical (advanced) discovery |
| Main question | Which data assets exist and can I trust and access them? | What patterns, drivers and exceptions does the data show? |
| Typical users | Data stewards, engineers, analysts searching for sources | Business users, analysts, citizen data scientists |
| Typical tools | Microsoft Purview Unified Catalog, OpenMetadata, Unity Catalog | Power BI, Tableau, Databricks Genie and other BI platforms |
| Output | Metadata, lineage, glossary terms, access requests | Visuals, explanations, forecasts, shared findings |
| Dependency | Feeds analytical discovery with trusted, described data | Relies on the catalogue for meaning, ownership and permissions |
A common open-source reference stack shows how the layers connect. OpenMetadata describes itself as a "unified platform for data discovery, lineage, and governance", and its current documentation is for version 2.0. A catalogue such as this, or Unity Catalog on Databricks, provides the governed foundation that analytical tools query.
What does the data discovery process look like?
Whatever the platform, the data discovery process follows five steps. Augmented and agent-led tools change who does each step and how fast, not the order.
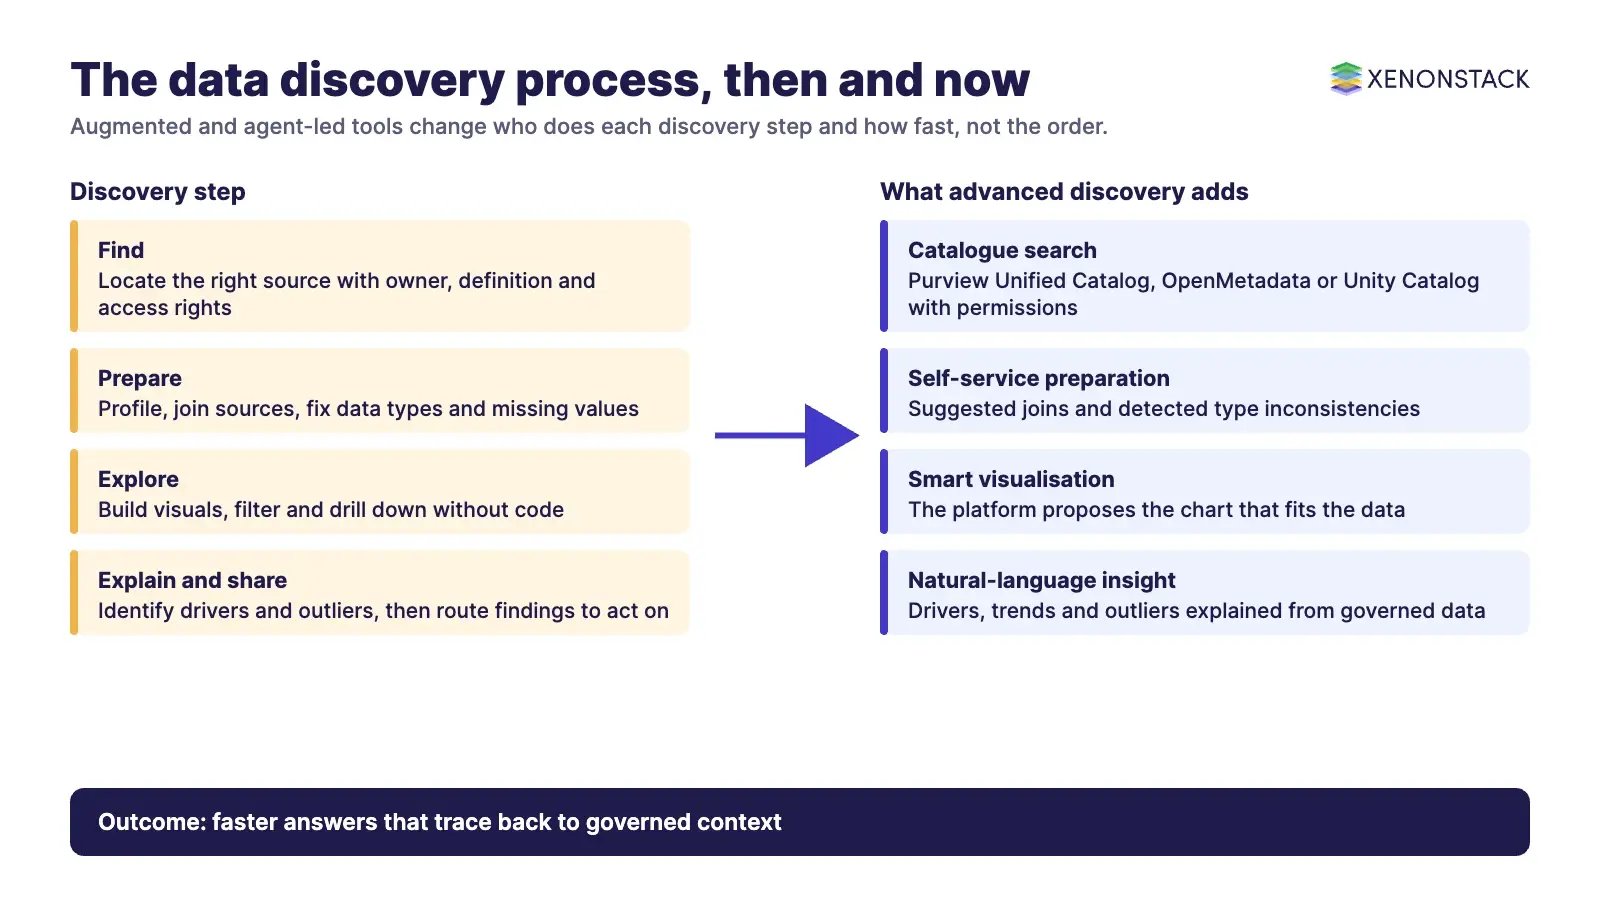
- Find: locate the right source through the catalogue, with owner, definition and access rights visible.
- Prepare: profile the data, join sources and fix types and missing values. Self-service data preparation tools suggest joins and detect inconsistencies. In our own data platform work, a discovery agent profiles new sources to infer their structure and flag or fill missing data before analysts start.
- Explore: build visuals, filter and drill down. Smart visualisation proposes the chart that fits the data's shape and dimensions.
- Explain: identify drivers, trends, contributors and outliers, and describe them in plain language. Predictive models such as clustering, classification and decision trees can be applied without coding.
- Share and act: annotate, publish and route findings to the people or systems that act on them, with a record of how the insight was produced.
The explore and explain steps are where visual analytics does most of the work. Our guide to visual analytics tools compares the software options in more detail.
Video: how visual analytics turns explored data into data-driven decisions (XenonStack).
How does augmented analytics enable advanced data discovery?
Augmented data management and augmented analytics move tasks that once needed statistical expertise into the platform, and present the results in a form business users can interpret. Three capabilities do most of the work.
| Capability | What it automates | What still needs a human |
| Self-service data preparation | Suggested joins across sources, detection of data type inconsistencies, ranking of relevant variables | Confirming that joined entities and business definitions really match |
| Smart visualisation and insight generation | Choosing a suitable chart; detecting drivers, trends, contributors and outliers | Deciding which findings matter for the business question |
| Plug-and-play predictive analysis | Applying pre-built clustering, classification, decision tree and association models to test hypotheses and scenarios | Escalating to data scientists before a model drives a material decision |
| Natural-language explanation | Summarising changes and answering plain-language questions | Checking that answers come from governed data, not general model knowledge |
The result is that much routine analysis moves to the person closest to the business context. This is the operational side of data democratisation: wider analytical capability, not just wider access. For teams that want plain-language analysis on governed enterprise data, AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights.
What has changed in data discovery platforms in 2026?
The leading platforms now combine augmented insight with conversational interfaces, but they ground their answers in different layers. The table summarises what each vendor's own documentation says.
| Platform | Discovery capability | What it is grounded in | Status and requirements |
| Copilot in Power BI | Summarise reports, answer questions about data, search for content; authors get help with reports, DAX and model descriptions | The semantic model; questions outside it are answered from the language model's general knowledge | Copilot pane generally available; standalone Copilot and Copilot in apps in preview. Needs paid Fabric capacity (F2 or higher) or Power BI Premium (P1 or higher); a Pro or PPU licence alone is not enough |
| Tableau Pulse | Insights Platform detects drivers, trends, contributors and outliers for metrics and explains them in natural language; digests by email, Slack and Microsoft Teams | A metrics layer; Tableau states the model does not analyse your data and uses pre-calculated insights | Runs on Tableau Cloud. Tableau Agent in Pulse is a Tableau+ premium feature that needs a Salesforce org with Einstein generative AI |
| Databricks Genie | Business users ask questions in Genie One; data teams configure Genie Agents with datasets, sample queries, instructions, metrics, business rules and verified answers | Organisation data governed through Unity Catalog | Account admins manage budgets and cost controls |
The pattern is consistent: conversational discovery works when data teams curate the semantic model, metrics or trusted datasets first. Without that curation, plain-language answers can look authoritative while drawing on undefined or general knowledge. Our overview of agentic analytics covers how agents extend this into monitoring and follow-up actions.
Which governance, security and cost controls does data discovery need?
Opening analysis to more people, and to AI assistants, widens the ways a wrong number can reach a decision. Each risk needs a matching control before rollout.
| Risk | Control |
| Answers drawn from undefined data or general model knowledge | Curated semantic models, certified metrics and verified answers; tell users which questions are in scope |
| Users seeing data they should not | Enforce permissions in the catalogue (for example Unity Catalog or Purview) so that every tool inherits them |
| Conflicting definitions across departments | A shared business glossary and one metrics layer, owned by named data owners |
| Untraceable insights | Lineage from source to visual, and a record of the question, data and logic behind each shared finding |
| Data residency and AI processing location | Review tenant settings; Microsoft states Copilot is off by default outside the US or EU data boundary unless an admin enables it |
| Unplanned capacity spend | Budgets and cost controls per workspace or account; review AI add-on licensing before broad rollout |
Our leaders summarise the underlying problem simply: organisations have never had more data, yet decisions are getting slower, and the gap only becomes visible when analysts or AI agents are expected to explain why they reached a conclusion. ElixirData Context OS keeps governed context, policy and decision traces in one decision layer above AI agents, so that an insight can be traced back to the context and authority it relied on. Where discovery spans documents as well as tables, AgentSearch provides permission-aware enterprise AI search and retrieval.
How should enterprises adopt advanced data discovery?
- Pick two or three decisions, not a tool. Start with business questions that currently wait days for an analyst.
- Fix the foundation for those decisions. Register the sources in the catalogue, agree glossary terms and owners, and check data quality.
- Curate the semantic layer. Build the semantic model or metrics, with sample questions and verified answers for conversational tools.
- Pilot with a defined group. Train a small group of business users as citizen data scientists and track which questions they can answer alone.
- Add controls before scale. Confirm permissions, lineage, tenant AI settings and cost budgets.
- Expand and measure. Roll out by function and review the outcome measures below each quarter.
Which outcomes should data and analytics leaders measure?
| Measure | What it tells you |
| Time to insight | Cycle time from business question to actionable finding, the main efficiency measure |
| Citizen data scientist growth | Number of business users doing their own analysis each quarter, a leading indicator of data literacy |
| Analytics request deflection | Fall in routine requests to IT or data science, showing capacity freed for complex work |
| Cross-source utilisation | Share of analyses that combine several governed sources, showing depth of adoption |
| Traceable decisions | Share of material decisions backed by a shared, traceable finding rather than intuition |
When is advanced data discovery the wrong choice?
Self-service and conversational discovery are not always the answer. They are a poor fit when:
- Definitions are not agreed. If finance and sales calculate revenue differently, more self-service multiplies conflicting numbers. Fix the glossary and metrics first.
- The output is statutory or regulated. Board packs, regulatory returns and audited figures need controlled, fixed reports.
- The question needs a bespoke model. Plug-and-play predictive features suit hypothesis testing; a model that drives pricing, credit or safety decisions still needs data scientists and model governance.
- Data quality is unknown. Augmented tools surface patterns quickly, including patterns caused by bad data.
For a broader view of how discovery feeds organisational knowledge, see our guide to data intelligence.
To map one data discovery decision your analysts or agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions about data discovery
What is data discovery?
Data discovery is the process of finding relevant data, preparing it, exploring it visually and explaining what it shows, so that business users and analysts can answer questions without waiting for IT or data science teams.
What makes data discovery advanced?
Advanced data discovery uses augmented analytics: machine learning and AI assist with data preparation, insight generation and insight explanation. The platform suggests joins and visuals, detects drivers and outliers, and explains findings in plain language.
What is the difference between data discovery and a data catalogue?
A data catalogue helps users find data assets and understand their meaning, ownership, lineage and access rights. Analytical data discovery uses those assets to find patterns and explain them. Discovery depends on the catalogue for trusted, governed data.
Do conversational tools such as Copilot in Power BI replace data teams?
No. Copilot in Power BI answers from the semantic model, Tableau Pulse from a metrics layer and Databricks Genie from datasets governed through Unity Catalog. Data teams still need to build and curate those layers, and to handle complex modelling.
What should be in place before rolling out advanced data discovery?
Agreed business definitions, catalogued and quality-checked sources, a curated semantic model or metrics layer, permissions enforced in the catalogue, lineage, AI tenant settings and cost budgets.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE