Key takeaway
- Data catalog for Hadoop explained: what HDFS and the Hive Metastore hold, how a catalog adds meaning and ownership, and what changed with cloud catalogs.
A data catalog for Hadoop is an inventory of the data stored and processed on a Hadoop cluster, built from metadata such as table structure, file locations, owners and lineage, so people can find, understand and govern that data. IBM describes a data catalog in general as "a detailed inventory of data assets within an organization" that helps users discover, understand, manage, curate and access data.
This guide is for data engineers, architects and analysts who run Hadoop or a Hadoop style data lake and need to know what to catalogue, which components hold the metadata, and how a modern catalog differs. It builds on our guide to data catalog architecture.
What is Hadoop, and where does its metadata live?
The Apache Hadoop project develops open source software for distributed computing. Its modules include HDFS, "a distributed file system that provides high-throughput access to application data", YARN for job scheduling and resource management, and MapReduce for parallel processing.
Metadata lives in several places. According to the HDFS design guide, the NameNode is "the arbitrator and repository for all HDFS metadata": it maintains the file system namespace and the mapping of blocks to DataNodes, and records every change in a transaction log called the EditLog. That tells you where a file is, but not what a column means or who owns the data. For table level structure, Hive adds its own store.
What does the Hive Metastore add?
The Hive design page describes the Metastore as a metadata repository that holds "all the structure information of the various tables and partitions in the warehouse", including column names and types, the serialisation formats needed to read the data, and the HDFS locations where it lives. It can run as a Thrift service, and third party tools can use that interface to read and change Hive metadata. Its table definitions are therefore a natural source for a catalog to harvest.
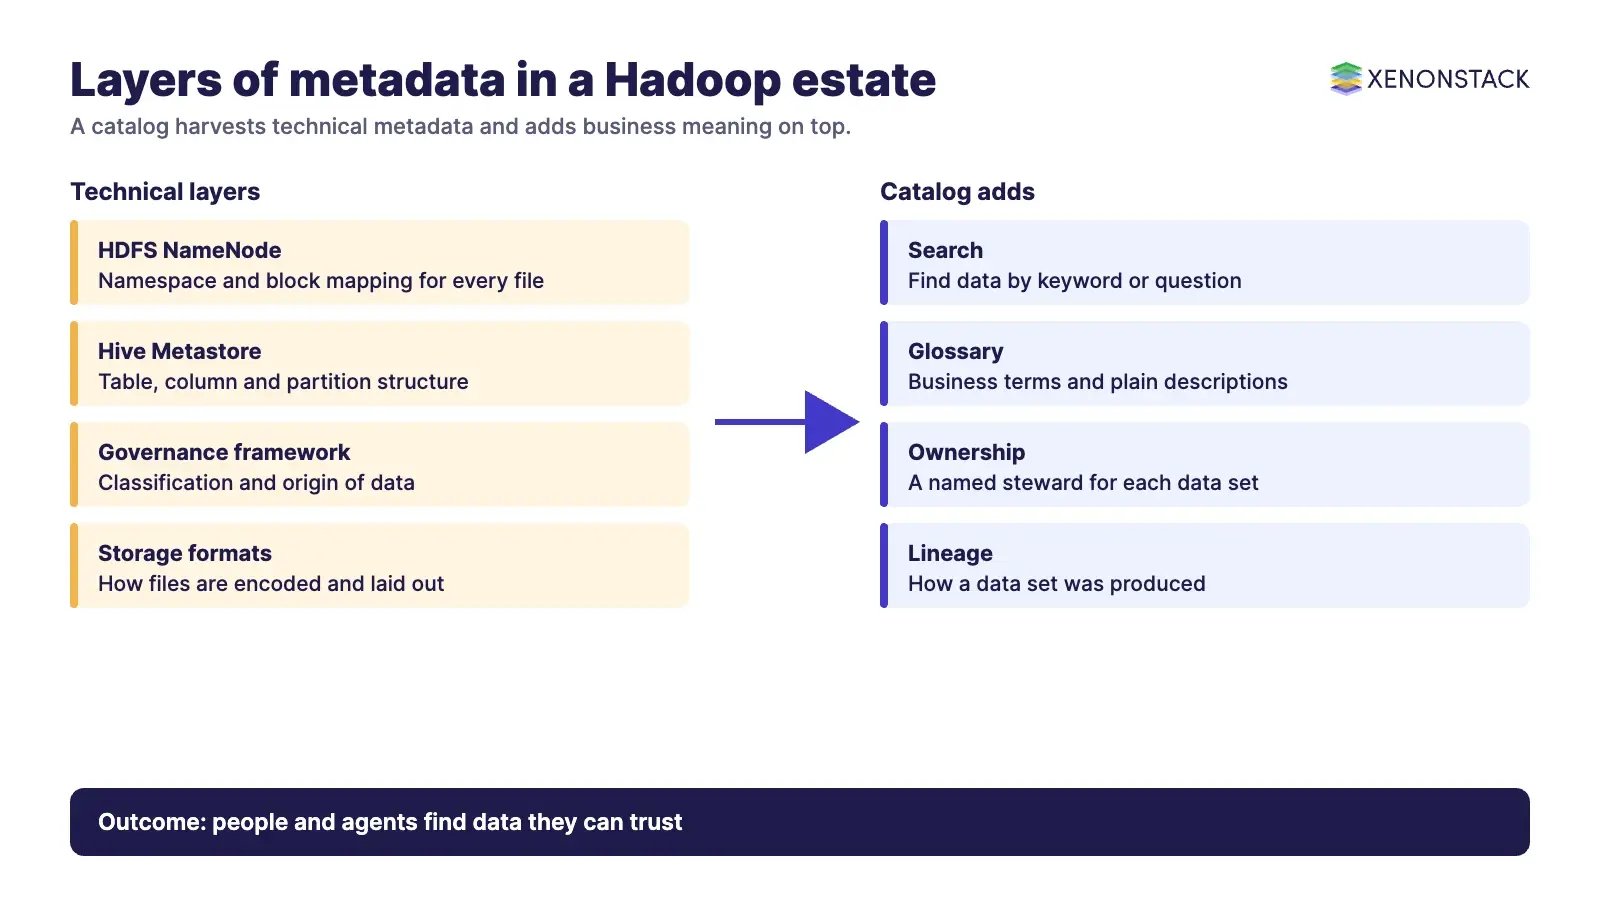
How does a data catalog differ from the metastore and from governance tools?
| Layer | Typical question it answers | Example in a Hadoop estate |
|---|---|---|
| File system metadata | Where are the blocks of this file? | HDFS NameNode namespace |
| Table metadata | What columns and partitions does this table have? | Hive Metastore |
| Governance framework | How is this data classified and where did it come from? | Apache Atlas, described on its site as a "Data Governance and Metadata framework for Hadoop" |
| Business catalog | What does this data mean, who owns it, can I use it? | A catalog with search, glossary, ownership and lineage |
A catalog sits on top of these layers. It harvests technical metadata from them and adds business meaning, search and stewardship. For a fuller view of that design, see data catalog architecture and the use cases of a data catalog in enterprises.
Why does a Hadoop data lake need a catalog?
- Raw files accumulate faster than people can remember what they hold, so analysts spend time searching instead of analysing.
- The same data is often copied to several places; a catalog shows which copy is authoritative.
- Access rules and sensitive fields need a single record of who may use what.
- Storage formats and layouts change over time; recording them avoids broken jobs. See our notes on Hadoop storage formats.
- Migrations are safer when you know what exists. Our guide to Hadoop to Delta Lake migration shows why the inventory comes first.
What should a Hadoop data catalog include?
- Search and discovery across tables, files and streams, as covered in data discovery tools and use cases.
- Harvesting of technical metadata from HDFS, Hive and other sources, kept current as data changes.
- A business glossary with terms, annotations and tags.
- Lineage, so you can see how a data set was produced.
- Ownership and access control for each data set.
- Automation to classify and tag data, with a person approving the results.
How are cloud catalogs changing the picture?
Many teams now run lakes on cloud storage rather than HDFS. The AWS Glue Data Catalog is described as "a centralized repository that stores metadata about your organization's data sets", populated by crawlers that scan data sources. Microsoft states that Azure Data Catalog was retired on 15 May 2024 and points users to Microsoft Purview for data catalog features. Older guidance, including our own Azure Data Catalog article, should be read with that in mind. The skills carry over: harvest metadata, add meaning, assign owners. Practices from DataOps help keep it current.
How do AI agents change the Hadoop data catalog?
An agent that queries a lake needs to know what a table means, whether it is current and whether it may use it. Catalog metadata is that context, so gaps in ownership or definitions become gaps in agent decisions. ElixirData, XenonStack's Context OS, turns catalogue style metadata into governed context for decisions. Our data catalog platform page and streaming data platform page describe the related services.
What should you do first?
- Inventory the Hive databases and HDFS paths that feed your most important reports.
- Name an owner for each, and record a plain language description.
- Harvest technical metadata automatically instead of copying it by hand.
- Mark sensitive fields and who may access them.
- Review the catalog on a schedule and retire data sets nobody uses.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is a data catalog for Hadoop?
It is an inventory of the data on a Hadoop cluster, built from metadata, that helps people find, understand and govern that data.
What is the difference between the Hive Metastore and a data catalog?
The Hive Metastore stores table and partition structure, including column types and HDFS locations. A data catalog adds business meaning, search, ownership and lineage on top of that technical metadata.
Where does HDFS keep its metadata?
The HDFS design guide says the NameNode is the repository for all HDFS metadata and maintains the file system namespace.
Is Azure Data Catalog still available?
No. Microsoft states that Azure Data Catalog was retired on 15 May 2024 and directs users to Microsoft Purview.
Who should own a Hadoop data catalog?
Each data set needs a named owner, and the catalog as a whole needs a team that keeps definitions, access rules and quality checks current.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE