Key takeaway
- Compare Hadoop storage formats: text, SequenceFile, Avro, ORC and Parquet. A decision table, trade-offs and an adoption sequence for data platform leaders.
What are Hadoop storage formats and why do they matter?
A Hadoop storage format is the file layout that decides how records are encoded, compressed and split across a distributed file system such as HDFS. The format you pick shapes how fast engines like Hive and Spark read data, how much space it takes, and how safely its schema can change. The five formats most teams choose between are text (CSV and JSON), SequenceFile, Avro, ORC and Parquet.
For a CTO or data platform lead, this is a cost and reliability decision as much as a technical one: the same dataset stored in the wrong layout is scanned more often, costs more to keep and is harder to govern. This guide compares the formats using their own project documentation. For the serialisation side of the same topic, read our post on data serialisation in Apache Hadoop, and for the table layer that now sits above these files, see our guide to the data lakehouse.
Which Hadoop storage format should you choose?
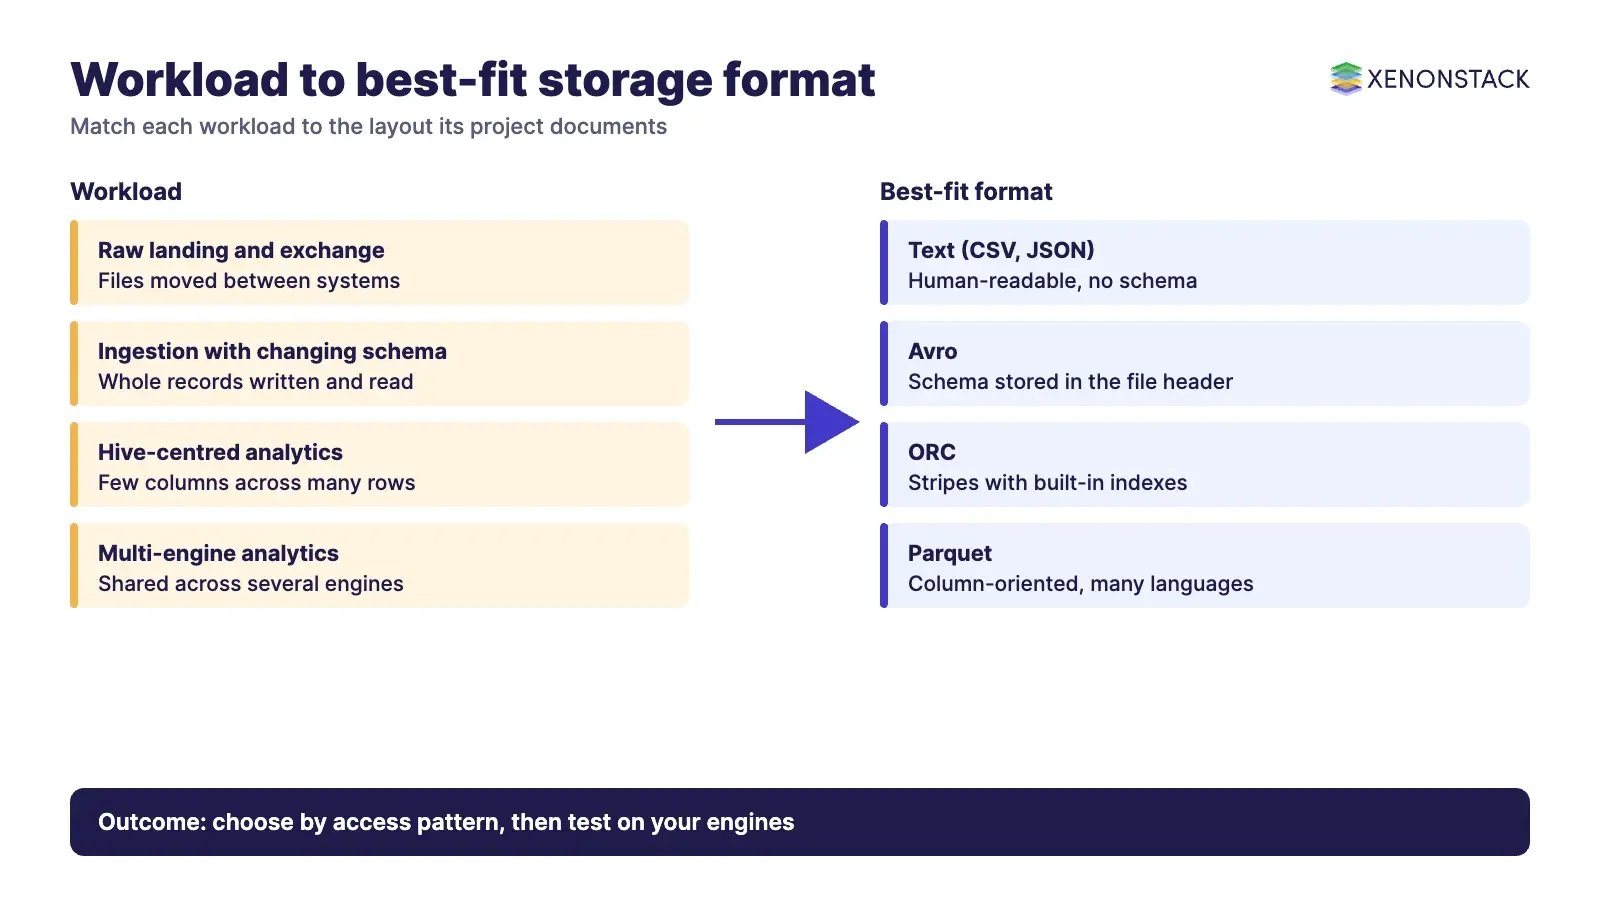
Choose by access pattern first: row-oriented formats suit writing whole records and moving data between systems, while columnar formats suit analytical queries that read a few columns from many rows. The table summarises what each project documents about its own format.
| Format | Layout | What the project documents | When it fits |
|---|---|---|---|
| Text (CSV, JSON) | Row, human-readable | TEXTFILE is the default Hive storage format unless the default is changed (Hive DDL manual) | Landing and exchange of raw data |
| SequenceFile | Row, binary key/value | Flat file of binary key/value pairs with uncompressed, record-compressed and block-compressed variants (Hadoop API docs) | Intermediate data between MapReduce jobs |
| Avro | Row, binary | Schema is stored in the file header as JSON; sync markers between blocks allow files to be split; reader and writer schemas can differ (Avro specification) | Ingestion, staging and data whose schema changes |
| RCFile | Hybrid row and column | Splits rows into row groups, then stores each by column; added in Hive 0.6.0 (Hive wiki) | Existing tables only |
| ORC | Columnar | Self-describing, type-aware format for Hadoop workloads, split into independent stripes with built-in indexes (orc.apache.org) | Hive-centred analytics |
| Parquet | Columnar | Column-oriented format with compression and encoding schemes, supported across many languages and engines (parquet.apache.org) | Analytics shared across several engines |
Hive lists TEXTFILE, SEQUENCEFILE, RCFILE, ORC, PARQUET, AVRO and JSONFILE as valid STORED AS formats; Parquet support arrived in Hive 0.13.0 and Avro in 0.14.0, according to the Hive manual.
How do row-oriented formats work?
Text, SequenceFile and Avro
Text files are easy to inspect and exchange, but they carry no schema and no type information. SequenceFile stores binary key/value pairs behind a common header that begins with the bytes SEQ. In block-compressed files, keys and values are collected into blocks and each block is compressed, with a sync marker per block.
Avro is the stronger choice when schemas change. Per its specification, the schema travels with the data as the avro.schema metadata property, and data written with one schema can be read with another if the two resolve. A field missing from the writer takes the reader's default value, and resolution fails if no default exists. The required codecs are null and deflate; bzip2, snappy, xz and zstandard are optional.
How do columnar formats work?
RCFile, ORC and Parquet
Columnar formats store each column together, so a query that needs three columns does not read the rest. RCFile, described in a 2011 ICDE paper, was the early Hive design for this. ORC was created in January 2013 to speed up Hive and reduce storage in Hadoop; its files hold stripes with a footer, and its indexes carry minimum and maximum values per column, with a row index stride of 10,000 rows by default. Hive's orc.compress setting accepts NONE, ZLIB or SNAPPY and defaults to ZLIB.
Parquet files begin and end with the magic number PAR1. Column chunks are grouped by row group, and the footer metadata locates every column chunk. The footer is written last so data can be written in a single pass, and the Parquet site warns that not all implementations support the same features, so test compatibility when engines are mixed.
What are the trade-offs and when should you not use a columnar format?
- Columnar formats favour reading few columns across many rows. When a workload reads whole records, such as bulk export or staging, a row format like Avro is usually the simpler fit.
- Writing columnar files needs buffering to build column chunks or stripes, so write paths can be heavier than for text or Avro. Measure on your own data before committing.
- Text files cost nothing to produce but leave schema, types and validation to downstream code.
- Feature support differs between engines and versions. Confirm the behaviour you rely on, such as schema changes or compression codecs, in the documentation of each engine you use.
What has changed since the early Hadoop era?
Hadoop is still maintained: the Apache Hadoop site lists 3.5.0 as the latest stable release, dated 2 April 2026. Many teams now keep Parquet or ORC files in object storage and manage them through table layers; our guide to Apache Hudi shows one such layer, and data lake vs warehouse vs lakehouse explains where each fits. The file format still decides scan cost, so the choice remains worth making deliberately.
How should governance, security and cost shape the choice?
- Governance: self-describing formats (Avro, ORC, Parquet) keep the schema with the data, which makes lineage and cataloguing easier than with bare text files.
- Security: file formats do not replace access control. Apply permissions and encryption at the storage and platform layer, and confirm any format-level features on the project page.
- Cost: compression and column pruning reduce bytes stored and scanned. Compare formats on a representative sample before migrating a large dataset.
- Storage layer: the file format sits on top of your storage design. See RAID storage for databases, the software-defined data centre guide and hybrid cloud storage solutions.
What is a sensible adoption sequence?
- List the workloads: ingestion, staging, interactive analytics, exports.
- Land raw data in Avro or text, and publish curated analytical tables in ORC or Parquet.
- Test two candidate formats on a sample with your real engines and queries.
- Record the chosen format, compression codec and schema rules in your data catalogue.
- Schedule conversions with an orchestrator; our Apache Airflow guide covers one option.
Once the data is in a queryable format, people want to ask questions of it directly. AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights, while ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents.
To map one data decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is the difference between Parquet and ORC?
Both are columnar. ORC is described as a self-describing, type-aware format designed for Hadoop workloads, with stripes and built-in indexes. Parquet is a column-oriented format supported in many languages and analytics tools. Check which engines you use, because feature support varies.
When should I use Avro instead of Parquet?
Use Avro when records are written and read whole, for example at ingestion, and when the schema changes, since Avro stores its schema in the file header and resolves differences between writer and reader schemas.
Are Hadoop storage files splittable?
Avro documents sync markers between blocks that permit efficient splitting for MapReduce, and ORC stripes are independent units of work. SequenceFile places sync markers in the file. Confirm splitting behaviour for your codec and engine in its documentation.
Which compression codecs does Avro support?
The Avro specification requires null and deflate, and lists bzip2, snappy, xz and zstandard as optional codecs.
Is Hadoop still maintained?
The Apache Hadoop site lists release 3.5.0 as the latest stable release, dated 2 April 2026.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE