Key takeaway
- Compare Avro, Parquet and ORC for Hadoop data serialization: when each fits, schema evolution, current Apache project status and how to adopt them.
Data serialization in Hadoop means turning records into bytes so they can be stored in HDFS or sent between systems, and reading them back without loss. For most enterprise data lakes the choice comes down to three formats: Avro (row-oriented, schema travels with the data, best for ingestion and exchange), Parquet and ORC (both columnar, best for analytics). Plain text and CSV remain useful for debugging but are a poor fit at scale.
For CTOs and data platform leads, the decision is less about speed benchmarks and more about schema change, engine support and who owns the schema. This guide gives a decision table, the current status of each project from its own Apache page, and an adoption sequence. For the wider storage question, see our guide to best practices for Hadoop storage formats.
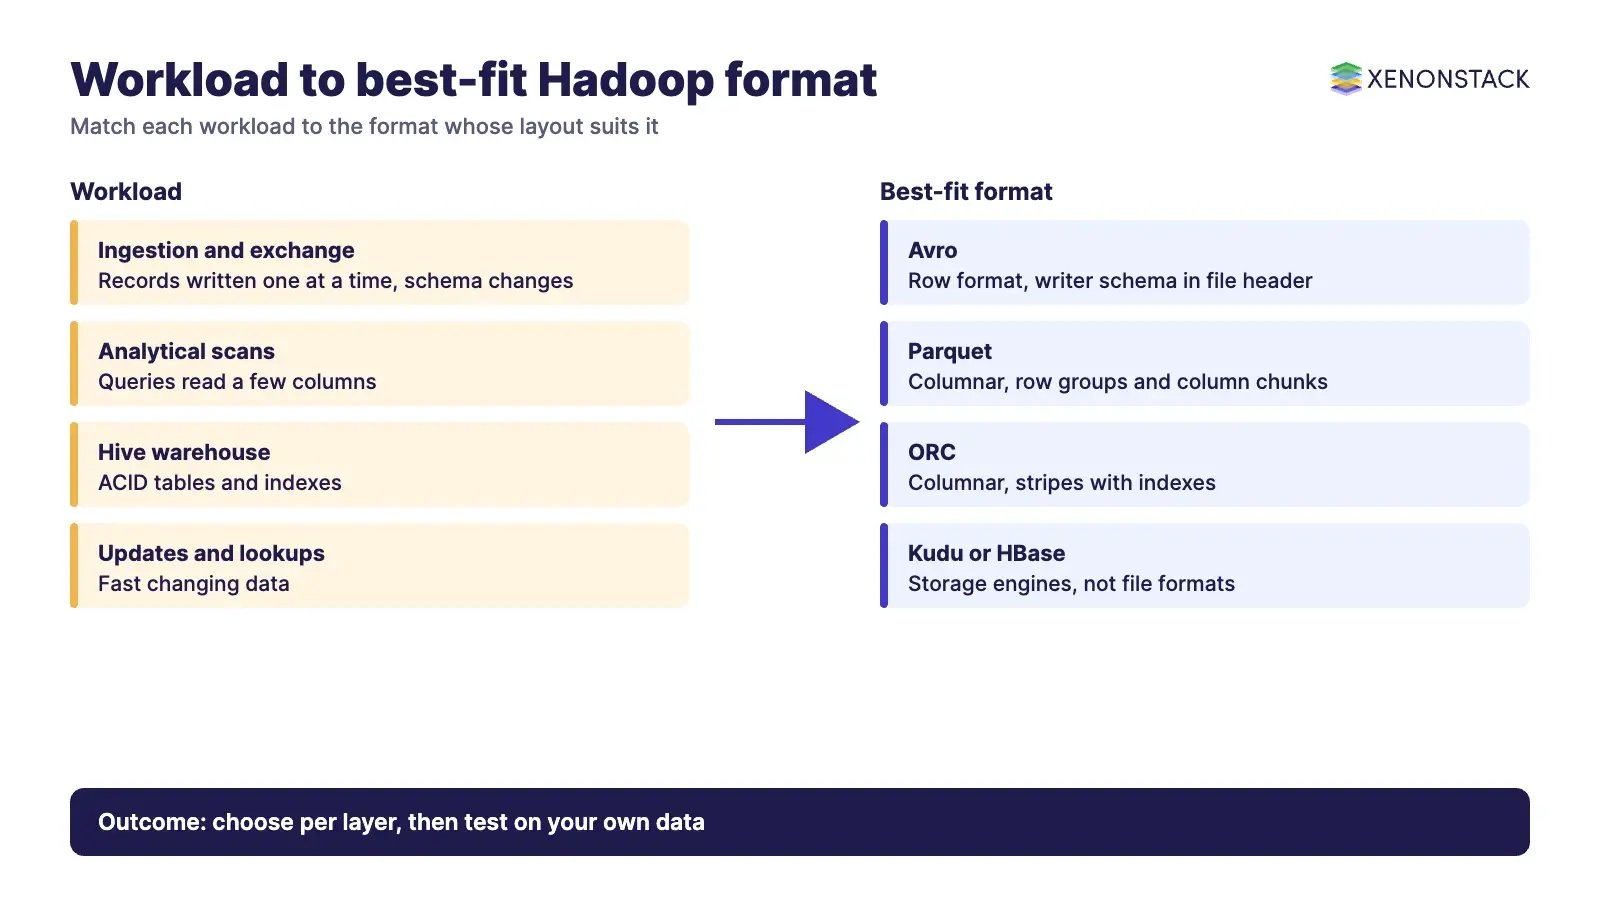
Which Hadoop file format fits which workload?
| Format | Layout | Fits when | Watch for |
|---|---|---|---|
| Text / CSV | Row, no schema | Debugging, small hand-off files | No schema, commas inside values break parsing |
| Avro | Row, schema in the file header | Ingestion, streaming, exchange, schema change | Less efficient than columnar for wide analytical scans |
| Parquet | Columnar, row groups and column chunks | Analytical queries across many engines | Footer metadata is written at the end, so a failed write can lose the file |
| ORC | Columnar, stripes with indexes | Hive-centred warehouses, ACID tables | Strongest in the Hive ecosystem; check support in other engines |
| Kudu / HBase | Storage engines, not file formats | Fast updates and random lookups | Different operating model from file formats |
What does serialization actually do in Hadoop?
Serialization translates a data structure into a stream of bytes that can be stored or transmitted regardless of the system that produced it. Deserialization reverses it. A good format for Hadoop is compact (bandwidth and storage), fast (low overhead), extensible (new fields without breaking readers) and interoperable (not tied to one language). Java's built-in serialization is neither compact nor language-neutral, which is why the Hadoop ecosystem uses purpose-built formats.
Delimited text shows the risk plainly: a comma inside a value breaks the record on read unless quoting rules are applied consistently. Formats that carry a schema avoid this because types and field boundaries are defined, not guessed.
What is Apache Avro and when should you use it?
Avro is a row-oriented serialization system. Per the Avro specification, each object container file stores the writer's schema as JSON in its header, along with a sync marker that lets readers find record boundaries. Schemas are JSON strings, objects or arrays (unions), so no code generation is required to read them.
How does Avro handle schema evolution?
- Data is written with the writer's schema and can be read with a different reader schema if the types match or a permitted promotion applies (for example int to long).
- Records match fields by name. Writer-only fields are ignored; reader fields missing from the writer take their default.
- A reader field with no default and no writer counterpart is an error, so defaults are the main governance control.
- Codecs: null and deflate are required; bzip2, snappy, xz and zstandard are optional.
- Logical types such as decimal, date, uuid and timestamps annotate an underlying type; readers ignore unknown ones.
Avro suits ingestion and messaging because the schema is explicit and compact binary encoding keeps records small. Our guide to data ingestion tools and pipelines covers where this fits in the pipeline. Apache Avro's own home page lists releases up to 1.12.x; check the download page for the version you deploy.
What are Apache Parquet and ORC, and how do they differ?
Both are columnar: values of one column are stored together, so a query reading three columns of fifty touches a fraction of the data, and similar values compress well. A table with rows r1(c1,c2,c3) is stored as c1(r1,r2,r3), c2(...), c3(...).
Apache Parquet
The Parquet project describes it as an open source, column-oriented data file format for efficient storage and retrieval, with compression and encoding schemes for complex data. Per the file format page, columns are split into row groups, each holding one chunk per column, and file metadata is written after the data to allow single-pass writing. The trade-off: the footer ends the file, so an interrupted write can leave an unreadable file. Write in finished batches and validate files after landing.
Apache ORC
The ORC project describes it as columnar storage for Hadoop workloads with support for ACID transactions and snapshot isolation. Per its documentation, files are divided into stripes (about 64 MB by default) that can be processed independently, writers build indexes that let readers skip stripes, and row indexes can narrow a search to blocks of 10,000 rows. ORC was created in January 2013 to speed up Apache Hive and cut storage size, and it supports all Hive types including structs, lists, maps and unions.
What is the current status of each project?
Status below is read from each project's own Apache page on 12 November 2026.
| Project | Current status | Source |
|---|---|---|
| Apache Avro | Active; download page lists 1.12.2 (no release date given on the page) | avro.apache.org |
| Apache Parquet | Active; parquet-java 1.18.0 listed 11 August 2026 and parquet-format 2.14.0 listed 11 September 2026 | parquet.apache.org |
| Apache ORC | Active; ORC 2.3.1 released 16 July 2026, with 1.9.9 on 8 July 2026 | orc.apache.org |
| Apache Hive | Active; Hive 4.2.1 on 24 August 2026 is a bugfix release that patches three security flaws, one in Avro SerDe schema URL handling | hive.apache.org |
| Apache Kudu | Top-level project; latest release 1.18.1 on 9 January 2026 | kudu.apache.org |
| Apache HBase | 3.0.0 listed 5 August 2026; 2.6.7 and 2.5.16 listed 1 October 2026, with 2.5.16 marked as the stable release | hbase.apache.org |
Note that the Hive release notes include a fix in Avro SerDe schema URL handling. Schema locations are an input to your platform, so treat them as a security surface and patch Hive on a schedule.
What has changed since older Hadoop guides were written?
- Hive's current release lists ACID transactions, Apache Iceberg support and LLAP among its main components, so table formats now sit above file formats in many designs.
- Parquet and ORC are still maintained actively, with releases in 2026; there is no single winner across all engines.
- Older comparisons that quote percentage savings or speed ratios depend on data shape and hardware. We have left such figures out because no current primary source confirms them; benchmark on your own data.
How do you choose and adopt a format?
- Classify workloads: ingestion and exchange, analytics, random lookup, archive.
- Pick per layer: Avro for landing and streaming; Parquet or ORC for curated analytical tables; Kudu or HBase only where updates and lookups need them.
- Test on your data: compare file size, scan time and write time with your engine and codec (Snappy, zstd).
- Own the schema: store schemas in a registry or repository, version them, and require defaults for new fields.
- Validate on landing: check record counts and schema conformance, as described in our guide to data validation testing and big data testing.
What are the governance, security and cost considerations?
- Governance: a schema change is a contract change. Record who approved it and which consumers it affects.
- Security: protect schema locations, patch SerDe libraries, and apply access control at table and HDFS level.
- Cost: columnar formats with compression cut storage and scan volume; row formats cost more to scan but are cheaper to write. Measure both.
Once data is stored consistently, the next question is who or what may act on it. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights.
When should you not use these formats?
- Do not use Parquet or ORC for single-record streaming writes; land in Avro first and compact in batches.
- Do not use Avro for wide analytical scans where only a few columns are read.
- Do not use text or CSV for anything with nested data or embedded delimiters.
- Do not pick a format only because a benchmark favoured it on someone else's data.
To map one data decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
Which file format should a Hadoop data lake use for analytics?
For read-heavy analytics, a columnar format such as Parquet or ORC is the usual choice, because queries read only the columns they need. Parquet is described by its project as a column-oriented format supported by many languages and analytics tools. ORC was created in 2013 to speed up Apache Hive and reduce storage size.
When is Avro the better choice?
Avro suits record-at-a-time work such as ingestion, messaging and exchange between systems, because each file carries its writer schema as JSON and readers can resolve it against a different reader schema.
Can a schema change without rewriting old data?
In Avro, yes within the resolution rules: fields are matched by name, a reader field missing from the writer takes its default, and writer-only fields are ignored. A reader field with no default and no writer counterpart is an error.
Is Apache Kudu still maintained?
Apache Kudu describes itself as a top-level Apache project, and its releases page lists version 1.18.1 dated 9 January 2026. It is a distributed storage engine, not a file format, so it complements file formats rather than replacing them.
Does serialization change how data should be governed?
The format does not carry business meaning. Schemas, versions and access policy still need an owner, so treat each schema as a governed asset with a version history and an audit trail.
What is the safest way to pick a format?
Test your own queries on a sample of your own data, with your engine and compression codec, before committing. Results depend on data shape, engine and hardware.
Related reading: Apache Hive security with Kerberos and NexaStack, an agentic operating platform for physical AI that runs across on-premises, cloud and hybrid environments.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE