Key takeaway
- Big data testing strategy: how to test ingestion, processing, storage and migration, which tools automate data quality, and how to adopt it step by step.
Big data testing is the set of checks that prove a data platform ingests, processes, stores and serves data correctly at scale. A workable strategy tests the data itself at each stage of the pipeline (ingestion, processing, storage, output), then tests performance, migration and the end-to-end workflow, and automates as much of it as possible.
For enterprise leaders the point is trust: analytics and AI agents are only as reliable as the data beneath them. This guide sets out the stages, the checks at each one, the tools, and how to adopt the approach in sequence. It builds on our guides to data validation testing, unit testing and API testing.
What is big data testing?
Big data testing verifies the accuracy, completeness, consistency and performance of applications that handle data too large or varied for traditional tools: structured tables, logs, sensor streams, images and documents. Unlike conventional application testing, much of the work is on the data, not the screen. The main test types are:
- Database testing: data is stored, retrieved and queried correctly.
- Infrastructure testing: the hardware, software and network that support the platform behave as designed.
- Performance testing: throughput and processing speed hold under load.
- Functional testing: the system meets business and technical requirements end to end.
The challenges that make this hard (volume, variety, velocity, quality) are covered in Big Data Challenges and Solutions.
What are the stages of a big data testing strategy?
Test each stage of the pipeline in order, so a defect is caught where it was introduced and not where it was noticed.
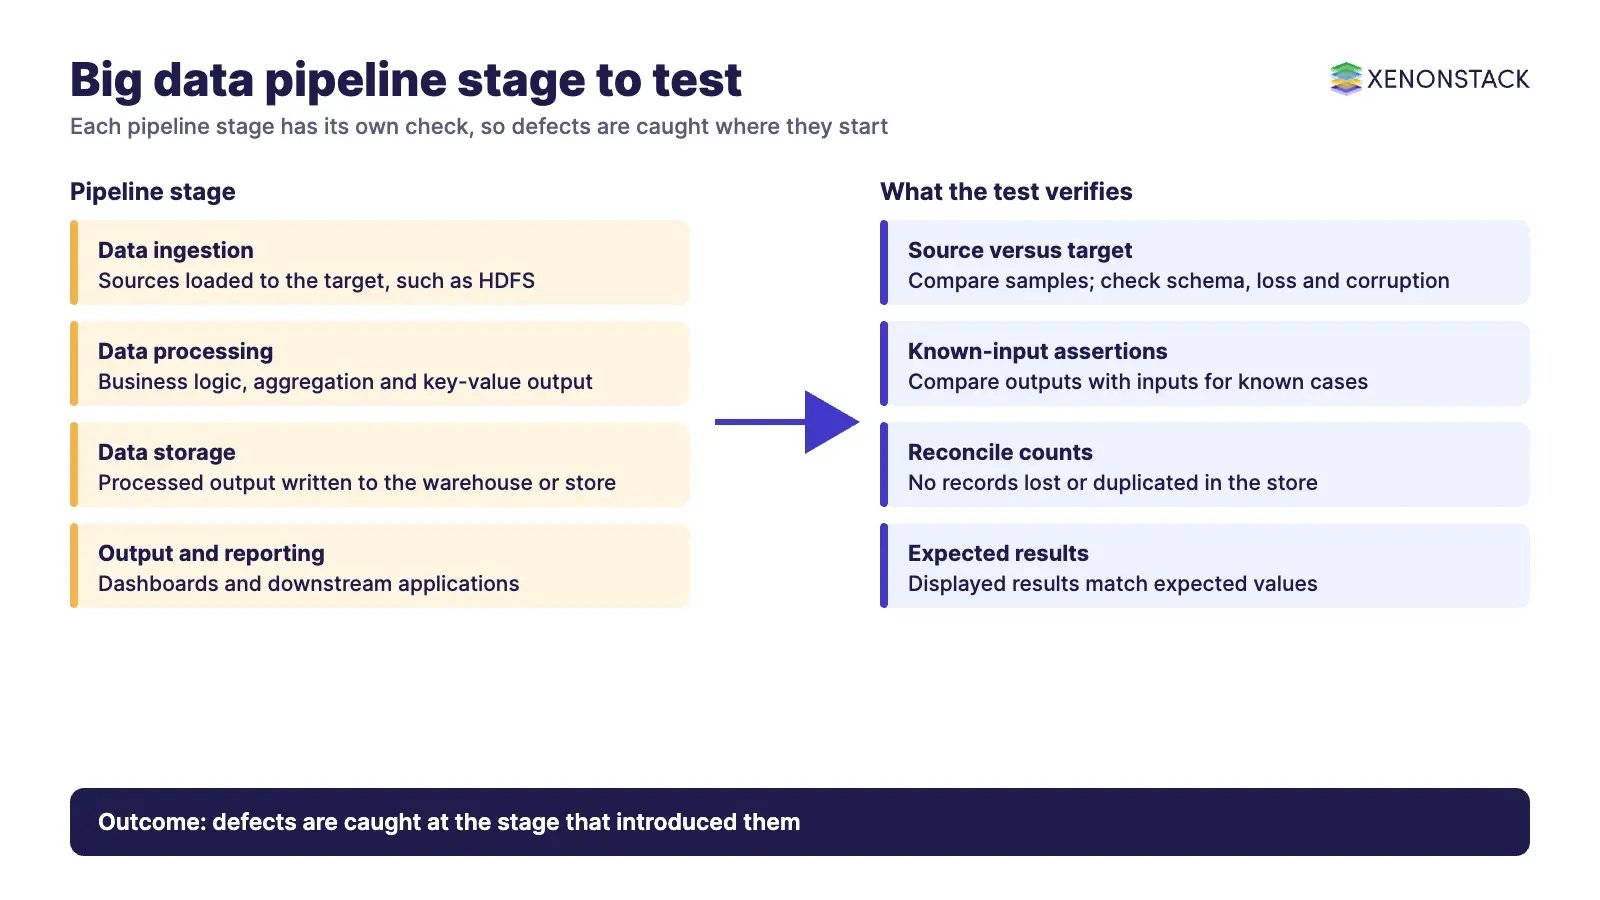
| Stage | What to verify | Typical tools |
|---|---|---|
| Data ingestion | Data is extracted from sources and loaded to the target (for example HDFS) without loss or corruption, and matches the defined schema. Compare a sample of source data with the ingested data. | Kafka, Sqoop, Flume, Apache ZooKeeper |
| Data processing | Business logic, aggregation and key-value generation are correct. Compare outputs with inputs for known cases. | Hadoop, Spark, Hive, Oozie |
| Data storage | Output in the warehouse or store equals the processed output; no records lost or duplicated. | HDFS, HBase |
| Output and reporting | Dashboards and downstream applications show results that match the expected values. | BI tools; see data visualization |
How do you test data ingestion, processing and storage?
Ingestion
Check row counts, schema conformance and checksums between source and target. According to its design documentation, the HDFS client implements checksum checking on the contents of HDFS files, so corruption in storage can be detected, but you still need to compare source with target to catch loss before or during the load. For streams, define the delivery guarantee you expect (at most once, at least once or exactly once) and test duplicates and gaps against it.
Processing
Run the same job on a small, known input and assert the output: aggregations, joins, filters and key-value pairs. Test edge cases deliberately (nulls, late data, skewed keys, malformed records). Keep the expected results under version control so every change to business logic is checked.
Storage
Reconcile counts and totals between the processed output and the stored data. HDFS is, according to its documentation, designed more for batch processing than interactive use, with write-once-read-many semantics, so test appends and re-runs for duplicates. For columnar formats, test schema changes: Spark documents that Parquet supports schema evolution, that merging schemas is off by default because it is relatively expensive, and that it is enabled with the mergeSchema option, so check that new columns appear as intended.
How do you test data migration?
Migration testing applies when data moves to a new platform or technology. The aim is minimal downtime and no data loss, in three phases:
- Pre-migration: fix the scope, record table counts and record counts, and list what is included and excluded.
- Migration: check hardware and software configuration on the new system and the connectivity between components while the move runs.
- Post-migration: confirm all data arrived, nothing is lost or duplicated, and functionality is unchanged.
Planning a larger move? See data center migration.
How do you performance test a big data platform?
Performance testing (see performance testing tools and practices) looks for architectural bottlenecks before production does. Focus on three areas:
- Data loading and throughput: the rate at which data is consumed from sources and written to the store.
- Data processing speed: how quickly jobs complete as volume grows.
- Sub-system performance: each component tested on its own to find where the bottleneck sits.
Functional and integration testing then covers the whole workflow, from big data ingestion to the front-end application, comparing displayed results with expected ones.
How do you automate data quality checks?
Manual comparison does not scale, so express checks as code that runs on every pipeline run. Deequ, an AWS Labs library built on Apache Spark, describes itself as unit tests for data: you define constraints (completeness, uniqueness, allowed values), it computes quality metrics as Spark jobs, and it can flag anomalies in metrics over time. Great Expectations is a Python library with a documented Expectations gallery for the same purpose. Pair these with shift-left testing so checks run early, at the point data is produced.
| Tool | Used for | Source |
|---|---|---|
| HDFS, Hive, HBase | The storage and query layers under test | Apache Hadoop documentation |
| Deequ | Constraint-based data quality checks on Spark | AWS Labs repository |
| Great Expectations | Python expectations for data validation | GX documentation |
How do you adopt big data testing in your organisation?
- Integrate live sources. Data arrives from many systems, so run end-to-end tests against realistic feeds.
- Validate data. Compare source data with what landed in the target.
- Validate processing. Check MapReduce or Spark logic, business rules, aggregation and key-value generation.
- Validate output. Confirm no corruption, successful loading, preserved integrity, and a match with the target data.
- Automate and schedule. Run the checks on every change and every load.
What are the best practices, and when does this approach fall short?
- Base tests on requirements and a clear objective.
- Prioritise fixing defects by business impact.
- Automate repeatable checks to save time.
- Keep test context, communication and technical skills in the team.
Trade-offs: full-volume tests are costly, so sample intelligently and reserve full runs for release gates. Source-to-target comparison proves data moved faithfully, not that the source was right, so add business-rule and quality checks as well.
Governance matters as testing matures: for AI agents that act on this data, a test result should be traceable to the policy it enforces. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents. AgentQA is described on its page as quality assurance for agent workflows, outputs and regression risk, and ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
Concluding the Holistic Strategy
To map one data-quality decision your agents rely on, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is big data testing?
Big data testing verifies the accuracy, completeness, consistency and performance of applications that process very large or varied data, by checking each stage of the pipeline: ingestion, processing, storage and output.
What are the types of big data testing?
Common types are database, infrastructure, performance and functional testing, plus data migration testing when data moves to a new system.
How do you test data ingestion?
Compare a sample of source data with the ingested data, check the schema and look for corruption, loss and duplicates between source and target.
Which tools are used for big data testing?
Teams test on the platform components themselves (HDFS, Hive, HBase, Spark) and use data quality libraries such as AWS Labs Deequ and Great Expectations to automate checks.
What are the phases of data migration testing?
Pre-migration (scope and record counts), migration (configuration and connectivity) and post-migration (completeness, no loss, functionality unchanged).
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE