Key takeaway
- Database testing explained: what to test, structural, functional and non-functional types, tools for SQL Server, Oracle and PostgreSQL, and limits.
Database testing checks that the data layer of an application stores, changes and returns data correctly. It covers the schema, constraints, transactions, stored procedures, triggers and the behaviour of the database under load. A failure here rarely looks like a crash. It usually looks like a wrong balance, a duplicate customer or an orphaned record that nobody notices for weeks.
This guide is the overview for engineering and data leaders: what to test, which type of test finds which fault, which tools fit which database, and where the limits are. For the hands-on view of writing unit tests for SQL, schemas and dbt models, see database unit testing. For checking the data itself, see data validation testing.
What does database testing cover?
Most database faults sit in one of seven places. The table below maps each one to the check that exposes it. The constraint types are those documented for PostgreSQL; other engines name them similarly, so confirm the details in your own database documentation.
| Component | What you check | Example check |
|---|---|---|
| Schema | Tables, columns, data types and keys match the design and the application code | Compare the live schema with the version in source control |
| Field constraints | Check, not-null, unique, primary key, foreign key and exclusion constraints reject bad data | Insert a row that breaks each rule and confirm it is refused |
| Referential integrity | Every non-null foreign key value matches a row in the referenced table | Try to create an order for a product that does not exist |
| Transactions | Concurrent work gives the results the chosen isolation level promises | Run two sessions against the same rows and compare the outcome |
| Stored procedures and functions | Given known inputs, they return the expected rows or side effects | Call the procedure with normal, empty and boundary inputs |
| Triggers and views | Side effects fire once, on the right events, and views return the right rows | Update a row and read the audit table the trigger writes to |
| Migrations | A change moves the database from one version to the next without losing data | Build a copy from scratch, apply the migration, compare with the expected state |
Source for constraint definitions: PostgreSQL documentation, Constraints (read 13 Nov 2026).
What are the types of database testing?
Database testing is not one technique. It combines structural checks on objects users never see, functional checks from the point of view of the application, and non-functional checks on speed, load and security. The split below follows how most test plans are organised.
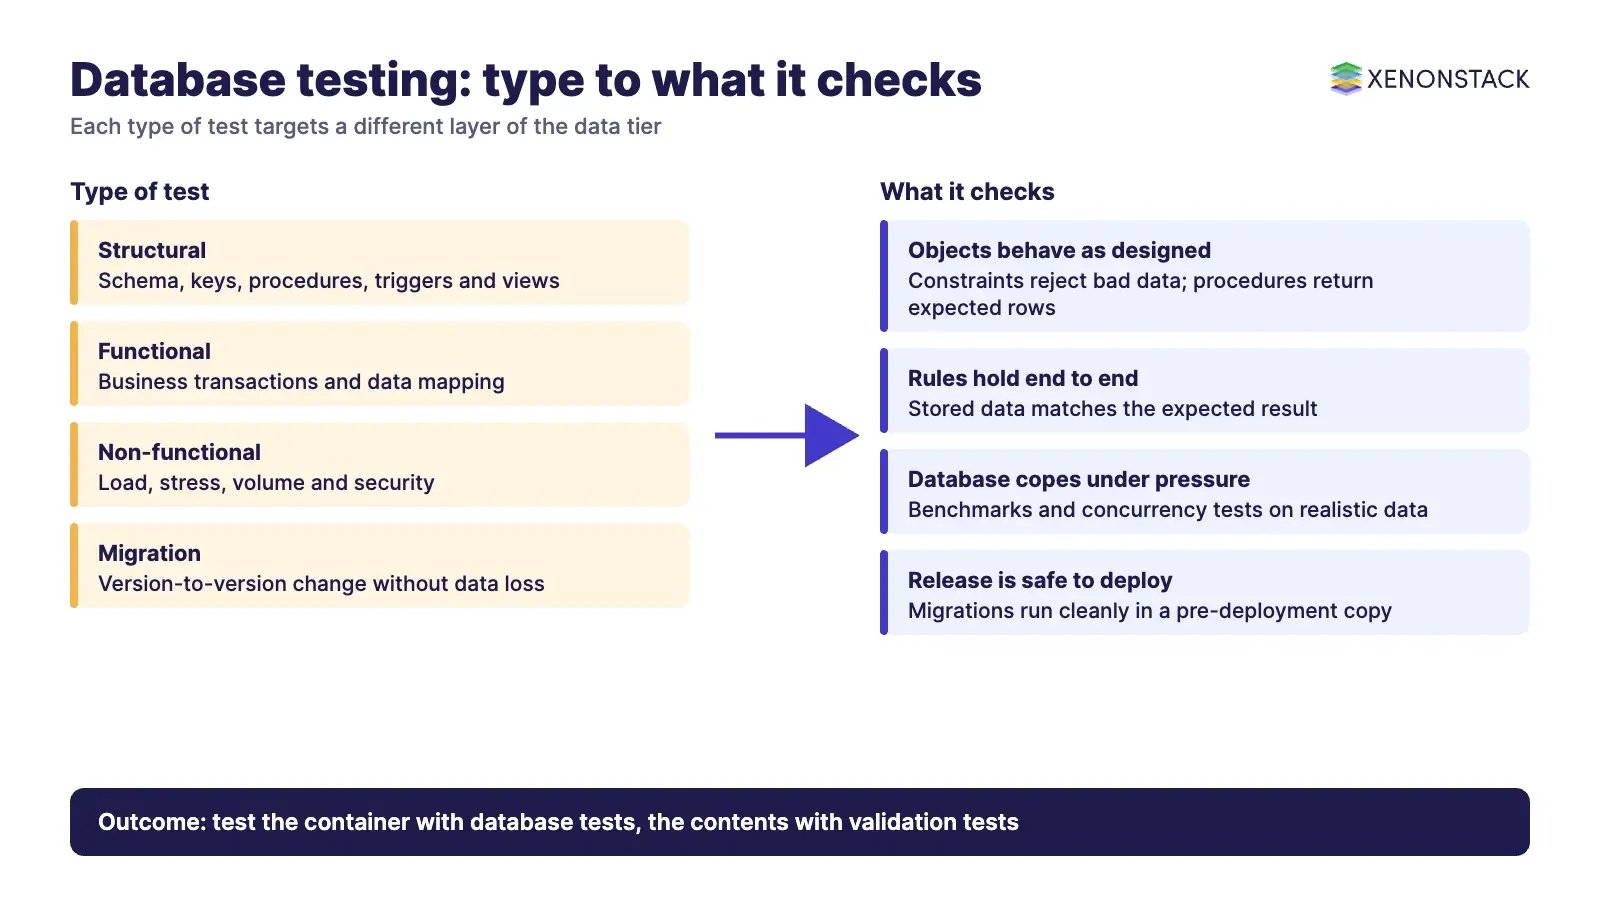
| Type | What it tests | Typical techniques |
|---|---|---|
| Structural | Schema, mapping between application objects and tables, stored procedures, triggers and views | SQL assertions on catalogue and data; needs testers who know SQL |
| Functional | Whether transactions and data flows meet the business requirement | Data mapping checks, stored-versus-retrieved comparisons, boundary values |
| Non-functional | Load, stress, volume and security | Load and benchmark runs, injection and permission checks |
Structural database testing
Structural testing verifies objects that end users never touch directly. It is closest to white box testing, because the tester reads the schema, procedures and triggers and designs tests from them. Typical checks are that every table has the keys the design requires, that a stored procedure returns the expected rows, and that a trigger writes its audit row once.
Functional database testing
Functional testing starts from the business rule: a transfer must debit one account and credit another, or neither. The tester drives the rule through the application or through SQL and compares what was stored with what was expected. This is black box work, so techniques such as equivalence partitioning and boundary value analysis apply.
Non-functional database testing
Non-functional testing asks how the database behaves under pressure. Load testing uses many simultaneous users, stress testing pushes beyond the expected limit, volume testing grows the data, and security testing looks for injection and over-broad permissions. Tools such as HammerDB (see the tools section) generate benchmark workloads for this purpose.
Which database should you test against?
Where you run a test decides how safe and how realistic it is. The four environments below are common practice, not a standard, so adapt them to your own release process.
| Environment | What it is for | Watch out for |
|---|---|---|
| Local development | Fast, isolated tests of schema and procedures while code is written | Small data hides performance and edge-case faults |
| Shared populated development | Checks that the application copes with a realistic volume of data | Tests can interfere with each other; reset it on a schedule |
| Pre-deployment | Confirms that all migrations apply cleanly before release | Must match production version and configuration |
| Production | Live data; read-only monitoring and smoke checks only | Never run destructive or load tests here |
Realistic test data matters as much as the environment. Where real customer data is sensitive, use masked or generated data that keeps the same formats and distributions. The post on test data management covers how to supply test data in the right amount, quality and format.
How does a database test run?
Whatever the tool, a reliable database test follows the same loop:
- Put the database into a known state, either by loading a dataset or by running inside a transaction that is rolled back.
- Run the action under test: a query, a procedure call, a migration or a batch job.
- Compare the actual result with the expected result.
- Report pass or fail, then restore the known state so the next test starts clean.
Frameworks automate this loop. DbUnit, for example, says on its site that it puts the database into a known state between test runs and checks that data matches an expected set of values. tSQLt runs each test inside a transaction. pgTAP's xUnit-style runner rolls back schema changes after each test. Each of these removes the clean-up work that makes manual database tests slow and flaky.
Which tools fit which database?
Pick the tool by database engine and by the job, not by popularity. The descriptions below come from each tool's own site, read on 13 November 2026.
| Tool | Database | What it does, according to its site | Note |
|---|---|---|---|
| DbUnit | Database-driven projects (JUnit extension) | Puts the database into a known state between runs, imports and exports XML datasets, checks data against expected values | Latest release listed on its site is 2.4.9 (30 Sep 2012); check project activity before adopting |
| tSQLt | SQL Server | Unit tests written in T-SQL, run inside transactions, with fake tables and views and stored procedure spies | Open source; SQL Server only |
| utPLSQL | Oracle | Write and run unit tests in PL/SQL, built for CI/CD pipelines, xUnit-inspired | Open source, Apache 2.0 |
| pgTAP | PostgreSQL | Database functions for TAP-emitting unit tests of schema, views, procedures, functions, rules and triggers | Script-style and xUnit-style tests |
| HammerDB | SQL Server, Db2, Oracle, PostgreSQL, MariaDB, MySQL and VillageSQL | Open-source database benchmarking with automation and shareable results | Performance, not correctness |
Sources: DbUnit, tSQLt, utPLSQL, pgTAP and HammerDB. Confirm current versions and database support on each page.
Open-source tools cost nothing to licence but not nothing to run: someone must maintain the test suites, the datasets and the pipeline integration. Budget for that effort when comparing them with commercial tools, and ask each vendor for its own documentation before relying on a feature.
What goes wrong in database testing?
| Challenge | Why it happens | What to do |
|---|---|---|
| Under-testing | No plan, so coverage and test data are thin | Write a risk-ranked list of tables, procedures and jobs before writing tests |
| UI-only scope | Testers exercise the application and never read the database | Add SQL-level checks for constraints, triggers and procedures |
| Unrealistic test data | A handful of invented rows hides real-world faults | Use masked or generated data with realistic formats and volumes |
| Wasted effort on minor features | Everything gets equal attention | Test the high-impact objects first, such as money, identity and audit tables |
| Tool cost misjudged | Free tools look cheap until upkeep is counted | Compare total effort, not licence fees |
How does concurrency change the test plan?
Two sessions touching the same rows can give different results depending on the isolation level. PostgreSQL documents four levels and the faults each permits: dirty reads, nonrepeatable reads, phantom reads and serialization anomalies. Its default is Read Committed, and its Read Uncommitted mode behaves like Read Committed. Other engines differ, so write concurrency tests against the level your application really uses and confirm it in your database documentation.
Source: PostgreSQL documentation, Transaction Isolation (read 13 Nov 2026).
How should enterprise teams govern database testing?
For CIOs, CDOs and platform leads the question is less which tool and more who owns the evidence. A workable minimum is: schema and migration changes pass automated checks before release; test data is masked or generated; results are kept with the release record; and the same rules apply to the data that AI agents read and write. The checks for big data testing extend the same discipline to pipelines and large stores.
Where AI agents depend on database content, a wrong row becomes a wrong decision. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentQA offers automated quality assurance for AI, according to its site. Both complement database tests; they do not replace them.
When is database testing not enough?
Database tests prove that the data layer follows its rules. They do not prove that the rules match the business, that source systems send correct data, or that a pipeline preserves meaning between systems. For those, add data validation testing on the data itself, and unit tests close to the code, as described in unit testing techniques. A rule of thumb: test the container with database tests, and the contents with validation tests.
What is a sensible adoption sequence?
- List the business-critical tables, procedures and jobs and rank them by impact.
- Put schema, constraints and migrations under automated test first, because they are cheap and catch the most.
- Add stored procedure and trigger tests with a framework that matches your engine.
- Add a populated pre-deployment environment and run migrations there on every release.
- Add load and concurrency tests for the two or three workloads that matter most.
- Report results with each release and review the suite each quarter.
To map one data-quality decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What is database testing?
Database testing checks that a database stores, changes and returns data correctly. It covers the schema, field constraints, transactions, stored procedures, triggers and behaviour under load.
What are the main types of database testing?
The three main types are structural testing of schema, procedures and triggers, functional testing of business transactions, and non-functional testing of load, stress, volume and security.
Which tools can test a database?
It depends on the engine. According to their own sites, tSQLt targets SQL Server, utPLSQL targets Oracle, pgTAP targets PostgreSQL, DbUnit is a JUnit extension for database projects, and HammerDB benchmarks several databases. Confirm current support on each site.
Can you test on a production database?
Only with read-only monitoring or smoke checks. Destructive, load and stress tests belong in development, populated or pre-deployment environments.
How is database testing different from data validation testing?
Database testing checks the container: schema, constraints, procedures and performance. Data validation testing checks the contents: whether the data is complete, consistent and correct.
Does PostgreSQL protect against dirty reads?
According to its documentation, PostgreSQL never allows dirty reads, and its Read Uncommitted mode behaves like Read Committed, which is the default level.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE