Key takeaway
- Modern batch processing explained: how pipelines work, batch vs streaming, current tools going into 2027, retired tools to avoid, and how to adopt it.
Modern batch processing runs a defined set of data or jobs together, on a schedule or on a trigger, and produces a complete, repeatable result. It suits work where completeness and cost matter more than seconds of latency: nightly reconciliation, reporting, data migration, bulk transformation and model training data preparation.
Today it is rarely a single overnight script. A modern batch pipeline combines distributed storage, an engine such as Apache Spark, an orchestrator such as Apache Airflow, and monitoring. This guide explains how the pieces fit, which tools are still current, and when to choose real-time streaming with Apache Spark and Kafka instead.
What is modern batch processing?
Batch processing collects records into a bounded set and processes that set as one unit of work. Spring Batch describes the typical batch program as one that reads a large number of records from a database, file or queue, processes them, and writes the data back in a modified form, usually offline and without user interaction (according to the Spring Batch reference). The word modern refers to how that work is now run: on distributed engines, scheduled by workflow orchestrators, and observed like any production system.
| Aspect | Batch | Streaming |
|---|---|---|
| Input | Bounded set of records with a clear start and end | Unbounded flow of events |
| Typical result | Complete, repeatable output for a period or job | Continuously updated output |
| Best for | Reconciliation, reporting, migration, bulk transformation | Alerts, live dashboards, event-driven actions |
| Main risk | A failed run delays everything downstream until it is fixed and rerun | State, ordering and late-arriving data |
How does a modern batch pipeline work?
Most pipelines follow the same five stages. The tools differ, but the responsibilities do not.
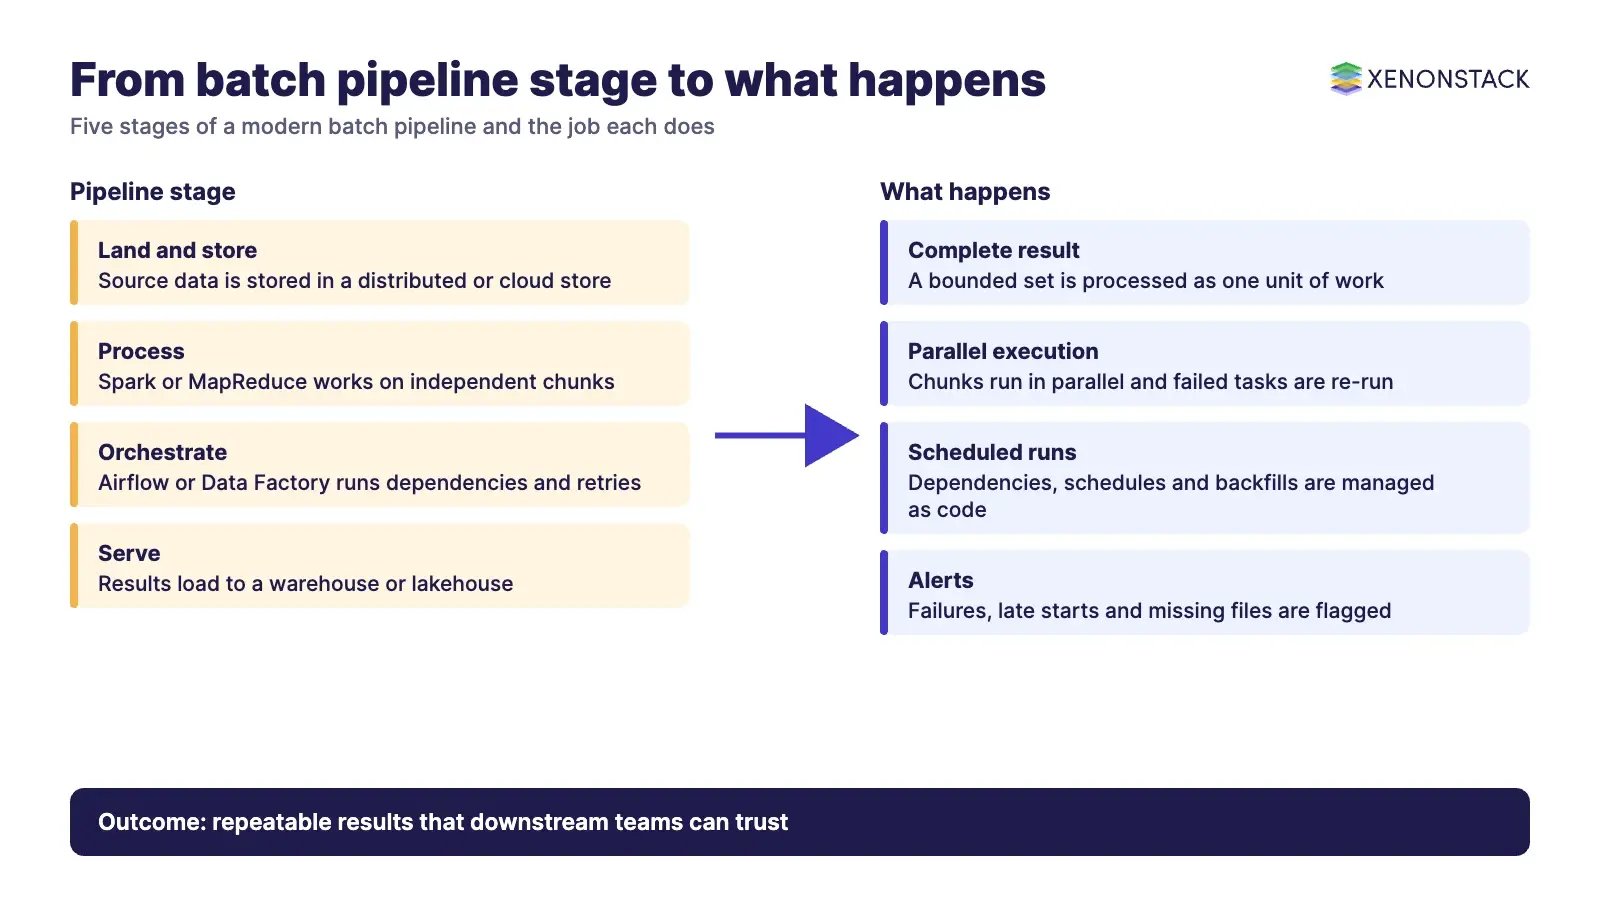
| Stage | What happens | Example tools (current docs) |
|---|---|---|
| 1. Land and store | Source data is extracted and stored in a distributed or cloud store | HDFS or cloud object storage; see our data lakehouse guide for table-format options |
| 2. Process | Data is split into independent chunks, transformed and aggregated in parallel | Apache Spark ("a unified analytics engine for large-scale data processing"), Hadoop MapReduce, Spring Batch for application-side jobs |
| 3. Orchestrate | Dependencies, schedules, retries and backfills are managed as code | Apache Airflow, which describes itself as a platform for orchestrating batch workflows; Azure Data Factory |
| 4. Serve | Results are loaded to a warehouse, lakehouse or reporting layer | Warehouse or lakehouse of your choice |
| 5. Monitor and notify | Failures, late starts, overruns and missing files raise alerts | Orchestrator UI and alerts, platform monitoring |
Hadoop MapReduce is the classic model: input is split into independent chunks, map tasks process them in parallel, the framework sorts the outputs for reduce tasks, and it schedules, monitors and re-executes failed tasks (according to the Hadoop MapReduce tutorial). Spark generalises the idea with higher-level APIs in Java, Scala, Python and R, and also covers SQL, streaming and machine learning (according to the Apache Spark documentation).
Batch or streaming: how do you choose?
Choose the processing style from the decision, not from the technology. If a person or system acts once a day or once an hour on a complete picture, batch is simpler and usually cheaper to run. If the action must happen while the event is still happening, you need streaming. Many enterprises use both: streaming for the live view and batch to recompute, reconcile and correct.
| Question | If yes | If no |
|---|---|---|
| Does the decision need data seconds old? | Streaming | Batch |
| Must the result be complete and reproducible for an audit period? | Batch, or batch to reconcile a stream | Either |
| Is the logic the same for history and live data? | Consider a unified model such as Apache Beam or Spark Structured Streaming | Keep batch and streaming separate |
| Are source systems only available in a window? | Batch | Either |
For the streaming side in detail, read our guide to real-time streaming with Apache Spark and Kafka. For orchestration in depth, see the Apache Airflow guide.
Which batch processing tools are current going into 2027?
Many older lists of batch tools name projects that have since been retired. Check status before you build on a tool.
| Tool | Role | Status according to its own or the vendor page |
|---|---|---|
| Apache Spark | Batch, SQL, streaming and ML engine | Current docs are for Spark 4.3.0 (Apache Spark site, read 13 Nov 2026) |
| Apache Airflow | Workflow orchestration for batch pipelines | Documentation shown is Airflow 3.4.0; workflows with a clear start and end that run on a schedule are a good fit (Apache Airflow site) |
| Hadoop MapReduce | Distributed batch programming model | Documented as a software framework for processing vast amounts of data in parallel (Apache Hadoop site) |
| Azure Data Factory | Managed ETL, ELT and orchestration | Microsoft states Data Factory in Microsoft Fabric is the next generation of Azure Data Factory and recommends it for new projects (Microsoft Learn) |
| Spring Batch | Java framework for application batch jobs | Provides restart, skip, transaction management and job statistics; intended to work with a scheduler, not replace one (Spring Batch reference) |
| Apache Oozie | Hadoop workflow scheduler | Retired in February 2025; move to the Attic completed April 2025 (Apache Attic) |
| Apache Sqoop | Bulk transfer between Hadoop and databases | Retired in June 2021; move to the Attic completed July 2021 (Apache Attic) |
| Azure Data Lake Analytics (U-SQL) | Job-based analytics service | Retired on 29 February 2024; Microsoft points to Azure Synapse Analytics or Microsoft Fabric (Microsoft Learn) |
If your estate still runs Oozie, Sqoop or U-SQL jobs, treat them as a migration backlog, not a platform choice. Airflow, Azure Data Factory or Fabric Data Factory are the usual landing places for orchestration, and Spark or the warehouse engine for the processing.
What are the advantages of modern batch processing?
| Advantage | Why it matters | What to put in place |
|---|---|---|
| Predictable, repeatable runs | The same input gives the same output, which supports audit and reconciliation | Versioned code and configuration, idempotent loads |
| Dependency management | Downstream jobs wait for upstream ones to succeed | An orchestrator with explicit dependencies |
| Monitoring and notification | Teams learn of failed jobs, missing files, late starts and overruns before users do | Alerts on failure, duration and data freshness |
| Efficient use of compute | Work is moved to a window and run on shared capacity | Scheduling, autoscaling and cost allocation |
| Recovery | Restart, skip and re-run reduce the cost of a failure | Restartable steps; bad-record handling |
What are the trade-offs and when should you not use batch?
The main trade-off is latency: results are only as fresh as the last completed run. A second is blast radius. When one stage fails, every consumer of that stage waits, so a batch estate needs clear ownership, retries and a way to rerun a single failed partition rather than the whole job. Avoid batch where an action must be taken on an event as it happens, such as blocking a payment or raising a live safety alert.
How do governance, security and cost apply to batch pipelines?
Batch jobs often touch the most sensitive and complete copies of enterprise data, so they need the same controls as any production system. This is XenonStack guidance, not a regulatory requirement.
| Concern | Practical control |
|---|---|
| Access | Service accounts with least privilege per job, secrets outside code |
| Lineage and audit | Record inputs, outputs, code version and run time for each run |
| Data quality | Validate row counts and schema at stage boundaries and fail early |
| Cost | Tag jobs by owner and product; review long-running and failed-and-rerun jobs |
| Change control | Review pipeline changes like application code; test with a sample batch |
When batch outputs feed AI agents or automated decisions, the data alone is not enough: you also need the policy and the decision trace. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights. See our guides to data operations and the data lakehouse for the surrounding data platform.
How do you adopt modern batch processing step by step?
| Step | Activity | Output |
|---|---|---|
| 1. Inventory | List existing jobs, schedules, owners, dependencies and retired tools | Job catalogue and migration backlog |
| 2. Classify | Mark each job batch, streaming or either by the decision it supports | Processing-style decision per job |
| 3. Design the batches | Choose batch size, partitioning, schedule and resource limits | Run plan and capacity estimate |
| 4. Build and orchestrate | Implement stages as restartable tasks; define dependencies in the orchestrator | Versioned pipeline code |
| 5. Observe | Add alerts for failure, duration, freshness and data quality | Runbook and dashboards |
| 6. Review | Review cost, failures and ownership each quarter | Retire, merge or move jobs |
To map one batch-fed decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
What should you plan for in 2027?
Plan the work as a rolling backlog, not a single migration project.
- Clear the retired tools. List every job still running on Apache Oozie, Apache Sqoop or Azure Data Lake Analytics, and schedule each one onto a maintained orchestrator and engine.
- Classify by decision. Mark each job batch, streaming or either according to how fresh the decision needs the data, and keep batch where completeness and cost matter more than latency.
- Review every quarter. Check cost, failed and rerun jobs, ownership and alerts for failure, duration and freshness, and retire, merge or move jobs that no longer earn their place.
Frequently asked questions about modern batch processing
What is modern batch processing?
It is the processing of a bounded set of data or jobs together on a schedule or trigger, run on distributed engines and managed by an orchestrator. Spring Batch describes the typical pattern as reading a large number of records, processing them and writing them back, usually without user interaction.
What is the difference between batch and stream processing?
Batch processes a bounded set with a clear start and end and produces a complete result. Streaming processes an unbounded flow of events continuously. Choose by how fresh the decision needs the data to be.
Which tools are used for modern batch processing?
Common choices are Apache Spark for processing, Apache Airflow or Azure Data Factory for orchestration, and Spring Batch for application jobs. Check status before adopting: Apache Oozie and Apache Sqoop are retired to the Apache Attic, and Azure Data Lake Analytics retired on 29 February 2024.
Is Apache Airflow a batch processing engine?
No. Airflow orchestrates workflows; it schedules and monitors tasks that run on other systems. Its documentation describes it as a platform for orchestrating batch workflows and says workflows with a clear start and end that run on a schedule are a good fit.
When should an enterprise not use batch processing?
When an action must happen as the event occurs, such as blocking a payment or raising a live alert. A failed batch also delays every downstream consumer, so batch needs retries, ownership and partial reruns.
How do I move off retired batch tools such as Oozie, Sqoop or U-SQL?
Inventory the jobs, then move orchestration to a maintained tool such as Airflow, Azure Data Factory or Fabric Data Factory, and processing to Spark or your warehouse engine. Microsoft names Azure Synapse Analytics and Microsoft Fabric as the alternatives to Data Lake Analytics.
Related reading
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE