Key takeaway
- Apache Hadoop security explained: Kerberos authentication, Ranger policies and audit, encryption settings and how to secure data access for AI agents.
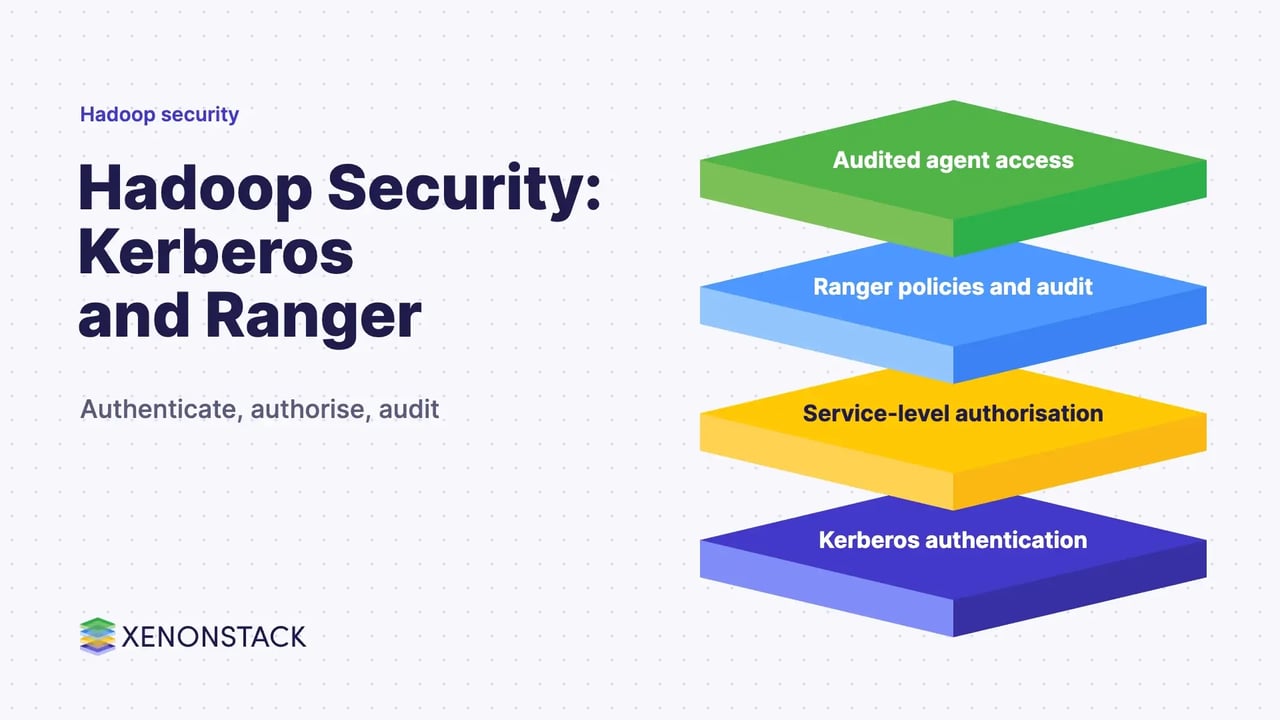
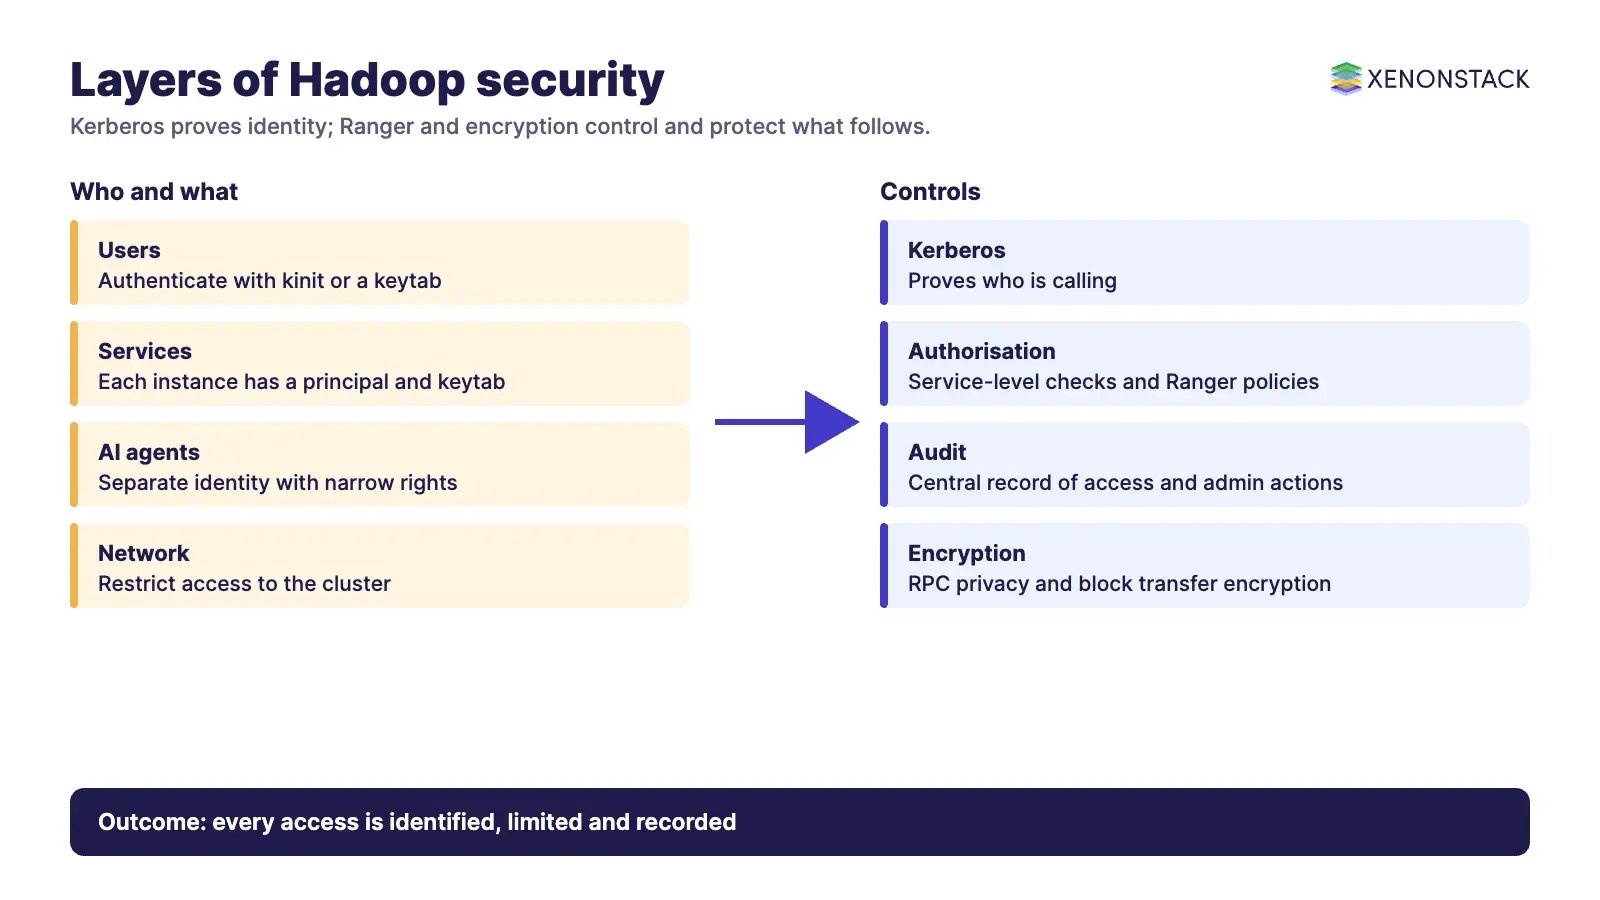
Apache Hadoop security is the set of controls that authenticate every user and service, limit what each may do, and protect data in transit, with Kerberos providing authentication and Apache Ranger providing centralised authorisation and audit. The two work together: Kerberos proves who is calling, and Ranger decides what that caller may access and records it.
This guide is for data platform, security and governance leads who run or inherit Hadoop clusters. It explains the pieces being protected, what Kerberos and Ranger each do, the configuration areas to plan, how AI agents change data access, and what to do first. It applies to data workflows, including data preparation for machine learning.
What needs protecting in a Hadoop cluster?
Hadoop stores and processes big data across many machines. Two layers carry most of the exposure. HDFS, the Hadoop Distributed File System, holds the data: a NameNode keeps metadata about where data lives, and DataNodes store the blocks, which are replicated to tolerate hardware failure. YARN allocates resources and schedules work: a ResourceManager receives requests and passes work to NodeManagers where processing happens. For background, see Apache Hadoop 3.0 features and how it works and data serialisation in Apache Hadoop.
The Hadoop Secure Mode page is direct about the starting point. In the default configuration, it expects you to keep attackers out by restricting all network access to the cluster. It then lists the security pillars as authentication, service-level authorisation, web-console authentication and data confidentiality.
How does Kerberos authentication work in Hadoop?
The Secure Mode page states that when Hadoop runs in secure mode, each Hadoop service and each user must be authenticated by Kerberos. Users typically run kinit, and keytab files serve when an interactive login is impractical. Each service instance is configured with its principal and keytab file location. Principals follow the pattern ServiceName/_HOST@REALM, and each instance substitutes _HOST with its own fully qualified hostname at runtime, so one configuration can be deployed everywhere.
Three details matter in practice:
- HDFS and YARN daemons should run as separate Unix users, such as hdfs and yarn, with the JobHistory Server as mapred.
- The setting hadoop.security.authentication is simple by default, which means no authentication. Setting it to kerberos enables Kerberos.
- The setting hadoop.security.auth_to_local maps Kerberos principals to operating system accounts. The page says the DEFAULT rule is probably unsuitable for most clusters, so review it.
The MIT Kerberos site describes Kerberos as a network authentication protocol that provides strong authentication for client and server applications through secret-key cryptography.
What does Apache Ranger add?
The Apache Ranger site defines it as a framework to enable, monitor and manage comprehensive data security across the Hadoop platform. Its stated goals include centralised security administration through a central UI or REST APIs, fine-grained authorisation for specific actions on Hadoop components, one standard authorisation method across components, support for multiple access-control approaches such as role-based and attribute-based, and centralised auditing of user access and administrative actions.
Ranger therefore sits on top of authentication. It does not replace Kerberos. For a view of how related components are secured, see our guides to Apache Hive, Apache HBase, Apache Kafka and Apache Storm. Check the Ranger documentation for which components your version supports.
What is the difference between Kerberos, Ranger and encryption?
| Control | Question it answers | Source of the detail |
|---|---|---|
| Kerberos | Who is this user or service? | Hadoop Secure Mode and MIT Kerberos |
| Service-level authorisation | May this authenticated user call this service at all? | Enabled with hadoop.security.authorization set to true |
| Ranger policies | What may this identity do, and is it recorded? | Apache Ranger site |
| Data confidentiality | Can someone read data on the wire? | hadoop.rpc.protection set to privacy; dfs.encrypt.data.transfer set to true |
The Secure Mode page lists three RPC protection levels: authentication, which is the default, integrity, and privacy. It also describes enabling encryption of DataNode block transfer, and HTTPS for the web consoles using the dfs.http.policy, yarn.http.policy and mapreduce.jobhistory.http.policy settings.
What are the best practices for Hadoop security?
- Authenticate every service and user with Kerberos, and keep keytab files readable only by the service account.
- Turn on service-level authorisation so that users authenticate before they reach any service.
- Manage fine-grained rules centrally, and review them as roles and teams change.
- Review configuration files regularly. A misconfigured file can quietly weaken protection for machine learning workflows that read from the cluster.
- Encrypt data in transit between components, including messaging and stream tools such as Apache Beam and Apache Flink.
- Change every default credential at installation, and never leave installer defaults in place.
The same discipline applies to a data lake architecture where many workloads share one cluster, and to IoT data arriving at scale. Also see Apache Calcite architecture for the query layer.
How do AI agents change Hadoop data access?
An AI agent that queries Hadoop data is another identity. It needs its own Kerberos principal, narrowly scoped policies, and an audit entry for each access, so that a decision can be traced back to the data it used. Fixed jobs run the same query every time. Agents choose what to read based on the task, which makes least privilege and audit more important, not less. ElixirData is XenonStack's Context OS for governed context, policy and decision traces above data platforms like this one.
What should you do first?
- Confirm the cluster is not reachable from networks that do not need it.
- Check whether hadoop.security.authentication is still simple.
- Inventory the users, services, jobs and agents that connect.
- Enable Kerberos in a test cluster, then add centralised authorisation and audit.
- Define which datasets an agent may read, and test that a refused request is logged.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop. Our guide to securing Apache ZooKeeper with Kerberos covers the coordination layer.
Frequently asked questions
What is the default authentication setting in Hadoop?
The default for hadoop.security.authentication is simple, which means no authentication. Setting it to kerberos enables Kerberos authentication.
What does Apache Ranger do?
Apache Ranger is a framework to enable, monitor and manage data security across the Hadoop platform, with central policy administration, fine-grained authorisation and centralised auditing.
Does Ranger replace Kerberos?
No. Kerberos authenticates users and services, and Ranger controls and audits what authenticated identities may do.
How do you encrypt data in transit in Hadoop?
Set hadoop.rpc.protection to privacy for RPC, set dfs.encrypt.data.transfer to true for DataNode block transfer, and use HTTPS for the web consoles.
Should AI agents get their own identity on Hadoop?
Yes. A separate principal and narrow policies per agent keep access limited and make each access traceable.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE