Key takeaway
- Data mesh architecture explained for data leaders: four principles, data product qualities, trade-offs, and when a central platform is the better choice.
What is data mesh architecture?
Data mesh is a distributed data architecture in which business domains own their analytical data and serve it to others as products, on a shared self-serve platform, under governance rules that apply to every domain. Zhamak Dehghani of Thoughtworks introduced it in How to Move Beyond a Monolithic Data Lake to a Distributed Data Mesh (20 May 2019) and set out its four principles in Data Mesh Principles and Logical Architecture (3 December 2020).
It answers a specific problem: a single central lake or warehouse, run by one platform team, struggles as sources and consumers multiply. For enterprise architects and data leaders the decision is not "mesh or no mesh" but where ownership, platform and governance should sit. If you are deciding whether to adopt it, read Data Mesh Adoption: Should You Adopt It?; this post covers the architecture itself. For a comparison with the other approach, see Data Fabric vs Data Mesh.
Why does a central data platform stop scaling?
According to How to Move Beyond a Monolithic Data Lake to a Distributed Data Mesh, the centralised, monolithic model pulls data from every domain into one platform and one team. Dehghani names several failure points:
- Ownership becomes domain-agnostic, so the platform team owns data it does not understand.
- Ingestion and transformation struggle to keep up as new sources and use cases arrive.
- Pipelines are split by technical stage, so one new feature touches the whole pipeline.
- Engineers sit apart from the business domains that create and use the data.
The same article notes that the central model can still work for simpler domains with fewer consumption cases. That is the honest starting point: mesh is a response to scale and organisational complexity, not a default.
What are the four principles of data mesh?
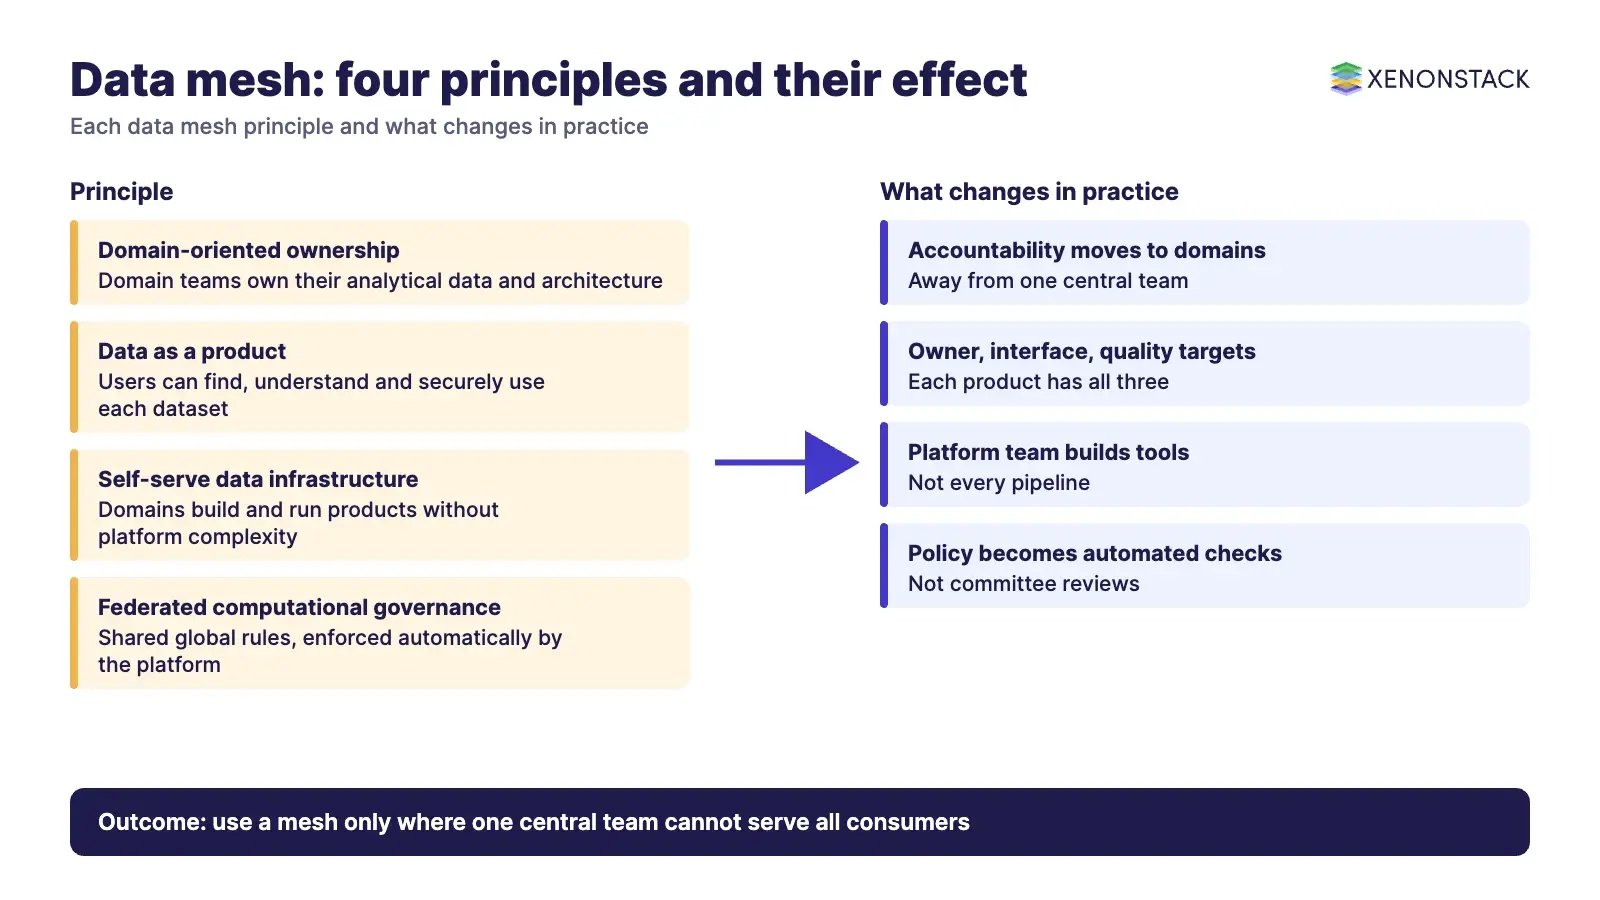
The principles below are from Data Mesh Principles and Logical Architecture. Each one changes a different part of the data platform.
| Principle | What it means | What changes in practice |
|---|---|---|
| Domain-oriented ownership | Domain teams own their analytical data and architecture; the system scales by adding autonomous nodes | Accountability moves from one central team to the business domains |
| Data as a product | Domains treat analytical data as a product that users can find, understand and use securely | Each dataset gets an owner, an interface and quality targets |
| Self-serve data infrastructure | A platform lets domain teams build and run data products without handling the underlying complexity | A platform team builds tools, not every pipeline |
| Federated computational governance | Domains keep local autonomy while following shared global rules that the platform enforces automatically | Policy becomes automated checks, not committee reviews |
What makes something a data product?
The 2019 article lists the qualities a data product should have. The table turns them into questions you can test before you call a dataset a product.
| Quality | Question to ask |
|---|---|
| Discoverable | Is it registered in a catalogue with owner, origin and lineage? |
| Addressable | Does it have a unique address that follows a global convention? |
| Trustworthy | Has the owner set quality targets as service level objectives and tested integrity? |
| Self-describing | Can a consumer use it from its schema, semantics and sample data alone? |
| Interoperable | Does it follow global standards, such as shared identifiers, so domains can be correlated? |
| Secure | Is access controlled per product, with central policy enforced through single sign-on and roles? |
Quality is the usual weak point, so tie each product to explicit checks. Our guides on why data quality matters and enterprise data catalog tools cover the controls and the catalogue side.
What does the logical architecture look like?
In the 2019 article, the architecture has three layers that replace the single pipeline.
Domain data products
Each domain runs its own pipelines as internal detail and cleanses data at the source. It serves the result through well-defined interfaces. An eCommerce company might form domains such as orders, carts, sessions and leads, each with its own storage and a governance layer for policy, access control and monitoring. This is an illustration of the pattern, not a reference design.
Self-serve platform
The platform is domain-agnostic. According to the 2019 article it provides storage, pipelines, cataloguing, lineage, monitoring, encryption and access control, and hides the underlying complexity. A practical test of it is how long a team takes to register a new data product.
Federated governance
Governance is a decision-making model led by a federation of domain data product owners and data platform product owners. Its central challenge, in Dehghani's words, is maintaining an equilibrium between centralisation and decentralisation. Global rules exist to create interoperability, and the platform executes them automatically.
In this model the lake and warehouse do not disappear. The 2019 article describes them as nodes on the mesh rather than its centrepiece.
What changes in the organisation?
Architecture alone does not deliver a mesh. According to the 2019 article, each domain team is cross-functional and includes data engineers and a data product owner. The owner manages the product roadmap, consumer satisfaction, lifecycle and KPIs. A central data infrastructure team provides the shared platform, and global standards keep domains interoperable.
This is why mesh programmes stall when treated as a tooling project: the change is in who is accountable, and how they are measured.
How does data mesh compare with a data lake, warehouse or data fabric?
| Approach | Ownership | Where it fits | Main trade-off |
|---|---|---|---|
| Central data lake or warehouse | One central team | Simpler domains with fewer consumption cases | Platform team becomes the bottleneck as sources and consumers grow |
| Data mesh | Business domains, with federated governance | Many domains, many consumers, strong domain knowledge | Needs new skills, product owners and a capable self-serve platform |
| Data fabric | Usually central, through a unified metadata and integration layer | Connecting distributed data without changing who owns it | Different goal from mesh; see our comparison |
The approaches are not exclusive. See Data Lake vs Data Warehouse vs Data Mesh for a storage-level view and Data Fabric vs Data Mesh for the metadata-driven alternative.
What are the benefits and the risks?
| Benefit | Risk to manage |
|---|---|
| Faster change: a domain can change its own data products without queuing for one team | Duplicated effort and inconsistent standards if governance is weak |
| Clear ownership: someone is accountable for meaning and quality | Domain teams may lack data engineering skills |
| Scales by adding nodes as sources and use cases grow | Interoperability fails without shared identifiers and standards |
| Governance enforced by the platform rather than by review | The platform is a significant build; weak tooling undermines autonomy |
Dehghani herself noted in 2019 that enterprise adoption was still early, and she rejected a return to fragmented silos. Treat mesh as an operating model to introduce in steps, starting with one or two domains that have clear owners and real consumers.
When should you not use data mesh?
Avoid it where one team can already serve every consumer, where domains have no clear owners, or where there is no appetite to fund a platform and product-owner roles. In those cases a well-run central platform, with better cataloguing and quality controls, is the cheaper answer.
Is a data mesh the same as a service mesh?
No. A service mesh manages communication between microservices, for example traffic control, mutual TLS and telemetry. A data mesh is an architecture and operating model for analytical data. The names overlap, and the two can run side by side, but they solve different problems. For the networking layer, see Service Mesh Architecture and Best Practices.
How do AI agents fit on top of a data mesh?
Agents that query data need to know which products exist, who owns them and what policy applies. Well-described data products give them that. ElixirData Context OS is described on its site as a decision harness for enterprise AI agents that assembles context for each decision, checks rules and permissions before an agent acts, and keeps traceable records of every action. AgentAnalyst is described on its site as offering natural-language analysis and real-time insights across data sources.
To map one decision your agents should make, and the data products and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What is data mesh architecture?
Data mesh is a distributed data architecture in which business domains own their analytical data and serve it as products on a self-serve platform, under shared governance rules. Zhamak Dehghani described it in 2019 and set out four principles in 2020.
What are the four principles of data mesh?
Domain-oriented decentralised ownership, data as a product, self-serve data infrastructure as a platform, and federated computational governance, according to Dehghani's December 2020 article.
What is the difference between data mesh and a data lake?
A data lake is a central store with central ownership. A data mesh distributes ownership to business domains, and a lake or warehouse can sit on the mesh as one node rather than as the centrepiece.
Is data mesh the same as data fabric?
No. A data fabric usually integrates distributed data through a unified, metadata-driven layer, while data mesh changes who owns and serves the data. See our Data Fabric vs Data Mesh comparison.
When is data mesh not a good fit?
When one central team can already serve all consumers, when domains lack clear owners, or when the organisation cannot fund a self-serve platform and data product owner roles.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE