Key takeaway
- Stream processing history from Storm and Kafka to Flink 2.0 and Kafka 4.0: what each generation solved, what changed by 2026 and what to plan next.
Stream processing has moved through three generations: record-at-a-time engines that gave speed but little else, log-based stateful engines that made results correct and replayable, and the 2025 to 2026 generation that is merging batch and streaming and moving state off local disks. For a CTO or architect, the useful lesson from the history is which problems are now solved by the platform and which are still yours: event-time correctness, reprocessing, cost and governance.
This post is the history and outlook view. If you need the definition and the choice between approaches, read Batch Processing vs Stream Processing. For a hands-on build, see Stream Processing with Apache Flink and NATS.
For the business-value side, see Streaming Analytics: What It Is and When It Pays Off, and for the market and platform landscape, Navigating the Data Streaming Landscape in 2025.
How did stream processing evolve, and what did each step change?
Before streaming engines, analytics ran as scheduled batch jobs: data was collected, stored and then processed, so insight lagged the event by hours or a day. The milestones below are the ones that changed enterprise architecture. Origin dates for open-source projects are as reported by Wikipedia; research dates come from the publishers.
| Period | Milestone | What it changed |
|---|---|---|
| Before streaming engines | Scheduled batch jobs on Hadoop-style systems | Large datasets became affordable to process, but results arrived after the event. |
| January 2011 | Kafka open-sourced by LinkedIn; Apache graduation 23 October 2012 | A durable, replayable log became the standard backbone for event data. |
| September 2011 | Storm, created at BackType and taken on by Twitter, released | Record-at-a-time, low-latency processing became practical; it joined Apache in 2013 and became a top-level project in September 2014. |
| 2013 | Google publishes MillWheel (VLDB) | Showed a computation graph with persistent state, fault tolerance and a notion of logical time at internet scale. |
| 2 July 2014 | Jay Kreps, "Questioning the Lambda Architecture" | Argued for one stream system plus a retained log instead of duplicate batch and stream code. |
| 2014 | Flink (from the Stratosphere research project begun in 2010) enters Apache; top-level in December 2014 | Stateful stream processing with exactly-once state consistency became open source. |
| 2015 | Dataflow Model paper (VLDB, Google) | Reframed the problem: assume you never know you have seen all the data, and choose your trade-off between correctness, latency and cost. |
| Early 2016 | Beam enters the Apache Incubator from Google's Dataflow SDKs | One programming model for bounded (batch) and unbounded (streaming) data, run on several engines. |
| March 2025 | Flink 2.0 (24 March) and Kafka 4.0 (18 March) | State moves towards remote storage; Kafka runs without ZooKeeper. |
Sources: Storm history, Kafka history, Flink history (all as reported by Wikipedia), MillWheel, the Dataflow Model, Kreps, Apache Beam.
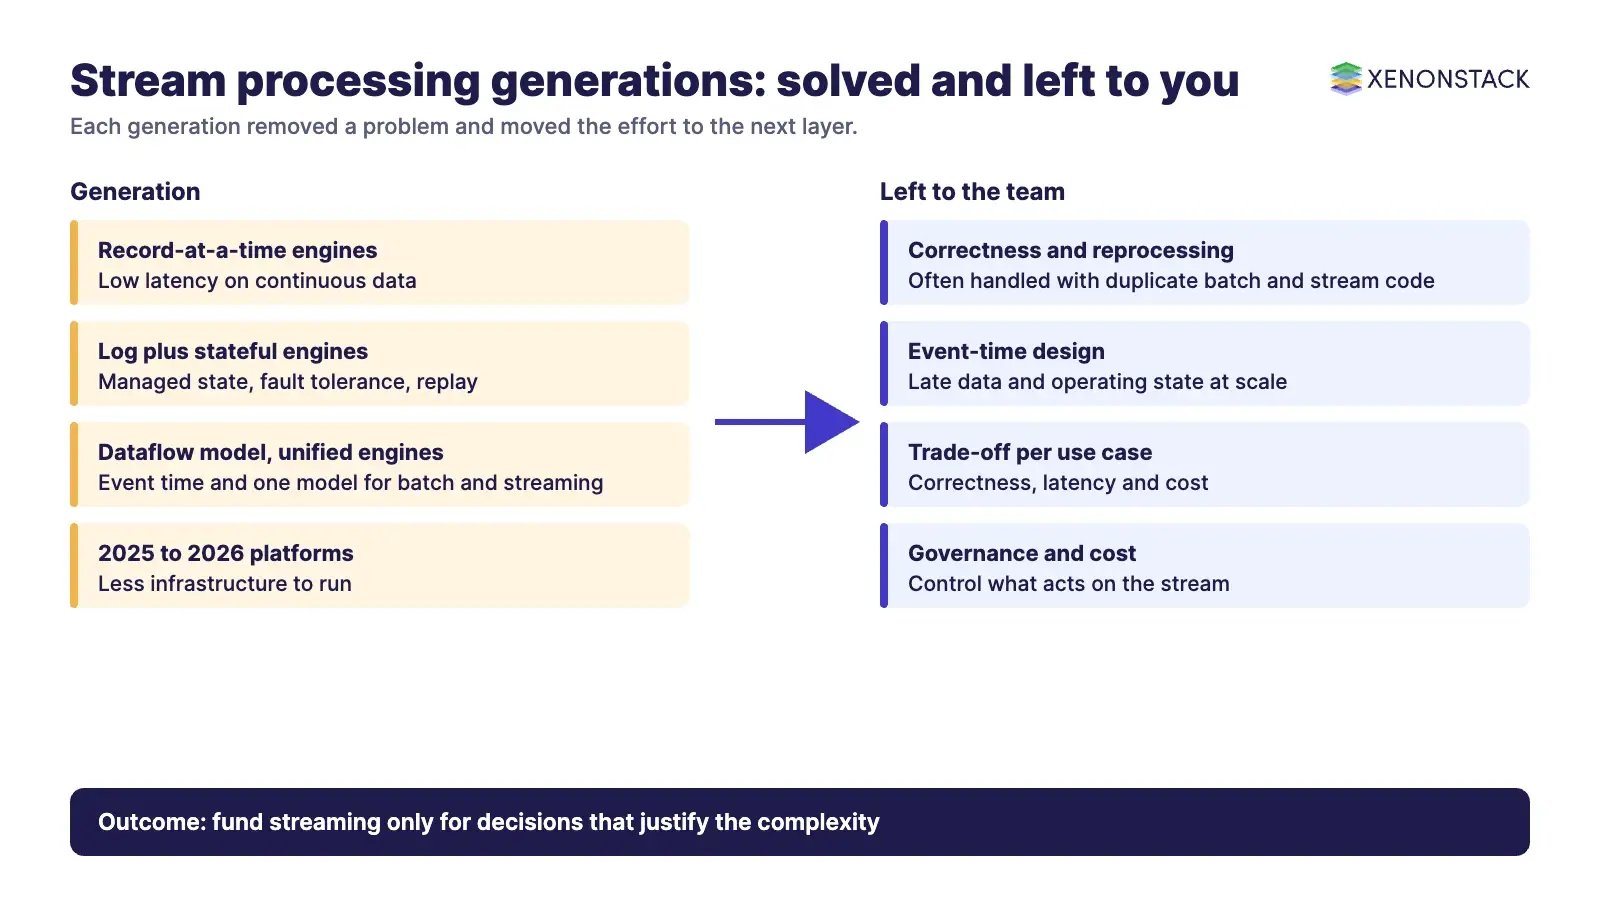
What did each generation solve, and what did it leave to you?
| Generation | Solved | Left to the team |
|---|---|---|
| 1. Record-at-a-time engines (early Storm era) | Low latency on continuous data | Stateful logic, reprocessing and correctness; teams often paired them with a batch system and kept the same logic in two codebases (the Lambda pattern Kreps criticised). |
| 2. Log plus stateful engines (Kafka with Flink-style engines) | Managed state, fault tolerance, replay from a retained log | Event-time design, late data, operating state at scale. |
| 3. Dataflow model and unified engines (Beam, Flink, Spark) | Event time and windowing for out-of-order data; one model for batch and streaming | Choosing the correctness, latency and cost trade-off per use case. |
| 4. 2025 to 2026 platforms | Less infrastructure to run (Kafka without ZooKeeper, disaggregated state in Flink, managed Flink on clouds) | Governance of what acts on the stream, and cost control. |
The grouping into generations is our own reading of the sources above, not an industry standard.
What has changed in stream processing between 2025 and 2026?
| Item | Current status | Why it matters |
|---|---|---|
| Apache Flink | 2.0 released 24 March 2025 with disaggregated state storage; the DataSet API and the Scala APIs were removed. 2.3.0 is listed as the latest stable release (25 June 2026). | Very large state is easier to rescale; teams on the removed APIs must migrate to the Java DataStream API or Table API and SQL. |
| Apache Kafka | 4.0.0 (18 March 2025) is the first major release to run entirely without ZooKeeper, in KRaft mode. Queues for Kafka (share groups) was early access in 4.0. 4.4.0 is listed as released on 22 October 2026. | Fewer moving parts to operate; plan the migration if you still run ZooKeeper-based clusters. |
| Apache Spark | Structured Streaming micro-batch reaches end-to-end latencies as low as 100 ms with exactly-once guarantees; Real-time Mode arrived in 4.1.0 (stateless) with stateful support from 4.3.0, Kafka source only. | Spark shops can cover lower-latency cases without a second engine, within the limits listed. |
| Apache Storm | Still maintained: 3.0.0 (22 July 2026), 3.1.0 (12 September 2026) and 3.2.0 (10 November 2026) are listed on the project site. | Legacy Storm estates have a supported path, but new builds usually start on Flink, Spark or Kafka Streams. |
| Amazon Kinesis Data Analytics for SQL | No new applications from 15 October 2025; applications deleted from 27 January 2026. AWS points to Amazon Managed Service for Apache Flink. | Applications must be re-created, not upgraded in place. |
Sources: Flink 2.0 announcement, Flink downloads, Kafka 4.0 announcement, Kafka downloads, Spark Structured Streaming, Spark Real-time Mode, Apache Storm, AWS discontinuation notice.
What does the 2026 outlook look like?
The points below are our assessment, grounded in the releases above rather than in market forecasts.
Will batch and streaming merge into one model?
The direction is clear. Beam defines one pipeline for bounded and unbounded data, Flink treats batch as a bounded stream, and Spark now offers micro-batch and real-time modes in one API. Expect fewer separate batch and speed layers, and more decisions about latency per use case instead of per platform. The related trade-offs are covered in our guide to event-driven architecture.
Where will operations get simpler?
Removing ZooKeeper from Kafka, moving Flink state to distributed storage and retiring older managed services all reduce what teams run themselves. The cost shifts to migration work and to watching storage and state growth.
What happens when AI agents act on streams?
Once a stream triggers an automated action, such as blocking a payment or opening an incident, the question moves from "is the data fast enough" to "who approved this action and on what context". ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents. AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights, and AgentSRE is aimed at SRE, AIOps, monitoring and incident management. Our own data platform work spans Hadoop, Spark and Flink estates, which is why we treat governance as a design input and not an afterthought.
When does stream processing fit, and when should you not use it?
| Situation | Fits when | Think twice when |
|---|---|---|
| Fraud, security and alerting | The decision loses value within seconds and someone or something can act. | No one acts on the alert in time. |
| Operational monitoring and IoT | Continuous sensor or log data drives automated response. | Hourly reporting would give the same outcome. |
| Reporting and finance close | Rarely; use batch with a streaming feed for freshness only where needed. | Correctness and reconciliation matter more than speed. |
| Model features and personalisation | Fresh features change the prediction. | The model retrains weekly and features are stable. |
How should an enterprise adopt or modernise a streaming platform?
- List the decisions, not the data. Rank decisions by how fast their value decays.
- Put a durable log first. A retained log lets you replay and reprocess, which removed much of the need for dual codebases.
- Pick one engine per latency class. Avoid adding a second engine unless a measured latency target demands it.
- Design for event time. Decide how late data is handled before building dashboards on top.
- Add governance and security early. Access control, encryption and an audit trail for automated actions are cheaper to design in than to retrofit.
- Track cost per decision. Watch state size, retention and compute, and review streaming jobs that no one uses.
The trade-off to accept: streaming raises operational complexity, so fund it only for decisions that justify it.
To map one decision your agents should make from a stream, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
When did stream processing start to appear in the enterprise?
Open-source engines arrived in the early 2010s: Kafka was open-sourced in 2011, and Storm was released in September 2011 (dates as reported by Wikipedia). Google had published MillWheel in 2013 and the Dataflow Model in 2015.
What was the Lambda architecture and why was it criticised?
It ran an immutable stream of records through a batch system and a stream system in parallel, with the same logic implemented twice and results combined at query time. Jay Kreps argued in July 2014 for a single stream system with a retained log, because duplicate code and two systems were costly to run.
What changed in Flink and Kafka in 2025?
Flink 2.0 (24 March 2025) introduced disaggregated state storage and removed the DataSet API and the Scala APIs. Kafka 4.0 (18 March 2025) was the first major release to run entirely without ZooKeeper.
Is Spark fast enough for streaming?
Micro-batch Structured Streaming reaches end-to-end latencies as low as 100 ms with exactly-once guarantees. Real-time Mode targets lower latency, with limits such as a Kafka-only source.
What happened to Amazon Kinesis Data Analytics for SQL?
No new applications could be created from 15 October 2025, and applications were deleted from 27 January 2026. AWS recommends Amazon Managed Service for Apache Flink, and applications must be re-created.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE