Key takeaway
- Kafka vs Pulsar compared on architecture, subscriptions, multi-tenancy, geo-replication and operations, using current Apache docs, with a decision table.
What is the difference between Apache Kafka and Apache Pulsar?
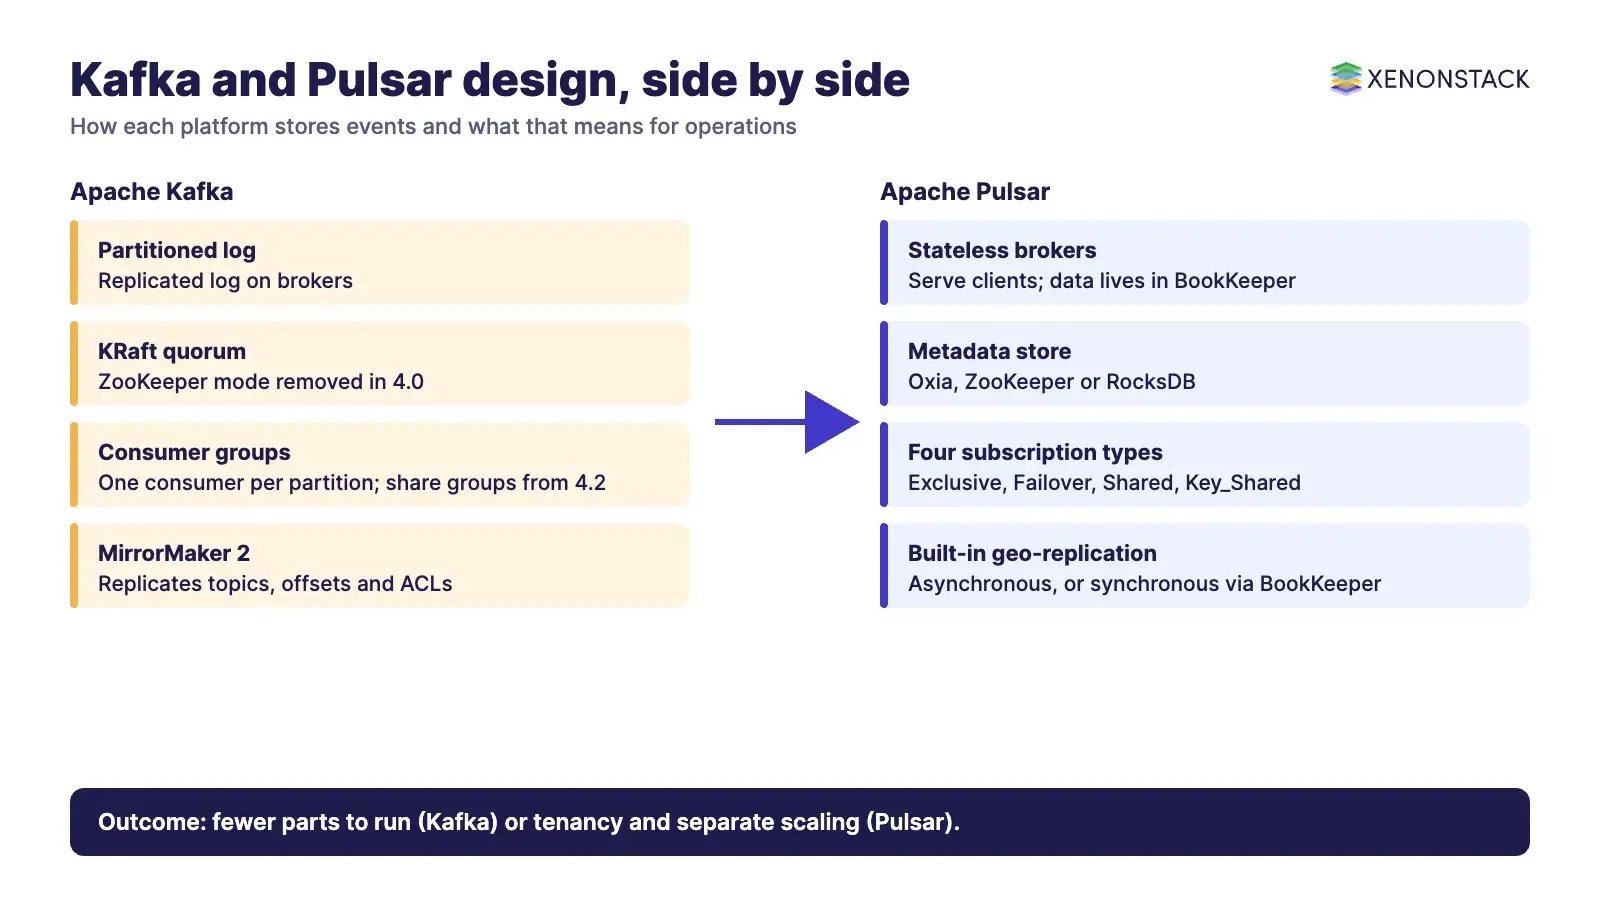
Apache Kafka and Apache Pulsar are both open-source platforms for streaming events between systems. Kafka keeps each partition as a replicated log on its brokers. Pulsar splits the work: stateless brokers serve clients, and Apache BookKeeper nodes (bookies) store the data. Neither is better in every case. The right choice depends on the skills you have, how you want to run the platform, and what your workloads need.
This guide compares the two using the projects' own documentation, as of November 2026. It covers architecture, subscriptions, multi-tenancy, geo-replication, tiered storage and recent releases. For a deeper look at one side, see our guides to Apache Pulsar architecture and Kafka and ZooKeeper (KRaft) architecture, and our wider view of the data streaming landscape.
How do Kafka and Pulsar differ at a glance?
The table below sets the two side by side. Each row comes from the Apache Kafka or Apache Pulsar documentation listed in the sources section.
| Area | Apache Kafka | Apache Pulsar |
|---|---|---|
| Core design | Partitioned, replicated log on brokers | Stateless brokers plus BookKeeper storage nodes |
| Metadata and coordination | KRaft controller quorum; ZooKeeper mode removed in 4.0 | Metadata store: Oxia (recommended for new clusters), ZooKeeper, or RocksDB for standalone |
| How consumers read | Consumers pull from brokers; a partition is read by one consumer per group | Four subscription types: Exclusive, Failover, Shared and Key_Shared |
| Queue-style consumption | Share groups (Queues for Kafka, KIP-932), called production-ready in 4.2 | Shared and Key_Shared subscriptions |
| Multi-tenancy | Quotas limit the broker resources used by clients | Tenants and namespaces, each with policies, with authentication and authorisation per tenant |
| Geo-replication | MirrorMaker 2, built on Kafka Connect | Built-in asynchronous replication; synchronous mode through BookKeeper |
| Long-term storage | Tiered storage with a local and a remote tier, with documented limits | Tiered storage offloads sealed ledgers to cloud or on-premises object stores |
| Licence | Apache 2.0 | Apache 2.0 |
How does Kafka store and serve events?
Producers write events to topics, and each topic is split into partitions. Kafka's design documentation says it writes all data to a persistent log on the filesystem and replicates the log for each partition across a configurable number of servers. Only members of the in-sync replica set are eligible for election as leader. Consumers pull data from brokers at their own pace, and offsets record their position in each partition.
Kafka's own transaction model is specific: only the producer is transactional, and it can update the consumer's committed offset. Exactly-once delivery is supported in Kafka Streams through the transactional producer and read-committed consumers. To control shared clusters, Kafka can enforce quotas on requests to limit the broker resources clients use.
How does Pulsar store and serve events?
A Pulsar cluster has three parts: brokers, a BookKeeper cluster of bookies, and a metadata store. The Pulsar documentation describes the broker as a stateless component. It runs an HTTP server for administration and topic lookup, and a dispatcher for data transfer. Bookies store each message as a write-ahead log with several copies, and they also hold consumer cursors, which track where each subscription has read to.
Because storage sits in BookKeeper, you add bookies to grow capacity and throughput, and brokers can be scaled separately. Pulsar's per-topic storage is a managed ledger made of several append-only BookKeeper ledgers, and old ledgers can be deleted once all cursors have consumed them. That is the practical meaning of Pulsar being "segment-centric": data is stored in ledgers spread across bookies rather than in one partition file on one broker.
Do Kafka and Pulsar still need ZooKeeper?
Kafka no longer does. Kafka 4.0, released on 18 March 2025, was described by the project as the first major release to operate entirely without Apache ZooKeeper. It supports only KRaft mode, so clusters that still use ZooKeeper must migrate before they move to 4.0. Our guide to Apache ZooKeeper explains what the service did.
Pulsar has a choice of metadata stores. Its documentation lists Oxia as recommended for new clusters, ZooKeeper as a production-ready option that ships in the Pulsar package, and RocksDB for standalone use. Pulsar 5.0 adds a migration framework (PIP-454) to move metadata from ZooKeeper to Oxia while clients keep running.
What changed in Kafka 4.x and Pulsar 5.0?
Both projects have moved on since most comparisons were written. The release pages show the following.
| Project | Change | What it means for you |
|---|---|---|
| Kafka 4.0 (March 2025) | KRaft only; new consumer rebalance protocol (KIP-848) generally available; Java 17 for brokers, Connect and tools | Plan a ZooKeeper-to-KRaft migration and a Java upgrade before moving |
| Kafka 4.2 (February 2026) | Share groups (Queues for Kafka) declared production-ready | Kafka can now serve shared-queue patterns without a second system |
| Kafka 4.4.0 (22 October 2026) | Newest release listed on the Kafka downloads page | Confirm the current release and support window on the downloads page before you plan |
| Pulsar 5.0 (5 October 2026) | Long-term support release; Scalable Topics that split and merge segments at runtime; Oxia recommended; Java 21 or later for servers | Existing topics, subscription types, the v4 client and ZooKeeper stay supported on the 5.0 line, so adoption of new features is optional |
Pulsar's announcement lists limits for Scalable Topics in 5.0: no geo-replication or replicated subscriptions, and v4 clients cannot use them. Check that page against your needs before you adopt them.
Which subscription model fits your workload?
Pulsar documents four subscription types. Exclusive allows one consumer and is the default. Failover has one active consumer with standbys. Shared distributes messages round-robin with no ordering guarantee. Key_Shared sends all messages with the same key to one consumer, so order is kept per key. Retention and expiry are set per namespace: by default acknowledged messages are deleted at once, and retention keeps them for a set period.
Kafka's model is partition-based: within a consumer group, each partition is read by one consumer, so parallelism is limited by the partition count. Since Kafka 4.2, share groups give a queue-style option where several consumers cooperate on the same records. If your main need is flexible queue-style delivery, Pulsar has offered it for longer, and Kafka now has a comparable feature. Test both with your own ordering and redelivery needs.
How do multi-tenancy and geo-replication compare?
Pulsar is built as a multi-tenant system. A tenant is the top-level unit and can have its own authentication and authorisation. Namespaces group topics inside a tenant, and policies set on a namespace apply to every topic in it. Kafka documents quotas as its tool for sharing a cluster fairly between clients. If many business units will share one platform with their own policies, Pulsar's model is the more direct fit on paper. Kafka estates often reach the same result by running separate clusters or by adding governance around them.
For replication across sites, Pulsar offers asynchronous geo-replication, where messages are first stored locally and then replicated, and a synchronous mode through BookKeeper that confirms a write only after a majority of data centres have it, at the cost of added latency. Subscriptions are local, so each cluster keeps its own cursor. Kafka uses MirrorMaker 2, built on Kafka Connect, which replicates topics, consumer group offsets and ACLs and supports active/active and active/passive layouts. Its documentation advises running it close to the target cluster, because producers are more sensitive to high-latency links.
How do tiered storage options compare?
Both projects can move older data to cheaper storage. Pulsar offloads sealed ledgers to Amazon S3, Google Cloud Storage, Azure Blob Storage, Alibaba Cloud OSS, a filesystem, or S3-compatible stores such as MinIO and Ceph, and clients can still read the backlog normally. Kafka's tiered storage keeps a local tier on broker disks and a remote tier on external storage, controlled by settings such as local.retention.ms. Its documentation lists limits, including no support for compacted topics, and does not ship a remote storage implementation, so check the status for your Kafka version and storage provider first.
When should an enterprise choose Kafka, and when Pulsar?
| If this is your priority | Lean towards | Why, from the docs |
|---|---|---|
| Fewer moving parts to run | Kafka | Brokers and a KRaft quorum, with no separate storage layer or external coordination service |
| Skills, tooling and connectors already in the team | Kafka | Kafka Connect, Kafka Streams and MirrorMaker 2 are part of the project |
| Many tenants with separate policies on one platform | Pulsar | Tenants and namespaces are first-class concepts |
| Scaling storage and serving separately | Pulsar | Stateless brokers over BookKeeper bookies |
| Built-in cross-site replication | Pulsar | Asynchronous and synchronous geo-replication are documented features |
| Queue and stream on one platform | Either | Pulsar subscription types, or Kafka share groups from 4.2 |
When not to move: if a Kafka estate runs well and your needs are plain streaming, switching adds cost without a documented gain. If you adopt Pulsar, plan to run and learn three kinds of component (brokers, bookies and a metadata store), and plan the Java and upgrade steps in the 5.0 notes.
How do you pick between them in practice?
Published benchmark numbers come from specific hardware, settings and vendors, and they often disagree, so we have not repeated them here. A sound sequence is: list your must-have behaviours (ordering, tenancy, replication, retention); run a short proof of concept on both with your own message sizes and latency targets; measure operating effort as well as speed; then decide. Treat the result as a decision about people and operations as much as software.
Where do AI agents fit?
Event streams tell AI agents what is happening in the business as it happens. Whichever platform carries the events, agents need them delivered with meaning and access rules attached. ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. ElixirData keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and its AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights. For the pattern behind such systems, see our guide to agentic workflows.
To map one streaming decision your agents should make, and the events, context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
Is Apache Pulsar faster than Apache Kafka?
It depends on the workload, configuration and hardware. Published benchmarks come from different set-ups and disagree, so test both with your own message sizes, retention and latency targets.
Does Kafka still need ZooKeeper?
No. Kafka 4.0 supports only KRaft mode, so ZooKeeper clusters must be migrated before upgrading to 4.0 or later.
Can Pulsar handle both queuing and streaming?
Yes. Its Exclusive, Failover, Shared and Key_Shared subscription types let one platform serve both patterns. Kafka added share groups for queue-style use, called production-ready in 4.2.
Does Kafka support multi-tenancy and geo-replication?
Kafka offers quotas to control the resources clients use, and MirrorMaker 2 to replicate topics, consumer group offsets and ACLs between clusters. Pulsar has tenants, namespaces and built-in geo-replication.
When should an enterprise choose Kafka or Pulsar?
Choose Kafka when you want fewer components and a large ecosystem of tools and skills. Choose Pulsar when you need first-class multi-tenancy, separate scaling of storage and serving, or built-in geo-replication. Confirm with a proof of concept.
Sources
- Apache Kafka design documentation
- Apache Kafka 4.0.0 release announcement
- Apache Kafka 4.2.0 release announcement
- Apache Kafka downloads
- Kafka geo-replication with MirrorMaker 2
- Kafka tiered storage
- Apache Pulsar architecture overview
- Pulsar messaging concepts
- Pulsar multi-tenancy
- Pulsar geo-replication
- Pulsar tiered storage
- Announcing Apache Pulsar 5.0
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE