Key takeaway
- Compare data lineage tools by fit and status: OpenLineage, Unity Catalog, Purview, Collibra, Atlan. Learn how lineage is captured and adopted.
What are data lineage tools, and what should enterprise buyers decide first?
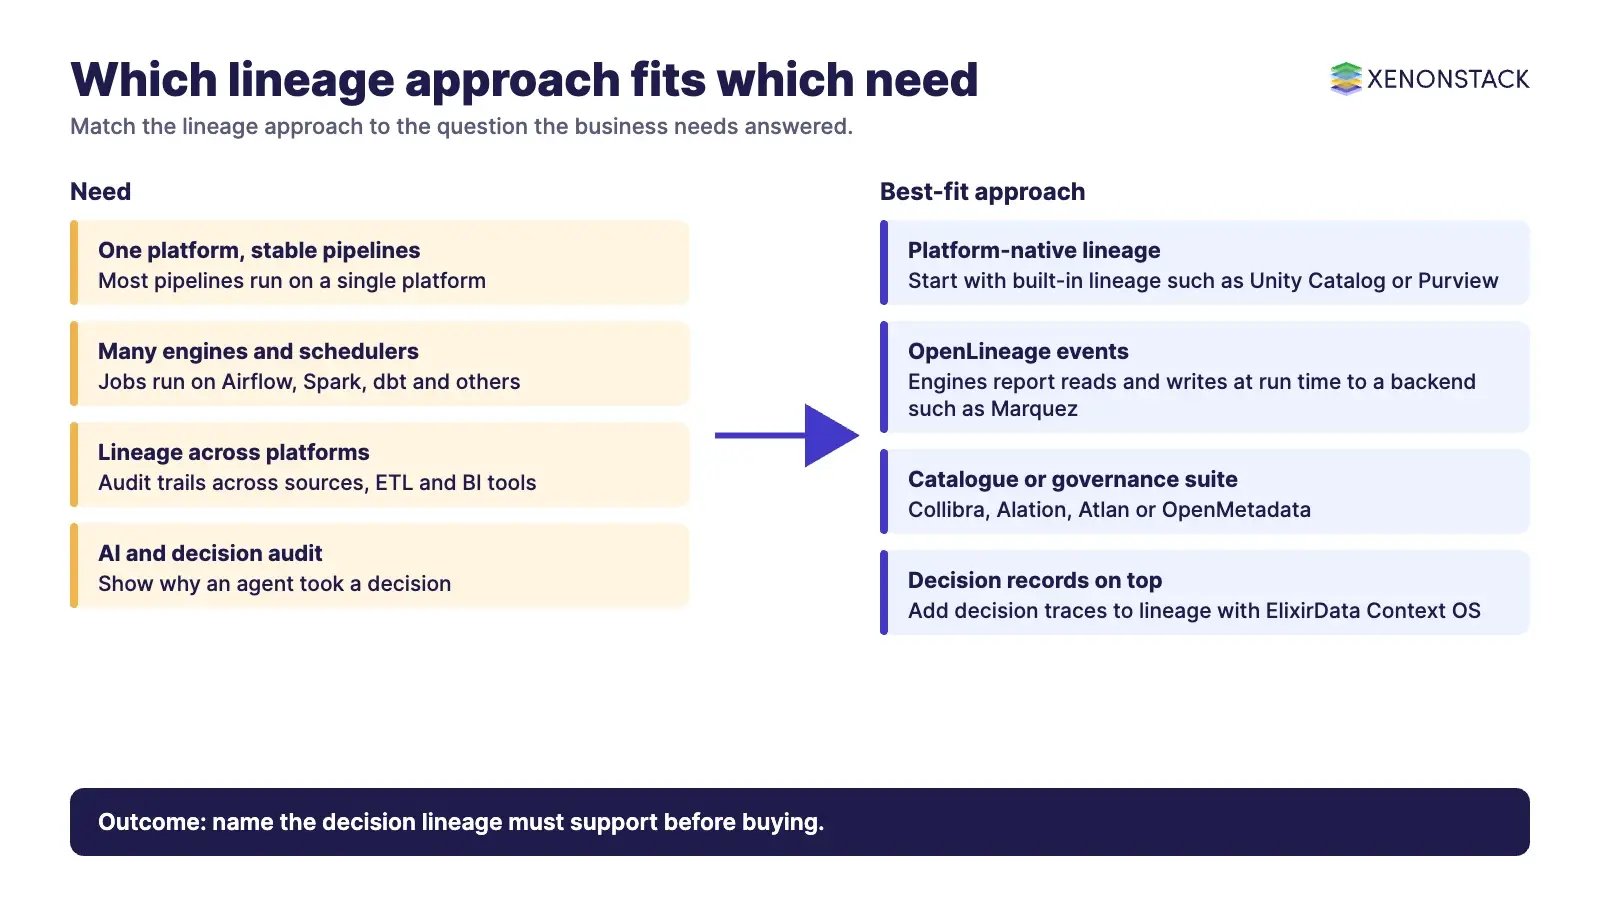
Data lineage tools record where data came from, which jobs and queries changed it, and which reports, models and agents now depend on it. Most enterprises buy one of three things: a lineage feature inside their platform (for example Microsoft Purview or Databricks Unity Catalog), a catalogue or governance suite with lineage (for example Collibra, Alation, Atlan or OpenMetadata), or an open standard with a backend (OpenLineage with Marquez). The first decision is not the vendor. It is the question lineage must answer, such as "which dashboards break if this column changes" or "which data trained this model".
This guide is for CDOs, Chief AI Officers, data architects and platform leads. It compares tool types with their current status, explains how lineage is captured, and sets out a sequence for adoption. For the open-standard route in more depth, read The Role of Open Standards in Advancing End-to-End Data Lineage.
What does data lineage record?
Data lineage is the documented path of data: its origin, each stop along the way, and how and why it changed. A business lineage view shows the flow from source to report without technical detail. A technical lineage view lets an architect drill down to table, column and query level.
A worked example: tracing a Customer ID column
Take a Customer ID column that starts in two source tables (Customer A and Customer B). It flows through an Accounts table and a Transactions table, into a Customer Rating table, and then into the Rewards and Marketing strategy tables. With lineage in place, an analyst can confirm that the column came from trusted sources and that every transformation was applied correctly. Without it, verifying the marketing team's numbers means reading pipeline code by hand.
Which data lineage tool fits which need?
The table groups tools by how they fit, using each vendor's own description. Check the current product page before shortlisting, because this market changes through acquisitions and renaming.
| Tool or standard | What it is | When it fits | Current status (read November 2026) |
|---|---|---|---|
| OpenLineage | Open standard and API for lineage collection at run time | You run several engines and schedulers and want one event format | Graduation-stage project of LF AI & Data; graduated July 2023 |
| Marquez | Metadata server, API and lineage graph for OpenLineage events | You want an open-source backend to store and view OpenLineage data | Reference implementation for OpenLineage; originally open-sourced by WeWork |
| OpenMetadata | Open metadata platform with lineage | You want an open-source catalogue with column-level lineage and OpenLineage input | Docs describe column-level lineage, automatic extraction and OpenLineage events |
| Microsoft Purview | Lineage inside the Microsoft data governance service | Your estate is mostly Azure, Power BI, Synapse and Databricks | Classic Data Catalog documentation points to the Unified Catalog for current lineage |
| Databricks Unity Catalog | Built-in lineage for queries run on Databricks | Your pipelines run mainly on Databricks | Column-level capture for supported queries; user-defined functions give table-level lineage only |
| Collibra | Governance suite with automated lineage | You need audit trails across sources, ETL and BI tools | Describes nearly 40 data sources and OpenLineage support |
| Atlan | Active metadata platform | You want lineage from SQL parsing, native integrations and OpenLineage | Describes column-level provenance across 80+ systems |
| Alation | Data catalogue with automated lineage | You want one cross-platform lineage graph in a catalogue | Describes lineage across 120+ connected systems; column-level not stated on its lineage page |
| Octopai | Automated lineage and catalogue platform | You are a Cloudera customer or want its lineage approach | Acquired by Cloudera; announced 14 November 2024 |
| Datameer | Low-code transformation for Snowflake | You transform data inside Snowflake and want lineage with it | Its site lists column-level and operational lineage under Callisto by Datameer |
Two names from older shortlists need care. Trifacta was a data preparation tool that Alteryx acquired, and Alteryx's own release notes list many Trifacta and Designer Cloud features as end of life, so treat it as a legacy item to confirm with the vendor rather than a lineage platform. CloverDX is a data integration product; confirm its lineage scope with the vendor before relying on it. When you evaluate any tool, test automation, cross-system coverage, column-level depth and how well it feeds governance workflows.
How is lineage captured, and which technique should you trust?
| Technique | How it works | When it fits | Limit |
|---|---|---|---|
| Parsing | Reads the SQL or code that processes the data | Warehouse and SQL-heavy estates | Needs support for each language and tool in the lifecycle |
| Runtime events | Engines report what they read and write as jobs run (the OpenLineage model) | Orchestrated pipelines on Airflow, Spark, dbt and similar | Only covers engines that emit events |
| Pattern-based | Infers lineage from patterns in metadata, not from code | Mixed tools where code is not accessible | Inferred links need validation |
| Data tagging | A transformation engine tags data as it moves and the tags are tracked | One controlled transformation engine | Works only if all flows go through that engine |
In practice enterprises combine techniques. Atlan, for example, describes using SQL parsing, native integrations and OpenLineage events together, and Collibra describes indirect lineage such as joins and conditional logic.
How is lineage implemented across the data pipeline?
Collect metadata at each stage into one repository, then analyse it. Each stage has a different job.
- Data ingestion: watch ingestion jobs for mapping errors between source and destination, and for transfer mistakes.
- Data processing: track the result of each action, such as reading a file, filtering or counting, and check each level for errors or compliance issues.
- Query history: record user queries and automated reports from warehouses, and run lineage on critical queries and reports.
- Data lakes: trace user access to objects and fields to find governance gaps, which are hard to enforce at volume. See Governed Data Lake: Architecture and Controls.
Lineage also supports data quality work, because a failed check is only useful if you can see what depends on the affected data. See Data Quality Management and its Best Practices and Data Observability in Data Streaming: 5 Key Pillars. If you are moving towards data mesh, owners of each data product need lineage too; the trade-offs are covered in Adopt or not to Adopt Data Mesh?
What has changed in data lineage recently?
| Change | What it means for buyers | Source |
|---|---|---|
| OpenLineage graduated within LF AI & Data in July 2023 | An open event standard is now a credible basis for multi-vendor lineage | LF AI & Data project page |
| Cloudera announced its acquisition of Octopai on 14 November 2024 | Independent lineage vendors are being absorbed into platform suites; check roadmap and support terms | Cloudera blog |
| Purview classic Data Catalog documentation directs readers to the Unified Catalog | Check which Purview experience your lineage documentation applies to | Microsoft Learn |
| Unity Catalog captures lineage automatically down to column level for supported queries | Platform-native lineage reduces setup, but column lineage is not captured when a source is referenced by file path | Databricks documentation |
Why do regulators and AI governance need lineage?
Three frameworks come up most often. The Basel Committee's BCBS 239 principles for risk data aggregation and risk reporting were published on 9 January 2013, after the financial crisis showed that banks could not aggregate risk exposures fully, quickly and accurately. Under GDPR Article 30, controllers must keep records of processing, including purposes, categories of data and recipients, with a limited exemption for organisations under 250 people. Under Article 10 of the EU AI Act, high-risk AI systems need data governance covering how training data was collected, where it came from and how it was prepared.
Lineage does not satisfy any of these on its own, but it is the evidence trail that makes the records credible. For AI, lineage shows which datasets fed a model. It does not show why an agent took a decision. That needs a decision record on top: ElixirData's Context OS describes gathering the information each decision needs and keeping a full record of every decision, and its Audit Agent assembles the decision trace, policy version and authority chain for auditor questions. Its own page notes that full decision lineage exists only for decisions made through Context OS. For the argument that lineage should carry decisions, see ElixirData's AI agents and data lineage.
What are the best practices for data lineage?
1. Automate extraction
Manual documentation cannot keep pace with production change. Prefer parsing, runtime events or catalogue crawlers, and keep manual entry for the gaps.
2. Validate with owners
Owners of tools and processes know best how timely and accurate their metadata is. Ask them to confirm or correct inferred links.
3. Include operational metadata
Capture metadata created by the operations that process, transform or move the data, not only table schemas.
4. Control who can change data
Keep sensitive data in a secure location with authorised access, so the owner knows who updates and uses it.
5. Name a lineage verifier
Assign a person to verify lineage for each domain, and hand over data handling rights clearly when ownership changes.
6. Extract and validate progressively
Record metadata in pipeline-stage order. Validate high-level links between systems first, then datasets, data items and transformation documentation.
7. Mark critical data
Identify critical and sensitive data and apply stricter policies to it.
8. Keep history
Retain the datasets that let you track data you may need later. Check retention limits in your tool: Unity Catalog, for example, keeps its lineage system tables on a rolling 395-day window by default.
9. Use lineage to trace report errors
When a report is wrong, follow the lineage back to the step that introduced the error.
What are the trade-offs, and when is a lineage programme not worth it?
| Area | Trade-off |
|---|---|
| Governance | Lineage shows access paths, so it needs its own access control. A catalogue that exposes sensitive column names is itself a risk. |
| Security | Platform-native lineage requires registered assets. Unity Catalog, for example, needs tables in a Unity Catalog metastore and permissions to view each object. |
| Cost | Platform-native lineage is cheapest to start but covers one platform. Suites cover more systems but add licence and integration effort. |
| When not to | If you run a handful of stable pipelines on one platform, use its built-in lineage and skip a separate suite. Do not buy a suite before you can name the decision lineage must support. |
What is a sensible adoption sequence?
- Pick one regulated or high-impact report and list its source systems.
- Turn on platform-native lineage where it exists.
- Add runtime events (OpenLineage) for orchestrated pipelines.
- Add a catalogue or governance suite when lineage must span platforms.
- Extend to AI training and inference datasets, then to decision records.
How should CDOs measure data lineage performance?
Tool counts measure presence, not value. Track these four dimensions, and set your own baselines because no universal target applies.
| Dimension | Metrics | What it tells you |
|---|---|---|
| Coverage | Share of critical data assets with end-to-end lineage | Is lineage broad enough to support governance? |
| Compliance readiness | Time from audit request to lineage evidence delivered | Can you answer examiners quickly? |
| Operational efficiency | Time to assess the impact of a change; error resolution time | Is lineage reducing manual investigation? |
| Trust and AI traceability | Share of AI training and inference datasets with validated lineage | Are model inputs defensible? |
What will change in data lineage over the next few years?
Expect lineage to be generated as a by-product of pipeline runs through open standards such as OpenLineage, rather than documented separately. Catalogues are also exposing lineage to AI agents: Atlan, for example, describes an MCP server through which agents query a column's provenance and policy before using it. These are vendor descriptions, so test them in your own environment.
To map one decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Related on XenonStack
- ElixirData: governed context for enterprise AI agents.
- OpenMetadata platform guide: metadata as context for agents.
- Agentic AI for data quality: what agents can fix safely.
Frequently asked questions about data lineage tools
What is a data lineage tool?
It records the origin of data, each stop along the way and how it changed, so teams can trace errors, assess the impact of changes and support audits.
What is OpenLineage?
An open standard and API for lineage collection. Data engines use it to report at run time which sources they read, what processing they perform and where results go. It is a graduation-stage project of LF AI & Data.
Is column-level lineage always available?
No. Unity Catalog captures it for supported queries but not when a source is referenced by file path, and user-defined functions give table-level lineage only. Check each tool's limits.
Which regulations make lineage important?
BCBS 239 on risk data aggregation, GDPR Article 30 on records of processing, and EU AI Act Article 10 on data governance for high-risk AI. Lineage supports the evidence for each but does not replace the records they require.
Should we buy a suite or use built-in lineage?
If most pipelines run on one platform, start with its built-in lineage. Choose a catalogue or governance suite when lineage must span several platforms.
How is lineage different from a decision trace?
Lineage shows how data moved and changed. A decision trace records what an agent or person decided, under which policy version and authority.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE