Key takeaway
- Plan a data fabric implementation: components, metadata pillars, a six-stage rollout, benefits to measure and risks, for CIOs, CDOs and architects.
A data fabric is a design approach that gives one governed view of data held across cloud, on-premises and edge systems, using active metadata, knowledge graphs, data virtualisation and automation. It is not a single product, and the same IBM description makes that point. This guide is about building one: what to put in place, in what order, what it costs you in effort and what to measure. If you are still choosing between a fabric and a domain-led model, read our Data Fabric vs Data Mesh decision guide first.
For a CIO, CDO or enterprise architect, the practical answer is to start with metadata and governance on a few high-value data sets, prove access and lineage there, and only then widen the integration layer. A fabric that begins with tooling and no ownership usually ends up as another catalogue nobody trusts. The benefits are covered in more breadth in Data Fabric Benefits and Use Cases.
What does a data fabric implementation include?
IBM, citing a Forrester report, lists six architecture components. We use them as the build checklist below. Our own notes on each are suggestions, not part of the IBM text.
| Component | What it covers | What to decide first |
|---|---|---|
| Data management | Governance, security and quality | Who owns each data set and which policies apply |
| Data ingestion | Moving or connecting data from sources | Which sources are in scope in phase one |
| Data processing | Preparing and transforming data | What stays in source systems and what is processed centrally |
| Data orchestration | Scheduling and automating flows | Which flows are critical and need failure handling |
| Data discovery | Cataloguing and metadata management | Which metadata types you will capture and keep current |
| Data access | Dashboards, visualisation and permissions | Who can see what, and how access is reviewed |
Three technologies sit underneath, according to the same IBM page: data virtualisation, which reaches data without physically moving it, federated active metadata, which uses knowledge graphs and AI to analyse and classify data continuously, and machine learning, which automates governance, lineage tracking and data quality fixes.
What are the main pillars of a data fabric?
Does the fabric collect every type of metadata?
Context is the core of the design. The fabric needs a connected store that can recognise and relate technical, business, operational and social metadata, so that a table name can be tied to an owner, a policy, a usage pattern and a business term. Our guide to data catalogues and data discovery covers the catalogue side.
Why must passive metadata become active metadata?
Passive metadata describes data once, in a catalogue. Active metadata is analysed continuously, so it can drive recommendations, flag changes and feed automation. In practice this means analysing what is already available for key statistics, modelling it as a graph, and using those signals to improve integration and management over time.
What does the knowledge graph add?
A knowledge graph adds a semantic layer, so relationships between data sets are explicit and readable by people and by machine learning. Integration engineers need standard ways to read from and deliver to it. Without that, adoption stalls.
Which integration styles must the backbone support?
A fabric should work with several delivery methods: ETL, streaming, replication, messaging and data virtualisation. It should serve IT teams with complex integration needs and business users who want self-service preparation. IBM also lists batch, real-time and change data capture as integration methods a fabric unifies.
How should you sequence a data fabric rollout?
The sequence below is our recommended order. It is an adoption approach rather than a published standard, so adapt it to your estate.
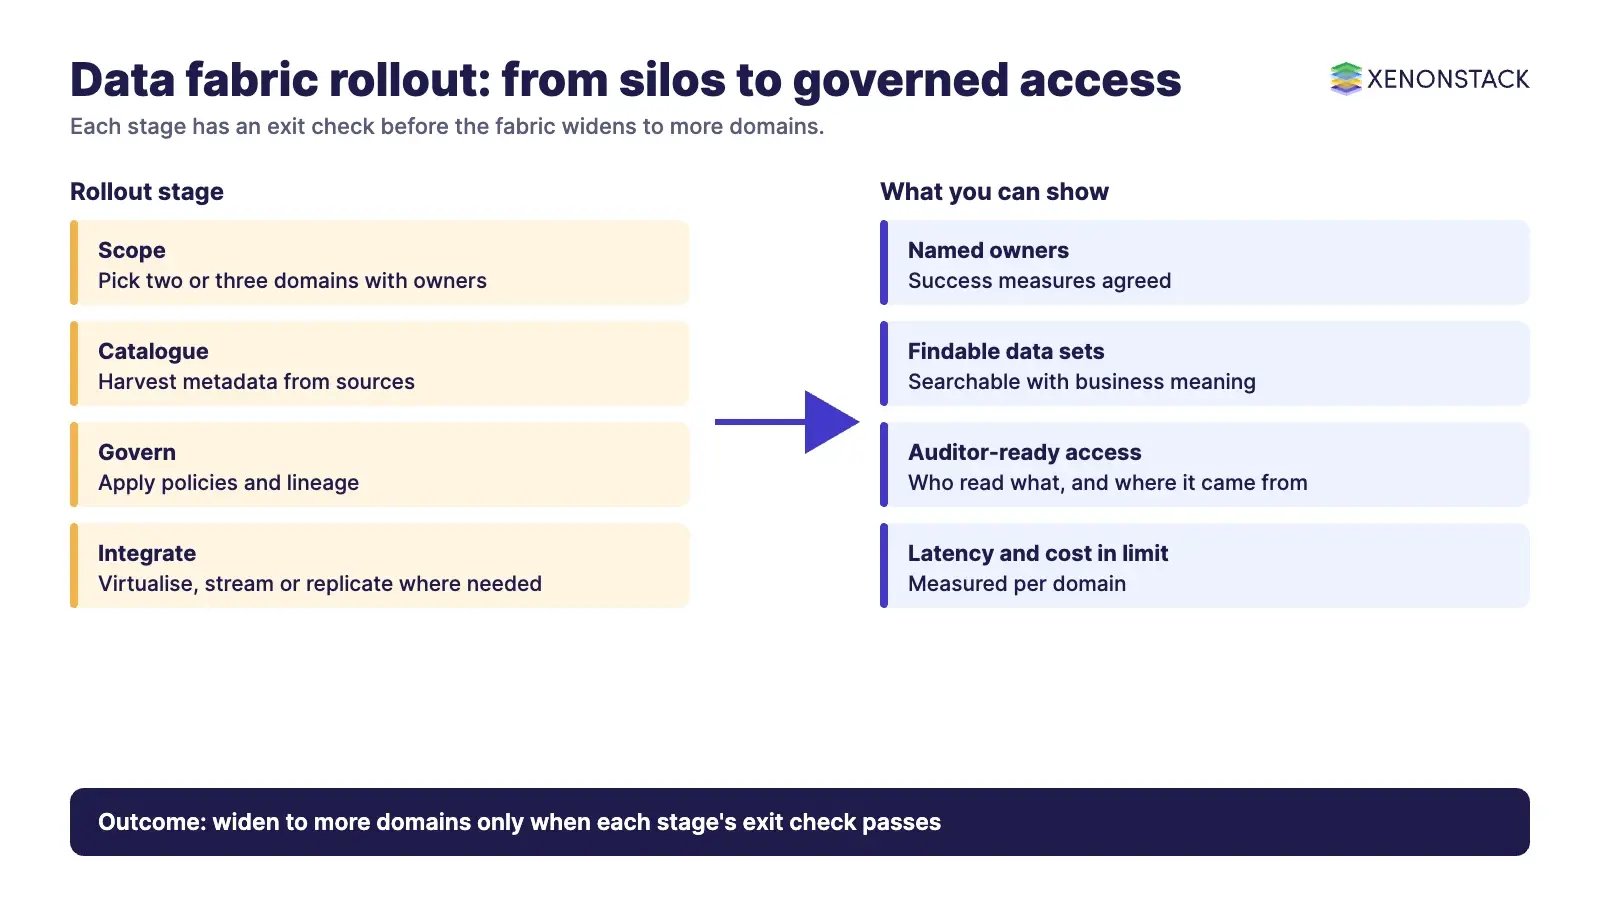
| Stage | What you do | Exit check |
|---|---|---|
| 1. Scope | Choose two or three data domains with a clear business question and named owners | Owners agreed, success measures written down |
| 2. Catalogue | Connect sources, harvest technical metadata, add business terms | Users can find the right data set without asking IT |
| 3. Govern | Attach policies, classification and access rules to the metadata | Access decisions and lineage can be shown to an auditor |
| 4. Integrate | Add virtualisation, streaming or replication only where a use case needs it | Latency and cost within the agreed limit |
| 5. Activate | Use active metadata for recommendations, quality alerts and automation | Fewer manual fixes than before |
| 6. Extend | Add domains and consumers, including AI and analytics workloads | Same controls hold at larger scale |
Data observability belongs alongside stages three to five, because a fabric depends on knowing when data is late, missing or changed. See How Data Observability Drives a Data Analytics Platform.
What benefits can a data fabric deliver?
| Benefit | How the fabric delivers it | Status and evidence |
|---|---|---|
| Less manual integration work | Automation reduces bottlenecks and eases technical teams' workloads | Stated by IBM as a benefit; measure in your own pipeline backlog |
| Wider access to data | Self-service discovery for engineers, scientists and business users | Stated by IBM; depends on catalogue quality |
| Lower risk | Visibility supports cataloguing and governance, with protections such as masking and encryption | Stated by IBM; verify in an audit of your own controls |
| Scalability and agility | Modular design that scales horizontally and vertically | Stated by IBM; test with your own workloads |
| Control wherever data sits | One set of governance and access rules across on-premises and cloud | Design principle, not a guarantee; needs consistent policy enforcement |
We have not found an independent source for a general percentage saving, so we do not quote one. Set a baseline for time to find data, time to deliver a new source to reports, and number of failed pipelines, then compare after each stage.
What problems does a fabric solve, and where does it fall short?
IBM describes the problems a fabric addresses: fast growth in structured, semi-structured and unstructured data, data lakes that lack metadata management, siloed business units, dark data that is unused or distrusted, and data gravity that makes large volumes hard to move. In its 2024 IBM Institute for Business Value study, as reported by IBM, only 29% of tech leaders strongly agree their data has the quality needed to scale generative AI.
| Risk | Why it happens | Mitigation |
|---|---|---|
| Catalogue nobody trusts | Metadata is harvested once and never kept current | Treat metadata as a product with owners and refresh rules |
| Slow queries | Virtualised access to remote sources adds latency | Replicate or cache only the hot data sets |
| Policy drift | Rules differ between source systems and the fabric | Define policy once and enforce it at the access layer |
| Tool-first rollout | A platform is bought before use cases are chosen | Start from two or three named business questions |
| Unclear ownership | Central team assumed to own all data quality | Agree domain owners and escalation before stage two |
A fabric may not be the right first step if you have one dominant platform, few sources and no governance gap. In that case a well-run warehouse or lakehouse with a catalogue is simpler. Our data strategy guide and data governance guide help you decide.
How does a fabric fit with AI agents and governed context?
AI agents need the same things a fabric provides: discoverable data, clear ownership and enforceable policy. ElixirData Context OS is described by its maker as a governance layer for enterprise AI agents that assembles context for a decision, checks policy before the agent reasons and before it acts, and records a trace of each decision. AgentAnalyst lets teams ask questions of their data in everyday language and records each step through Context OS for governance and audit. A fabric supplies the governed data underneath; these sit on top.
What has changed in how fabrics are built?
IBM's current description of a fabric centres on metadata, automation and a unified view of data, with the lifecycle of fabric components supported by MLOps and AI. For the design choice between a fabric and a domain-owned mesh, see our comparison.
To map one decision your agents should make, and the data, context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What is a big data fabric?
A data fabric is a design approach that creates a unified view of data across an organisation, using active metadata, knowledge graphs, data virtualisation and automation. IBM stresses that it is an approach, not a piece of software.
What are the main components of a data fabric?
IBM, citing Forrester, lists data management, data ingestion, data processing, data orchestration, data discovery and data access.
Does a data fabric move all data into one place?
No. Data virtualisation reaches data without physically moving it, although you can still replicate or process some data centrally where a use case needs it.
What is the difference between passive and active metadata?
Passive metadata is recorded once in a catalogue. Active metadata is analysed continuously, using knowledge graphs and AI, so it can drive recommendations and automation.
Where should a data fabric rollout start?
Start with two or three data domains that have named owners and a clear business question. Prove cataloguing, governance and lineage there before adding more integration.
Is a data fabric the same as a data mesh?
No. A fabric is metadata-led and automated, while a mesh organises data by domain ownership. They can coexist. Our Data Fabric vs Data Mesh guide covers the choice.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE