Augmented data quality (ADQ) means using machine learning, metadata and automation to profile, monitor, match and fix data, instead of relying only on hand-written rules and periodic audits. According to Gartner's definition, as reported by Pure AI in March 2024, augmented data quality solutions are "a set of capabilities for enhanced data quality experience" that use AI and machine learning, graph analysis and metadata analytics to find insights, suggest next actions and automate processes.
For a CDO, CTO or Chief AI Officer, the practical question is where automation helps and where people must still decide. This guide explains what ADQ does, how it differs from classic data quality management, what Databricks and Snowflake document today, and how to adopt it in a sensible order. For the cost side of poor data, read why data quality matters.
Key takeaways
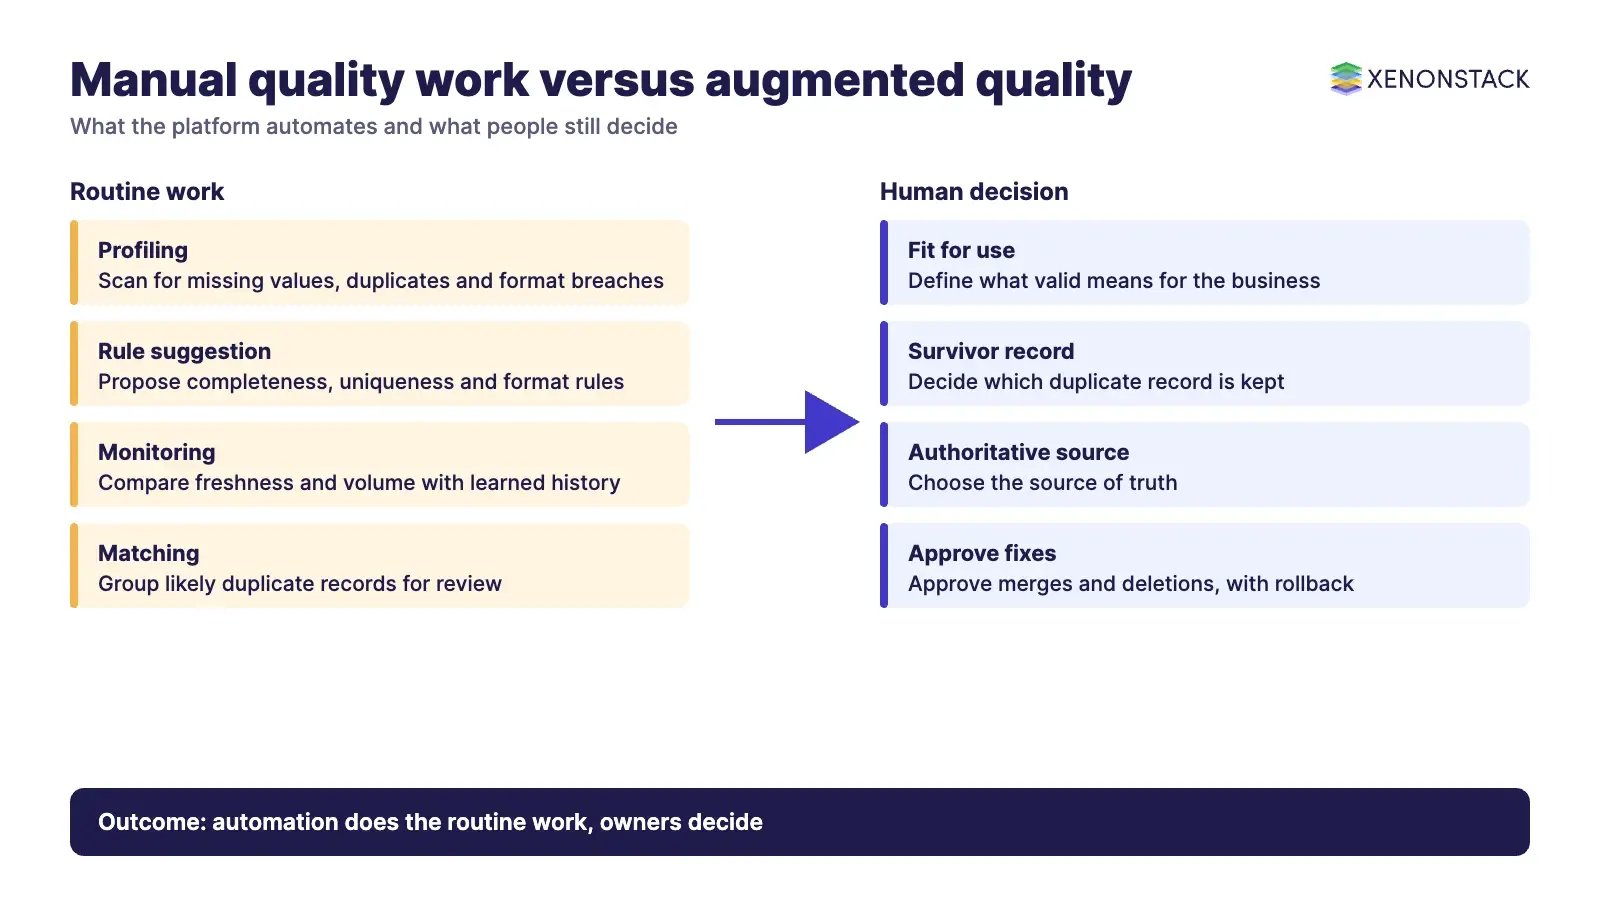
- ADQ automates the repetitive work of profiling, rule suggestion, deduplication and monitoring. People still own the definition of "fit for use" and the decision to change or delete records.
- Vendor platforms now ship this as built-in monitoring. Databricks documents freshness and completeness checks, and Snowflake documents volume and freshness anomaly detection.
- Start with one data domain, one measurable KPI and a rollback plan before you let automated fixes write to production data.
- AI models inherit the quality of the data they are trained and prompted with, so ADQ belongs in AI readiness planning, not only in reporting.
What is data quality, and why does it fail at scale?
Data quality is the degree to which data is fit for its intended use. Common dimensions include accuracy, completeness, consistency, timeliness, validity and uniqueness. The data quality metrics guide explains how to measure each one.
Manual quality work depends on review cycles: periodic audits, validation scripts and exception queues. As the number of tables, sources and pipelines grows, review capacity does not grow with it. Errors then reach reports and models before anyone sees them, and they look plausible, which makes them harder to catch than an empty result. The most frequent causes are listed in common data quality issues and how to fix them.
How does augmented data quality differ from traditional data quality management?
The main change is who does the routine work. In traditional management, engineers write and maintain every rule. In ADQ, the platform learns normal patterns from the data and metadata, proposes rules and raises alerts, and engineers review the proposals.
| Area | Traditional approach | Augmented approach |
|---|---|---|
| Rules | Written and updated by hand for each dataset | Suggested from data patterns and metadata, then reviewed |
| Detection | Scheduled audits and fixed thresholds | Continuous monitoring against learned history |
| Matching and merging | Scripted rules or manual review | Algorithmic matching with human review of uncertain cases |
| Unstructured data | Often out of scope | Increasingly in scope, with graph and extraction techniques |
| Ownership | Data engineering team | Shared between data owners, stewards and engineers |
What do platforms document today?
Two widely used platforms describe their data quality monitoring in their own documentation. Read the linked pages for current limits, because features and editions change.
| Platform | What its documentation says | Worth checking |
|---|---|---|
| Databricks data quality monitoring | Anomaly detection checks table freshness and completeness from historical patterns, does not modify monitored tables, and uses Unity Catalog lineage to point to the likely upstream cause. | Needs Unity Catalog and serverless compute. Views and foreign tables are not supported, and completeness does not consider null fraction. |
| Snowflake data quality monitoring | Data metric functions measure attributes such as NULL counts, and expectations turn a measurement into a check. Snowflake can detect anomalies in the volume and freshness of data. | Requires Enterprise Edition. The default schedule runs a metric function once every hour, and billing applies to scheduled runs. |
Both are built-in monitors rather than complete ADQ suites. Dedicated tools add matching, stewardship workflows and rule management, so compare them against your own list of needs.
Which data quality problems does ADQ address?
ADQ helps most where the problem is repetitive and pattern-based. It helps less where the answer depends on business judgement.
| Problem | How ADQ helps | Where people still decide |
|---|---|---|
| Duplicate records | Matching algorithms group likely duplicates for merging | Which record survives, and what counts as the same customer or product |
| Wrong or invalid values | Validation rules flag out-of-range and mis-keyed values at entry | What is valid for the business |
| Inconsistent formats | Standardisation rules for dates, units and names | The target standard |
| Fragmented sources | Profiling across sources shows where definitions diverge | Which source is authoritative |
| Stale data | Freshness monitoring alerts when updates arrive late | How fresh each dataset must be |
Related reading on observability, which watches the pipeline that carries the data: pillars of data observability.
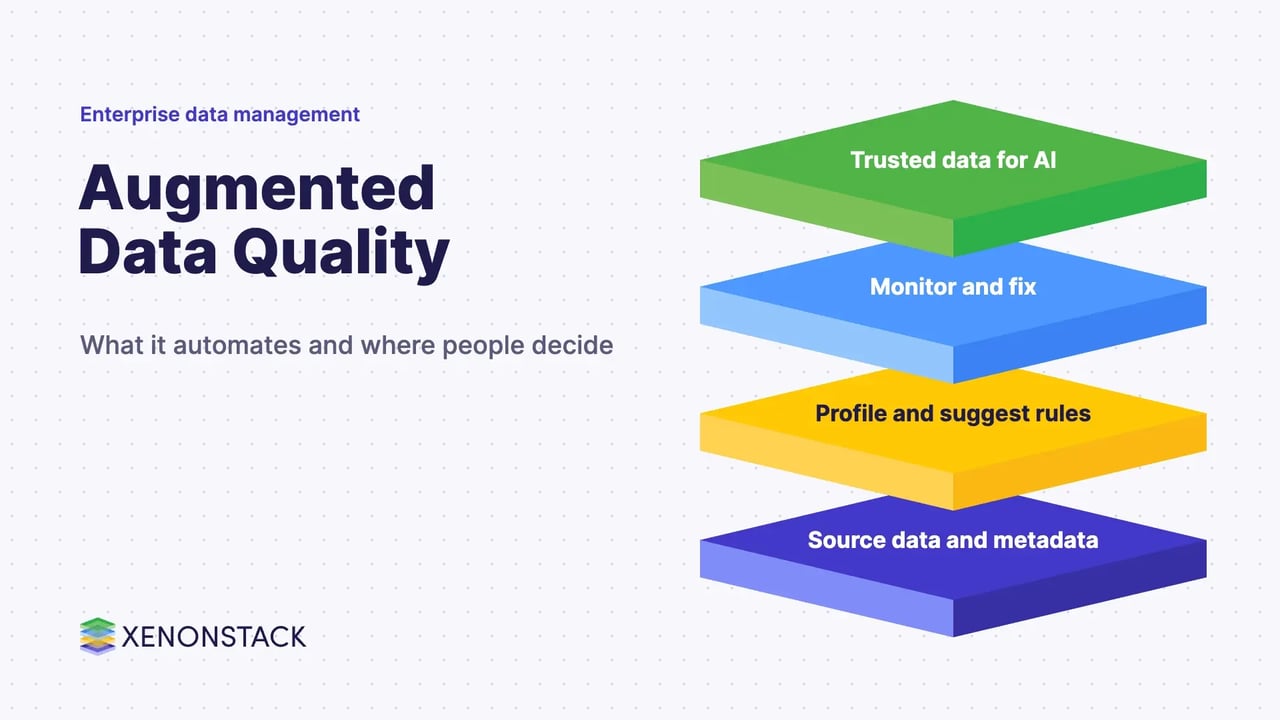
How does an ADQ workflow run?
- Ingest: data arrives from source systems.
- Profile: the tool scans for missing values, duplicates, format violations and range breaches.
- Apply rules: suggested and hand-written rules run against the data.
- Fix or quarantine: cleansing, standardisation and deduplication run, or bad records are held for review.
- Validate: results are checked against agreed thresholds before moving downstream.
- Monitor: quality metrics are tracked over time and alerts fire when thresholds are breached.
What are the core features of an augmented data quality tool?
Automated profiling and rule suggestion
The tool reads the data and its metadata and proposes completeness, uniqueness and format rules, so engineers review suggestions instead of writing every rule.
Matching and merging
Algorithms score how likely two records describe the same entity and group them, with a review queue for borderline matches.
Continuous monitoring and alerts
Metrics are tracked over time and compared with learned history. Ataccama reports that the 2026 Gartner Magic Quadrant now treats alerts and visualisation as a standalone capability.
Handling of unstructured and semi-structured data
The same Ataccama summary says the 2026 report adds graph technologies to its unstructured data scope. Treat this as an area to test with your own files before relying on it.
Integration with the wider data stack
Checks work best when they sit next to the catalogue, lineage and pipelines. See data mesh adoption for how domain teams can own quality for their own data products.
What has changed in 2026?
As reported by Ataccama (February 2026, updated April 2026), the 2026 Gartner Magic Quadrant for Augmented Data Quality Solutions evaluates AI assistants, names generative and agentic automation in its innovation criterion, and replaces "AI/ML development" with "analytics and AI readiness", which includes monitoring production AI pipelines. It also notes data products and data contract SLAs as an emerging use case. This is a vendor's summary, so confirm the details with Gartner.
What are the six best practices for implementing ADQ?
- Automate the repetitive tasks first. Profiling, monitoring and format standardisation remove the most manual work and give rule suggestion a baseline.
- Start small and tie it to a KPI. Pick one domain where quality can be measured against a business outcome, then expand.
- Deal with duplicates early. Duplicates distort counts and joins, so removing them shows quick, visible gains.
- Make every automated change reversible. Keep backups, an audit log and a rollback path before automation edits or deletes records.
- Scope rules to data types and domains. Numeric ranges, categorical lists and date formats need different checks.
- Name an owner for each dataset. Someone must approve rules, review matches and act on alerts.
When is ADQ not the right answer?
- When the data has no agreed definition. Automation will enforce a vague rule consistently, not correct it.
- When volumes are small and stable. A few well-owned SQL checks may be enough.
- When fixes carry legal or financial weight. Keep a person in the approval step, and read what agents can fix safely before letting any automation write back.
- When the root cause is upstream. Alerts help, but the permanent fix is validation at the source system.
Why does ADQ matter for AI and analytics readiness?
Models and agents inherit the quality of their inputs. Duplicated, stale or inconsistent data produces confident answers on a weak base, and no model tuning removes that. ADQ checks training sets, retrieval sources and reporting tables against agreed thresholds before they are used. The wider practice is covered in augmented data management best practices, and our augmented data quality solutions page describes how we approach delivery.
Quality is also one input to governed context. According to its site, ElixirData lists quality alongside metadata, lineage and definitions as part of the data context that agents reason on. AgentAnalyst lets teams ask questions of enterprise data in plain language, which makes trustworthy source data matter even more.
How should you sequence adoption?
| Stage | Action | Exit test |
|---|---|---|
| 1. Baseline | Profile one high-value domain and agree the quality dimensions | Owner and KPI named |
| 2. Monitor | Turn on built-in or dedicated monitoring in alert-only mode | Alerts reviewed weekly, noise understood |
| 3. Fix | Automate low-risk fixes with backup and audit log | Rollback tested |
| 4. Extend | Add matching, more domains and AI pipeline inputs | KPI improving for two cycles |
To map one decision your agents should make, and the data quality, context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is augmented data quality?
It is the use of machine learning, metadata analytics and automation to profile, monitor, match and fix data. Gartner's definition, as reported by Pure AI, calls it a set of capabilities for an enhanced data quality experience.
How is it different from data quality management?
Traditional management relies on hand-written rules and periodic audits. ADQ suggests rules, monitors continuously and automates routine fixes, while people review and approve.
Do Databricks and Snowflake offer it?
Both document built-in data quality monitoring. Databricks describes freshness and completeness anomaly detection, and Snowflake describes volume and freshness anomaly detection plus data metric functions. Check each page for current limits.
Can ADQ fix data automatically?
It can for low-risk, rule-based fixes such as formats. Keep backups, an audit log and human approval for merges and deletions.
Where should we start?
Pick one domain, one KPI and one owner, run monitoring in alert-only mode, and add automated fixes once rollback has been tested.
More reading: augmented data management solutions and data management services and solutions.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE