Key takeaway
- Data denormalization adds redundant data to a normalised database to speed up reads. Learn the techniques, risks and when it pays off for your workload.
Data denormalization is the deliberate addition of redundant or pre-combined data to a normalised database so that common reads need fewer joins. You trade some write speed, storage and consistency effort for faster, simpler queries. It is a targeted optimisation for read-heavy paths, not a replacement for a sound normalised design.
This guide explains how denormalization differs from normalization, the main techniques, when it pays off and when it does not, and the controls that keep duplicated data trustworthy. If you are still choosing a database model, read SQL vs NoSQL vs NewSQL first.
What is data denormalization, and how is it different from normalization?
According to Microsoft Learn, normalization is "the process of organizing data in a database", creating tables and relationships by rules that remove redundancy and inconsistent dependency. Its benefits include less redundancy and easier maintenance, because an address that lives in one table is changed in one place. The same page notes that many small tables may degrade performance, and that third normal form is considered the highest level necessary for most applications.
Denormalization starts from a normalised design and selectively reverses part of it. It is not the same as unnormalised data: the model was designed properly first, and each copy of data is a conscious choice with a named owner and a refresh rule.
| Aspect | Normalised design | Denormalized design |
|---|---|---|
| Main goal | One authoritative copy of each fact | Fast, simple reads for known query patterns |
| Reads | More joins across smaller tables | Fewer joins, wider rows or documents |
| Writes | Change one place | Change every copy, or refresh a derived store |
| Typical fit | Transactional systems | Reporting, search, read-heavy APIs, analytics |
Which denormalization techniques do teams use?
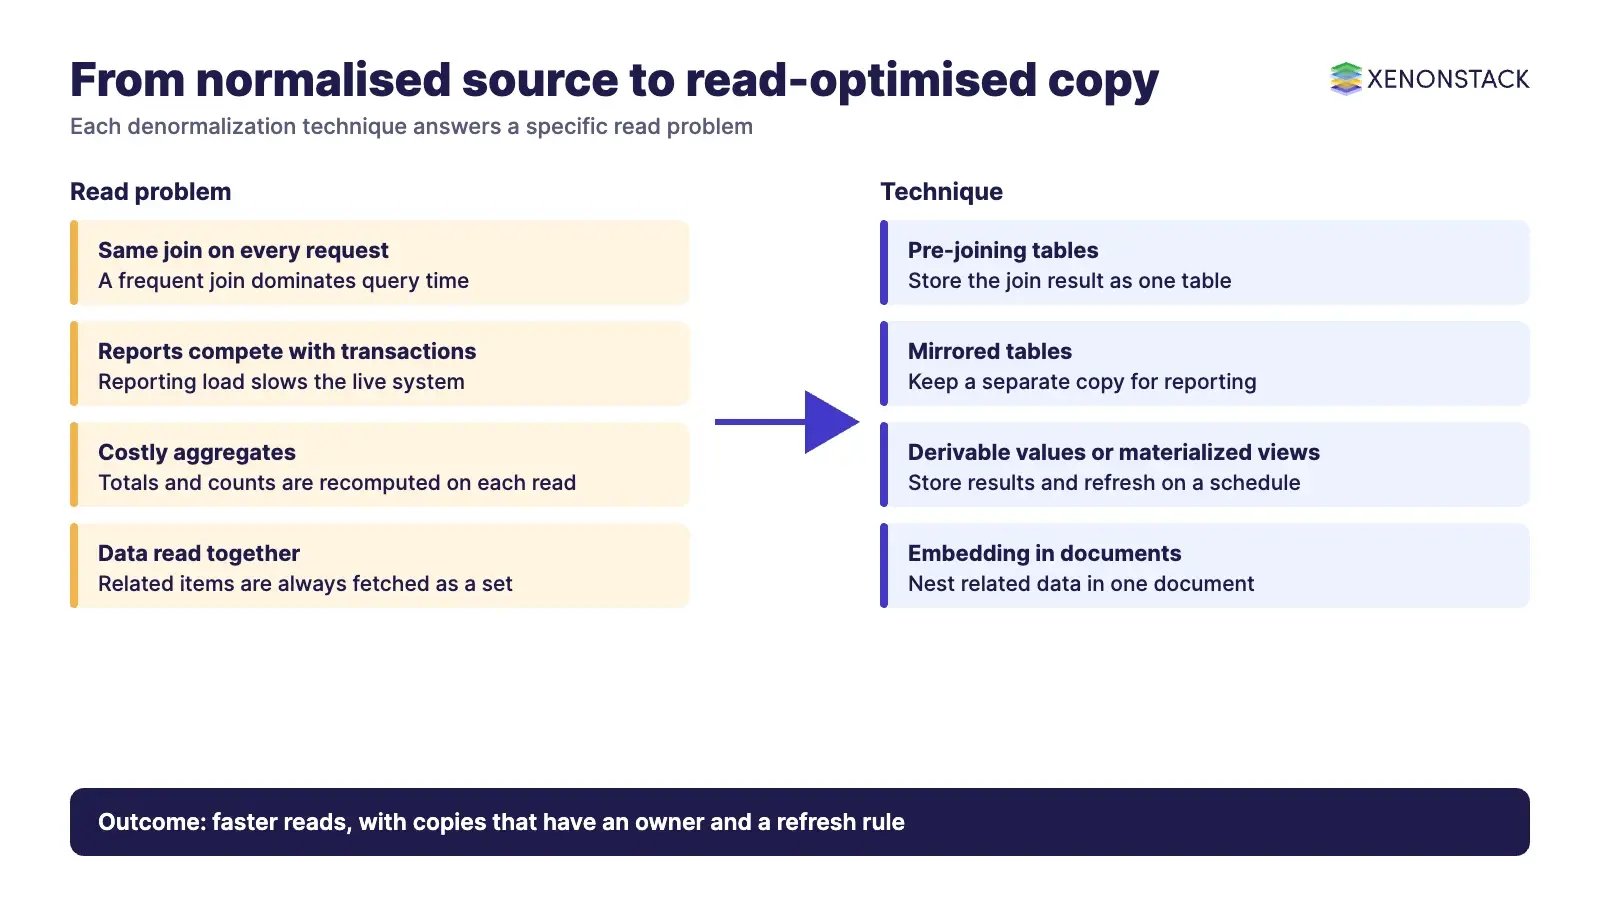
Most denormalization falls into a few patterns. The right one depends on where the read cost sits and how often the source data changes.
| Technique | What it does | When it fits | Main cost |
|---|---|---|---|
| Pre-joining tables | Stores the result of a frequent join as one table | The same join runs on every request | Rebuild or sync when either source changes |
| Mirrored tables | Keeps a copy of a table for a different workload, such as reporting | Reports should not compete with transactions | Copy lag and extra storage |
| Table splitting | Separates rarely used or heavy columns from hot ones (vertical) or rows by range (horizontal) | Hot and cold data have different access patterns | More design and routing logic |
| Storing derivable values | Keeps totals, counts or flags instead of recomputing them | Aggregates are read far more often than written | Values must be updated with every change |
| Materialized views | Stores the result of a query inside the database | Tolerable staleness, expensive aggregation | Refresh scheduling and stale reads |
| Embedding in documents | Nests related data inside one document | Data is read together and changes rarely | Document growth, duplicated updates |
Two of these have vendor documentation worth reading. According to the PostgreSQL documentation, a materialized view persists query results "in a table-like form", is returned like a table when queried, and is refreshed with REFRESH MATERIALIZED VIEW. The same page says the data is not always current, and that if you can tolerate periodic updates the performance benefit can be substantial (PostgreSQL: Materialized Views). For documents, Microsoft Learn says denormalized models typically give better read performance and normalised models typically better write performance, and that embedding suits data that is queried together, changes infrequently and does not grow without bound (Azure Cosmos DB: data modeling).
When does denormalization pay off, and when does it not?
Denormalize only after you have measured a real read problem. The table below is a decision aid, not a rule.
| Situation | Denormalize? | Why |
|---|---|---|
| A report joins many tables and runs often | Often yes | Pre-computed results remove repeated join work |
| Source data is stable and read together | Yes | Few updates, so few copies to keep in step |
| Shared data changes many times a day | No | Each change must reach every copy |
| Related items grow without limit | No | Embedded collections become unbounded, as Microsoft Learn warns for document models |
| Strict consistency is a legal or financial duty | Only with controls | Duplicated values can disagree |
| The query is slow for another reason | No | Check indexes, query plans and statistics first |
A practical sequence is: measure the slow query, add or fix indexes, then try a materialized view or summary table, and only then change the base model. This keeps the authoritative normalised tables intact and makes the performance copy easy to rebuild.
What are the risks of denormalized data?
The central risk is that the same fact exists in several places and the copies drift apart. Normalization exists to prevent three anomalies, and denormalization can bring them back.
| Risk | What goes wrong | Control |
|---|---|---|
| Update anomaly | One copy is changed and others keep the old value | Change copies in one transaction, or derive them from one source |
| Deletion anomaly | Removing a row also removes facts held only there | Keep an authoritative table that is never the denormalized copy |
| Insertion anomaly | A fact cannot be recorded without unrelated attributes | Keep the normalised source for writes |
| Larger storage and slower writes | More data, more work per change | Measure write cost before and after |
| Stale derived data | A summary shows yesterday's numbers | State the refresh schedule and show the as-of time |
Triggers, transactions and scheduled refresh jobs are the usual controls. Whichever you choose, treat the denormalized structure as derived data: document its source, its owner and its refresh rule, and test it. Our guide to database testing covers how to check that data stays consistent after changes.
How does denormalization fit analytics, lakehouses and AI?
Analytical models already accept redundancy. Star-style designs keep wide, query-friendly tables, and our snowflake and star schema guide shows the performance trade-off between them. For a wider view of where analytical data lives, see data warehouse vs data lake vs data mesh and data lakehouse architecture. Distributed stores such as CockroachDB add a further design question, because data placement affects how costly a join or a multi-row update is.
For enterprise AI the same rule applies: every denormalized copy that an agent reads is a copy someone must govern. ElixirData keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights. Both depend on knowing which copy of a number is the authoritative one. Broader data issues are covered in big data challenges and what is a database.
To map one data decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is data denormalization in simple terms?
It is adding redundant or pre-combined data to a normalised database so that frequent reads need fewer joins, at the cost of slower writes and extra effort to keep copies consistent.
Is denormalization the same as unnormalised data?
No. Denormalization is applied to a design that was normalised first, and each copy is a deliberate choice. Unnormalised data was never organised by those rules.
When should I avoid denormalization?
Avoid it when shared data changes often, when related items grow without limit, or when the slowness comes from missing indexes or poor query plans. Measure first.
Is a materialized view a form of denormalization?
It is a common way to do it. According to the PostgreSQL documentation, it stores query results like a table and must be refreshed, so its data may not be current.
How do I keep denormalized data consistent?
Keep a normalised source of truth, update copies in one transaction or through a scheduled refresh, document the owner and refresh rule, and test for drift.
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE