Key takeaway
- Golang for big data explained: goroutines, channels, worker pools, race detector and GC tuning, plus where Spark is the better tool, sourced from Go docs.
Golang (Go) is a good fit for the concurrent services around a big data platform: ingestion workers, stream consumers, APIs and operators. Its goroutines and channels let one program run very large numbers of independent tasks without hand-written thread management. It is not a replacement for a distributed engine such as Apache Spark, which documents Java, Scala, Python and R as its supported languages.
For enterprise architects and engineering leads, the useful question is where Go belongs in the data stack, not whether it is "better". This guide covers what Go gives you, how goroutines, channels, worker pools and the race detector work, how to tune memory, and when to pick another tool. For the surrounding platform, see our guides to the big data platform and to data ingestion; for a comparison with another systems language, see Rust for big data.
What does Go offer for big data work?
According to the Go FAQ, Go became a public open source project on 10 November 2009, after design work began in September 2007. The language is compiled and statically typed, and concurrency is built into the language rather than added by a library. The Go release history lists Go 1.27.0 (19 August 2026) as the latest major release, and says each major release is supported until two newer major releases exist, so Go 1.26 and 1.27 are the supported versions at the time of reading (13 November 2026).
| Capability | What the Go documentation says | Why it matters for data services |
|---|---|---|
| Goroutines | Cheap functions run concurrently, with a stack of a few kilobytes that the runtime resizes (Go FAQ) | Many simultaneous connections, partitions or files per process |
| Channels | Typed conduits that combine communication with synchronisation (Effective Go) | Hand data between pipeline stages without shared locks |
| Race detector | The -race flag reports data races at run time (Go race detector article) | Catches concurrency faults in tests before production |
| Garbage collector | Concurrent mark-and-sweep, tunable with GOGC and GOMEMLIMIT (Go FAQ, GC guide) | Predictable memory behaviour when tuned and profiled |
| Standard toolchain | Modules and the testing framework are part of the standard Go toolchain | Simple builds and CI for platform teams |
Where does Go fit next to Spark, Beam and the lakehouse?
Go works best as the glue and the services layer. Heavy distributed transformation stays in an engine built for it. The table shows the position of each option, using each project's own documentation.
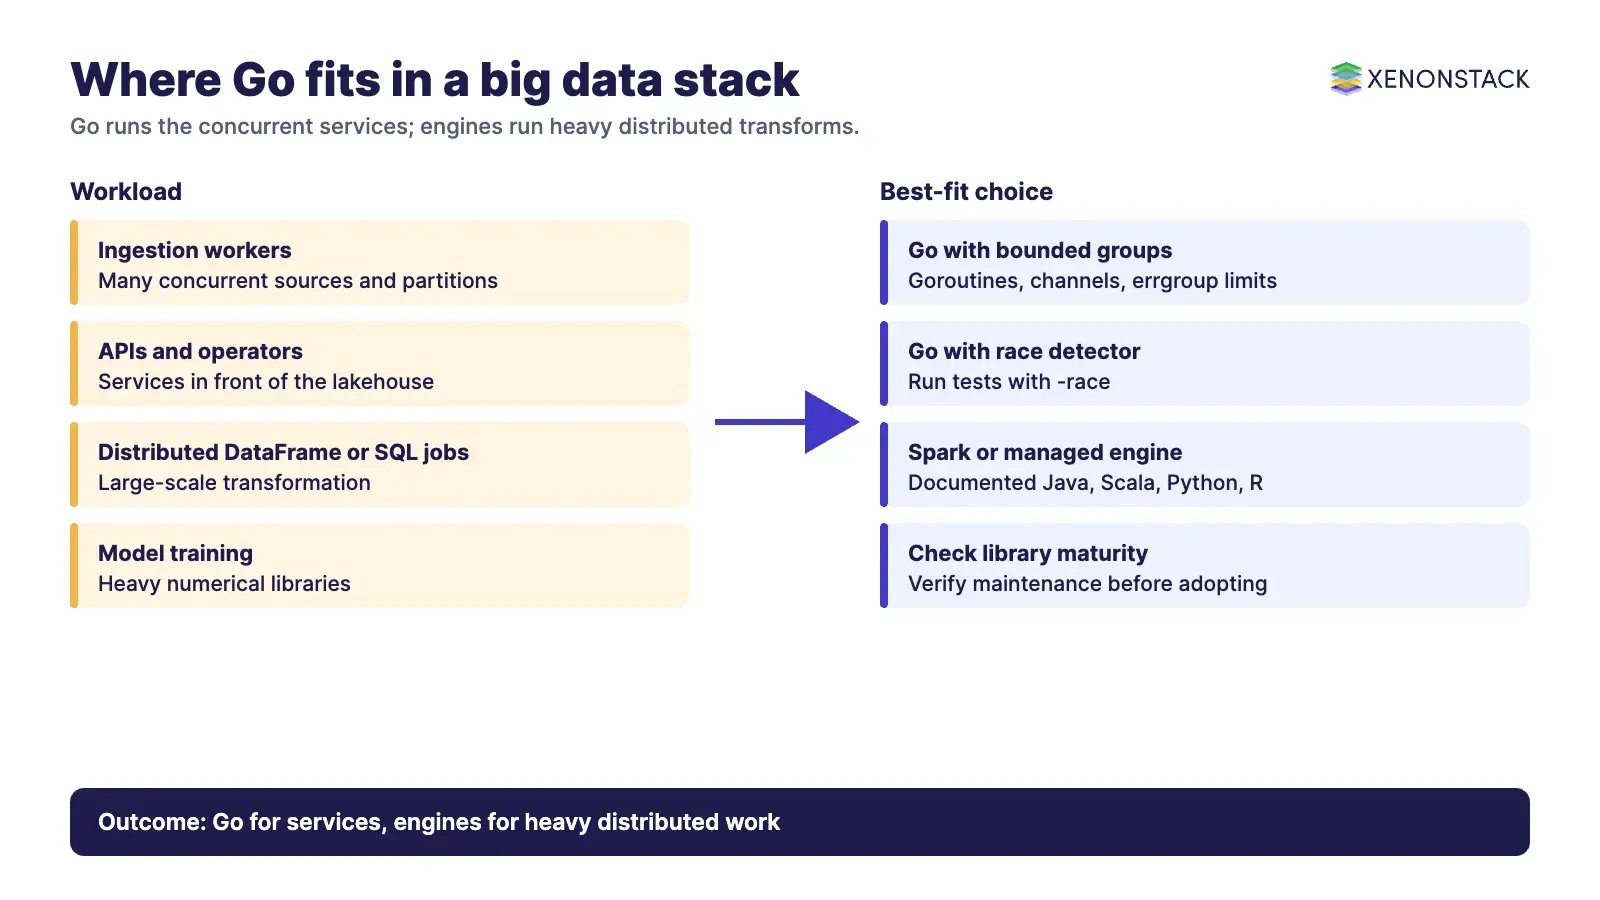
| Workload | Fit for Go | Current status (source) |
|---|---|---|
| Distributed DataFrame or SQL processing | Poor fit as the main language | Spark documents Java, Scala, Python and R, and marks SparkR as deprecated; the page covers Spark 4.3.0 (Spark docs) |
| Calling Spark from Go | Possible, experimental only | The Spark Connect client for Go says it is highly experimental and should not be used in any production setting (spark-connect-go README) |
| Portable batch pipelines | Possible through Apache Beam | The Beam Go SDK supports most batch features, but built-in transforms may be missing or incomplete (Beam Go SDK page) |
| Ingestion workers, API gateways, operators, stream consumers | Strong fit | Concurrency primitives are core to the language; see the patterns below |
| Model training and heavy numerical analysis | Check library maturity first | Verify each library's own repository for maintenance before adopting |
If your platform is built on open table formats, read data lakehouse architecture first, then decide which components are Go services and which are engine jobs. For a streaming reference built on Spark, see real-time streaming with Apache Spark.
How do goroutines and channels work?
A goroutine is started by putting the go keyword before a function call. Effective Go describes it as a function executing concurrently with other goroutines in the same address space, costing little more than the allocation of stack space. The Go FAQ adds that the runtime multiplexes goroutines onto operating system threads, and moves others to a runnable thread when one blocks, so the programmer sees none of this. The FAQ states that hundreds of thousands of goroutines in one address space are practical, and that if goroutines were plain threads, system resources would run out at a much smaller number.
Channels carry values between goroutines. Effective Go explains that an unbuffered channel combines communication with synchronisation, and summarises the idea as: do not communicate by sharing memory; instead, share memory by communicating. It also warns that the approach can be taken too far, and that a mutex around a counter is sometimes the simpler tool. For shared state, the sync package provides mutexes and wait groups, and the sync/atomic package provides low-level atomic primitives.
Which concurrency patterns suit data pipelines?
| Pattern | What it does | Source |
|---|---|---|
| Worker pool | A fixed number of goroutines read from one channel; the pool size limits simultaneous work | Effective Go |
| Fan-out and fan-in | Several goroutines read from one channel (fan-out); several channels merge into one (fan-in) | Go blog: pipelines |
| Cancellation | A shared done channel, closed once, tells every stage to stop and avoids leaked goroutines | Go blog: pipelines |
| Bounded groups with errors | errgroup propagates the first error, cancels the shared context and can cap active goroutines with SetLimit | errgroup package |
A bounded group is usually the safest starting point for partition or file processing, because it limits concurrency and stops the batch on the first error:
g, ctx := errgroup.WithContext(ctx)
g.SetLimit(8) // at most 8 active goroutines
for _, part := range partitions {
    g.Go(func() error { return process(ctx, part) })
}
if err := g.Wait(); err != nil {
    return err
}
Effective Go notes that goroutine loops written this way share the loop variable in Go versions before 1.22, so build with a current toolchain. The sync.WaitGroup type also gained a Go method in Go 1.25.0, which its documentation recommends over manual Add and Done calls.
Is Go parallel as well as concurrent?
Effective Go separates the two ideas. Concurrency is structuring a program as independently executing components; parallelism is executing calculations at the same time on multiple CPUs. It says Go is a concurrent language, not a parallel one, and that not every parallelisation problem fits its model. In practice the runtime spreads goroutines across the cores set by GOMAXPROCS, which defaults to the number of CPUs. The Go 1.25 release notes add container-aware GOMAXPROCS, which matters when pipelines run in limited-CPU containers; confirm the exact behaviour on the release notes for your version.
How do you find data races and leaks before production?
A data race happens when two goroutines access the same variable concurrently and at least one access is a write. The Go race detector finds these at run time when you build or test with -race, and prints stack traces for the conflicting accesses. It only reports races in code that actually runs, so test coverage matters. Its documentation says memory use may increase by 5 to 10 times and execution time by 2 to 20 times, so run it in tests and canary environments. Pair it with tests as described in our guide to Go unit testing.
How do you tune Go memory for large data volumes?
The Go garbage collector guide models collector cost as physical memory plus CPU time, and says doubling GOGC roughly doubles heap overhead and roughly halves collector CPU cost. The default is 100. The memory limit, added in Go 1.19 and set with GOMEMLIMIT, is a soft cap on total runtime memory; the guide suggests leaving 5 to 10 per cent headroom in containers. It warns that too low a limit makes the collector run constantly, and recommends profiling before tuning.
| Situation | Guide recommendation |
|---|---|
| Service in a container with fixed memory | Consider a memory limit with headroom |
| Program already close to the environment's limit | Do not rely on a limit to avoid out-of-memory kills; it trades that risk for severe slowdown |
| Unknown input size and memory, such as a CLI tool | Avoid a memory limit |
| Any tuning | Profile with CPU and heap profiles first |
What governance, security and cost points apply?
Treat Go data services like any production software. Pin and audit dependencies using modules and vulnerability scanning, as covered in Go package management. Keep concurrency limits explicit, because an unbounded goroutine per request design can consume unlimited resources, as Effective Go points out. Log pipeline decisions with enough context to audit them. On cost, concurrency limits and memory settings are the levers you control; measure them in your own environment instead of relying on published speed comparisons.
When should you not use Go for big data?
| Situation | Better choice | Reason |
|---|---|---|
| Large-scale distributed transformation | Spark or a managed engine | Spark documents its own language APIs; the Go client is experimental |
| Interactive analytics by business users | Warehouse or lakehouse SQL engine | Users work in SQL, not services |
| Model training or specialist numerics | A language with a mature library for that task | Check library maintenance first |
| Team has no Go skills | Start with a small service, not a platform rewrite | Skills and operating cost matter more than syntax |
How should an enterprise adopt Go in its data stack?
- Pick one bounded service, such as an ingestion worker or an API in front of the lakehouse.
- Set concurrency limits, context cancellation and error handling from the first commit.
- Run tests with
-raceand profile memory before changing GOGC or GOMEMLIMIT. - Pin dependencies, scan them for vulnerabilities and record the Go version.
- Measure against your own workload, then decide whether to widen the use.
As data services start to feed AI agents, the harder problem moves from throughput to decisions: which policy applied, on what data, with what trace. ElixirData Context OS describes itself as keeping governed context, versioned policy and decision traces in one decision layer above AI agents, and ElixirClaw as an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. Both sit above services like the ones in this guide, and AgentAnalyst, according to its site, lets teams ask questions of enterprise data in plain language and get real-time insights.
To map one data decision your services and agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
Is Go a good language for big data?
Go suits the services around a big data platform, such as ingestion workers, API layers, stream processors and operators, because goroutines and channels make concurrent code short. It is not a replacement for Spark. Apache Spark documents Java, Scala, Python and R as its languages, and the Go client for Spark Connect is described by its own README as highly experimental and not for production.
What is the difference between a goroutine and a thread?
A goroutine is a function running concurrently in the same address space. According to the Go FAQ it has little overhead beyond a stack of a few kilobytes, which the runtime grows and shrinks, and the runtime multiplexes goroutines onto operating system threads. The FAQ says hundreds of thousands of goroutines in one address space are practical.
Does Go run code in parallel?
Yes, when more than one core is available, but Effective Go makes a distinction: concurrency is structuring a program as independently executing components, and parallelism is executing calculations at the same time on multiple CPUs. Go gives you concurrency primitives, and the runtime schedules goroutines across the cores set by GOMAXPROCS.
How do I find data races in a Go data pipeline?
Run tests and staging workloads with the -race flag. The Go race detector reports conflicting goroutine accesses with stack traces, but only for code paths that execute. Its documentation says memory use may grow by 5 to 10 times and run time by 2 to 20 times, so use it in tests and canary runs, not as a permanent production setting.
How should I tune Go memory for large data volumes?
Profile first. The Go garbage collector guide describes GOGC as the trade-off between collector CPU and memory, and GOMEMLIMIT as a soft limit on total runtime memory. It advises against using a memory limit to avoid out-of-memory kills when a program is already close to its environment limit.
When should I choose something other than Go?
Choose Spark, a warehouse or a managed engine when the job is large-scale distributed SQL or DataFrame processing, and choose a language with a mature library for the specific task when the work is model training or heavy numerical analysis. Check the library and its maintenance status before committing.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE