

Key takeaway
- OpenMetadata is an open-source platform for data discovery, lineage and governance. See its design, MCP and AI features, deployment options and fit.
OpenMetadata is an open-source metadata platform that gives data and AI teams one place to find assets, trace lineage, assign ownership and apply governance. According to its documentation it is a "unified platform for data discovery, lineage, and governance", released under the Apache License 2.0, so an enterprise can run it without a licence fee and shape it through its APIs. If you are new to the topic, start with our guide to treating metadata as a product.
The decision for a CIO, CDO or data platform lead is rarely whether metadata matters. It is whether to run an open platform yourself, buy a commercial catalogue, or combine both. This guide covers how OpenMetadata is built, what it does today, where it fits, and when it does not. For a vendor-by-vendor comparison, read our enterprise data catalog tools buyer's guide.
What is OpenMetadata and who is it for?
OpenMetadata describes itself as an open context platform for people, AI assistants and agents. Its site organises the offer around three ideas: metadata (asset structure, lineage and ownership), meaning (glossary terms and definitions) and memory (corrections, decisions and an audit trail). It is built for engineering-led data teams that want an open specification, an API for every capability, and control over where the platform runs.
| Question | Answer from OpenMetadata's own pages |
|---|---|
| What is it? | An open-source platform for data discovery, lineage, governance, quality and collaboration |
| Licence | Apache License 2.0 (GitHub repository) |
| Connectors | 130+ data connectors, according to its site |
| Design | Schema-first and API-first, with only four system components, according to its site |
| Managed option | A hosted service is offered through Collate, which also publishes the project site |
How is OpenMetadata designed?
The platform defines its metadata through open specifications written in JSON Schema and RDF/JSON-LD, so the model is the same for the user interface, the APIs and the connectors. Its site says the architecture has "only four system components", which keeps deployment and upgrades simpler than stacks built from many services. The detail of those components is in the project documentation; check it against your version before you plan capacity.
Where can it run?
| Option | What the documentation says | When it fits |
|---|---|---|
| Docker | Run it on a machine for a hands-on view of a real deployment | Evaluation and proofs of concept |
| Kubernetes | Deploy with Helm charts for a scalable, production-ready setup | Production on cloud or hybrid estates |
| Bare metal | Install on physical or self-managed servers without Kubernetes | Regulated or air-gapped environments |
| Hosted sandbox or Collate service | A live sandbox with demo data and a free SaaS option with your own data | Trying it before committing platform effort |
What can OpenMetadata do for discovery, lineage and governance?
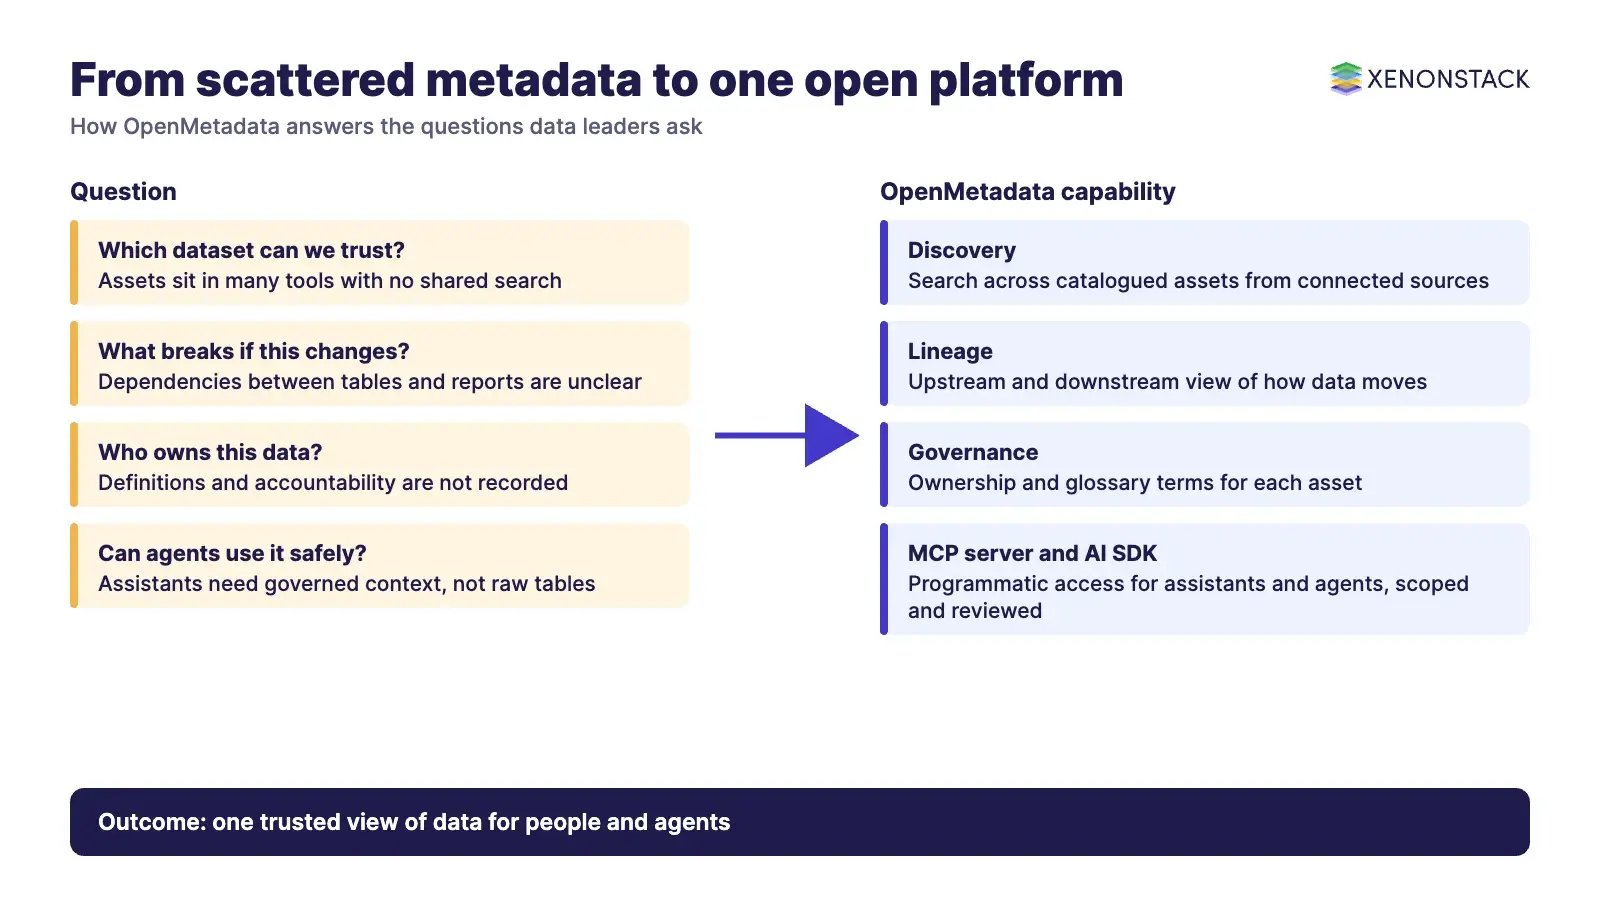
Its documentation groups the work into discovery, lineage, observability, insights, data contracts and governance. The table shows how each maps to a decision a data leader makes.
| Capability | What it gives you | Decision it supports |
|---|---|---|
| Discovery | Search across catalogued assets from many sources | Which dataset should an analyst or an agent trust? |
| Lineage | How data moves between upstream and downstream assets | What breaks if this table changes? |
| Governance | Ownership, glossary terms and definitions | Who is accountable for this data? |
| Data quality | Dimension checks such as completeness, accuracy, consistency and timeliness, plus quality as code through version-controlled configuration | Can this data be used for a regulated report or a model? |
| Data contracts | A guide for agreeing expectations between producers and consumers | What does the producing team promise? |
| Integrations | Connectors such as Snowflake, BigQuery, Redshift and Databricks | How much of the estate can be covered on day one? |
Lineage is only as useful as the events behind it. The OpenLineage project describes an open framework for collecting lineage about datasets, jobs and runs, which is worth checking against your orchestration tools. Our data lineage tools guide covers the options in more depth.
What has changed in OpenMetadata for AI and agents?
The current documentation (version 2.0.x) goes beyond cataloguing. It describes an MCP server so external tools and assistants can reach metadata through the Model Context Protocol, an AI SDK for building agents with programmatic access in Python, TypeScript, Java and the command line, and a Context Center where assistants can search documents, articles, glossary terms and metrics.
| Area | Current position, per its documentation | What to do with it |
|---|---|---|
| MCP server | Integrates OpenMetadata with external tools through MCP | Let approved agents read catalogue context; keep write access separate |
| AI SDK | Build and embed custom agents with programmatic access | Pilot on one domain before wider use |
| Context Center | Assistants search notes from documents, articles, glossary terms and metrics | Curate the glossary first, because assistants will quote it |
| Quality as code | Checks managed through version-controlled configuration | Put quality rules through the same review as application code |
How should you govern and secure it?
A catalogue holds the map of your data, so it needs the same care as the data. Name an owner for every domain, agree a glossary before ingesting widely, and confirm in the documentation for your version how access control and authentication work before exposing it to the wider business. Treat any agent that reads through the MCP server as a user with a defined scope and review what it can reach. Cost is mostly people and platform time, because the software carries no licence fee; plan for upgrades, connector maintenance and a named platform owner.
Which approach fits: OpenMetadata, another open tool or a commercial catalogue?
| Situation | Likely fit | Why |
|---|---|---|
| Engineering-led team, many modern data sources, wants open standards | OpenMetadata | Apache 2.0, API-first, large connector set |
| Need stewardship workflows and vendor support across a large business | Commercial catalogue | Support and workflow depth; see the buyer's guide |
| No platform team to run it | Hosted service or commercial option | Avoids operating the platform yourself |
| Metadata spread across many domains | Open platform plus a metadata operating model | See our enterprise metadata management guide |
How does it fit data mesh and data fabric?
A mesh needs every domain to publish discoverable, owned data products, and a fabric needs a metadata layer that connects sources. An open catalogue can serve either, as long as ownership is clear. Read how to decide on data mesh adoption and data fabric versus data mesh before you decide how much central control the platform should carry. For growth in metadata volumes, see our note on the metadata lake.
What is a sensible adoption sequence?
- Pick one domain and one question. For example, finding the trusted source for a regulated report.
- Connect the sources behind it. Start with the warehouse and the orchestration tool, then add dashboards.
- Assign owners and glossary terms. Without owners the catalogue becomes a list nobody trusts.
- Switch on lineage and quality checks for the assets that feed reports and models.
- Open it to agents carefully. Give read access through MCP to one agent, review its use, then widen.
- Review quarterly. Retire stale assets and check connector coverage.
What are the trade-offs, and when should you not use it?
- Open source moves cost from licences to people. If you lack engineers to run and upgrade it, buy a managed or commercial option.
- A catalogue does not fix poor ownership. If nobody will steward data, start with the operating model.
- Connector coverage varies by source and version. Test your own critical systems in a proof of concept.
- Vendor claims such as market position come from the project's own site; judge them with your own trial.
Open metadata becomes more valuable when agents consume it. ElixirData Context OS keeps governed context and decision traces in one decision layer above AI agents, AgentSearch provides enterprise AI search and retrieval, and AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need.
To map one decision your agents should make, and the metadata, ownership and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is OpenMetadata?
An open-source platform for data discovery, lineage, governance, quality and collaboration, released under the Apache License 2.0.
Is OpenMetadata free to use?
The software carries no licence fee under Apache 2.0. You still carry the cost of running, upgrading and owning it, or you can use the hosted service offered through Collate.
How many connectors does it have?
Its site claims 130+ data connectors. Check that your own sources and versions are covered before committing.
Where can OpenMetadata be deployed?
Its documentation lists Docker for evaluation, Kubernetes with Helm charts for production, and bare metal without Kubernetes.
Can AI agents use OpenMetadata?
Its documentation describes an MCP server, an AI SDK and a Context Center so assistants and agents can reach metadata programmatically. Scope their access and review it.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE


