Key takeaway
- How multimodal AI reads images and text together: tasks, vision-language models, vendor limits, risks, EU AI Act dates and enterprise adoption steps.
Multimodal AI for image understanding means one model reads an image and text together, so it can describe the image, answer questions about it, find similar images from a text query and read the text inside it. For an enterprise, the useful question is not whether a model can do this in a demo, but which image tasks are reliable enough to automate, which need a human check, and what must be logged. This guide covers how the models work, where they fit, where the vendors themselves say they fall short, and what to set up before production.
It builds on our guide to multimodal AI agents and our overview of convolutional neural networks. Read it as a decision guide for CTOs, CDOs, architects and platform leads: tasks first, then architecture, then limits and governance.
What is multimodal AI for image understanding?
A unimodal model handles one type of data. A text model cannot see a photograph and a classic vision model cannot write a description in context. A multimodal vision-language model takes both an image and a text prompt and returns text (and, in some systems, boxes or masks). Google's Gemini API documentation lists captioning, classification, visual question answering, object detection with bounding boxes and segmentation as image tasks, and OpenAI's documentation says its vision-capable models can describe images, read visible text and answer questions about objects, shapes, colours and textures.
| Task | What it does | Typical enterprise use | What to check |
|---|---|---|---|
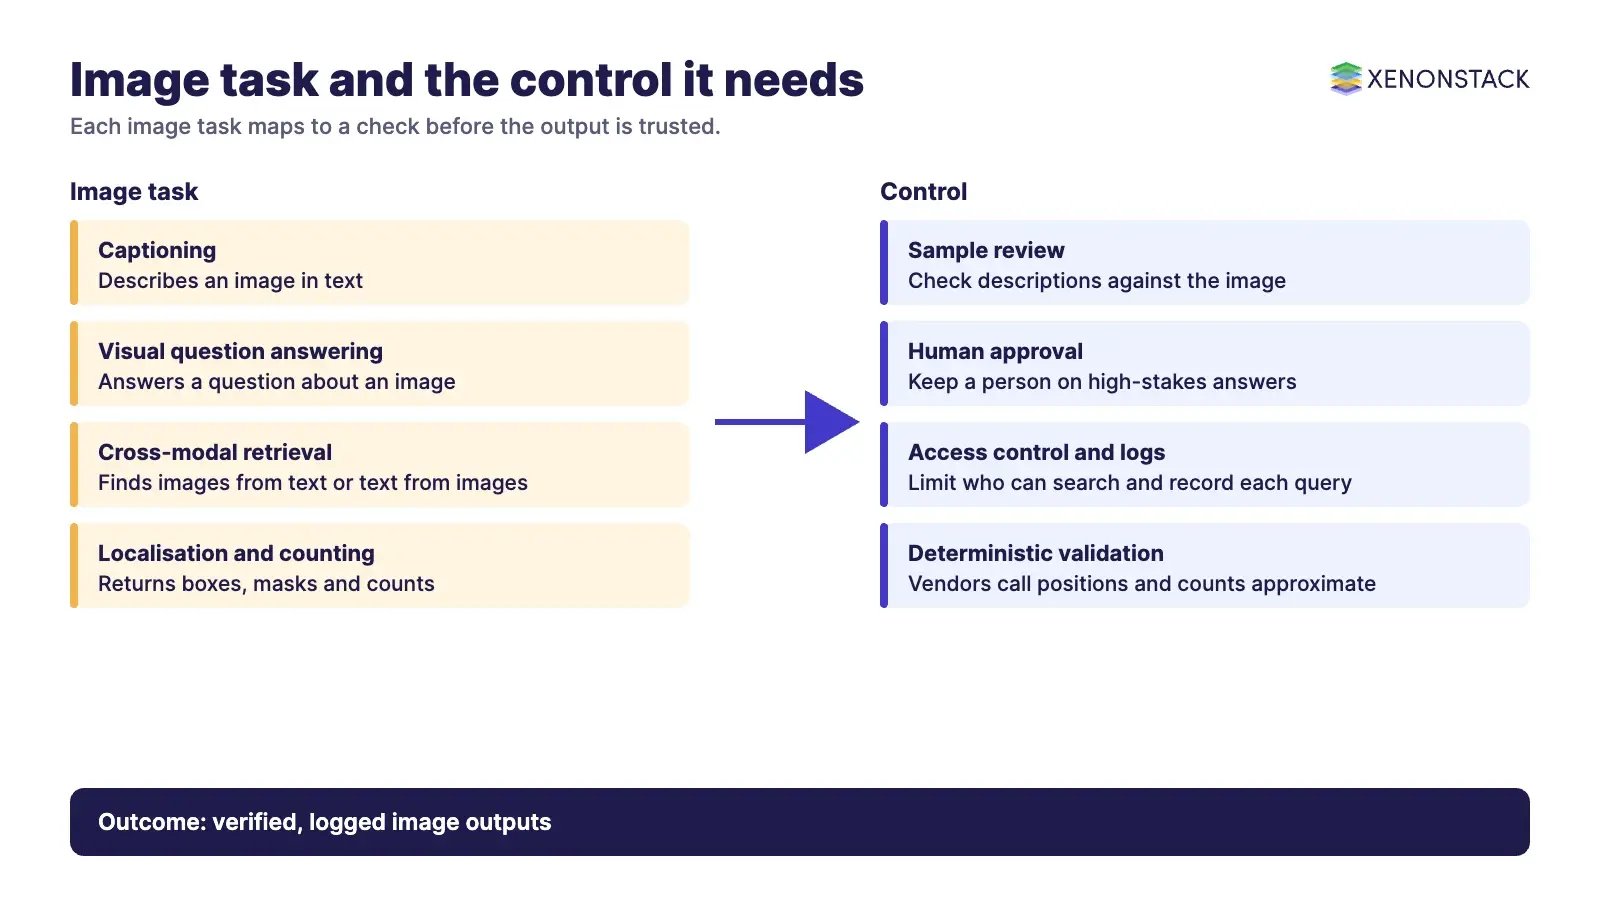
| Image captioning | Writes a description of the image | Alt text, asset metadata for a media library | Wrong or missing detail; review sample outputs |
| Visual question answering (VQA) | Answers a question about an image | Support agents asking about a product photo or a diagram | Hallucinated answers; keep a human check on high-stakes cases |
| Cross-modal retrieval | Finds images from text, or text from an image | Catalogue and knowledge search | Index freshness and access control on the images |
| Localisation | Returns boxes or masks for objects | Inspection, document layout, counting | Vendors call coordinates and counts approximate |
| Reading text in images | Extracts visible text and structure | Forms, labels, screenshots | Small or rotated text; resolution settings |
Why does single-modality AI fall short for enterprise work?
Most enterprise evidence arrives mixed: a photo with a ticket, a scanned form with a table, a product image with a catalogue entry. A text-only model misses what the image shows. A vision-only model cannot use the surrounding text to interpret it. Joining the two lets a system answer questions that depend on both, such as whether a photographed part matches the part number in a work order. Fusing the inputs does not make the answer correct, so the later sections cover where outputs still need checking.
How do vision-language models work?
Most systems combine an image encoder, a text model and a way to connect them. Two research results explain the building blocks. The Vision Transformer paper (arXiv, October 2020) splits an image into patches, treats them as a sequence and feeds them to a standard Transformer with no convolutional layers, and reports results competitive with leading convolutional networks. The CLIP paper (arXiv, February 2021) trains on 400 million image and text pairs from the internet to match each image to its caption, and reports that the resulting model can be applied to new vision tasks by naming the concepts in language, often competitive with supervised baselines on over 30 datasets.
How are image and text signals combined?
Practitioners describe three fusion patterns. These are common engineering terms rather than a single standard, so treat the table as guidance.
| Pattern | How it works | When it fits |
|---|---|---|
| Early fusion | Image and text features are combined before most processing | Tasks where fine detail in both inputs matters together |
| Late fusion | Each modality is processed separately and the results are merged | Teams that want to reuse existing vision and text components |
| Hybrid | Early and late fusion are mixed by task | Complex pipelines with different needs per step |
Hosted models hide this choice behind an API. The decisions left to the enterprise are how images are supplied, at what resolution, and what happens to the output. Gemini, OpenAI and Claude each document how images are passed in (URL, base64 or an uploaded file) and how resolution affects cost: Gemini states 258 tokens for small images and tiles larger ones, Claude states one visual token per 28 by 28 pixel patch, and OpenAI offers a detail setting, including an original-detail option it recommends for fine detail such as OCR and small-object detection.
What are the current trends in multimodal AI?
The cards below summarise themes we track in this area: open tooling, tighter fusion of image and text, synthetic data and real-time sensor use.

Enhance Cross-modal Interaction
Advanced attention mechanisms and transformers enable AI to better align and fuse different data formats, resulting in more coherent and contextually accurate outputs.
Real-Time Multimodal Processing
In autonomous driving and augmented reality, AI integrates data from various sensors (like cameras and LIDAR) in real-time for instantaneous decision-making.
Multimodal Data Augmentation
Researchers are creating synthetic data that combines multiple modalities (such as text and images) to enhance training datasets and boost model performance
Open Source Collaboration
Platforms like Hugging Face and Google AI provide open-source tools, encouraging collaboration among researchers and developers to advance AI technology
Where does multimodal image understanding fit in an enterprise?
Start with tasks where a wrong answer is cheap or easy to catch, and add checks as the stakes rise. Retrieval is a good early step: ranking images for a text query is reviewed by the person searching. Captioning for internal asset libraries is also low risk. Anything that triggers a payment, a safety decision or a customer commitment needs a human approval step. For search over image collections, AgentSearch covers enterprise AI search and retrieval, and for vision on cameras and edge hardware, NexaStack is described on its site as an agentic operating platform for physical AI across on-premises, cloud and hybrid environments.
| Use case | Fits when | Does not fit when |
|---|---|---|
| Product and catalogue search by image | Images are indexed with catalogue data and reviewed by the searcher | Results trigger orders without a check |
| Accessibility descriptions and asset metadata | Descriptions are sampled and corrected | Descriptions are legally required to be exact |
| Support with customer photos | An agent reads the model suggestion and decides | The model replies to customers unreviewed |
| Document and screenshot reading | The layout is stable and extraction is validated against rules | Small, rotated or low-quality scans with no validation |
| Medical or diagnostic images | A regulated, validated medical device is used by clinicians | A general model is used as a diagnostic tool |
What does an enterprise image search flow look like?
This is an illustrative design, not a customer case. A shopper uploads a photo of a product. The system embeds the image, searches a catalogue index and returns the closest items. A vision-language model then writes a short description of the match and answers follow-up questions, such as whether a listed specification applies. The answer is shown next to the catalogue record, so the shopper can verify it, and the request, the image reference, the retrieved items and the answer are logged.
The order matters. Retrieval narrows the candidates, generation explains them and the catalogue stays the source of truth for stock and specifications. A model should not state availability or price from an image alone.
What are the limits and risks of image understanding models?
The vendors are direct about limits. Anthropic's vision documentation says Claude may hallucinate or make mistakes on low-quality, rotated or very small images (under 200 pixels), that spatial and localisation outputs are approximate, that counts can be imprecise with many small objects, that it cannot reliably tell whether an image is AI-generated, that it should not be used to name people in images, and that it is not designed to interpret complex diagnostic scans such as CTs or MRIs. Google's documentation says outputs may be inaccurate, biased or offensive, so post-processing and human evaluation are essential. OpenAI's page says to account for the model's limitations when using its answers.
| Risk | What it looks like | Control |
|---|---|---|
| Hallucinated detail | A confident description of something not in the image | Sample review, grounded retrieval, human check for high stakes |
| Approximate counts and positions | Wrong object counts or box coordinates | Validate against a deterministic check or a specialist vision model |
| Prompt injection through images | Instructions hidden in an image that accompany benign text | Treat image content as untrusted, least privilege, human approval for risky actions |
| Privacy and identity | Faces and personal data in uploaded images | Data minimisation, access control, retention limits |
| Bias and unfair outcomes | Uneven quality across people, languages or conditions | Test on your own data, track errors by segment |
On injection, the OWASP guidance on prompt injection notes that multimodal systems add risk because attackers can hide instructions in images that accompany benign text, and says multimodal-specific defences need further research. Its listed mitigations include least privilege, separating untrusted content, output validation and human approval for high-risk actions. For wider risk management, NIST AI 600-1 is the generative AI profile of the NIST AI Risk Management Framework, published on 26 July 2024 for voluntary use.
How should an enterprise adopt multimodal image understanding?
| Step | What to do | Output |
|---|---|---|
| 1. Pick one task | Choose captioning, search or document reading with a named owner | A scoped use case |
| 2. Build a test set | Collect representative images, including poor-quality ones, with correct answers | An evaluation set you control |
| 3. Choose the model | Compare hosted models on your test set, not on public claims | A documented choice |
| 4. Set resolution and cost | Decide image size and detail settings against token cost | A cost per image estimate |
| 5. Add checks and logging | Human approval for high-stakes actions, logs of inputs and outputs | An audit trail |
| 6. Monitor | Track error rates and reviewer corrections | A review cadence |
Where an agent takes an action based on an image, the decision needs governed context: which policy applied, who approved and what evidence was used. ElixirData Context OS is described on its site as keeping governed context, versioned policy and decision traces in one decision layer above AI agents. For the wider pattern, see our guide to agentic workflows.
When should you not use a multimodal model for images?
Use a specialist model or a rule-based method when the task needs exact counts, measurements or coordinates, when latency must be very low at the edge, or when an error has a safety or legal consequence. A trained detector with known error rates on your own images is often easier to certify than a general model. For quality inspection on a line, see vision AI for quality inspection. For a medical setting, use only tools that are cleared or approved for that purpose and keep clinicians in charge; this article is not medical advice.
What will change in multimodal image understanding over the next 3 to 5 years?
The points below combine what vendors and regulators have published today with our own expectation of direction. They are not market forecasts, and we cite no market figures.
| Area | What is published today | What we expect |
|---|---|---|
| Resolution and cost controls | Gemini documents a media resolution setting, OpenAI a detail setting with an original-detail option, and Claude a higher-resolution tier for Claude 4.7 and later (2,576 px long edge) | More explicit control over how much of an image the model sees, so teams budget cost and accuracy per task |
| Localisation | Gemini documents bounding boxes and segmentation masks; Anthropic says coordinates are approximate | Better grounding, but a validation step stays necessary where positions matter |
| Regulation | The European Commission lists the AI Act as in force from 1 August 2024, with general application on 2 August 2026, Annex III high-risk obligations (including biometrics) on 2 December 2027 and Annex I product obligations on 2 August 2028 (confirm on the official page) | Image systems that identify people or sit in regulated products will need documentation, logging and human oversight |
| Security | OWASP says multimodal-specific defences need further research | Treating images as untrusted input becomes standard architecture |
| Risk management | NIST AI 600-1 is the generative AI profile of the AI RMF | Evaluation on your own data becomes part of procurement |
Outlook FAQ
Will multimodal models replace specialist vision models? Not for every task. General models are flexible, but specialist detectors with measured error rates on your own images remain a sound choice where accuracy, speed or certification matter. Expect hybrid designs that use both.
What should a leader plan for by 2030? Plan for evaluation sets, logging and human approval steps now, because the regulatory dates above and the vendor limits will both apply to image systems in production.
To map one image-based decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is multimodal AI for image understanding?
It is AI that takes an image and text together and returns text, such as a caption, an answer to a question about the image, or the text it contains. Some systems also return boxes or masks for objects.
How do vision-language models work?
They pair an image encoder with a text model. Research such as the Vision Transformer splits images into patches, and CLIP learns to match images with captions from 400 million image and text pairs. Hosted models expose this through an API.
What are the limits of image understanding models?
Vendor documentation says outputs can be wrong or biased. Anthropic lists approximate counts and coordinates, mistakes on low-quality or very small images, and no reliable detection of AI-generated images. Verify high-stakes outputs.
Can I use a general multimodal model for medical images?
Anthropic says Claude is not designed to interpret complex diagnostic scans such as CTs or MRIs. Medical use needs tools cleared or approved for that purpose and clinician oversight. This is not medical advice.
How do I keep image inputs safe?
Treat image content as untrusted. OWASP notes instructions can be hidden in images, and lists least privilege, separating untrusted content, output validation and human approval for high-risk actions as mitigations.
What will change in the next 3 to 5 years?
Resolution controls, localisation and regulation are the main moving parts. The EU AI Act reaches general application on 2 August 2026, with Annex III high-risk duties from 2 December 2027 (confirm on the official page).
Ready to put AI agents to work? See an ElixirClaw demo: the agentic OS to build, orchestrate and govern AI agents across your enterprise systems.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE