Key takeaway
- Six DevOps adoption challenges and how to fix them: legacy migration, tool integration, process change, training and culture, measured with DORA metrics.
The six most common DevOps challenges are moving from legacy infrastructure to microservices, integrating tools from different domains, changing processes that already work, separate toolsets for development and operations, adopting new tools without training, and resistance to change. Most of them are about people, process and ownership, not about picking another tool.
This guide explains each challenge, what to do about it, and how to tell whether the fix is working. For the measures behind that last point, see our guide to DevOps metrics, and for the wider operating model see Enterprise DevOps: operating model and adoption plan.
What makes DevOps adoption hard?
DevOps joins development and operations around one delivery flow across the software development life cycle (see our guide to AI in the SDLC). That sounds simple, yet each team arrives with its own tools, incentives and habits. The table summarises the six challenges and the first move for each.
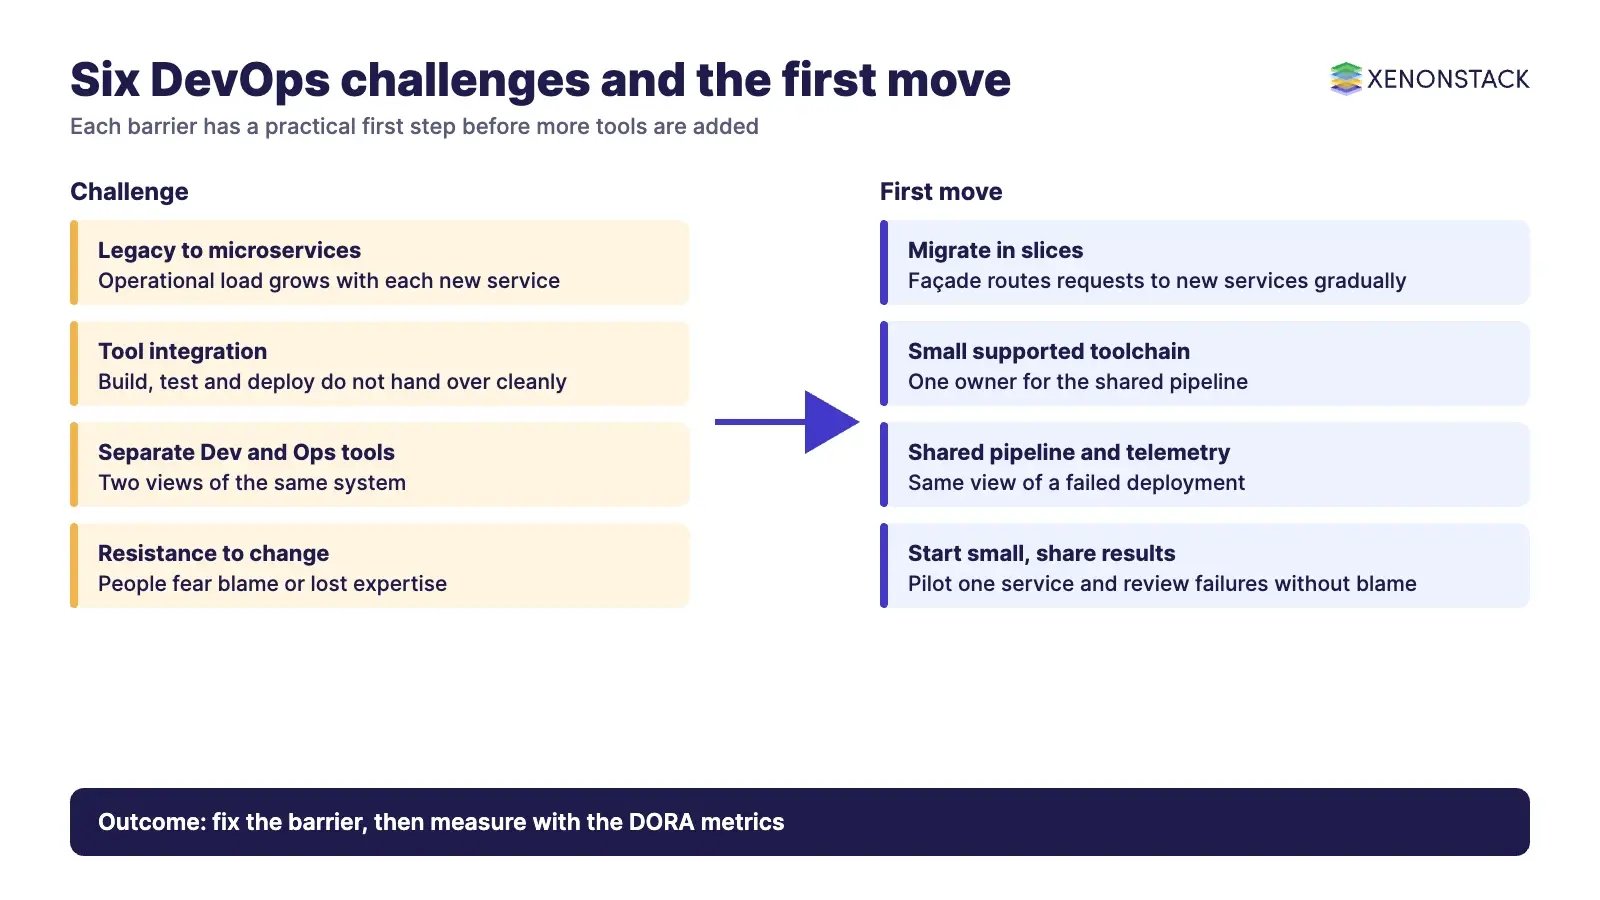
| Challenge | Why it hurts | First move |
|---|---|---|
| 1. Legacy infrastructure to microservices | Operational load grows with every new service | Migrate in slices and automate configuration and delivery first |
| 2. Integrating tools from different domains | Build, test and deploy do not hand over cleanly | Agree a small, supported toolchain with clear interfaces |
| 3. Changing well-defined processes | Old steps add delay but feel safe | Map the flow, find waiting time, change one step at a time |
| 4. Separate toolsets for Dev and Ops | Two views of the same system | Share the pipeline, telemetry and runbooks |
| 5. Adopting new tools | Tools arrive faster than skills and security review | Train first, pilot, then scale |
| 6. Resistance to change | People fear blame or lost expertise | Start small, share results, build trust |
1. How do you move from traditional infrastructure to microservices?
Legacy systems keep running for good reasons, but they get harder to support and change. Microservices can speed up change, yet they raise the operational workload, so configuration management, automation and continuous delivery should be in place before you split a system up.
A proven way to reduce risk is incremental migration. The Strangler Fig pattern in the Microsoft Azure Architecture Center puts a façade in front of the legacy system and gradually routes requests to new services until the old system can be retired. According to that page, it is a poor fit when requests cannot be intercepted, when you cannot change the legacy system at all, or when the system is small enough to replace outright. It also warns that the façade must not become a single point of failure or a bottleneck.
2. How do you integrate tools from different domains?
Continuous integration only works when build, test, security scanning and deployment tools pass work to each other without manual steps. The challenge is rarely any single tool. It is the seams between them.
Keep the toolchain small and supported, define what each stage hands to the next, and give one team ownership of the shared pipeline. Our guide to continuous integration and delivery covers the stages in more detail.
3. How do you change processes that already work?
Start by looking at where work waits, not where people are busy. Review handoffs, approvals and rework, then change one step at a time and measure the result. Process change is not only for software developers: operations, security and business stakeholders all own part of the flow.
4. What if Dev and Ops use separate toolsets?
Different toolkits give each team a different picture of the same system, which slows incident response and blames the gap on the other side. Aim for shared pipelines, shared telemetry and shared runbooks, so that a failed deployment looks the same to both teams.
Many organisations now do this through an internal platform. DORA states that a platform is an internal product and developers are its customers, and recommends starting with a minimum viable platform around the most common workflow. Our guide to platform as a product explains the model, and SRE versus DevOps explains where reliability roles fit.
5. Why does adopting new tools often fail?
New tools look as if they solve every problem, but they only help when people are trained, the tool meets security requirements and it fits the current infrastructure. Otherwise the organisation spends its effort on the tool and loses sight of the outcome.
Pilot with one team, write down the working practice, then widen use. Judge the result by delivery outcomes, not by the number of tools installed.
6. How do you overcome resistance to change?
People resist when change feels like criticism or a threat to their expertise. Culture is a stated factor in DORA research: it describes a high-trust, generative culture, based on Ron Westrum's typology, as a predictor of software delivery and organisational performance, and says failure in such a culture leads to inquiry rather than blame. DORA presents this as a predictive link, not proof of cause.
In practice, pick a small product or one part of an existing application, apply DevOps practices there, and share what the team learned. Other teams adopt faster when they see a real example.
How do you know the fixes are working?
Use the five software delivery measures on dora.dev. DORA groups three as throughput (change lead time, deployment frequency, failed deployment recovery time) and two as instability (change fail rate, deployment rework rate). Track them per service, review them as a team, and treat them as signals for improvement, not individual targets.
| Challenge | Signal to watch |
|---|---|
| Legacy to microservices | Change lead time and change fail rate per migrated service |
| Tool integration | Deployment frequency and manual handoffs in the pipeline |
| Process change | Change lead time and where work waits |
| Separate toolsets | Failed deployment recovery time |
| New tool adoption | Change fail rate and deployment rework rate after rollout |
| Resistance to change | Team participation and how failures are reviewed |
How does AI change DevOps adoption challenges?
According to the 2025 DORA report, AI's primary role is as an amplifier, magnifying an organisation's existing strengths and weaknesses. That applies here: AI coding and operations assistants help a team with clear ownership, solid pipelines and good habits, and they can add noise where those are missing. Fix the six challenges first, then add AI where the flow is already healthy. Our DevOps trends for 2026 covers the wider picture.
What is the recommended adoption sequence?
- Pick one service or product and agree what better delivery means for it.
- Map the current flow and list the waiting time and manual handoffs.
- Fix the pipeline and shared tooling for that service before adding more tools.
- Train the team and write down the working practice.
- Measure with the DORA metrics, review as a team, then repeat on the next service.
A checklist of practices for each stage is in our DevOps checklist for enterprises.
When is DevOps adoption not the right first step?
If a system is small, stable and rarely changes, a full migration or a new toolchain may cost more than it returns. If teams do not yet agree on who owns production, settle ownership first. Tooling cannot replace that decision.
When automation and AI agents start to take actions in delivery pipelines, the policy, context and approvals behind those actions need to be explicit. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. XenonStack builds both, so treat this as a vendor view.
To map one delivery decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What are the biggest challenges in DevOps adoption?
The six most common are moving from legacy infrastructure to microservices, integrating tools from different domains, changing existing processes, separate toolsets for development and operations, adopting new tools without training, and resistance to change.
How should we migrate from a legacy system to microservices?
Do it in slices. The Strangler Fig pattern in the Microsoft Azure Architecture Center routes requests through a façade and moves functionality to new services gradually until the legacy system can be retired. It is a poor fit when requests cannot be intercepted or the system is small.
How do we measure whether DevOps adoption is working?
DORA groups five software delivery measures: change lead time, deployment frequency and failed deployment recovery time for throughput, and change fail rate and deployment rework rate for instability.
Does culture really matter for DevOps?
DORA states that a high-trust, generative culture predicts software delivery and organisational performance. It presents this as a predictive relationship, not proven cause.
Will AI fix DevOps adoption problems?
According to the 2025 DORA report, AI acts mainly as an amplifier of an organisation's existing strengths and weaknesses, so the underlying challenges still need to be addressed.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE