Key takeaway
- DevOps process explained for enterprise leaders: the lifecycle, the 6 C's, ownership, DORA delivery metrics, GitOps, AI and a sequence to adopt it.
DevOps is an operating model for software delivery: development and operations work as one accountable team, and the path from commit to production is automated, observable and measured end to end. The DevOps process is the repeatable loop that model runs on, from planning a change to learning from it in production.
This guide takes the process and operating-model view: the lifecycle, the six continuous practices, who owns what, how delivery is measured and how to sequence adoption. For the toolchain, read our guide to DevOps tools. For security inside the pipeline, see DevSecOps, and for pipeline stages and CI/CD tooling see CI/CD pipelines.
What does DevOps change for the business?
The model removes a specific failure: development and operations working as separate functions, with work handed across a boundary and feedback arriving long after the decisions that caused it. Two things move when delivery works well. Throughput is how often you ship and how long a change waits before it reaches customers. Instability is how often changes cause a problem and how long recovery takes. The older assumption was that the two trade off; the DORA delivery-performance research has argued that under the right practices both can improve together.
Where the process pays back:
- Faster flow of planned work into production, and shorter time to value.
- More stable environments and faster recovery when something breaks.
- Automated controls at each stage, so compliance evidence becomes a by-product rather than a project.
- Better communication between teams that previously handed work over a wall.
- More engineering time on product rather than repeated manual operations.
What does the DevOps lifecycle look like?
The DevOps lifecycle is a continuous loop of eight stages. Development runs plan, code, build and test; operations runs release, deploy, operate and monitor; and what the team learns while monitoring production feeds the next plan. The six continuous practices below are how each part of the loop is run day to day.
What are the 6 C's of DevOps processes?
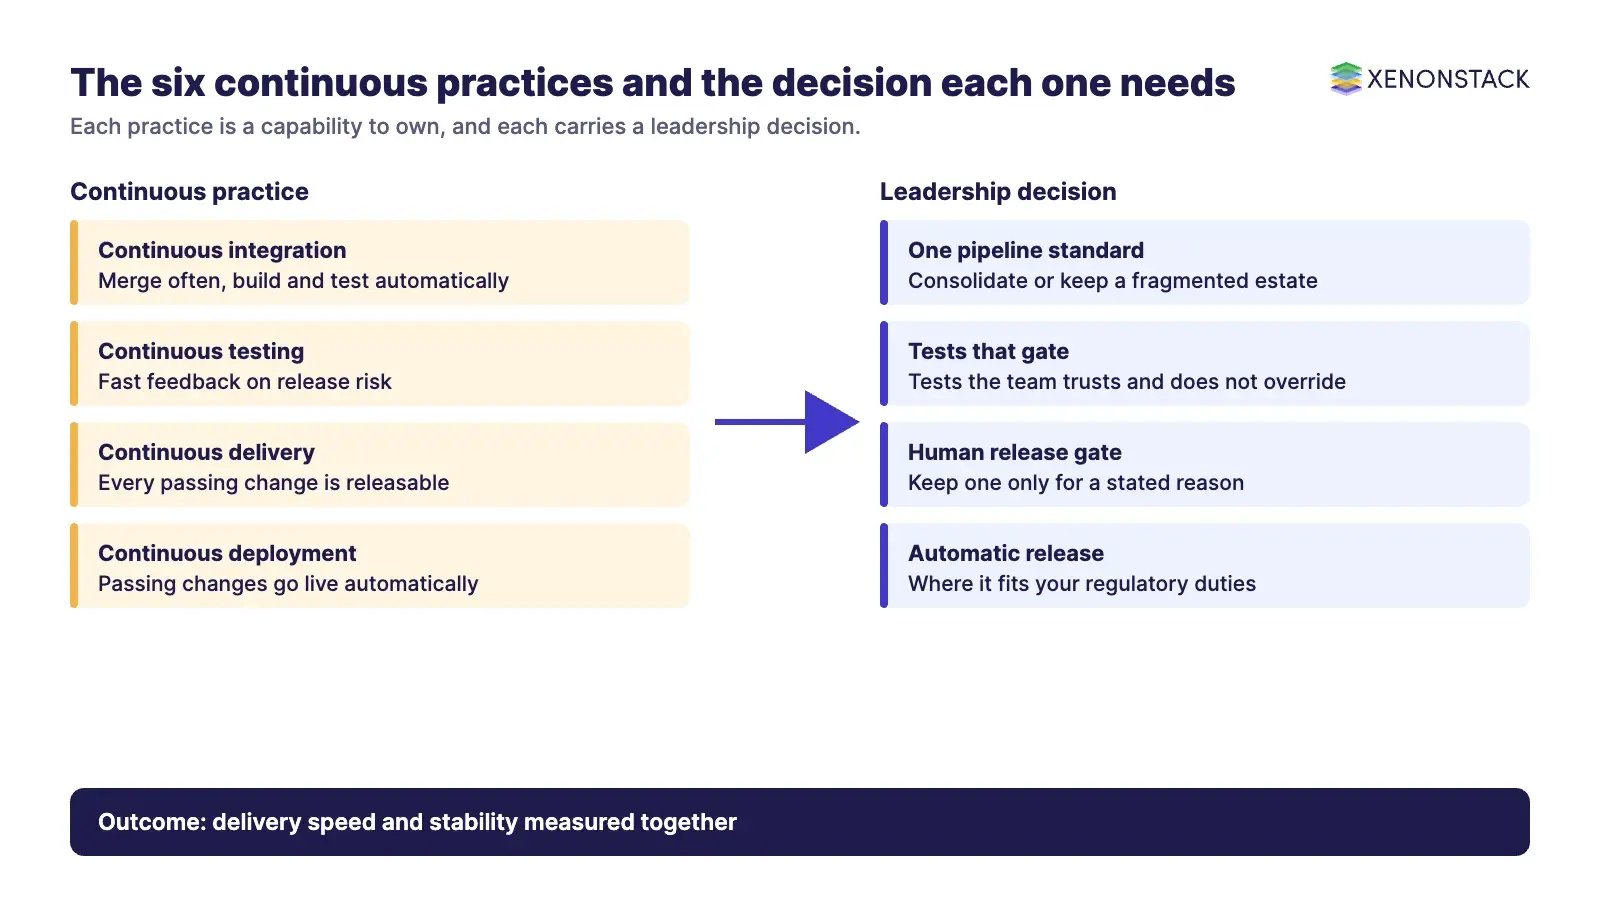
Each of the six is a capability to build and own, not a tool to buy.
| Practice | What it does | Decision for leadership |
| Continuous integration | Merges changes to a shared mainline often, builds and tests automatically | One pipeline standard or a fragmented estate, and the migration cost between them |
| Continuous testing | Gives fast feedback on the business risk of a release | Whether tests gate the pipeline and the team trusts them |
| Continuous delivery | Keeps every passing change releasable; release is a business decision | Which changes need a human release gate, and why |
| Continuous deployment | Sends a change that passes every gate to production automatically | Where automatic release is acceptable under your regulatory duties |
| Continuous monitoring | Returns production evidence to the team | Instrument against an open standard or accept lock-in |
| Continuous business planning | Funds and prioritises in small increments, using live evidence | Changing how money is allocated, not only how software is built |
Continuous integration
Every change is merged frequently, then built and tested automatically, so defects surface within minutes rather than at the end of a release cycle. What you are buying is a short feedback loop and a mainline that is always in a known state. The decision is rarely which CI tool is best in the abstract. It is whether to consolidate a fragmented estate onto one pipeline standard, against the benefit of a single security and audit surface. Tooling choices are covered in our CI/CD guide.
Continuous testing
Continuous testing gives immediate feedback on release risk. The useful question is not how much test automation you have, but whether your tests gate the pipeline and the team trusts them. A suite routinely overridden because it is flaky provides assurance on paper only. Treat end-to-end UI testing as the most expensive and most brittle layer, with unit and contract tests beneath it.
Continuous delivery and continuous deployment
Continuous delivery means every change that passes the pipeline is releasable, and releasing is a business decision rather than an engineering event. Continuous deployment goes one step further: a change that passes every gate goes live with no human approval. The difference is a governance decision, not a maturity ladder. A regulated business may keep a release gate for segregation of duties while automating everything up to it. What matters is that the gate exists for a stated reason, not because nobody trusts the pipeline. Where deployment is automatic, canary releases, blue-green deployments and feature flags separate deploying code from exposing a feature to customers.
Continuous monitoring
Production is the environment that tells the truth. Monitoring asks whether a known thing is behaving; observability asks why an unknown thing is happening. Host and service checks remain a useful layer, but they are not a strategy for distributed, ephemeral systems. The consolidation point is OpenTelemetry, a vendor-neutral standard for traces, metrics and logs, which the CNCF lists as a graduated project since 11 May 2026. Instrument once against an open standard and you own your telemetry, which keeps the choice of analysis backend open.
Continuous business planning
The loop only closes if what operations learns in production changes what the business plans next. In practice this is the hardest of the six, because it is the only one that changes how money is allocated rather than how software is built.
Who owns what in a DevOps operating model?
Process fails when ownership is vague. A workable split is below; adapt it to your size and regulatory position.
| Role | Owns | Typical measure |
| Product and engineering teams | The service end to end, including its pipeline and its on-call | Change lead time, change fail rate |
| Platform team | Shared pipelines, environments and golden paths, run as a product | Developer adoption and time to first deployment |
| Security and risk | Policy, expressed as automated checks in the pipeline | Policy checks that cannot be bypassed |
| Leadership | Funding in increments, and the decision on release gates | Evidence that delivery performance is improving |
Risk teams increasingly ask for evidence that autonomous and AI-assisted changes stay inside policy. AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need, and ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
How is delivery performance measured?
The current DORA guidance defines five software delivery metrics, grouped as throughput and instability (source: dora.dev).
| Measure | Group | What it tells leadership |
| Change lead time | Throughput | How long from committing a change to it running in production |
| Deployment frequency | Throughput | How often you deliver change |
| Failed deployment recovery time | Throughput | How long it takes to recover from a failed deployment that needs immediate intervention |
| Change fail rate | Instability | The share of deployments that need immediate fixing, such as a rollback or hotfix |
| Deployment rework rate | Instability | The share of deployments that are unplanned and triggered by a production incident |
Rework rate is the newest and the most revealing. A team can raise deployment frequency simply by shipping fixes for its own breakages; rework rate shows whether extra speed is real throughput or churn. Two cautions. Any benchmark table you are shown should be dated to the report year it came from. And these are system measures, not individual ones: used to rank engineers, they will be gamed.
What are microservices, and when are they worth it?
Microservices split an application into small, independently deployable services owned by small teams. You exchange the simplicity of one deployable unit for independent scaling and release cadence. The gains are independent releases, scaling per service and contained failures. The costs are permanent operational complexity, harder testing across service boundaries and distributed-systems problems such as partial failure and network latency. Microservices solve an organisational scaling problem before a technical one: if a few teams can ship a well-structured single application without blocking each other, the complexity is rarely justified.
Containers, orchestration and scheduling: what do they commit you to?
A container packages an application with its dependencies and runs it isolated on a shared host kernel, so the same artefact runs on a developer machine, in test and in production. Docker is not a synonym for containers. Container formats are open standards maintained by the Open Container Initiative, and Kubernetes removed its built-in Docker shim in version 1.24 (source: Kubernetes). Images built with Docker still run on OCI-compatible runtimes such as containerd and CRI-O. Express your container strategy in open standards, not one vendor's product.
Orchestration is the automated coordination of containers and their resources across a cluster. Scheduling is a feature of orchestration, not a synonym for it: the scheduler decides which node a container runs on, while orchestration ensures the environment those workloads need exists, including load balancing, health monitoring and automatic recovery.
Which orchestration platform should an enterprise choose?
| Platform | When it fits |
| Kubernetes | The portable default across clouds and on-premises, when scale or multi-cloud portability justifies the platform skills. See our guide to cloud native DevOps with Kubernetes. |
| Managed Kubernetes (GKE, AKS) | You want the Kubernetes API without operating the control plane, usually matched to your main cloud. |
| Amazon ECS | AWS-native orchestration for teams committed to AWS. |
| Docker Swarm mode | Clustering built into Docker Engine, for smaller estates where Kubernetes is more machinery than the problem needs. |
| HashiCorp Nomad | A scheduler for containerised and non-containerised workloads together, for mixed legacy and modern estates. |
Check any platform still in your estate against its vendor's current support status before extending it.
Where does serverless fit, and where does it not?
Serverless computing lets teams deploy code without provisioning the servers under it; responsibility for them moves to the platform, which scales to demand and bills by use. It is strong for event-driven, spiky and intermittent workloads. It is weaker for sustained high-throughput work, where per-invocation pricing can exceed reserved compute, and for latency-sensitive paths affected by cold starts. Portability is usually lost in proprietary event bindings and identity integration rather than in function code. Treat serverless as a workload-level choice, decided case by case.
What has changed since these practices were first written down?
GitOps and declarative operations
The OpenGitOps principles define four properties: desired state is expressed declaratively; it is stored versioned and immutably with a complete history; software agents pull it automatically; and agents continuously reconcile actual state against it. For a regulated enterprise the governance consequence follows from those properties: every change to production has an author, a timestamp and a review, and drift is detected rather than discovered during an audit.
Infrastructure and policy as code
If environments are defined in code, they can be reviewed, tested, versioned and rebuilt identically. The same logic extends to governance: security and compliance rules expressed as policy that runs in the pipeline move enforcement from a review meeting to an automated gate, the difference between a control that is asserted and one that cannot be bypassed.
Platform engineering, with its costs stated
Platform engineering treats internal infrastructure as a product with developers as its customers, delivered as an internal developer platform with self-service provisioning and golden paths. Be honest about the cost: a platform team has a build-up period before it pays back, and adoption figures vary with how a platform team is defined, so check the definition behind any number before using it in a business case.
Software supply chain security, now with deadlines
Software bills of materials and build provenance are becoming a condition of selling software into the European Union. The EU Cyber Resilience Act entered into force on 10 December 2024; reporting obligations began on 11 September 2026 and the main obligations apply from 11 December 2027. Build provenance, dependency inventory and vulnerability handling therefore become pipeline capabilities. Our DevSecOps guide covers how to build them in.
Where does AI actually fit in software delivery?
DORA's 2025 research describes AI as an amplifier, magnifying an organisation's existing strengths and weaknesses, and says the greatest returns come from the underlying organisational system rather than the tools (source: dora.dev). Generating code faster does not help if the constraint is review, testing or deployment capacity: it produces a larger queue, not more value.
There is also a security dimension. Veracode's 2025 GenAI Code Security Report states that AI-generated code introduced risky security flaws in 45% of tests (source: Veracode), which makes automated scanning in the pipeline a requirement. Where AI takes part in building or running systems, boards will ask about provenance, review and auditability, which is the control problem the practices above already address. See our view on the role of ML and AI in DevOps transformation.
How do enterprises sequence adoption, and when is it not worth it?
- Measure first. Baseline lead time, deployment frequency, change fail rate, recovery time and rework rate before changing anything.
- Automate the path to production for one real service, end to end, including rollback.
- Make environments reproducible through infrastructure as code.
- Instrument against an open standard before adding architectural complexity.
- Only then consider a platform team, once enough teams repeat the same work for standardisation to pay for itself.
The common failure is starting at step five: building a platform before anyone has agreed what good delivery looks like. Full DevOps investment is also hard to justify for a single small team shipping one application with low change volume; start with steps one and two there.
To map one delivery decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Related on XenonStack
- SRE AI agents: incident response and reliability with agents.
- CloudOps AI agents: cloud operations run by governed agents.
- QAOps AI agents: testing and quality with agents.
Frequently asked questions
What are the 6 C's of DevOps?
Continuous integration, continuous testing, continuous delivery, continuous deployment, continuous monitoring and continuous business planning. Together they describe the loop from planning a change to learning from it in production.
What are the stages of the DevOps lifecycle?
Plan, code, build and test on the development side, then release, deploy, operate and monitor on the operations side. Monitoring feeds back into planning, so the lifecycle is a loop rather than a line.
What is the difference between container orchestration and container scheduling?
Scheduling is one feature within orchestration. The scheduler decides which node a container runs on; orchestration is the wider system that provides the environment, load balancing and health management those workloads need.
How do we measure whether a DevOps investment is working?
Use the five DORA measures: change lead time, deployment frequency and failed deployment recovery time for throughput; change fail rate and deployment rework rate for instability. Measure the system, not individuals.
What do the EU Cyber Resilience Act deadlines mean for our pipeline?
Reporting obligations began on 11 September 2026 and the main obligations apply from 11 December 2027. Build provenance, dependency inventory and vulnerability handling become pipeline capabilities rather than documentation exercises.
Is continuous deployment always the goal?
No. The difference between delivery and deployment is a governance decision. A regulated business may keep a release gate for segregation of duties while automating everything before it.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE