What is incident management and why does it matter to the business?
Incident management is the structured process an organisation uses to detect, respond to and recover from events that disrupt a service, then learn from them. It runs in five stages: identification, escalation, assessment, resolution and follow-up, supported by incident management software that keeps one record of what happened, who owned it and what was done.
For a CIO or head of engineering the value is simple: shorter disruption, a documented trail and fewer repeat incidents. For 2026 the decision is no longer only which ticketing tool to buy. It is how much of detection, diagnosis and remediation you let AI agents do, and which approvals and evidence you require around them. Our guides to AIOps for IT operations and AIOps vs MLOps cover that wider shift.
Key takeaways
- Incident management is a five-stage process: identification, escalation, assessment, resolution and follow-up.
- Incident management software centralises detection, tracking and response, so teams stop coordinating through spreadsheets, email and chat.
- Three tool categories do most of the work: monitoring tools, service desks and AIOps platforms. AI agents are the newer layer on top.
- Roles, declaration criteria and blameless post-incident reviews matter as much as the tool you choose.
- Any automated remediation needs an approval rule and an audit trail before it goes near production.
What are the stages of the incident management process?
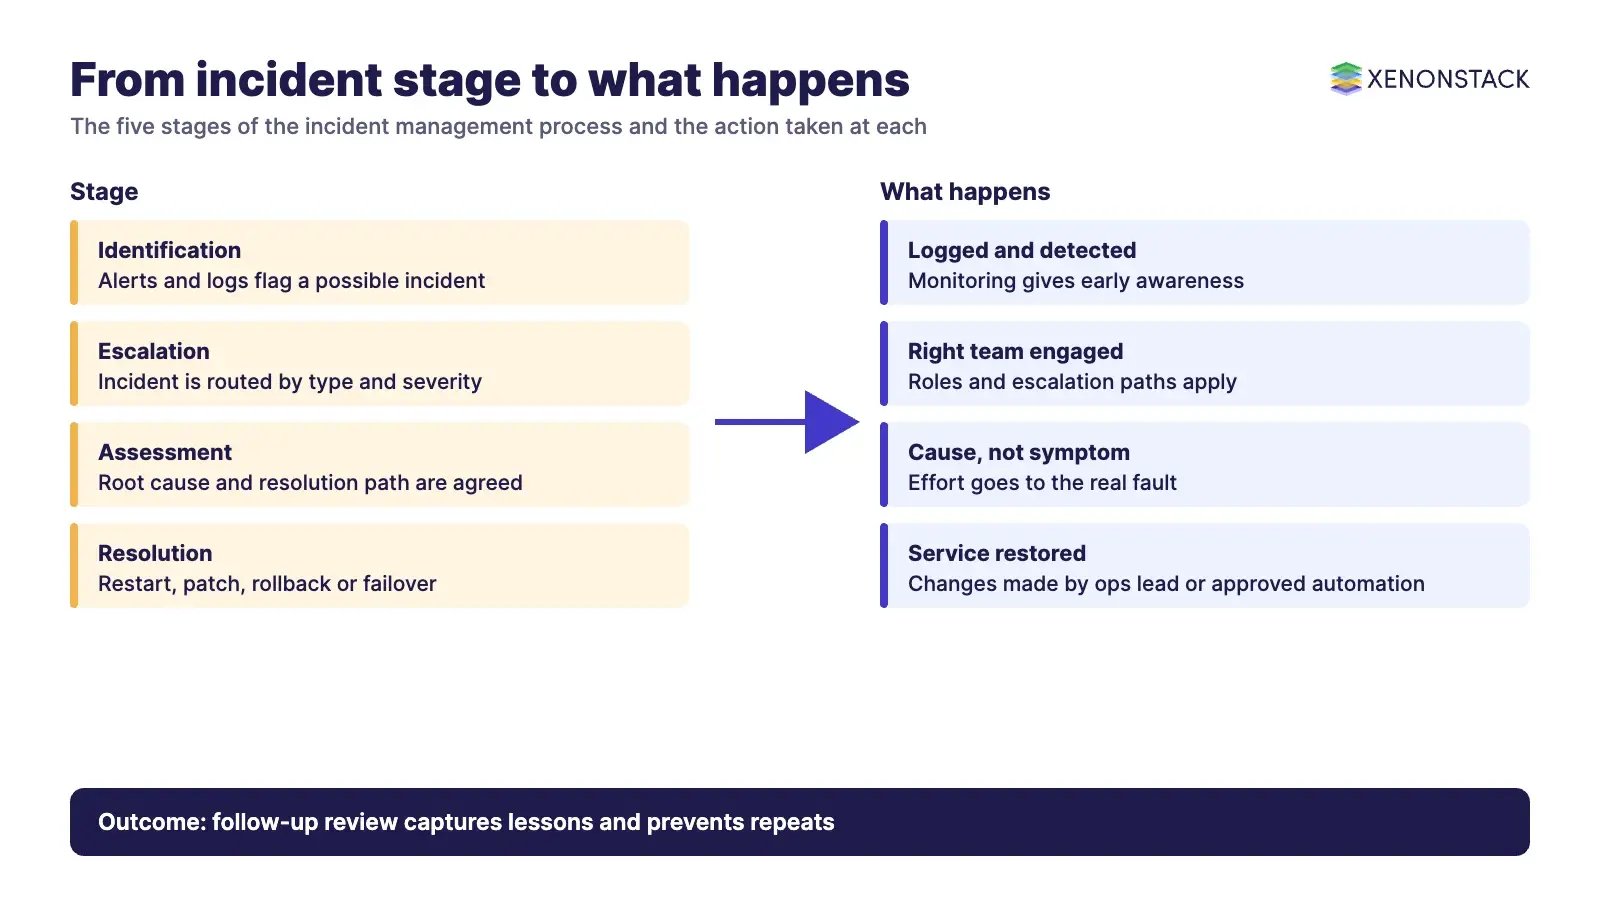
Without a defined process, teams respond from individual memory, informal messages and manual status tracking. That delays escalation to the right people and leaves no record for later analysis. A formal process fixes roles, escalation paths and resolution steps in advance, so the response is consistent whatever the incident type or severity.
| Stage | What happens | Why it matters |
|---|---|---|
| 1. Identification | Monitoring, logs and alerts detect the incident and it is logged | Early awareness before impact spreads |
| 2. Escalation | The incident is routed to the right team by type and severity | The right expertise engages without delay |
| 3. Assessment | The team finds the root cause and agrees the resolution path | Effort goes to causes, not symptoms |
| 4. Resolution | Corrective action: restart, patch, rollback or failover | Normal service is restored quickly |
| 5. Follow-up | Post-incident review, recovery checks and knowledge capture | Prevents recurrence and keeps the lesson |
Who does what during a major incident?
Google's Site Reliability Engineering book describes four roles for larger incidents: an incident commander who tracks overall state and assigns work, an operations lead who is the only person changing the system, a communications lead who sends regular updates to responders and stakeholders, and a planning role that files bugs, arranges handoffs and records changes to be reverted. It also advises declaring early, for example when a second team must help, when customers can see the outage, or when the issue is unsolved after an hour of focused analysis (source: Google SRE book, Managing Incidents).
What does incident management software do?
As environments grow, tracking incidents across spreadsheets, email threads and chat becomes unsustainable. Teams lose sight of status, duplicate effort, miss service windows and cannot see recurring failure patterns. Incident management software gives one operational view of active incidents, with status, severity, priority and owner.
- Collects incident data from several sources into one record
- Organises incidents by severity, priority and status
- Tracks timelines, actions taken and responsible parties
- Keeps an auditable incident history that supports disaster recovery and continuity planning
- Speeds response by putting the right context in front of responders
Which tool categories belong in an incident management stack?
| Category | What it does | When it fits | Current status |
|---|---|---|---|
| Monitoring tools | Detect outages, diagnose incidents and trigger alerts | Every estate; the source of stage 1 | Established |
| Service desks | Take tickets and chat, prioritise and categorise work, support self-service | Whenever users or teams raise incidents and requests | Established |
| AIOps platforms | Use logs and historical data to correlate events and support decisions | High alert volumes and recurring patterns | Maturing; see our AIOps guide |
| AI agents for operations | Investigate alerts, find root cause and propose or run governed fixes | Mature runbooks and clear approval rules | Newer; start with recommendations, not unattended action |
How are AI agents changing incident management?
The change is in stages 1 to 4. Instead of a person reading alerts and searching runbooks, an agent can correlate alerts, trace a likely cause and prepare a fix for a human to approve. AgentSRE describes this as a fleet of AI agents that automates detection, root cause analysis and remediation (source: AgentSRE, an ElixirClaw site, read 12 November 2026). Our piece on automation in incident triage covers the triage step in detail.
The video below shows the pattern in practice: many alerts collapse into one incident that reaches a single approver.
AI incident response: 212 alerts, one incident, one approver (ElixirData).
Autonomy raises a governance question: who approved the action, under which policy, and where is the evidence? ElixirData's Audit Agent assembles decision traces, policy versions, approvals and authority chains so compliance teams can answer auditor questions without reconstructing decisions by hand, and ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents.
How should organisations choose the right incident management solution?
| Factor | Question to ask | Trade-off |
|---|---|---|
| Budget | What can we afford to run, not only to buy? | Lower cost often means fewer integrations |
| Timeframe | Is this a short engagement or a long-term platform? | A feature-heavy tool is poor value for a three-month need |
| Scope of use | Do we need basic ticketing or full response coordination? | Too simple misses escalation; too complex goes unused |
| Integration | Does it connect to our monitoring, deployment and chat tools? | Poor integration brings back manual copying |
| Governance | Does it record approvals and give an audit trail? | Needed before any automated remediation |
What incident management tactics work in practice?
- Define an incident for your business. Separate incidents from service requests, and prioritise by severity, impact and urgency.
- Set declaration criteria. Agree in advance when an event becomes an incident, so declaring early is normal rather than awkward.
- Assign roles and skills. Everyone should know their role, and high-priority work should come first.
- Automate routine steps. Automatic ticket assignment and routing improve work distribution and free the team for critical tasks.
- Choose communication channels deliberately. Match channels to team size, and share regular updates so end users can follow progress.
- Review without blame. Google's SRE guidance says to focus on contributing causes, not individuals, because you cannot fix people but you can fix systems and processes. It suggests triggers such as data loss, on-call intervention like a rollback, or resolution time above a set threshold (source: Google SRE book, Postmortem Culture).
What governance, security and cost controls should sit around incident response?
For security incidents, NIST published SP 800-61 Rev. 3 in April 2025. It replaces Rev. 2 (2012) and frames incident response recommendations within the NIST Cybersecurity Framework 2.0 as part of cybersecurity risk management (source: NIST SP 800-61 Rev. 3, read 12 November 2026). Practical controls that follow:
- Record who declared, approved and closed each incident, with timestamps.
- Require human approval for production changes proposed by an automated system until its record justifies more autonomy.
- Keep incident history so repeat causes and downtime cost can be measured, not guessed.
- Restrict who and what can change systems during an incident to the operations lead and approved automation.
What is the sensible adoption sequence, and when should you not automate?
- Define severity levels, roles and declaration criteria, and write them down.
- Centralise records in one incident management tool.
- Connect monitoring and route alerts by severity.
- Add AIOps correlation, then AI agents that recommend actions.
- Allow approved, low-risk remediations to run with an audit trail.
Do not automate remediation where runbooks are untested, ownership is unclear or the change is hard to reverse. A tool cannot repair a missing process.
To map one incident decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Incident management FAQ
What are the stages of incident management?
Identification, escalation, assessment, resolution and follow-up.
What does incident management software do?
It collects incident data in one record, organises incidents by severity, priority and status, tracks resolution and keeps an auditable history.
Which tool categories support incident management?
Monitoring tools, service desks and AIOps platforms, with AI agents as a newer layer for investigation and remediation.
When should an incident be declared?
Google's SRE guidance says to declare early, for example when a second team must help, customers can see the outage, or the issue is unsolved after an hour of focused analysis.
What is a blameless post-incident review?
A review that focuses on contributing causes rather than individuals, so people feel safe escalating and the organisation fixes systems and processes.
How do AI agents change incident response?
They can automate detection, root cause analysis and remediation steps, which is why approval rules and audit trails need to be in place first.
Conclusion: why is incident management essential for operational resilience?
Incident management is a business capability, not only an IT function. A defined process, the right software, clear roles and governed automation reduce downtime, protect revenue and build the record that prevents the next incident.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE