Key takeaway
- AgentOps is the practice of observing, tracing and governing AI agents across their lifecycle. See how it differs from MLOps and LLMOps, and how to start.
AgentOps is the practice of observing, tracing and managing AI agents across their whole lifecycle, from design and testing to deployment and ongoing monitoring. It extends the operations disciplines used for models to systems that plan, call tools and act with some autonomy.
This guide is for AI platform owners, engineering leads and risk teams who are running or planning agentic AI in production. It covers how AgentOps relates to MLOps and LLMOps, the artifacts to trace, a lifecycle workflow, the challenges and what to do first.
What is AgentOps?
The research paper AgentOps: Enabling Observability of LLM Agents (Dong, Lu and Zhu, submitted November 2024) describes it as a DevOps-style practice for observing LLM agents. The authors propose a taxonomy that identifies the artifacts and associated data that should be traced throughout the entire lifecycle of agents. They say it is meant as a reference template for monitoring, logging and analytics infrastructure, and their stated goal is AI safety: helping stakeholders understand agents, detect anomalies and prevent failures, given that agent behaviour is autonomous, non-deterministic and continuously evolving.
How does AgentOps differ from MLOps and LLMOps?
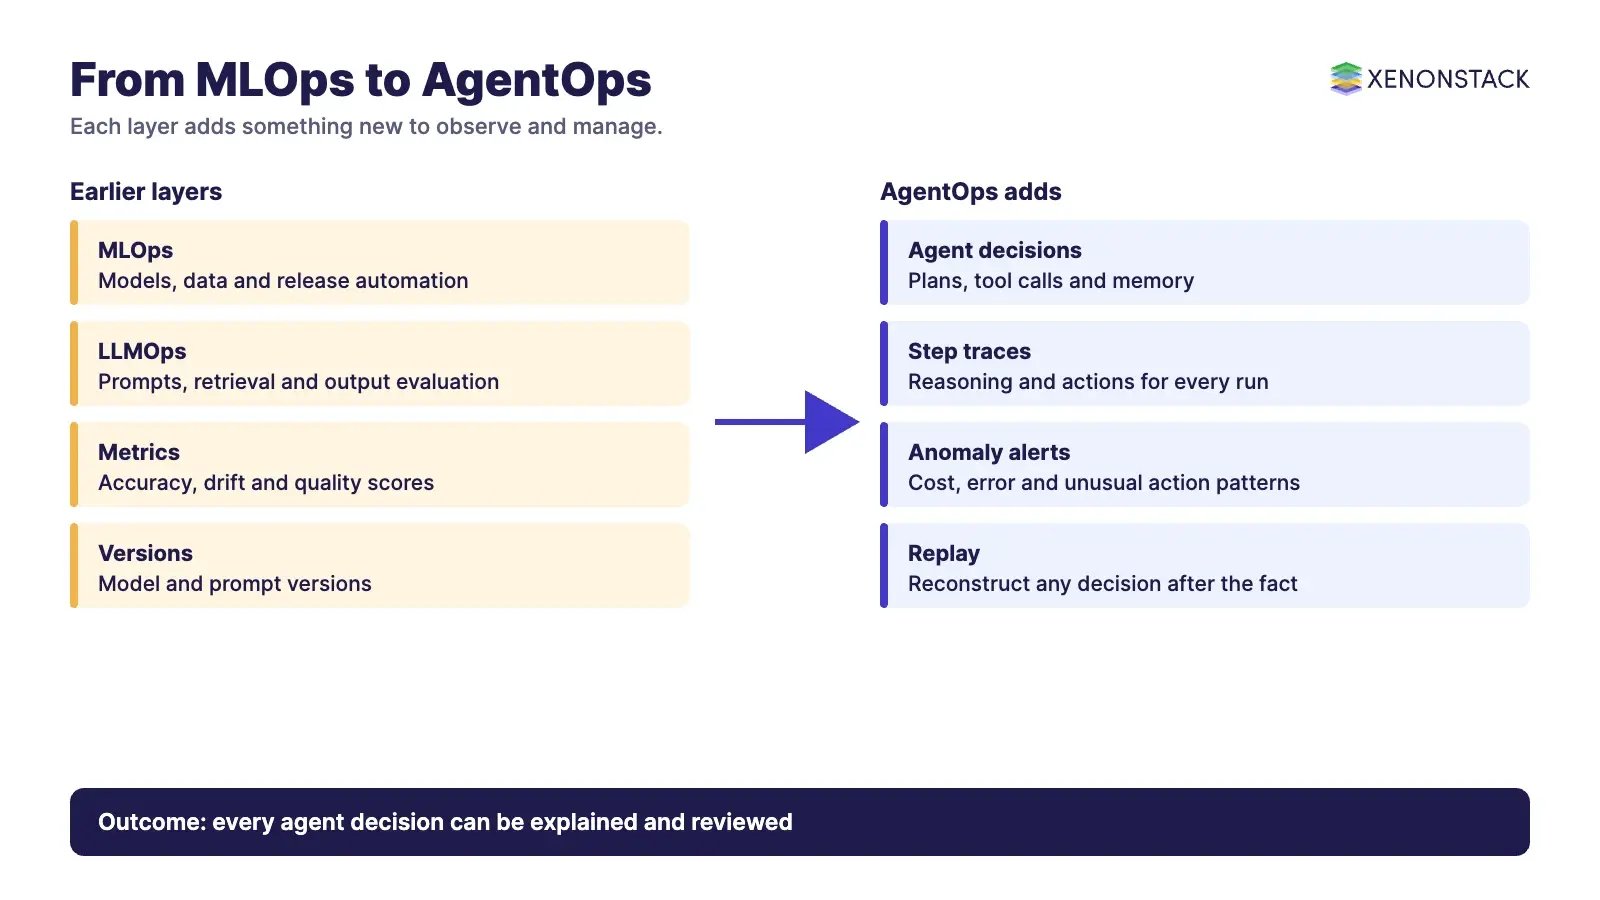
Each layer adds a new thing to manage. MLOps manages the lifecycle of machine learning models and their data, with automation through continuous integration and continuous deployment. LLMOps adapts that to large language models, with prompts, retrieval and evaluation of generated text. AgentOps adds the behaviour of autonomous agents: plans, tool calls, memory and multi-step decisions.
| Aspect | MLOps | LLMOps | AgentOps |
|---|---|---|---|
| Main object managed | Trained models and data | Prompts, models and retrieval | Agents: plans, tools, memory and decisions |
| Typical question | Is the model accurate and current? | Is the output grounded and safe? | Why did the agent take that action? |
| Failure that matters | Drift and degraded accuracy | Wrong or unsafe text | A wrong action in a real system |
| Core evidence | Metrics and model versions | Prompt versions and evaluations | Step by step traces of reasoning and tool use |
The table is a simplification, since real teams run the three practices together.
What are the core principles of AgentOps?
- End to end observability. Record inputs, outputs, reasoning steps, tool calls and results for every run, and show them in dashboards with alerts for anomalies.
- Traceable artifacts. Version prompts, tools, models, retrieval sources and configuration, and keep tamper-resistant logs so any decision can be reconstructed.
- Monitoring and debugging built for multi-step work. A single failing step inside a long chain, or a poor retrieval step in a RAG pipeline, must be easy to find and replay.
For standard telemetry, OpenTelemetry has published GenAI semantic conventions. Its agent spans page now states that these conventions have moved to a separate repository and are no longer maintained on that page, so check the new repository before you adopt a naming scheme.
What does an AgentOps workflow look like?
- Design: define the agent’s goal, tools, permissions and the human approval points.
- Build and test: run scenario tests, including adversarial ones, and compare results across versions.
- Release: promote through environments with the same discipline as any service.
- Operate: trace every run, watch cost, latency and error patterns, and alert on anomalies.
- Review: replay incidents, feed findings back into prompts, tools and policies, and update the tests.
What challenges should you expect?
- Volume and cost of storing detailed traces, so decide what to keep and for how long.
- Reasoning that cannot be fully inspected, so traces show what happened without always proving why.
- Balancing agent autonomy against organisational goals, which is a policy decision, not a tooling one.
- Sensitive data in traces, which needs the same access control as the source data.
Our guides on guiding agentic AI, AI agentic workflows and autonomous agents and agentic AI cover the design questions around these trade-offs.
How do AI agents change operations practice?
With agents, the unit of operations is the decision, not only the model or the service. Traces need to link a decision to the data and policy it used. The AI agents computing platform ElixirClaw is where agent teams build and run agents, and an AgentOps practice gives the people responsible for them the evidence they need.
What should you do first?
- List the agents you run and what each can do.
- Decide the minimum trace for every run: input, steps, tool calls, output and version.
- Store traces with access control and a retention rule.
- Set alerts for cost, error and unusual action patterns.
- Replay one real or simulated incident end to end to test the process.
If you want to discuss your own set-up, contact us or talk to a specialist.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is AgentOps?
AgentOps is the practice of observing, tracing and managing AI agents across their lifecycle. A 2024 research paper describes it as a DevOps-style practice for observing LLM agents.
How is AgentOps different from LLMOps?
LLMOps manages prompts, models and retrieval for language model applications. AgentOps adds the behaviour of agents, including plans, tool calls, memory and multi-step decisions.
What should an AgentOps trace include?
At least the input, each reasoning or planning step, each tool call and result, the output and the versions of the prompt, model and tools in use.
Why does AgentOps matter for safety?
The AgentOps research paper states a goal of AI safety: helping stakeholders understand agents, detect anomalies and prevent failures, given that agents are autonomous, non-deterministic and continuously evolving.
Is there a standard for agent telemetry?
OpenTelemetry has GenAI semantic conventions, which its documentation says have moved to a separate repository. Check that repository for the current agent definitions.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE