Key takeaway
- Automated performance testing in CI/CD: k6, JMeter, Gatling, Locust and Taurus compared, test types, pass/fail thresholds and a rollout plan.
Automated performance testing runs load, stress, soak and spike tests as code inside the delivery pipeline, with pass or fail thresholds on response time and error rate, so a slow build fails just as a broken build does. Instead of a performance team testing once before release, every change gets a measured answer to the question "is this still fast enough?".
In 2026 the common open-source choices are Grafana k6, Apache JMeter, Gatling and Locust, often wrapped by Taurus for YAML-based CI runs, with managed services such as Azure Load Testing and Perforce BlazeMeter for scale. The tool matters less than three decisions: which journeys you test, which thresholds encode your service levels, and where in the pipeline each test runs.
What is automated performance testing?
Performance testing checks how a system behaves under load: response times, throughput, error rates and resource use. Automating it means the test script, the load profile and the pass or fail criteria live in version control and run without a person starting them, usually from a CI server such as Jenkins, GitHub Actions or Azure Pipelines. For background on the metrics and test types, see our guide to performance testing tools and best practices.
The key element is the threshold. Grafana's k6 documentation defines thresholds as "the pass/fail criteria that you define for your test metrics" and notes that if a threshold fails, k6 exits with a non-zero exit code, which a CI job treats as a failed build. Taurus offers the same idea through its passfail module, which sets the test status to failed when a criterion such as average response time is breached.
Why automate performance tests instead of running them before release?
Many design and implementation decisions affect performance, and a regression introduced early is cheaper to find when the change is still small. Running load tests throughout development lets teams trace which change made a service slower, rather than discovering a problem in a final test cycle with dozens of changes to untangle.
Automation also removes the manual steps of collecting measurements, comparing runs and deciding whether a result is acceptable. Those steps are slow and easy to skip under release pressure. With thresholds in code, the decision is consistent from one run to the next, and developers get feedback without waiting for a specialist tester. This is the same principle behind shift-left testing: move checks earlier, where fixes cost less.
Which performance test types should you automate?
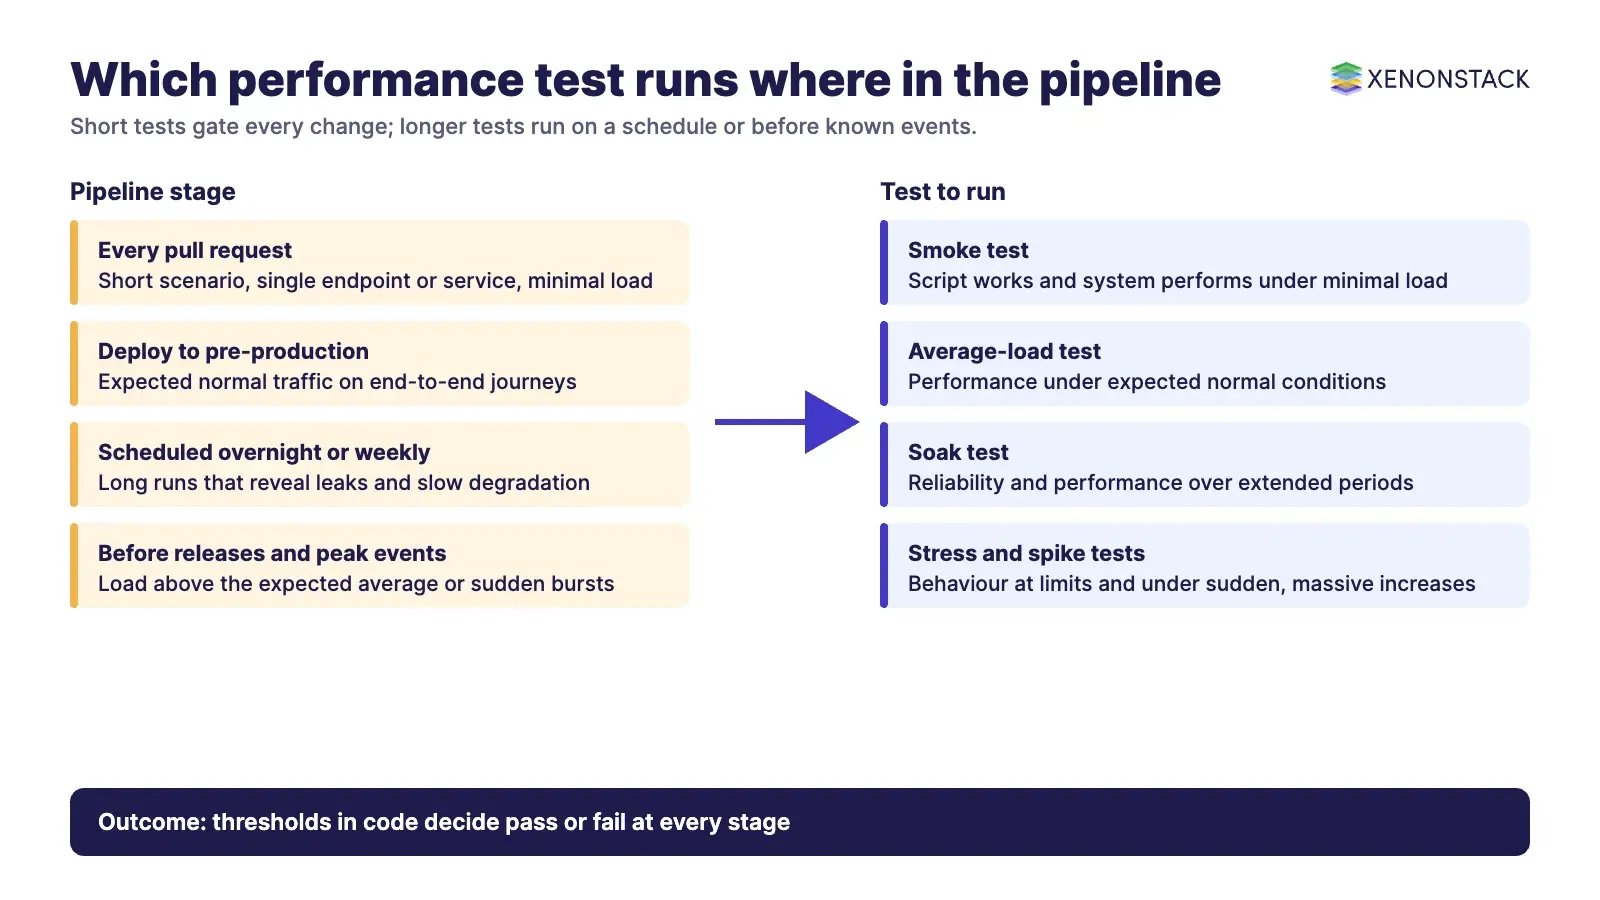
The k6 testing guides describe six load-test types. Each answers a different question, and they do not all belong in every pipeline run.
| Test type | What it checks (k6 definition) | When it fits in the pipeline |
|---|---|---|
| Smoke | The script works and the system performs adequately under minimal load | Every commit or pull request; fast and cheap |
| Average-load | How the system performs under expected normal conditions | Daily or per deployment to a pre-production environment |
| Stress | How the system performs at its limits when load exceeds the expected average | Before major releases or after architecture changes |
| Soak | Reliability and performance over extended periods | Scheduled, for example overnight or weekly; finds leaks and slow degradation |
| Spike | Behaviour and survival under sudden, short and massive increases in activity | Before known events such as campaigns, launches or seasonal peaks |
| Breakpoint | Gradually increases load to find the capacity limits of the system | Capacity planning; run on demand, not on every build |
Which automated performance testing tools fit which team?
All of the tools below can run headless from a CI job. The practical difference is the scripting language your engineers already use and whether you need managed, distributed load generation.
| Tool | What it is (from its own documentation) | When it fits | Current status (checked November 2026) |
|---|---|---|---|
| Grafana k6 | Open-source, developer-friendly, extensible performance testing tool; scripts use the k6 JavaScript API, with TypeScript support | Developer-owned tests in JavaScript or TypeScript, thresholds that fail CI builds, browser and synthetic checks | Active; docs list v2.3.x as latest |
| Apache JMeter | Apache Software Foundation open-source load testing tool | Teams with existing JMeter test plans, protocol coverage beyond HTTP, managed-service compatibility | 5.6.3 is the latest listed release; 5.6.x needs Java 8 or later (Java 17 recommended), and the next major release will need Java 17 |
| Gatling | Load testing tool with Community and Enterprise Editions; Java SDK (Maven or Gradle) and JavaScript or TypeScript SDK | JVM teams that want simulations as code in the same build as the application | Active; Gatling Enterprise Edition for managed runs |
| Locust | Open-source load testing tool; user behaviour defined in Python code; distributed over multiple machines | Python teams, custom user journeys, large distributed tests | Active |
| Taurus | Open-source test automation framework with YAML configuration, Apache 2.0 licence, maintained by BlazeMeter | A single YAML wrapper over JMeter (default), Gatling, Locust, k6, Playwright, Selenium and others | Active; lists 20 executors |
| Azure Load Testing | Fully managed load-testing service for high-scale load | Azure estates; triggered from Azure Pipelines, GitHub Actions or the Azure CLI | Supports JMeter and Locust scripts only |
| Perforce BlazeMeter | Performance and load testing platform for web, mobile and API testing | Managed scale and reporting for JMeter, Taurus and other open-source scripts | Part of Perforce Software |
How do you write a performance test with a pass or fail threshold?
A test that only produces a report still needs a person to read it. A test with thresholds makes the decision itself. Two short examples follow; point them at a pre-production URL, not at production.
Taurus YAML example
Taurus describes load with three settings: concurrency (the number of target concurrent virtual users), ramp-up (the time to reach that concurrency) and hold-for (how long the target is held). The passfail criterion below marks the run as failed if the home page average response time stays above 750 ms for 10 seconds.
execution:
- concurrency: 250
  ramp-up: 120s
  hold-for: 5m
  scenario: simple

scenarios:
  simple:
    requests:
    - label: HomePage
      url: https://staging.example.com/
    - label: ContactPage
      url: https://staging.example.com/contact

reporting:
- module: passfail
  criteria:
  - avg-rt of HomePage>750ms for 10s, continue as failed
Run it with bzt test.yml. Changing the load profile, for example a 90-second ramp-up, is a one-line edit reviewed in a pull request, instead of an edit inside a GUI test plan. In the Taurus passfail syntax, stop ends the test early when the criterion is met, while continue applies the failed status at the end of the run.
k6 example with percentile thresholds
Percentiles are usually a better service-level signal than averages, because an average can hide a slow tail. This k6 script fails the run if the 95th percentile response time exceeds 500 ms or more than 1% of requests fail.
import http from 'k6/http';

export const options = {
  vus: 50,
  duration: '5m',
  thresholds: {
    http_req_duration: ['p(95)<500'],
    http_req_failed: ['rate<0.01'],
  },
};

export default function () {
  http.get('https://staging.example.com/');
}
Note that k6 checks do not change the exit status on their own; the k6 documentation recommends combining checks with thresholds when an assertion should fail the run.
How do you run performance tests in Jenkins and other CI/CD pipelines?
The pattern is the same on any CI server: store the script with the application code, run the tool from a pipeline stage against a pre-production environment, and let the exit status decide whether the pipeline continues. In Jenkins, the Performance plugin tracks performance KPIs from JMeter, JUnit and Taurus results and can chart trends across builds. Keep the plugin current: its page lists past security advisories for older versions.
For managed scale, Azure Load Testing can be triggered from Azure Pipelines or GitHub Actions, or from the Azure CLI for other CI tools, and its test fail criteria catch regressions such as average response time or error counts above a threshold. BlazeMeter receives results from Taurus and other open-source tools for shared reporting. For the wider practice of test automation in delivery pipelines, see our guide to testing agentic process automation, which applies the same discipline to AI-driven workflows.
What is a practical automated performance testing strategy?
Match test length to pipeline stage. If a user scenario is short, for example a single API endpoint or microservice tested in under 30 seconds, run it on every commit as a smoke test. Longer end-to-end journeys need more time to collect enough samples to be meaningful, so run them about once a day or on each deployment to the pre-production environment where load tests run.
- Pick the journeys that matter. Start with the three to five user or API flows that carry revenue or service-level commitments.
- Write thresholds from service levels. Express targets as percentiles and error rates, agreed with product and operations owners.
- Add a smoke test to every pull request. Low load, short duration, and a threshold that fails the build.
- Schedule average-load and soak tests. Run them against a production-like environment with representative data volumes.
- Compare runs, not single results. Store results so each run is compared with the previous baseline, and investigate trends as well as failures.
- Connect testing to monitoring. Use the same metrics in tests and in production performance monitoring, so a test failure and a live alert mean the same thing.
What governance, security and cost controls do performance tests need?
- Environment approval. Load tests can look like a denial-of-service attack. Run them against pre-production by default, and require written approval, a time window and a named contact for any production test.
- Test data. Use synthetic or masked data. Do not load real customer records into test environments to make a test realistic.
- Secrets. Keep tokens and passwords in the CI secret store, not in YAML or JavaScript files in the repository.
- Cost limits. Cloud load generators are billed by scale and duration. Cap virtual users and duration in code, and use the auto-stop options in Taurus passfail or Azure Load Testing so a failing test ends early.
- Third-party limits. Stub or exclude payment gateways, email providers and other external APIs, whose terms and rate limits rarely allow load tests.
How does automated performance testing apply to AI agents and LLM services?
AI agents and model-backed APIs are services with response times, error rates and capacity limits like any other, so the same thresholds and pipeline stages apply. Teams typically add AI-specific checks alongside them, such as whether answers remain correct and within policy under load. AgentQA provides automated quality assurance for AI, and AgentEvaluation tests and benchmarks AI agents. For teams running agents and automation workflows in production, ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
When is automated performance testing not worth it, and what are the trade-offs?
Automation has a maintenance cost. Scripts break when user journeys change, test environments that differ from production give misleading numbers, and noisy shared environments produce flaky failures that teams learn to ignore. For a low-traffic internal tool with no service-level commitment, occasional manual load tests before major changes may be enough.
The trade-off is usually worth making for customer-facing services, APIs with contractual service levels and systems with known peak events. Start small with one smoke test and one threshold, prove that failures are real, then extend coverage. Performance is one part of software quality management, alongside functional, security and user acceptance testing.
To map one release decision your pipeline and agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is automated performance testing?
It is running load, stress, soak and spike tests as code from a CI/CD pipeline, with thresholds on metrics such as response time and error rate that pass or fail the build without manual review.
Which tools are used for automated performance testing?
Common open-source tools are Grafana k6, Apache JMeter, Gatling and Locust, with Taurus as a YAML wrapper over them. Managed options include Azure Load Testing, which supports JMeter and Locust scripts, and Perforce BlazeMeter.
How do thresholds fail a CI build?
In k6, if a threshold fails, k6 exits with a non-zero exit code, which CI servers treat as a failed step. Taurus uses passfail criteria, such as average response time above 750 ms for 10 seconds, to mark the test as failed.
How often should automated performance tests run?
Short scenarios, such as a single API endpoint under 30 seconds, can run on every commit. Longer end-to-end scenarios usually run about once a day or on each deployment to pre-production. Soak, stress and breakpoint tests run on a schedule or on demand.
Which performance test types does k6 describe?
Smoke, average-load, stress, soak, spike and breakpoint tests. Smoke tests suit every pull request; the others suit scheduled runs or specific events.
Does Apache JMeter still need Java 8?
JMeter 5.6.x requires Java 8 or later, with Java 17 or later recommended. The project states that the next major release will require Java 17 or later.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE