Key takeaway
- History of computer vision from Hubel and Wiesel, the 1966 MIT project and ImageNet to AlexNet, transformers, foundation models and governed vision agents.
Computer vision is the branch of artificial intelligence that lets software interpret images and video. Its history runs from neuroscience in 1959, through rule-based scene analysis in the 1960s and hand-crafted features in the 2000s, to deep learning after 2012 and, since 2020, transformers and foundation models trained on hundreds of millions of images. Each step lowered the cost of teaching a machine to see a new thing.
For enterprise leaders the history matters because it explains today's choices: when a classic rule-based system is still the right answer, when to fine-tune a foundation model, and why vision is now moving from dashboards to governed vision agents that act on what cameras see. This guide sets out the milestones with their original sources, what has changed since 2024, and how to adopt computer vision safely.
What is computer vision?
Computer vision turns pixels into structured information: a class label, a bounding box, a segmentation mask, a reading of text, a track of a moving object or a written description of a scene. That output then feeds a decision, such as rejecting a part, raising an alert or updating a record. Modern systems learn these mappings from data rather than from hand-written rules, which is the main thread of the history below. For how a project runs end to end today, see our computer vision workflow guide.
How did computer vision begin?
The field grew out of two lines of work in the 1950s and 1960s: studies of how biological vision processes images, and early attempts to make computers describe simple scenes.
1959: how the visual cortex processes images
In 1959 David Hubel and Torsten Wiesel published Receptive fields of single neurones in the cat's striate cortex in The Journal of Physiology. Their work on the visual system later shared the 1981 Nobel Prize in Physiology or Medicine "for their discoveries concerning information processing in the visual system". The idea that vision is built up in layers, from simple features to complex shapes, shaped neural network design for decades.
1963 to 1966: the first machine vision programmes
Lawrence G. Roberts' 1963 MIT PhD thesis, Machine perception of three-dimensional solids, is one of the earliest studies of how a computer could recover three-dimensional objects from images. In July 1966 Seymour Papert's MIT memo The Summer Vision Project (AI Memo 100) set summer workers the task of building a significant part of a visual system: figure-ground analysis, region description and finally object identification against a vocabulary of known objects. The project showed how much harder vision was than it first appeared.
1980: the neocognitron
In 1980 Kunihiko Fukushima published the neocognitron in Biological Cybernetics: a multilayer network, modelled loosely on Hubel and Wiesel's hierarchy, that learned without a teacher to recognise shapes regardless of their position. Its alternating feature-extracting and shift-tolerant layers are an ancestor of today's convolutional neural networks.
What are the key milestones in the history of computer vision?
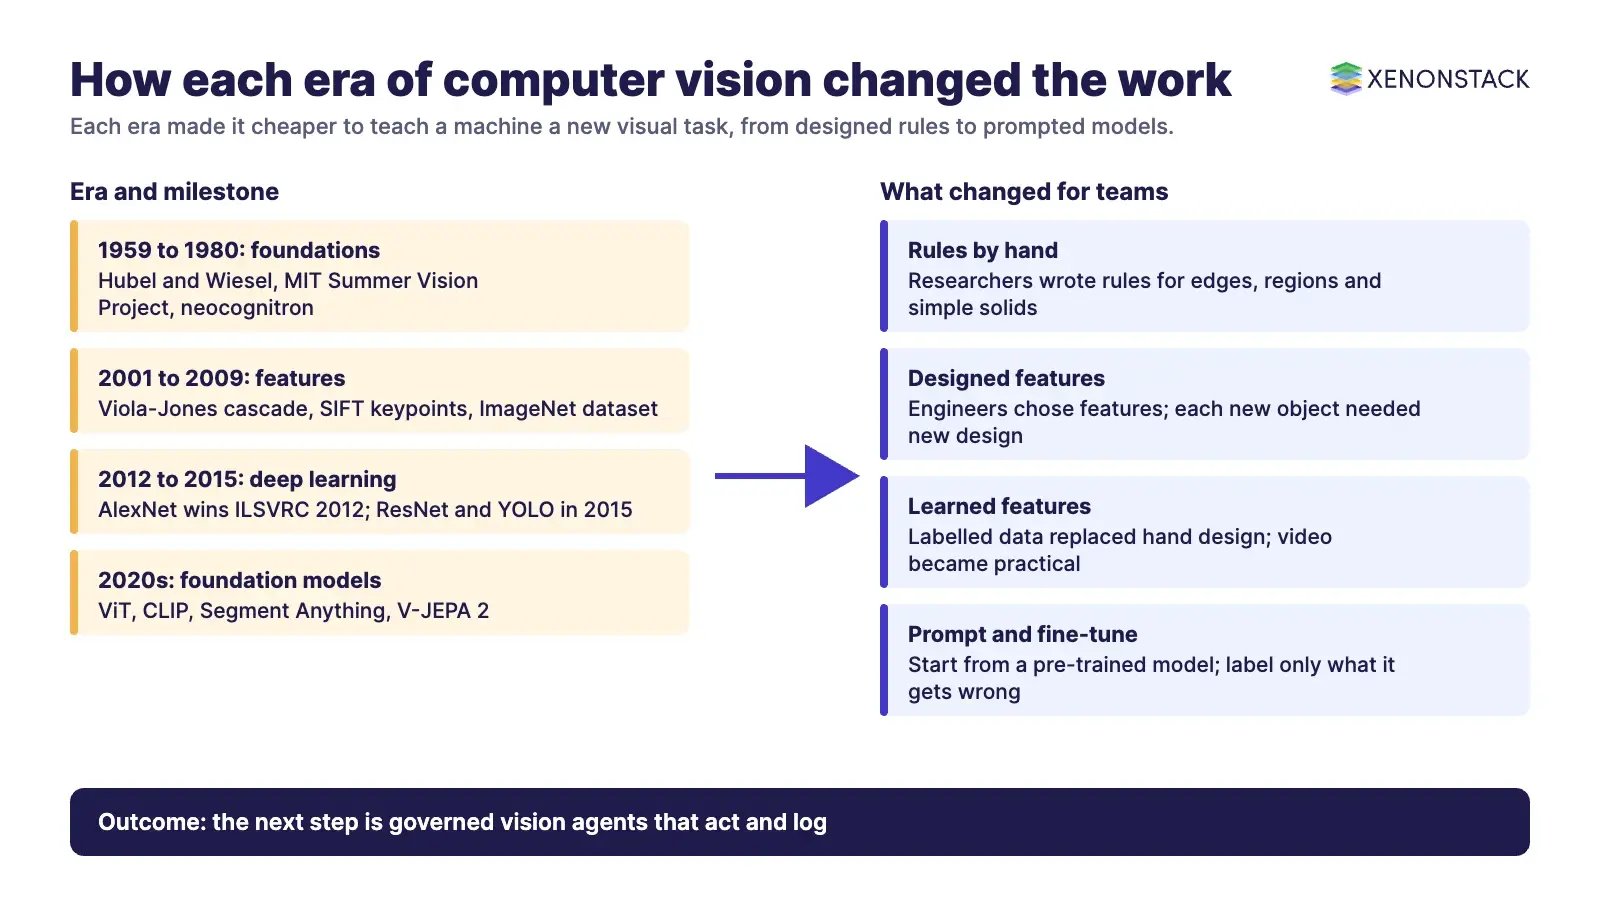
The table lists the milestones that most shaped enterprise computer vision, each linked to its original paper or record, and what each one means for a project today.
| Year | Milestone | Why it mattered | Status today |
| 1959 | Hubel and Wiesel, receptive fields in the visual cortex | Showed vision is processed in layers of simple to complex features | Foundational science; idea lives on in layered networks |
| 1963 | Roberts, machine perception of 3D solids (MIT thesis) | Early attempt to recover 3D objects from 2D images | Historical; 3D perception now uses depth sensors and learned models |
| 1966 | MIT Summer Vision Project (AI Memo 100) | Framed vision as segmentation, description and identification | Historical; the same sub-tasks still define the field |
| 1980 | Fukushima's neocognitron | Shift-tolerant, layered pattern recognition | Ancestor of convolutional networks |
| 2001 | Viola and Jones, boosted cascade face detector | Real-time face detection on ordinary hardware | Still used where compute is tiny; largely replaced by deep detectors |
| 2004 | Lowe, SIFT features (IJCV) | Robust matching of keypoints between images | Patent expired 7 March 2020; still used for matching and mapping |
| 2009 | ImageNet dataset | Large labelled dataset organised by the WordNet hierarchy | Remains a reference benchmark |
| 2012 | AlexNet (SuperVision) wins ILSVRC 2012 | Deep convolutional networks overtook hand-crafted features | Start of the deep learning era |
| 2015 | ResNet and YOLO | Very deep networks became trainable; real-time single-pass detection | Residual blocks and one-stage detectors remain standard |
| 2020 | Vision Transformer (ViT) | Transformers matched convolutional networks on image classification | Common backbone for foundation models |
| 2021 to 2025 | CLIP, Segment Anything, V-JEPA 2 | Image-text, promptable segmentation and video foundation models | Default starting point for new projects |
How did hand-crafted features shape the 2000s?
Before deep learning, engineers designed the features a system looked for. Two papers show the approach at its best.
- Viola and Jones (2001). Rapid Object Detection using a Boosted Cascade of Simple Features introduced the integral image, AdaBoost feature selection and an attentional cascade that rejects most background quickly. The paper reports face detection at about 15 frames per second on a 700 MHz Pentium III.
- SIFT (2004). David Lowe's Distinctive image features from scale-invariant keypoints (International Journal of Computer Vision, 60(2), 91 to 110) gave a reliable way to match points between images. The University of British Columbia's US patent 6,711,293 expired on 7 March 2020, and open implementations are available in libraries such as OpenCV.
The limit of this era was data. Each new object or defect type needed new expert-designed features. ImageNet, first published in 2009, changed that by organising labelled images according to the WordNet hierarchy, aiming for an average of 1,000 images per concept. Large labelled datasets made it possible to learn features instead of designing them. Labelling is still the slowest step in most projects; AgentLabel combines AI-assisted annotation with human review to label text, images and more at scale.
Why was 2012 a turning point for computer vision?
In 2012 Alex Krizhevsky, Ilya Sutskever and Geoffrey Hinton trained a deep convolutional network on the ImageNet competition data. Their paper, ImageNet Classification with Deep Convolutional Neural Networks, describes a network with 60 million parameters and five convolutional layers classifying images into 1,000 classes. In the ILSVRC 2012 results, their SuperVision entry won the classification task with a top-5 error of 0.153, against 0.262 for the best entry from another team.
Progress then came quickly. ResNet (He et al., December 2015) trained residual networks up to 152 layers deep and placed first in the ILSVRC 2015 classification task, with an ensemble reaching 3.57% error on the ImageNet test set. YOLO (Redmon et al., 2015) framed detection as a single regression problem and reported real-time processing at 45 frames per second, which made video use cases practical.
How did transformers and foundation models change computer vision?
Since 2020 the field has moved from one model per task to large pre-trained models that are adapted with little data.
| Model | What it introduced | Source | When it fits |
| Vision Transformer (2020) | Applies a pure transformer to image patches; competitive with convolutional networks when pre-trained on large data | Dosovitskiy et al. | Backbone for large-scale pre-training; see our Vision Transformers guide |
| CLIP (2021) | Trained on 400 million image and text pairs; classifies new categories from text prompts without task-specific training | Radford et al. | Search, tagging and zero-shot screening |
| Segment Anything (2023) | Promptable segmentation; SA-1B dataset of over 1 billion masks on 11 million licensed images | Kirillov et al. | Faster labelling and segmentation without training from scratch |
| V-JEPA 2 (2025) | Self-supervised video model pre-trained on over 1 million hours of internet video and images; used for video question answering and zero-shot robot planning | Assran et al. | Video understanding and physical AI research |
The practical result is that many enterprise projects now start from a foundation model and fine-tune or prompt it, rather than collecting tens of thousands of labelled images first. Check each model's licence before commercial use, because licences differ by model and version.
How does modern computer vision work?
A current enterprise system combines pieces from every era of the history above.
- Capture. Cameras, scanners, drones or depth sensors produce images or video.
- Pre-processing. Frames are resized, normalised and, where privacy requires it, cropped or blurred.
- Perception model. A convolutional network, vision transformer or vision-language model produces labels, boxes, masks, text or a description.
- Decision logic. Thresholds, business rules or an AI agent decide what the result means and whether to act.
- Action and record. The system rejects a part, raises an alert or updates a record, and logs what it saw and why it acted.
- Monitoring. Low-confidence cases and drift are sent back for review and relabelling.
Steps 4 and 5 are where the field is moving now. Rather than only showing detections on a dashboard, vision AI agents read the scene, check policy and take the next step, as described in our guide to agentic AI for real-time video analytics.
Video: what computer vision is and why enterprises use it (XenonStack).
What has changed in computer vision since 2024?
| Change | What it means | Date and source |
| EU AI Act prohibitions in force | Untargeted scraping of internet or CCTV images for facial recognition databases, emotion recognition at work and in education, and some biometric categorisation are banned | Applied from 2 February 2025 (European Commission) |
| High-risk dates moved by the AI Omnibus | High-risk use cases in Annex III, such as biometrics and critical infrastructure, apply later; AI in regulated products later still | 2 December 2027 (Annex III) and 2 August 2028 (Annex I) (European Commission) |
| Older cloud vision APIs retired | Microsoft retired Computer Vision API versions 1.0, 2.0, 3.0 and 3.1; Image Analysis 4.0 preview APIs were retired earlier | 13 September 2026 and 31 March 2025 (Microsoft Learn) |
| Video foundation models | Self-supervised models learn from very large video collections and support question answering about video | V-JEPA 2, June 2025 (arXiv) |
| Reference designs for vision agents | Vendors publish blueprints in which agents search, summarise and verify alerts from live and recorded video | NVIDIA VSS blueprint, docs version 3.3.0 (NVIDIA) |
What do governance, security and cost look like for computer vision?
| Area | What to put in place | Why |
| Privacy | Data protection impact assessment for cameras in public or work areas; blur or crop where identity is not needed | Biometric data used to identify people is a special category under GDPR Article 9 |
| Regulation | Map each use case against the EU AI Act prohibited list and the Annex III high-risk categories | Prohibitions already apply; high-risk duties apply from 2 December 2027 |
| Traceability | Log the frame or clip, model version, confidence and action for every automated decision | Needed for audit, dispute handling and model improvement |
| Security | Treat cameras and edge devices as network assets: patching, segmentation, signed models | Compromised devices can leak footage or feed false inputs |
| Cost | Decide where inference runs (edge, cloud or both) from latency, bandwidth and privacy needs | Streaming all video to the cloud is often the largest running cost |
| Vendor lifecycle | Track end-of-support dates for every API and SDK in use | Cloud vision APIs have been retired with fixed deadlines |
How should enterprises adopt computer vision today?
- Pick one decision, not one model. Name the action the system will take and the error rate the business can accept.
- Check the legal position first. Screen the use case against the EU AI Act prohibited list, high-risk categories and GDPR before buying cameras.
- Start from a foundation model. Prompt or fine-tune an existing model and measure it on your own images before collecting large datasets.
- Label what the model gets wrong. Use model proposals with human review rather than labelling everything by hand.
- Decide edge, cloud or hybrid. NexaStack is an agentic operating platform for physical AI that runs across on-premises, cloud and hybrid environments, including vision AI at the edge.
- Govern the action, not only the model. Record who or what approved each automated step; Audit Agent assembles decision lineage, policy versions, approvals and authority chains for compliance teams.
- Scale by site and use case. Add cameras and use cases once monitoring shows the first one is stable.
For use cases by industry, see our guide to computer vision applications, and for factory inspection, our machine vision guide.
What are the trade-offs, and when is computer vision the wrong choice?
- Rule-based tools still win in controlled scenes. Fixed lighting and known parts often need only classic measurement, which is cheaper to validate than deep learning.
- Foundation models are large. They may be too slow or costly for small edge devices without distillation or quantisation.
- Accuracy is not uniform. Performance can drop for rare conditions, new sites or under-represented groups of people; test by slice, not only on average.
- Some uses are not allowed. If the use case needs emotion recognition at work or untargeted facial scraping, it is prohibited in the EU.
- Another sensor may be simpler. Barcodes, RFID, weight sensors or a form field can answer the question with less risk.
What will change in computer vision over the next 3 to 5 years?
The history shows a steady pattern: each era made it cheaper to teach a machine a new visual task. The predictions below rest on dated regulation, vendor notices and published research. Where a row is our own view, it says so.
| Prediction | Why we expect it (evidence) | Timeframe | What leaders should do now |
| EU biometric and critical infrastructure vision will need full high-risk compliance | High-risk Annex III duties apply from 2 December 2027 and Annex I from 2 August 2028 (European Commission) | By December 2027 and August 2028 | Inventory vision use cases now and start logging and human-oversight design |
| Foundation models will be the default starting point for most new vision projects | XenonStack's view, based on the trend from CLIP (2021) to Segment Anything (2023) and V-JEPA 2 (2025) (arXiv). Would be wrong if task-specific models keep a clear cost and accuracy lead | Within 1 to 3 years | Benchmark one foundation model against your current model on your own data |
| Video understanding will move from detection to vision agents that search, summarise and act | Vendor reference architectures for vision agents already exist, such as NVIDIA's VSS blueprint (NVIDIA); timing is XenonStack's view | Within 2 to 4 years | Define which actions an agent may take alone and which need approval |
| More legacy vision APIs will be retired in favour of general model platforms | Microsoft retired Computer Vision API 1.0 to 3.1 on 13 September 2026 (Microsoft Learn); extension to other vendors is XenonStack's view | Ongoing | List every vision API in use with its support date |
| Agentic vision projects without risk controls will be stopped | Gartner predicts over 40% of agentic AI projects could be cancelled by the end of 2027, citing costs, unclear value and weak risk controls, as reported by New Electronics | By end of 2027 | Tie each vision agent to a measured business outcome and a policy owner |
What this means for you: if you are a CTO or CDO, the next step is not a bigger model but a governed one: pick a use case that is legal, measurable and logged, and build from a foundation model.
To map one vision decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions about the history of computer vision
Who started computer vision?
No single person did. Key early work includes Hubel and Wiesel's 1959 study of the visual cortex, Lawrence Roberts' 1963 MIT thesis on perceiving three-dimensional solids, and Seymour Papert's 1966 MIT Summer Vision Project.
Why was AlexNet important in the history of computer vision?
In ILSVRC 2012 the AlexNet entry, SuperVision, won image classification with a top-5 error of 0.153 against 0.262 for the best other team. It showed that deep convolutional networks trained on large datasets beat hand-crafted features.
What is the difference between classic and modern computer vision?
Classic systems used features designed by engineers, such as Viola-Jones cascades or SIFT keypoints. Modern systems learn features from data with convolutional networks, vision transformers and foundation models such as CLIP and Segment Anything.
What changed in computer vision regulation recently?
The EU AI Act bans untargeted facial image scraping, emotion recognition at work and in education, and some biometric categorisation from 2 February 2025. High-risk duties for Annex III use cases apply from 2 December 2027.
Is SIFT still patented?
No. The University of British Columbia's US patent 6,711,293 for SIFT expired on 7 March 2020, according to David Lowe's SIFT page.
How will computer vision change over the next 3 to 5 years?
We expect foundation models to become the usual starting point and vision agents to search, summarise and act on video. In the EU, high-risk vision uses need full compliance from 2 December 2027 (Annex III) and 2 August 2028 (Annex I).
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE