What are data quality metrics and how do you use them to make decisions?
A data quality metric is a number that tells you how well a dataset meets a stated requirement, for example the percentage of customer records with a valid email address. A dimension such as completeness is the quality you care about; the metric is the formula, the threshold and the owner that make it measurable.
This guide focuses on measurement: formulas for each dimension, how to set thresholds, how to report them and where metrics mislead. For the automation side, see our guide to augmented data management best practices.
Key takeaways
- Measure six dimensions: accuracy, completeness, consistency, timeliness, validity and uniqueness. Each maps to a different business risk.
- A metric needs a formula, a threshold, an owner and an action when it fails. Without these it is a vanity number.
- For CDOs: set tighter thresholds on critical data elements and report them separately from dataset averages, which hide the failures that matter.
- For Chief AI Officers: model reliability is bounded by upstream data quality, so track the metrics on training and retrieval data before the model, not only on reports.
Which standards define data quality characteristics?
No single list of dimensions is universal, so anchor yours to a standard. ISO/IEC 25012:2008 defines a data quality model of 15 characteristics across inherent and system-dependent perspectives, and ISO/IEC 25024 (latest edition 2015) specifies how to measure them (as summarised by arc42 Quality Model). ISO 8000-8:2015 takes a different cut, defining syntactic, semantic and pragmatic quality, meaning conformance to format, correct meaning and fitness for the user's purpose (also via arc42). The six dimensions below are a practical subset that most enterprise teams can operate.
Which metric measures each dimension?
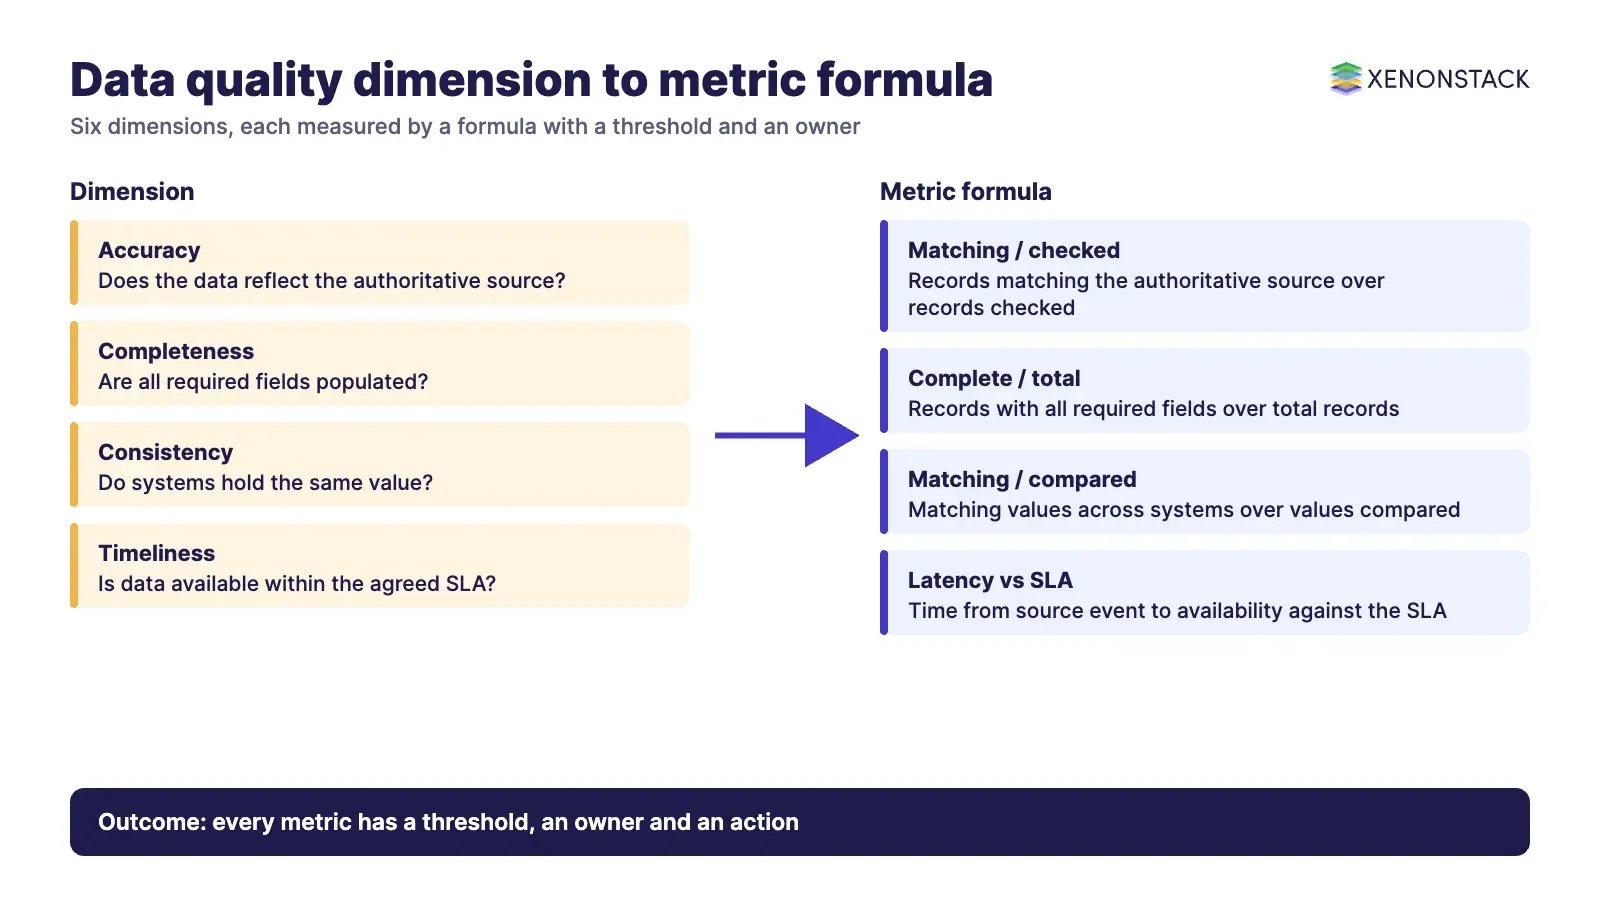
| Dimension | Metric formula | Example | Business risk if it fails |
|---|---|---|---|
| Accuracy | Records matching the authoritative source / records checked | Customer address versus the billing system | Flawed analysis and regulatory errors |
| Completeness | Records with all required fields populated / total records | Transactions with amount and timestamp | Skewed aggregates and invalid models |
| Consistency | Matching values across systems / values compared | Same customer status in CRM and ERP | Teams report different numbers |
| Timeliness | Time from source event to availability, compared with the agreed SLA | Order data available within the refresh window | Decisions made on stale data |
| Validity | Records passing format, range and code rules / records checked | Country codes in the allowed list | Wrong inferences despite populated fields |
| Uniqueness | Distinct entities / total records for that entity | One record per customer ID | Inflated counts and false signals |
Accuracy: does the data reflect reality?
Cross-verify against an authoritative source and track error rates per domain or field, using statistical sampling where full checks are too costly. Accuracy is the precondition for any analysis used in financial, regulatory or clinical decisions.
Completeness: are required elements present?
Track the share of missing values in critical fields, and run gap analysis against the fields each decision process actually needs. A dataset can be 99 per cent complete overall and still miss the one field a model depends on.
Consistency: is data uniform across systems?
Compare the same element across datasets and run reconciliation checks at set intervals. Enforcing standard entry procedures at source prevents most discrepancies. Master data management addresses the cross-system cause directly.
Timeliness: is data there when the decision is made?
Track refresh cycles against business-defined SLAs and measure latency from source event to availability. The right refresh rate depends on the operational pace of the consuming team, for example supply chain or trading versus monthly reporting.
Validity: does data follow business rules?
Enforce format, range and enumeration checks at capture and run routine compliance checks. Data can be present and accurate in isolation yet still break the rules of the system consuming it.
Uniqueness: are duplicates corrupting analysis?
Use identifier-based deduplication and automated flagging, and keep cleaning pipelines running so duplicates do not re-accumulate. Duplicates distort customer analytics and financial reconciliation.
How do you set thresholds and KPIs that people own?
Give each dimension a target per data element, document it and name an owner. Percentages such as 95 per cent accuracy or 98 per cent completeness for critical fields are illustrative starting points, not standards; set yours from the cost of an error to the business process using the field. Review thresholds quarterly. Our guide to common data quality issues helps you decide which defects deserve the tightest targets.
How are data quality metrics measured and reported at enterprise scale?
1. Data profiling
Profiling analyses distributions, patterns and outliers. Run it before onboarding a source and at regular intervals after integration.
2. Automated monitoring
Scan continuously against defined rules, alert on threshold breaches and track trends, so teams intervene before issues reach downstream systems.
3. Dashboards and scorecards
Business intelligence dashboards give executives and operators the same view, with alerts when a metric falls below its threshold. AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights, which helps non-specialists query quality results.
4. User feedback
Metrics catch structural failures. Surveys by user group catch data that is technically correct but does not serve the task.
What is the data quality lifecycle?
| Phase | Activity | Metric output |
|---|---|---|
| Discovery | Identify sources, classify data, gather requirements | Inventory of critical data elements |
| Profiling | Quality sweep, rule suggestion, rule approval | Baseline per dimension |
| Rules | Run approved business rules against datasets | Pass rates against thresholds |
| Remediation | Publish reports, assign owners, clean up | Open issues and time to fix |
| Monitoring | Dashboards and scorecards | Trend per dimension |
How do you turn metrics into continuous improvement?
- Review regularly. Find high error rates, field-level gaps and cross-system conflicts, and run root cause analysis on the costliest.
- Share KPIs and ownership. Shared targets stop quality failures falling between teams.
- Back them with governance. Define roles, entry standards and escalation paths. ElixirData keeps governed context, versioned policy and decision traces in one decision layer above AI agents.
- Train the people who enter data. Standards only hold if the people capturing data understand them.
- Iterate quarterly. Compare progress with targets and adjust.
Where do data quality metrics mislead?
- Averages hide critical failures. Report critical data elements separately.
- Passing rules is not accuracy. A valid-looking value can still be wrong, so sample against a source.
- Too many metrics. Track few metrics per domain, each with an owner and an action.
- Static thresholds. Business processes change, so review them.
To map one data quality decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What are data quality metrics?
Measurable indicators, each with a formula, threshold and owner, that show how well data meets requirements for accuracy, completeness, consistency, timeliness, validity and uniqueness.
What is the difference between a dimension and a metric?
A dimension is the quality attribute, such as completeness. A metric is the calculation that measures it, for example complete records divided by total records.
How can duplicate data be detected?
Through identifier-based matching and automated deduplication, then tracked as distinct entities divided by total records.
What threshold should we set?
There is no universal figure. Set it from the cost of an error to the process using the data, and review it quarterly.
Which standards apply?
ISO/IEC 25012 defines a data quality model, ISO/IEC 25024 covers measurement, and ISO 8000-8 defines syntactic, semantic and pragmatic quality.
Conclusion: measure what you will act on
Good data quality metrics are few, owned and tied to an action. Audit current practice across the six dimensions, set thresholds on critical data elements, and assign owners. Automation can then reduce the effort, as covered in our augmented data management guide.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE