Key takeaway
- Serverless microservices in Java run as event-driven functions. Learn twelve-factor rules, Lambda packaging, cold starts and the AI agent impact.
A serverless microservice in Java is a small, single-purpose Java service that runs as an event-driven function on a managed platform, so the team ships code and configuration while the provider runs the servers. It keeps the microservice idea of one job per service and removes the work of provisioning and patching the machines underneath.
This guide is for Java developers, DevOps engineers and architects who want to move one service to functions. It covers how serverless differs from running servers, which twelve-factor rules matter, how to build and package an employee lookup function, where the limits are, and how AI agents change the design. It links to our guides on serverless computing applications and architectures and building serverless microservices with Python.
What is a serverless microservice in Java?
Serverless does not mean there are no servers. It means developers no longer manage them. The AWS Lambda documentation puts it this way: "AWS Lambda is a serverless compute service. With Lambda, you can run code without provisioning or managing servers." You write a handler function, connect it to a trigger such as API Gateway, Amazon S3 or Amazon SQS, and the platform runs it.
Serverless applications lean on third-party backend services (Backend as a Service) or on custom code in short-lived containers (Function as a Service). The shift is from a framework that reacts to many events to a small function that reacts to one. Serverless architectures and AWS serverless computing go further on the platform side. Where a traditional PaaS asks you to specify resources such as dynos or gears, a serverless platform finds a place to run the code and scales it when needed.
How does serverless differ from owning servers?
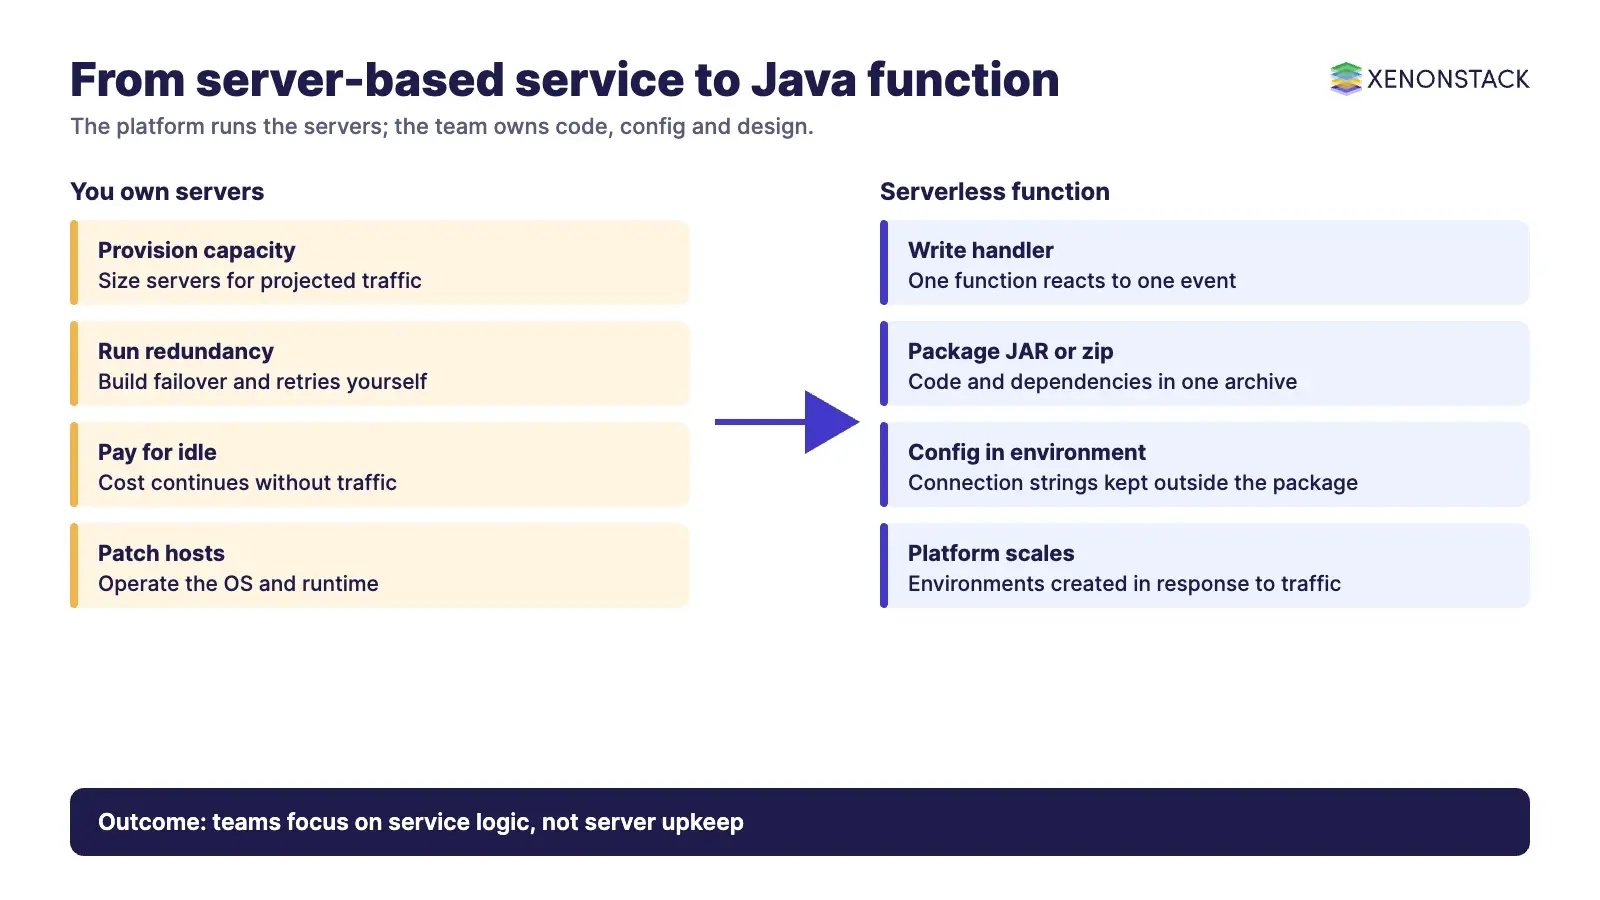
Owning servers means you map your application to CPU, memory and disk, pay for capacity sized to projected traffic whether or not it arrives, and build redundancy, failover and retries yourself. A serverless platform moves most of that to the provider, but design duties remain.
| Concern | Server-based service | Serverless function |
|---|---|---|
| Capacity | You provision for expected traffic | Per the Lambda docs, the platform creates and destroys execution environments in response to traffic |
| Billing | You pay for provisioned servers | Per request plus GB-seconds of execution time, with no upfront commitment |
| Reliability | You build redundancy, failover and retries | The provider manages the infrastructure; you still design retries and idempotent handlers |
| State | Held in the process if you choose | Each invocation runs independently; state may not persist, so keep it in a database |
Which twelve-factor rules matter for Java microservices?
Microservices are independently deployable, independently scalable systems that talk over protocols such as HTTP with JSON or XML, Thrift or Protocol Buffers. They apply the single responsibility principle at the codebase level. The Twelve-Factor App gives a practical checklist, and six of its factors bear directly on a Java function. See also our overview of microservices architecture.
| Factor | Rule as stated | What it means for a Java function |
|---|---|---|
| Codebase | One codebase tracked in revision control, many deploys | One repository per service, one deployable artifact |
| Dependencies | Explicitly declare and isolate dependencies | Declare libraries in Maven or Gradle, never rely on jars already on a server |
| Config | Store config in the environment | Pass the database connection string as an environment variable, not a file in the package |
| Build, release, run | Strictly separate build and run stages | Build the artifact once, release it with its configuration, then run it |
| Logs | Treat logs as event streams | Write logs to the platform stream and route them to log analysis |
| Dev/prod parity | Keep development, staging, and production as similar as possible | Test with the same runtime version you deploy |
How do you build an employee lookup function in Java?
The example is an Employee Service with one function, GetEmployee, that reads a record from a database. The steps use AWS Lambda; the pattern carries to other platforms.
- Prepare the data store. Install MongoDB, create an EmployeeDB database, create an Employee collection and insert a few demo records.
- Create the project. The Java on Lambda page lists aws-lambda-java-core as required (handler interfaces and the context object) and aws-lambda-java-events for event input types, both published on Maven Central. If you prefer a framework, the Spring Framework ecosystem includes Spring Cloud Function, whose reference lists an AWS Lambda adapter under serverless platform adapters.
- Write the handler. The page shows a class implementing RequestHandler with a handleRequest method that takes an event and a context, and a handler setting in the form example.Hello::handleRequest.
- Create the database client outside the handler and read the connection string from an environment variable. The Lambda docs say objects declared outside the handler remain initialised when an environment is reused, and recommend checking whether a connection exists before creating one.
- Package it. The page describes a .zip file archive containing your code, with .zip or JAR archives and container images as the two options. Keep dependencies in the build file and let the build tool assemble the archive.
- Deploy, set the handler, add a trigger such as API Gateway and test with a sample event. Check the logs for the request ID.
What are the limits of serverless microservices?
The trade-offs are real, and most follow from how the platform runs your code. The Lambda execution environment page describes an Init, Invoke and Shutdown lifecycle, and says a cold start covers downloading code and setting up the environment, typically occurring in under 1% of invocations and ranging from under 100 ms to over 1 second. Java teams should watch initialisation time, because static setup runs in that phase.
- Duration: the Lambda overview lists up to 15 minutes per invocation by default, so long jobs need another pattern.
- Statelessness: the docs say not to assume an environment persists; keep durable state in external services.
- Version support: the Java page lists supported runtimes with deprecation dates, so pin a supported runtime and plan upgrades.
How do AI agents change serverless microservices in Java?
AI agents call services as tools, so each function becomes an action an agent may take, not only an endpoint a screen calls. That raises the bar on the basics: a stable request and response shape, idempotent handlers that survive a retried call, narrow permissions per function, and logs that show who called what. Long-running agent tasks belong in a workflow, not one function. ElixirClaw, the AI agents computing platform, is where XenonStack builds and runs agents that call services like these.
What should you do first?
- Pick one read-only service, such as employee lookup, and rebuild it as a single function.
- Move every setting into environment variables and keep the package free of secrets.
- Create clients outside the handler and measure cold start on your own runtime.
- Route logs to one analysis system and alert on errors.
- Decide which functions agents may call and document their inputs and outputs.
For hands-on support, see our managed services for microservices. You may also like Laravel Docker application development, best practices for monitoring Docker containers and container security solutions.
To map one decision your agents make across services, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
Is serverless the same as having no servers?
No. Servers still run your code, but the provider provisions, scales and patches them, so the team manages code and configuration instead.
Which Java runtimes does AWS Lambda support?
The Java on Lambda page lists managed runtimes for several Java versions with deprecation dates. Check that page for the current list before you choose one.
How do I reduce cold start time for a Java function?
Keep static initialisation small, create clients once outside the handler, and measure Init duration in your logs. The Lambda documentation also describes provisioned concurrency for functions that need initialisation done in advance.
Where should a Java function keep its configuration?
In environment variables, following the twelve-factor rule to store config in the environment, so the same package runs in development, staging and production.
Should every microservice become a function?
No. Short, event-driven, stateless services fit well. Long-running or tightly stateful services may suit containers or virtual machines better.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE