Key takeaway
- Serverless microservices in Python run as event-driven functions. Learn packaging, deployment, cold starts and limits, and how AI agents change the design.
A serverless microservice in Python is a small Python function, packaged with its dependencies, that a managed platform runs in response to an event, so the team writes application logic without managing servers, operating systems or virtual machines. The servers still exist, but provisioning and managing the infrastructure belongs to the service provider.
This guide is for programmers, DevOps engineers and architects who want a clear path from a Python service to a function. It covers how monolith, microservice and function styles differ, how to package and test a Python function, the limits to plan for, and how AI agents change the design. For the Java version, read our guide to serverless microservices in Java.
What is a serverless microservice in Python?
The AWS Lambda documentation describes Lambda as "a serverless compute service" where you "run code without provisioning or managing servers". You write a handler, connect it to a trigger, and the platform runs it. Our guide to serverless computing covers the wider model, and function as a service explains the function layer. Your company still owns software design: serverless removes machine work, not engineering work.
How do monolith, microservice and function styles differ?
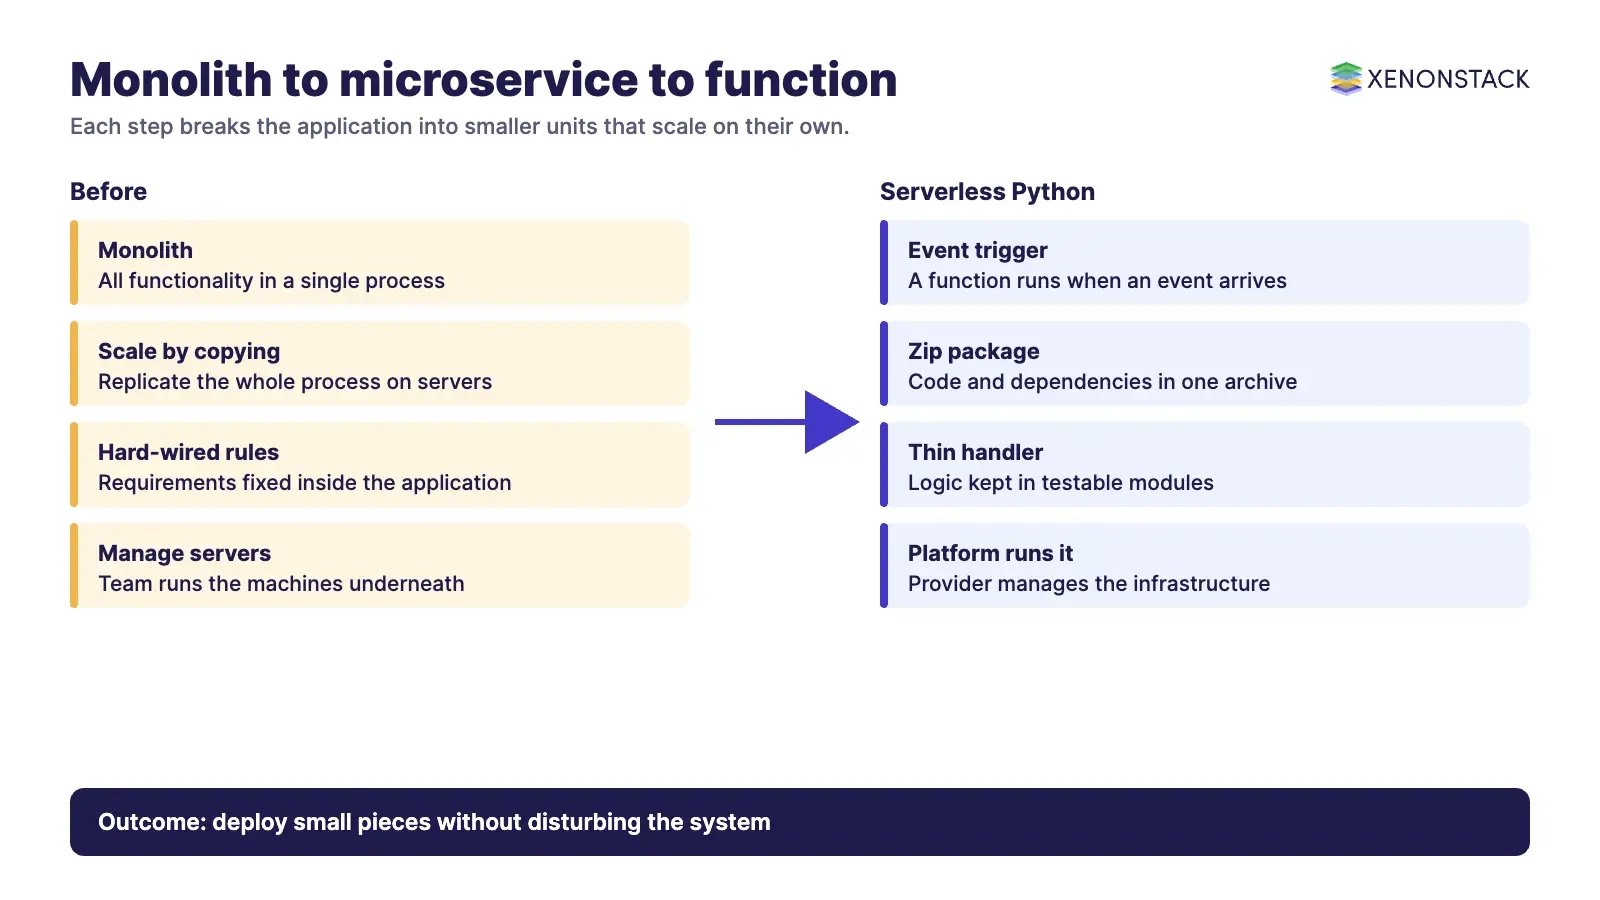
Serverless changes how applications are built. Traditionally, business rules, boundary conditions and complex integrations are wired into one application, which slows delivery and hard-codes a fixed set of requirements. Smaller deployable units let an application evolve and be deployed without disturbing the rest of the system. See our overview of microservices architecture.
| Style | How it is built | How it scales |
|---|---|---|
| Monolith | All functionality in a single process | Replicate the whole process on more servers |
| Microservice | Each capability is a separate service | Distribute services across servers and replicate as needed |
| Function (FaaS) | Services broken into functions triggered by events | The platform runs functions as events arrive |
How do you package and deploy a Python function?
The Python on Lambda page lists the supported runtimes with their deprecation dates, so choose a supported version first. A handler has the signature lambda_handler(event, context), and the code runs in an environment that includes the AWS SDK for Python (Boto3), with credentials from an IAM role that you manage. The page also lists three deployment options: .zip file archives, layers, and container images.
Our worked example is an employee lookup that reads from a MongoDB database. The steps below follow the .zip route.
- Prepare the data store: install MongoDB, create an EmployeeDB database and an Employee collection, and insert a few demo records.
- Create a project directory and save your .py source files at its root, with a folder such as app for the code.
- List extra libraries in requirements.txt and install them into the directory so they ship with the code.
- Read the connection string from an environment variable instead of a config.py file inside the package, then create the client outside the handler.
- Zip the directory contents, upload the archive, set the handler name and choose a trigger.
- Run a test event and check the response and logs.
The execution environment page explains why the client belongs outside the handler: objects declared outside it remain initialised when an environment is reused, and it recommends checking whether a connection exists before creating a new one.
What are the limits of serverless in Python?
| Limit | What it means | How to respond |
|---|---|---|
| Cold start | Per the Lambda docs, a cold start covers downloading code and setting up the environment; it typically occurs in under 1% of invocations and ranges from under 100 ms to over 1 second | Keep imports light, create clients once, measure Init time |
| Long-running work | The Lambda overview lists up to 15 minutes per invocation by default | Split the job, or use a workflow or container |
| Vendor dependence | Handler signatures, events and costs are provider-specific, and a platform API or price can change | Keep business logic in plain Python modules behind a thin handler |
| No shared state | Environments can be frozen, reused or replaced, and /tmp content may remain between runs | Store durable state in a database; treat /tmp as a cache |
| Function sprawl | Hundreds of functions can pile up with no map of what each does | Name, own and document every function; retire unused ones |
| Call overhead | Functions and microservices call each other over the network, never locally | Design coarse, well-defined interfaces |
If cold starts matter, the Lambda pricing page lists provisioned concurrency as a separately billed option, with no free tier applying to it. It also lists a free tier of one million requests and 400,000 GB-seconds per month, which suits a first prototype.
How do AI agents change serverless microservices in Python?
Python is the common language for agent tooling, so many functions become tools an agent calls. A function that once served a web page now sits inside a decision, which makes input validation, predictable errors and idempotent behaviour matter more. Give each tool function a narrow job and permissions, return structured responses, and log every call. ElixirClaw, the AI agents computing platform, is where XenonStack builds and runs agents that call such functions. For monitoring, see our use case on AIOps monitoring for Kubernetes and serverless.
What should you do first?
- Choose one small, stateless service and rebuild it as a function.
- Keep the handler thin and move logic into testable modules.
- Put configuration in environment variables and secrets in a managed store.
- Measure cold start and duration before tuning anything.
- Decide which functions agents may call and record their inputs and outputs.
To go further, read about the serverless framework Kubeless, the serverless computing guide and our serverless services and solutions.
To map one decision your agents make through a function, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is a serverless microservice in Python?
It is a small Python function packaged with its dependencies and run by a managed platform in response to an event, so the team does not manage servers.
How is a function different from a microservice?
A microservice is a separate service for one capability. A function breaks that service into smaller pieces that run when an event triggers them.
How do I deploy a Python function on AWS Lambda?
Save your .py files at the root of a directory, add dependencies, zip the contents, upload the archive and set the handler. Layers and container images are the other options listed in the Python on Lambda page.
What is a cold start?
A cold start is the time to download code and set up a new execution environment before your handler runs. The Lambda documentation says it typically occurs in under 1% of invocations.
When should I avoid serverless?
Avoid it for long-running work beyond the platform duration limit, or where you cannot accept dependence on one provider without isolating your business logic.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE