Key takeaway
- AI agents in DevOps triage builds, run canary releases and handle incidents within guardrails. See the architecture, approval gates and DORA metrics.
AI agents in DevOps are software agents that plan, run and check delivery work: they triage failing builds, propose fixes, drive canary releases, flip feature flags and handle the first steps of an incident. They act through the same pipelines, APIs and permissions as your engineers, inside guardrails you set, and they hand risky or irreversible changes to a human for approval.
For enterprise leaders, the point is not more automation for its own sake. It is shorter lead time and faster recovery without a higher change fail rate. That only happens when agents work on top of solid CI/CD, observability and progressive delivery, with clear approval gates and a measured blast radius.
What are AI agents in DevOps, and why do they matter now?
Classic DevOps automation follows fixed rules: a pipeline runs the steps you scripted, and an alert pages a person. An AI agent adds a reasoning loop. It reads context (logs, metrics, diffs, tickets, runbooks), decides on a next step, calls a tool, checks the result and either continues, rolls back or escalates. Predictive AI tells you something is likely to go wrong; an agent can also take a bounded action about it.
The timing matters because AI is already in most engineering teams. The 2025 DORA State of AI-assisted Software Development report found that about 90% of technology professionals now use AI at work, and it describes AI as an amplifier: it magnifies the strengths of well-run organisations and the dysfunctions of struggling ones. The same research links AI adoption to higher delivery throughput while delivery instability keeps rising. More code reaching production faster is exactly why release, rollback and incident work need agents with guardrails, not just faster coding assistants.
| Approach | What it does | Who acts | Typical example |
|---|---|---|---|
| Scripted automation | Runs fixed steps on a trigger | The pipeline | Build, test and deploy on merge |
| Predictive AI | Flags anomalies and forecasts risk | A human, after reading the signal | Alert that a deploy looks unusual |
| AI agent | Reasons over context, calls tools, checks results | The agent, within set permissions | Pauses a canary, collects evidence, opens a rollback request |
Where do AI agents fit across the delivery lifecycle?
Agents are most useful at hand-off points, where work waits for someone to read context and make a routine call. The table maps common jobs to what the agent does and what a human should keep.
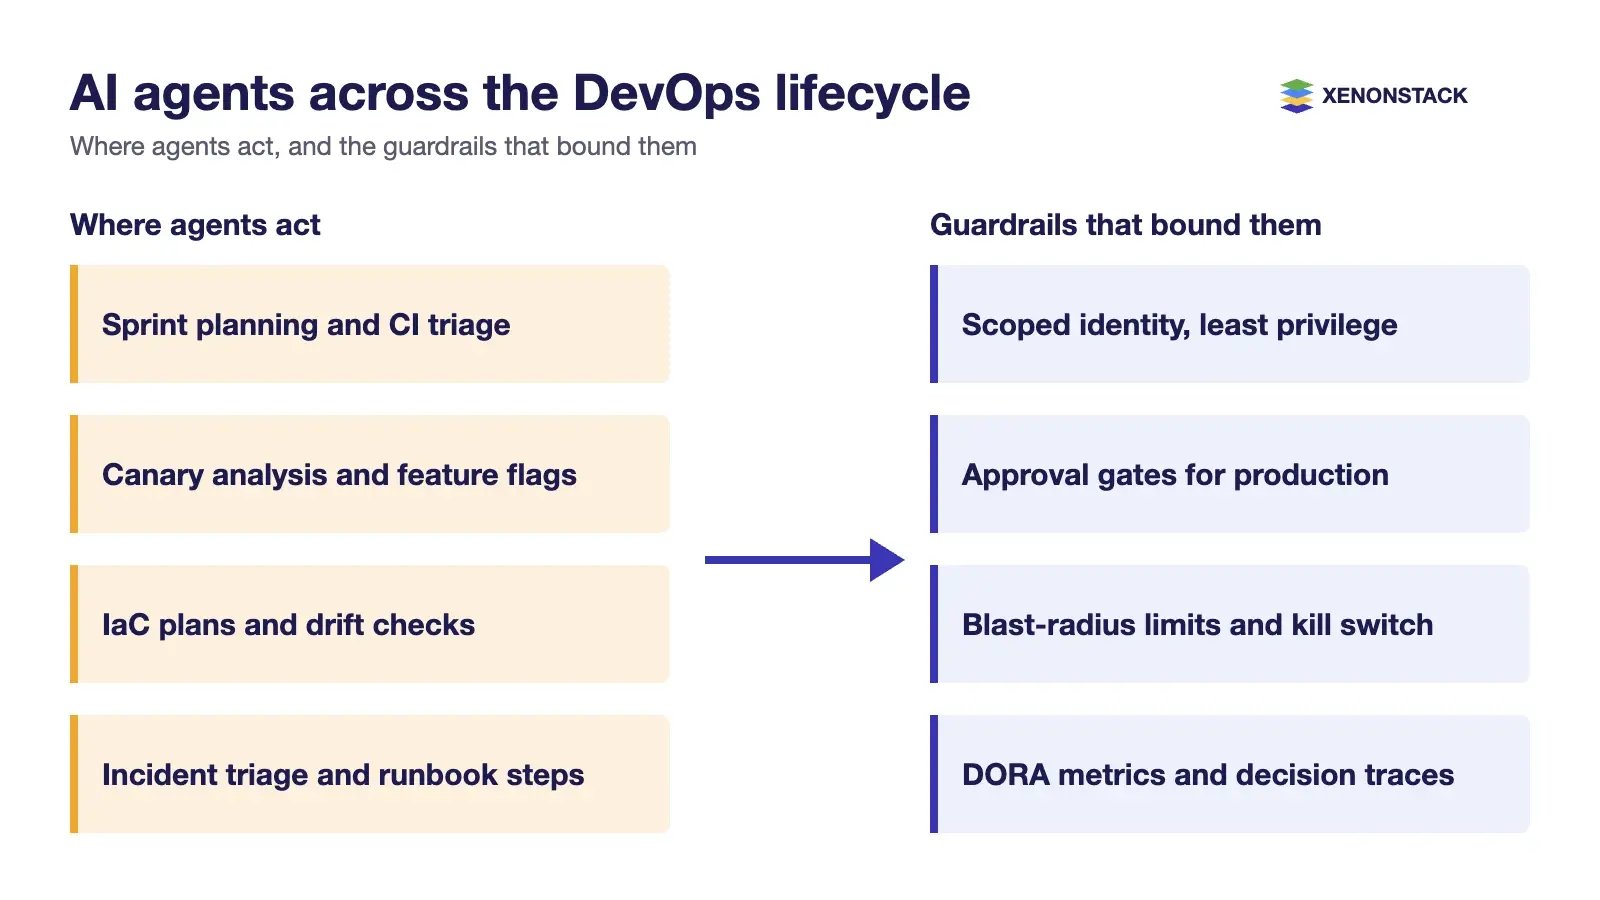
| Stage | What the agent does | What a human keeps | Signal to watch |
|---|---|---|---|
| Plan | Drafts sprint plans, groups tickets, flags blockers and carry-over | Priorities and scope | Planned vs delivered work |
| Code and review | Summarises diffs, checks tests and policy, suggests fixes | Merge approval on sensitive code | Review wait time, escaped defects |
| CI | Triages failing and flaky builds, reruns or quarantines tests, proposes the fix | Changes to the pipeline itself | Build success rate, queue time |
| Release | Runs canary steps, reads analysis, adjusts feature flags, pauses or rolls back | Go-live of high-risk changes | Change fail rate |
| Infrastructure | Generates and checks IaC plans, detects drift, opens pull requests | Apply on production and shared networks | Drift count, failed applies |
| Operate | Correlates alerts, gathers evidence, runs approved runbook steps, drafts the post-incident review | Customer communication and irreversible actions | Failed deployment recovery time |
For the planning end of the loop, Agent Scrum automates sprint planning and Scrum ceremonies with agentic AI, so delivery data and blockers reach the team before the stand-up rather than during it.
What does a reference architecture for DevOps agents look like?
A working setup has four layers. Keep them separate, so you can change a model or a tool without rewriting your controls.
1. Context layer
Telemetry (metrics, logs, traces), deployment history, change records, service ownership, SLOs, runbooks and past incidents. Agents are only as good as this layer. If a service has no owner or no SLO, the agent cannot make a sound call about it.
2. Agent and orchestration layer
One or more agents with narrow jobs (build triage, release, incident) and an orchestrator that routes work, holds state and records every step. Narrow agents are easier to test and to limit than one general agent with wide access.
3. Tool and action layer
The CI/CD system, GitOps controller, feature flag service, cloud APIs, ticketing and chat. Agents should act through these existing interfaces with their own scoped identities, so every action shows up in the same audit trail as a human change. Our guide to GitOps continuous delivery with Argo CD and Flux shows why a Git-based desired state makes agent changes reviewable and easy to revert.
4. Policy and governance layer
Rules for what each agent may do, on which environments, under what conditions, and who must approve. This layer also stores the reasoning and evidence behind each decision. ElixirData provides this as a decision layer above the agents, holding governed context, versioned policy and decision traces in one place.
Where does it break?
- Poor telemetry: missing traces or noisy alerts lead to confident but wrong actions.
- Shared credentials: an agent using a human admin token has an unlimited blast radius and no clean audit trail.
- Loops: two automations reacting to each other (for example an autoscaler and a remediation agent). Add rate limits and a stop switch.
- Unclear ownership: nobody is accountable for what the agent changed.
How do AI agents run progressive delivery safely?
Progressive delivery exposes a change to a small share of users, measures it, and widens exposure only when the numbers hold. It already contains the control points an agent needs.
- Canary analysis. Tools such as Argo Rollouts define success metrics in an analysis template; if the analysis fails, the controller aborts the rollout and returns canary traffic to zero. The agent's job is to choose sensible metrics, read results across services, explain why a step failed and open the follow-up, not to override the automatic abort.
- Feature flags. Flags separate deploy from release. OpenFeature, a CNCF incubating project, gives a vendor-neutral API for flag evaluation, which lets an agent work with more than one flag provider. Agents can ramp a flag, switch it off on error spikes, and flag stale flags for removal.
- Error budgets. The Google SRE example error budget policy freezes releases, except urgent fixes, once a service exceeds its budget. Encode the same rule as policy, so a release agent stops on its own when the budget is spent.
The choice between rollout patterns still matters. See canary vs blue-green deployment for when each one fits.
How do AI agents change incident response?
Most incident time goes on finding out what changed and who owns it. Agents shorten that part. On an alert, an incident agent can group related alerts, link them to the latest deploys and flag changes, pull the relevant dashboards and logs, suggest a likely cause with evidence, and run approved runbook steps such as a restart, scale-out or flag switch-off. A human incident commander still leads, owns customer communication and approves anything irreversible.
After the incident, the agent drafts the timeline and post-incident review from the recorded steps, which keeps learning honest because every action is already logged. AgentSRE applies agentic AI to incident management and observability for teams that cannot afford downtime. For the wider process, read our guide to incident management with AI agents.
Which guardrails keep DevOps agents safe?
The OWASP Top 10 for LLM Applications (LLM06:2025 Excessive Agency) names the root causes of harmful agent actions: too much functionality, too many permissions and too much autonomy. DevOps guardrails should target all three.
| Guardrail | What it limits | How to apply it |
|---|---|---|
| Scoped identity | Permissions | One identity per agent, least privilege per environment, short-lived credentials |
| Tiered actions | Autonomy | Read-only and reversible actions run alone; production writes need approval; destructive actions are blocked |
| Approval gates | Autonomy | Human approval in the pipeline or chat for high-risk tiers, with the agent's evidence attached |
| Blast-radius limits | Impact | Cap traffic share, number of services, regions or hosts per action; one change at a time |
| Policy as code | Functionality | Change windows, error budget state and compliance rules checked before every action |
| Kill switch and rate limits | Runaway loops | Stop all agent writes in one step; cap actions per hour |
| Decision trace | Audit gaps | Store input context, reasoning, action and outcome for each step |
Agent-written code and pipeline changes still fall under your secure development practice. The NIST Secure Software Development Framework (SP 800-218) is a useful baseline, and our guide to DevSecOps pipelines and governance covers the controls to keep in the pipeline.
When should you use an agent, a pipeline rule or a human?
| Choose | When | Example |
|---|---|---|
| Pipeline rule | The step is fully predictable and the right action never changes | Run unit tests on every commit |
| AI agent, autonomous | The task needs context reading, the action is reversible and the blast radius is small | Quarantine a flaky test and open a ticket |
| AI agent with approval gate | The agent can prepare the work, but the change touches production or customers | Promote a canary to 100% or apply an IaC plan |
| Human-led | The action is irreversible, novel or has legal, security or customer impact | Data migrations, security incidents, customer notices |
How do you measure impact with DORA metrics?
Use the DORA software delivery metrics as the scorecard, measured before and after each agent goes live. DORA now groups them into throughput and instability:
| Metric | Group | Agent that should move it |
|---|---|---|
| Change lead time | Throughput | Review, CI triage and release agents |
| Deployment frequency | Throughput | Release agents running smaller, safer steps |
| Failed deployment recovery time | Throughput | Incident and rollback agents |
| Change fail rate | Instability | Canary analysis and policy checks |
| Deployment rework rate | Instability | Test and review agents catching issues earlier |
Track throughput and instability together. If lead time falls but change fail rate rises, the agent is moving risk downstream, which is the pattern the 2025 DORA research warns about. Also track agent-level numbers: share of actions approved without edits, actions rolled back, and time saved per incident.
A practical adoption path
- Observe (weeks 1 to 4). Agents read and summarise only: build failures, release health, incident timelines. Fix telemetry and ownership gaps they expose.
- Recommend. Agents propose actions with evidence; humans approve every one. Measure how often the proposal was right.
- Act on low-risk tiers. Allow reversible actions in non-production and small-blast-radius production steps, with a kill switch.
- Expand by evidence. Widen autonomy only where DORA metrics and agent accuracy show it is safe.
When are AI agents not the answer?
- When CI/CD, tests and observability are weak. Agents amplify what is there; fix the foundations first.
- When a fixed rule does the job. A deterministic pipeline step is cheaper and easier to audit than an agent.
- When actions are irreversible or regulated, such as data deletion or security response that has legal impact. Keep a human in charge.
- When nobody owns the outcome. Every agent needs a named owner, a scope and a way to switch it off.
If you are starting with infrastructure work, our explainer on infrastructure as code tools and practices covers the base that IaC agents build on.
To map one decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What are AI agents in DevOps?
AI agents in DevOps are software agents that read delivery context, decide on a next step and act through CI/CD, feature flag, cloud and ticketing tools within set permissions. They triage builds, run canary steps, handle first incident steps and hand risky or irreversible changes to a human.
How are AI agents different from DevOps automation?
Scripted automation runs fixed steps on a trigger. An AI agent reasons over logs, metrics, diffs and runbooks, chooses an action, checks the result and then continues, rolls back or escalates.
Can AI agents deploy to production on their own?
They can for reversible, small-blast-radius steps when policy allows it. Promoting a canary to all users, applying production infrastructure changes or any irreversible action should go through an approval gate with the agent's evidence attached.
How do AI agents help with canary releases and feature flags?
Agents choose and read canary analysis metrics, explain failed steps, ramp or switch off feature flags on error spikes and stop releases when the error budget is spent. Automatic aborts in tools such as Argo Rollouts stay in place.
Which guardrails do DevOps agents need?
Scoped identities with least privilege, tiered actions, approval gates, blast-radius limits, policy as code, a kill switch with rate limits, and a decision trace for every step. These target the excessive functionality, permissions and autonomy that OWASP lists under Excessive Agency.
Which DORA metrics show whether AI agents are working?
Track change lead time, deployment frequency, failed deployment recovery time, change fail rate and deployment rework rate together. Faster lead time with a rising change fail rate means the agent is moving risk downstream.
Continuous Integration and Continuous Delivery (CI/CD)
Automates building, testing, and deployment to enable frequent updates and fast feedback
Collaboration and Communication
Fosters open communication among developers, operations, and all stakeholders for effective teamwork
Monitoring and Observability
Ensures continuous performance and infrastructure health checks to catch issues early
Infrastructure as Code (IaC)
Manages infrastructure via code for consistent configurations and automated setups
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE