Key takeaway
- Agentic AI for NLP explained for enterprise leaders: how agents differ from RAG and pipelines, where they fit, OWASP risks and a five-step adoption plan.
Agentic AI for NLP means putting a language model inside a loop that can plan, call tools, check its own output and act, instead of returning one answer to one prompt. For an enterprise it matters when a language task ends in a business action: resolving a ticket, completing a compliance check or routing a clinical summary. For a single classification or summarisation call, a plain model is usually cheaper and easier to govern.
This guide is for CTOs, CIOs, CDOs and solution architects deciding where agents belong in a language workflow. For the foundations, read our guides to natural language processing and large language models in AI agents. For library and cloud API choices, see NLP tools compared. Here we cover architecture, use cases, risks and an adoption sequence.
How is agentic AI for NLP different from a standard NLP pipeline?
A classic NLP pipeline runs fixed steps such as tokenisation, entity extraction and classification. An LLM call replaces many of those steps with one prompt. An agentic system adds a control loop around the model: it decides what to do next, retrieves evidence, calls tools, reviews the result and stops, retries or escalates.
| Approach | How it works | Best fit | Main limit |
|---|---|---|---|
| Fixed NLP pipeline | Predefined steps and trained models | High-volume, stable tasks such as classification or entity extraction | Does not adapt to new request types |
| Single LLM call | One prompt, one response | Summarisation, drafting, translation of a single document | No access to live data or actions; output unchecked |
| Retrieval-augmented generation (RAG) | Fetches documents, then generates an answer | Question answering over enterprise knowledge | Fixed retrieval path; weak on multi-step questions |
| Agentic NLP | Model plans, calls tools, checks results, then acts or escalates | Language tasks that end in an action or need several lookups | More model calls, more to test, more to govern |
What has changed in agentic NLP research?
Three primary sources explain how the field moved from text generation to action. The ReAct paper (Yao et al., submitted October 2022) has a model interleave reasoning steps with actions such as calling an external API, and reports fewer hallucinations on question answering and fact verification than chain-of-thought prompting alone. Toolformer (Schick et al., February 2023) showed a model learning when to call tools such as a search engine, a calculator or a translation system and how to use the results.
The agentic RAG survey (Singh et al., first submitted January 2025, latest revision April 2026) describes retrieval where agents reflect, plan and call tools, and lists evaluation, coordination, memory, efficiency and governance as open challenges. Those open challenges are where most enterprise effort now goes.
What does an agentic NLP system consist of?
| Component | Role in a language workflow | Design question |
|---|---|---|
| Language model | Understands the request, plans steps, drafts output | Which model per step, and what is the fallback? |
| Retrieval | Finds evidence in documents, tickets and knowledge bases | Is each answer traceable to a source? |
| Tools | Search, databases, ticketing, email, calculators | Which actions are read-only and which change records? |
| Memory | Keeps task state and conversation context | What is stored, for how long, and who can see it? |
| Validator | Checks format, grounding and policy before output is used | Which checks run in code rather than in the model? |
| Human approval | Signs off high-risk actions | Which actions always need a person? |
Platforms such as ElixirClaw describe themselves as an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control. For retrieval over unstructured knowledge, AgentSearch offers enterprise AI search and retrieval.
Where does agentic AI for NLP fit in the enterprise?
Fit depends on whether the language task ends in an action and whether the action can be checked. The table sets out common patterns and what should stay deterministic.
| Use case | What the agent does | Keep deterministic or human-approved |
|---|---|---|
| Customer service | Reads the message, looks up the account, drafts or sends a reply, escalates when unsure. See agentic AI in customer service. | Refunds, account changes, policy exceptions |
| Healthcare and life sciences | Summarises records and literature for practitioners. See agentic AI in healthcare. | Clinical decisions, patient-identifiable data handling |
| Banking and financial services | Reads transaction text and regulatory documents, assembles compliance evidence | Reporting submissions, final fraud decisions |
| Telecom and IT services | Reads tickets and logs, finds likely causes, routes to the right team. See intelligent ticket resolution. | Changes to production systems |
| Retail and e-commerce | Summarises reviews, tags sentiment, supports search and recommendations | Pricing and promotion changes |
| Recruitment | Parses resumes and drafts candidate communications | Shortlisting and rejection decisions |
Video: how one incoming message can start several governed workflows (ElixirClaw).
When should a language task stay a plain model or a single LLM call?
Choose the simpler option when the task has one input and one output, the categories are stable, nothing downstream acts on the result, or the cost of a wrong answer is low and a person reviews it anyway. A trained classifier or one summarisation call is faster to test, cheaper to run and easier to audit. Agents earn their cost only where a task needs several lookups, decisions or actions.
Agents also add cost and delay. Each plan, retrieval, tool call and check is another model or system call, so a task takes longer and costs more than a single prompt. Set a step limit, a time limit and a spending limit per task, and measure cost per resolved task rather than cost per call.
What governance and security controls does it need?
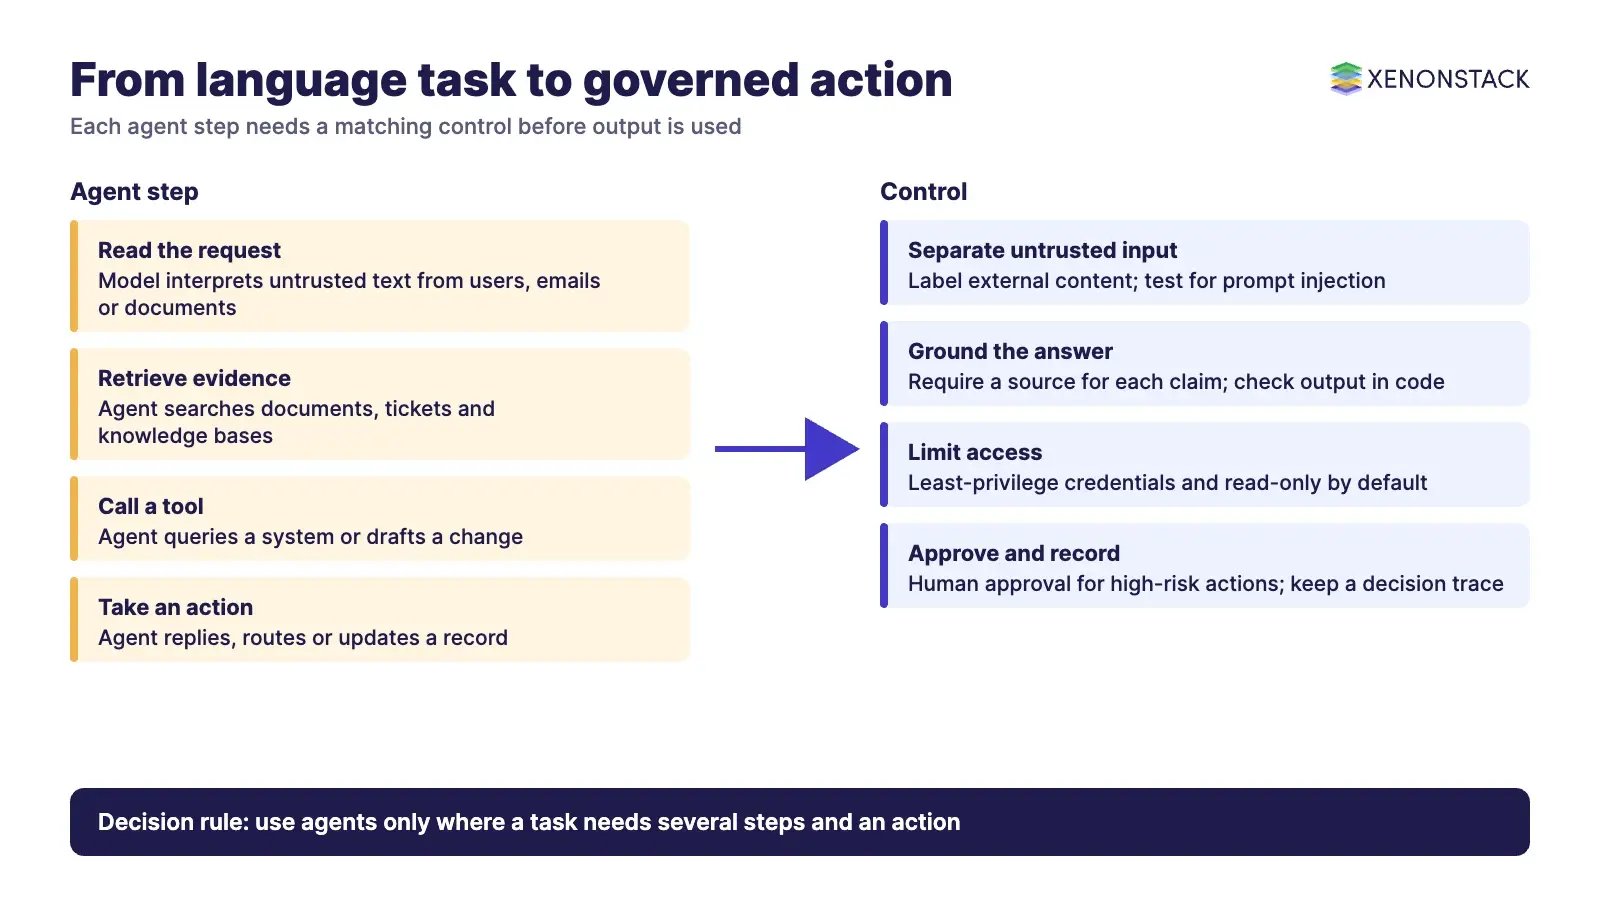
Agents read untrusted text and can act on it, so the language input is also an attack surface. OWASP lists prompt injection as LLM01, the top risk in its 2025 LLM Top 10, and says it cannot be fully prevented, only reduced. Its mitigations include limiting the model's role and scope, checking output formats in deterministic code, filtering inputs and outputs, giving the application its own minimum-privilege credentials, separating untrusted external content, requiring human approval for high-risk actions and running adversarial tests.
| Risk | Control |
|---|---|
| Prompt injection through documents, emails or web pages | Label and separate untrusted content; least-privilege tool access; adversarial testing |
| Sensitive data in prompts and logs | Redact before the model; set retention limits; keep an access log |
| Biased or ungrounded output | Require source citations; check output against retrieved evidence; sample for review |
| Actions taken outside policy | Policy checks before each action; human approval for high-risk steps |
| Cannot explain a past decision | Record the input, retrieved evidence, tool calls and approval for every task |
Where agent actions need policy checks and an audit trail, AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents. Check regional rules such as GDPR and sector rules such as HIPAA with your own legal and compliance teams before go-live.
How should an enterprise adopt agentic AI for NLP?
- Pick one workflow. Choose a language task with a clear end action and a measurable outcome, such as ticket routing.
- Baseline first. Measure today's accuracy, handling time and error rate with the current pipeline or people.
- Start read-only. Let the agent retrieve, summarise and recommend while a person acts.
- Add actions behind approvals. Enable low-risk actions first and keep human approval on high-risk ones.
- Evaluate continuously. Test grounding, injection resistance and cost per task on a fixed test set, and re-run it whenever the model, prompt or tools change.
What will change in agentic NLP next?
The agentic RAG survey names evaluation, coordination between agents, memory, efficiency and governance as open challenges. Expect enterprise teams to focus on three things: shared evaluation sets for agent tasks, tighter control of what agents remember, and decision records that regulators and auditors can read. We have not found a sourced forecast with dates, so we do not give one.
To map one language-driven decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Related on XenonStack
- RAG and LLM development services: grounded answers that cite their sources.
- ElixirClaw: run governed AI agents with decision boundaries and human approvals.
- Agentic AI vs AI agents vs automation: the key differences.
FAQ
What is agentic AI for NLP?
It is a language model placed inside a loop that can plan, retrieve evidence, call tools, check its output and act or escalate, rather than returning a single answer to one prompt.
How is it different from RAG?
RAG retrieves documents and then generates an answer along a fixed path. In agentic RAG, agents can reflect, plan and call tools, so retrieval adapts to the question, as the agentic RAG survey describes.
When should I not use agents for NLP?
Avoid them for stable, single-step tasks such as classification or one-document summarisation, or where nothing downstream acts on the result. A plain model is cheaper and easier to audit.
What is the biggest security risk?
Prompt injection. OWASP ranks it LLM01 in its 2025 LLM Top 10 and says it can be reduced but not fully prevented, so limit tool access and require approval for high-risk actions.
How do we start?
Pick one workflow with a clear end action, baseline current performance, run the agent read-only, then add low-risk actions behind human approval and test continuously.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.