Key takeaway
- Agentic graph systems let AI agents reason over a shared knowledge graph. Learn the architecture, GraphRAG vs vector RAG, governance and adoption.
An agentic graph system is an AI architecture in which autonomous agents use a knowledge graph as shared context and memory, and a task graph to plan and coordinate their work. The knowledge graph holds entities, relationships and their sources, so agents can reason across connected facts rather than isolated text chunks. The task graph breaks a request into dependent steps, so independent steps run in parallel and every step can be traced.
For enterprise leaders, the case is practical. Vector search answers "find me the passage about X" well, but it struggles with questions that span many documents or many hops, such as "which suppliers share a sub-contractor with a supplier that failed an audit?". Graph-based retrieval, popularised by Microsoft Research's GraphRAG, targets exactly those questions. The trade-off is cost and effort to build and govern the graph. This guide covers the architecture, GraphRAG versus vector RAG, governance and how to adopt it.
What is an agentic graph system?
An agentic graph system combines two kinds of graph with a set of AI agents.
- A knowledge graph (what the agents know). Nodes are business entities such as customers, products, contracts, assets or policies. Edges are typed relationships such as "supplies", "owns" or "is governed by". Nodes and edges carry properties and a pointer back to the source they came from.
- A task graph (how the agents work). A user request is decomposed into sub-tasks (nodes) and dependencies (edges), usually as a directed acyclic graph (DAG). Tasks with no dependency between them run concurrently, which shortens the critical path.
- Agents (who does the work). An orchestrator builds the task graph, a delegator assigns each task to the agent or tool best suited to it, and an executor runs the tasks in dependency order and collects results.
The point of the design is that agents do not each carry a private, partial view of the business. They read from and write to one connected model of it, and their own plans are explicit graphs that can be inspected, replayed and audited.
Why do agentic graph systems matter to enterprises now?
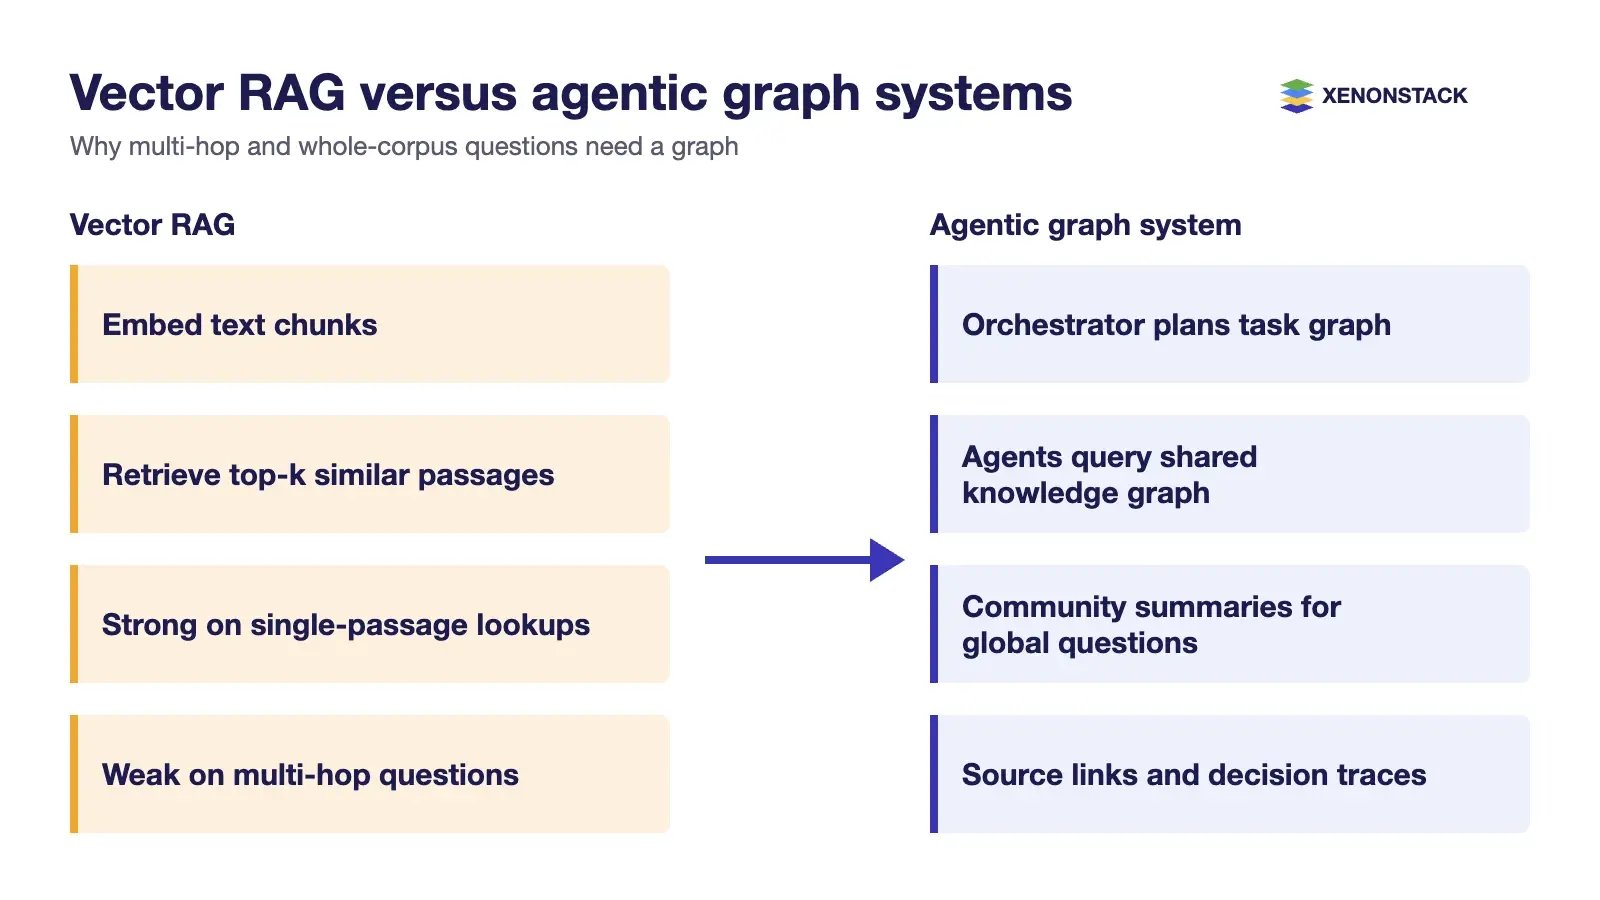
Most enterprise AI pilots began with retrieval-augmented generation (RAG) over a vector index. That works for questions whose answer sits in one or two passages. It breaks down in three common situations.
- Multi-hop questions. The answer depends on following relationships across records, for example from a customer to their contracts, to the products on those contracts, to the open incidents on those products.
- Whole-corpus questions. Questions such as "what are the main risk themes across all audit reports?" need a summary of the whole collection, not the top few matching chunks.
- Agents that act. Once an agent approves, routes or changes something, leaders need to know which facts and which policy it relied on. A graph with source links gives that lineage; a list of similar text chunks does not.
Graph standards have also matured. ISO published GQL (ISO/IEC 39075:2024), the first international standard query language for property graph databases, in 2024 (ISO/IEC JTC 1). That reduces lock-in to a single vendor's query dialect, alongside the long-standing W3C RDF and SPARQL stack.
How does the architecture of an agentic graph system work?
A production system usually has five layers. Each one has its own integration points and its own ways to fail.
| Layer | What it does | Integration points | Where it breaks |
|---|---|---|---|
| Knowledge graph | Holds entities, relationships, properties and source links; may be built from structured systems, extracted from documents by an LLM, or both | ERP, CRM, data catalogue, document stores, graph database (RDF or property graph) | Duplicate or wrongly merged entities, stale edges, extraction errors that look like facts |
| Retrieval | Answers agent questions with graph traversal, community summaries, vector search or a mix | Graph query (GQL, Cypher, SPARQL), vector index, GraphRAG-style indexes | Wrong query mode for the question, traversals that explode in size, summaries that drift from sources |
| Agents and orchestration | Orchestrator plans a task DAG, delegator assigns tasks, executor runs them in parallel where dependencies allow | LLMs, agent frameworks, workflow engines | Over-decomposed plans, loops, one failed task blocking the critical path |
| Tools and integration | Lets agents read and write business systems and update the graph with results | APIs, event streams, tool protocols such as MCP | Over-broad credentials, unsafe tool chains, writes that bypass validation |
| Governance | Applies access policy, records decision traces, routes high-risk actions to people | Identity provider, policy engine, audit store, evaluation pipeline | Policy checked only at the prompt, no trace from answer back to sources |
The main design trade-off is where to spend effort. A graph built from well-modelled structured systems is accurate but slow to extend. A graph extracted from documents by an LLM is fast to build but needs evaluation, because extraction mistakes become "facts" that every agent then trusts. Most enterprises end up with a hybrid: a curated core ontology for critical entities, plus extracted relationships that are labelled with their source and confidence. For a deeper look at combining the two, see our guide to building knowledge graphs with large language models, and how graph databases store and query connected data.
How do the agents coordinate?
Coordination happens in two places. In the task graph, the orchestrator makes dependencies explicit, so agents do not wait on each other unnecessarily and do not act on results that are not ready. In the knowledge graph, agents share state: one agent writes a finding with its source, and the next agent reads it rather than re-deriving it. This is where agent platforms such as ElixirClaw, an agentic OS platform to build, orchestrate, and govern AI agents and automation workflows, sit. Our article on multi-agent coordination covers the patterns in more detail.
What is GraphRAG and how is it different from vector RAG?
GraphRAG is a retrieval approach from Microsoft Research, described in the paper From Local to Global: A Graph RAG Approach to Query-Focused Summarization (Edge et al., 2024, arXiv:2404.16130). The authors point out that standard RAG handles questions about specific content well but fails on global questions about a whole corpus. GraphRAG uses an LLM to build an index in two stages: it extracts an entity knowledge graph from the documents, then pre-generates summaries for communities of closely related entities. At query time, each relevant community summary produces a partial answer, and those are combined into a final answer. On global sensemaking questions over datasets of around one million tokens, the paper reports substantial gains over a conventional RAG baseline in the comprehensiveness and diversity of answers.
The open-source GraphRAG documentation describes the indexing pipeline: chunk text into units, extract entities, relationships and claims, cluster the graph hierarchically with the Leiden algorithm, and write community reports. It offers four query modes: global search for whole-corpus questions, local search for questions about specific entities, DRIFT search that adds community context to local search, and basic top-k vector search. The documentation also warns that using it out of the box may not give the best results and recommends prompt tuning for your data.
| Aspect | Vector RAG | GraphRAG (full) | Lighter graph variants |
|---|---|---|---|
| Index | Embeddings of text chunks | LLM-extracted entity graph plus community summaries | Concept graph from NLP extraction and graph statistics |
| Best at | Specific, single-passage questions | Whole-corpus themes and multi-hop questions | Mixed workloads where indexing cost matters |
| Indexing cost | Low | High, because an LLM reads the whole corpus | Microsoft reports LazyGraphRAG indexing at the cost of vector RAG and 0.1% of full GraphRAG |
| Query cost | Low | Higher for global search | Shifts LLM cost to query time |
| Explainability | Shows matching chunks | Shows entities, relationships and the summaries used | Shows concepts and source chunks |
The lighter variant in the table is LazyGraphRAG, which Microsoft Research announced in November 2024. It builds its graph with noun-phrase extraction instead of LLM summarisation and defers LLM use until query time (Microsoft Research). In an agentic graph system, these retrieval methods are tools. An agent can choose local graph search for an entity question, global search for a themes question and plain vector search for a lookup, instead of forcing one method on every request. We explain the wider shift in why RAG alone is not enough for enterprise AI.
When should you choose a graph approach over vector RAG?
| Choose | When |
|---|---|
| Vector RAG only | Questions are answered by one or two passages, content changes often, and you need a working assistant quickly |
| GraphRAG-style retrieval | Users ask about themes across a large collection, or answers need relationships that are spread across many documents |
| Curated knowledge graph plus agents | Agents take actions on core entities (customers, assets, contracts) and you need precise, auditable relationships |
| Hybrid (graph plus vector) | You have both structured systems of record and large unstructured content, which is the case in most enterprises |
| Task graph without a knowledge graph | The challenge is coordinating many steps and tools, not reasoning over connected data |
A useful test is to write down ten real questions your users or agents must answer. If most need more than one hop or a corpus-wide view, a graph will pay back its cost. If most are lookups, start with vector RAG and add a graph later for the questions it cannot answer. Our agentic graph systems use cases article gives industry examples.
How do you govern an agentic graph system?
A shared knowledge graph makes agents more capable, and it also concentrates risk. If bad data enters the graph, every agent that reads it is affected. The OWASP Top 10 for Agentic Applications for 2026, released in December 2025, lists the risks that matter most here, including memory and context poisoning, tool misuse, identity and privilege abuse, insecure inter-agent communication and cascading failures (OWASP GenAI Security Project).
- Provenance on every edge. Record the source, extraction method, time and confidence of each relationship. Let agents prefer curated edges over extracted ones for high-impact decisions.
- Controlled writes. Treat graph writes by agents as changes that need validation, not as free memory. This is the main defence against context poisoning.
- Access policy at node and edge level. An agent acting for a user should only traverse what that user may see. Filtering only the final answer is too late, because restricted facts may already have shaped it.
- Scoped agent identity. Give each agent its own short-lived credentials and the narrowest tool permissions it needs.
- Decision traces. For each action, keep the task graph, the graph queries, the facts returned, the policy version applied and any human approval. This is what auditors and regulators will ask for.
ElixirData provides this as a decision layer above the agents, with governed context, versioned policy and decision traces in one place. For compliance workflows specifically, AgentGRC applies the same approach to governance, risk and compliance. See also our guide to agentic AI governance and compliance.
How should enterprises adopt agentic graph systems, and what should they measure?
- Pick one decision. Choose a decision with clear business value and a known owner, for example supplier risk review or incident triage.
- Model only what that decision needs. Define the core entities and relationships, connect the systems of record, and extract the rest from documents with source links.
- Build the evaluation set first. Collect real questions with expected answers and sources before building retrieval.
- Add agents and a task graph. Start read-only. Allow actions only once accuracy and traces meet the bar the decision owner sets.
- Extend the graph by reuse. The second use case should reuse entities from the first. If it does not, the graph is becoming a set of silos.
| Metric | What it tells you |
|---|---|
| Answer accuracy and groundedness on the evaluation set | Whether retrieval and reasoning are correct and backed by sources |
| Multi-hop and whole-corpus question success rate | Whether the graph adds value over vector RAG |
| Graph quality (duplicate entities, stale edges, extraction precision) | Whether agents are reasoning over trustworthy data |
| End-to-end latency and critical path length | Whether the task graph is actually running work in parallel |
| Cost per task (indexing plus query) | Whether the chosen retrieval mode is economical |
| Share of actions with a complete decision trace | Audit readiness |
| Human override rate | Where agents still need guidance or better context |
When is an agentic graph system not the answer?
- Simple lookups. If questions are answered by single passages, vector RAG or plain search is cheaper and easier to run.
- Fast-changing, unstructured content with no stable entities. Re-extracting a graph from content that changes daily can cost more than it returns.
- No data ownership. A knowledge graph needs owners for its core entities. Without them it decays, and agents act on stale facts.
- Deterministic processes. Where the steps are fixed and rules are clear, a conventional workflow engine is more predictable than agents planning a task graph.
- No evaluation capacity. If you cannot measure answer quality, you cannot tell whether the graph is helping or hiding errors.
To map one decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is an agentic graph system?
An agentic graph system is an AI architecture in which autonomous agents use a knowledge graph as shared context and memory, and a task graph to plan and coordinate their work. The knowledge graph holds entities, relationships and sources; the task graph breaks a request into dependent steps that can run in parallel.
Why do AI agents need a knowledge graph?
A knowledge graph gives agents one connected model of the business, so they can follow relationships across records, share findings with each other and trace each answer back to its sources. Vector search alone returns similar text chunks without those relationships.
What is the difference between GraphRAG and vector RAG?
Vector RAG retrieves text chunks that are similar to the question. GraphRAG, from Microsoft Research, uses an LLM to extract an entity knowledge graph and pre-generate community summaries, which helps with multi-hop and whole-corpus questions. GraphRAG costs more to index.
Is GraphRAG expensive to run?
Full GraphRAG indexing is costly because an LLM reads the whole corpus to extract entities and write summaries. Microsoft Research reports that its LazyGraphRAG variant indexes at the same cost as vector RAG and 0.1% of full GraphRAG, by deferring LLM use to query time.
What are the main layers of an agentic graph system?
A production system usually has five layers: the knowledge graph, retrieval, agents and orchestration, tools and integration, and governance. Each layer has its own integration points and failure modes.
How do you govern an agentic graph system?
Record provenance on every edge, validate agent writes to the graph, enforce access policy at node and edge level, give each agent scoped credentials and keep a decision trace for every action. The OWASP Top 10 for Agentic Applications lists memory and context poisoning and tool misuse among the key risks.
When should we not use an agentic graph system?
Avoid it for simple lookups, fast-changing content with no stable entities, data with no clear owners, fixed deterministic processes, or when you cannot evaluate answer quality. In those cases vector RAG, search or a workflow engine is simpler.
Task Orchestration
The Integration Layer controls the activity of the agents and the tools, meaning that it has to manage the execution of certain tasks based on previously defined task dependencies.
Memory Management
According to their information, agents depend on memory to keep context across exchanges. The Integration Layer oversees the Short-Term Memory (current context) and the Long-Term Memory.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE