Key takeaway
- Kubernetes operators explained for platform leads: the control loop, Operator SDK, OLM, Kubeflow training operators, governance and when not to build one.
A Kubernetes operator is a custom controller paired with a custom resource that encodes how one application should be installed, upgraded, backed up and repaired. Kubernetes describes operators as "software extensions to Kubernetes that make use of custom resources to manage applications and their components", following the control loop principle. For a platform lead, the question is which stateful or complex services deserve an operator and who owns it afterwards.
This guide covers how the pattern works, what the Operator Framework (Operator SDK, Operator Lifecycle Manager and Operator Metering) offers today, and how operators run machine learning training through Kubeflow. It builds on our guides to Kubernetes architecture and components and DevOps for machine learning.
What is a Kubernetes operator?
The operator pattern aims "to capture the key aim of a human operator who is managing a service or set of services", in the words of the Kubernetes documentation. A human operator knows how a system should behave, how to deploy it and how to react to problems. An operator moves that knowledge into code that runs inside the cluster.
Two parts make it work. A custom resource is a new object type added to the Kubernetes API, so a team can declare a database or a message broker the way it declares a Deployment. A controller watches those objects, compares the actual state with the declared state and acts to close the gap. That loop is the same one Kubernetes uses for its own built-in controllers, which is why the pattern fits the platform so naturally.
Why do stateful applications need operators?
Deploying a stateless service is easy. A database or a multi-node cluster with primary and replica roles is harder, because adding or removing an instance needs preparation and follow-up steps, and later changes such as resizing, reconfiguration, backup, healing or a security patch each need care. Done by hand, that work falls on the DevOps team and does not scale across many clusters. An operator automates these steps for one application and applies them the same way every time. Our guide to PostgreSQL deployment in Kubernetes shows the kind of workload where this matters.
| Approach | What it does | When it fits |
|---|---|---|
| Deployment or StatefulSet only | Runs pods and keeps them available | Simple services with no application-specific lifecycle |
| Package manager templates | Installs a set of manifests with chosen values | One-time installs where day-two work is handled elsewhere |
| Operator | Runs a continuous control loop on a custom resource for one application | Complex or stateful services with upgrade, backup and recovery logic |
What is the Operator Framework?
The Operator Framework is an open source toolkit for building and managing operators. Its parts have different status today, so check each before you plan around it.
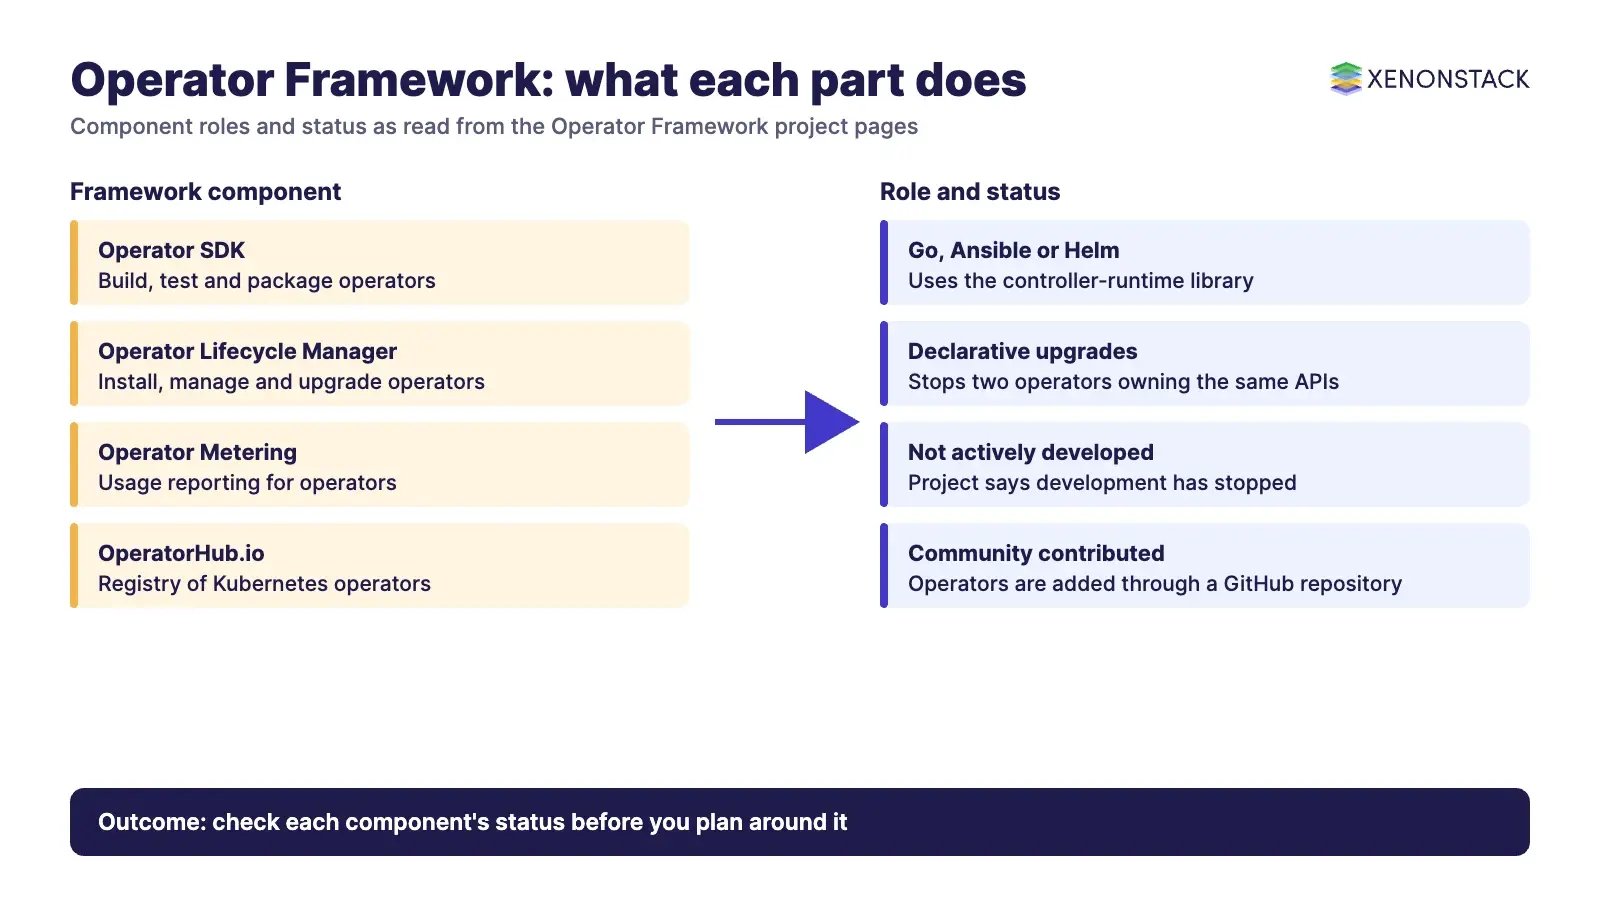
| Component | What it does | Current status (read 12 Nov 2026) |
|---|---|---|
| Operator SDK | Tools to build, test and package operators in Go, Ansible or Helm | Maintained, with releases listed up to v1.42; uses the controller-runtime library |
| Operator Lifecycle Manager | Declarative install, management and upgrade of operators; prevents two operators owning the same APIs | Open source project with several release branches |
| Operator Metering | Usage reporting for operators that provide services | The project states it is no longer under active development |
| OperatorHub.io | A registry for Kubernetes operators | Live; operators are contributed through a community GitHub repository |
How do you build an operator?
The Operator SDK lets developers build operators from their application knowledge without mastering every detail of the Kubernetes API. The Kubebuilder book is the other common starting point for teams that want to build their own Kubernetes APIs. Pick Go when the logic is complex, and Ansible or Helm when you mainly need to wrap existing automation.
How do operators run machine learning training?
Training a model needs resource management, monitoring and the ability to repeat a run on different infrastructure. Containers and Kubernetes give ML teams that, and operators add a job-level abstraction on top. The Kubeflow project packages operators for this. The older pattern was one operator per framework: a TensorFlow operator (tf-operator) with a TFJob resource, where a training job is split into roles such as parameter servers and workers, and the mpi-operator, which runs allreduce-style distributed training through an MPIJob resource (the repository shows kubeflow.org/v2beta1).
The project has moved on. Kubeflow Trainer is now described as a Kubernetes-native distributed AI platform for large language model fine-tuning, with TrainJob and runtime APIs, support for PyTorch, JAX, XGBoost, DeepSpeed and other frameworks, and MPI-style multi-node, multi-GPU orchestration. Its documentation keeps a migration guide and legacy documentation for teams still on Kubeflow Training Operator v1. If you inherited TFJob manifests from older guides, plan that migration rather than copying them forward. For the wider pipeline context, see DevOps for machine learning.
What should leaders govern before adopting operators?
An operator is software with broad rights in your cluster, so treat it like any privileged workload.
- Privilege. Review the permissions each operator requests, and scope them to the namespaces it manages. Our Kubernetes security automation guide covers policy checks you can apply to this.
- Ownership. Name a team accountable for each operator's upgrades and for the custom resource definitions it installs.
- Maintenance health. Check release activity before you depend on a community operator. Operator Metering shows how a framework component can stop being actively developed.
- Observability. Track reconcile errors and the health of the managed application with the tools in our cloud native observability guide.
- Audit. Operators change production state automatically, so keep an evidence trail of what changed and under which policy. Audit Agent from ElixirData produces audit trails and compliance evidence for decisions made through its Context OS.
Automate Workloads with Kubernetes Operators
Kubernetes has made it simple to deploy and scale services, and operators extend that to stateful applications, so teams spend less time on routine lifecycle work and more on the models and products that run on top.
When should you not write an operator?
Operators carry a build and maintenance cost. Skip a custom operator when a plain Deployment covers the need, when a maintained community operator already exists for the application, or when no team can own the code through Kubernetes version upgrades. The current stable release is Kubernetes 1.37, with patch 1.37.1 published on 15 September 2026 on the Kubernetes releases page, so API compatibility is a recurring task.
How should you adopt operators in sequence?
- Start with a maintained operator from a registry such as OperatorHub.io for one non-critical stateful service.
- Define ownership, permissions, monitoring and upgrade rules for it.
- Add Operator Lifecycle Manager once you run several operators and need controlled upgrades.
- Write a custom operator only for a service where the lifecycle logic is specific to your business.
- Where agents will act on clusters, run them through a governed platform such as ElixirClaw, an enterprise platform for building, coordinating and governing AI agents with policies and audit trails.
For deployment practice, read Kubernetes deployment tools and best practices, or talk to us about Kubernetes consulting services.
To map one Kubernetes operations decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
FAQ
What is a Kubernetes operator?
It is a custom controller that uses custom resources to manage an application and its components, following the Kubernetes control loop.
What is the difference between an operator and a controller?
Controllers reconcile actual state with desired state. An operator is a controller that carries application-specific operational knowledge, such as how to upgrade or back up one database.
What does the Operator SDK support?
Operator SDK provides tools to build, test and package operators in Go, Ansible or Helm, and uses the controller-runtime library.
Is Operator Metering still maintained?
Its repository states that it is no longer under active development, so do not plan new usage reporting around it.
Should I still use tf-operator for training jobs?
Check Kubeflow Trainer first. Its documentation points Training Operator v1 users to a migration guide and describes TrainJob APIs for current training workloads.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE