Key takeaway
- Deploy PostgreSQL on Kubernetes with a StatefulSet, Secrets and storage, and learn when to move to an operator such as CloudNativePG for failover.
Running PostgreSQL on Kubernetes is a decision about operations, not just packaging. A single pod with a volume is enough to learn on. Production needs a stable identity, durable storage, replication, backups and a tested failover path, and the choice is between building those yourself with a StatefulSet or using a PostgreSQL operator such as CloudNativePG.
This guide shows the minimal manifest pattern, explains what it does not give you, and sets out when to move to an operator. For the wider cluster picture, see our guides to Kubernetes architecture components and Kubernetes deployment tools and practices.
Should you run PostgreSQL on Kubernetes at all?
Kubernetes suits PostgreSQL when your platform team already runs stateful workloads, has a storage class with reliable persistent volumes, and wants one deployment model for applications and data. It suits less well when nobody owns backup, restore and failover testing. A managed database service removes that burden; a self-run database moves it onto your team.
PostgreSQL itself is open source and, according to its about page, has been ACID-compliant since 2001, supports write-ahead logging, asynchronous, synchronous and logical replication, and point-in-time recovery. Those are features of the database; Kubernetes does not add them. It schedules the pods and attaches storage.
Which PostgreSQL version should you deploy?
Deploy a supported major version. According to the PostgreSQL versioning policy, a major version is supported for 5 years after its first release, and each version receives minor releases at least once every three months. The page, read on 13 November 2026, lists these versions:
| Major version | First release | Final release | Status when read |
|---|---|---|---|
| 18 | 25 September 2025 | 14 November 2030 | Supported |
| 17 | 26 September 2024 | 8 November 2029 | Supported |
| 16 | 14 September 2023 | 9 November 2028 | Supported |
| 15 | 13 October 2022 | 11 November 2027 | Supported |
| 14 | 30 September 2021 | 12 November 2026 | Final release date reached; plan the upgrade |
| 9.6 (older release) | 29 September 2016 | 11 November 2021 | Unsupported |
Older releases such as 9.6 are out of support, so new deployments should use a current major version. The project recommends running the current minor release of whichever major version you choose.
How do you deploy PostgreSQL with a StatefulSet?
A StatefulSet runs a group of pods and, according to the Kubernetes documentation, maintains a sticky identity for each pod, which suits applications that need persistent storage or a stable, unique network identity. That is why a database belongs in a StatefulSet rather than a plain Deployment. Confirm the details of headless Services and volume claim templates on that page for your Kubernetes version.
Step 1. Use the official image
Instead of building your own image from a base operating system, start from the official postgres image on Docker Hub. According to its page, POSTGRES_PASSWORD is required, POSTGRES_USER is optional and defaults to postgres, and PGDATA became version specific from PostgreSQL 18. For version 17 and below the page says to mount the data volume at /var/lib/postgresql/data; from 18 the declared volume is /var/lib/postgresql. Check the tag page for the exact tag you pin.
Step 2. Keep the password in a Secret
Do not put the superuser password in the manifest. Create a Secret and reference it from the pod.
kubectl create secret generic postgres-credentials \
  --namespace production \
  --from-literal=POSTGRES_PASSWORD="$(openssl rand -base64 24)"
Step 3. Create a headless Service and a StatefulSet
The manifest below is an illustrative single-instance pattern for PostgreSQL 18. Replace the storage class and size for your cluster. It uses the stable apps/v1 API; older beta workload APIs such as extensions/v1beta1 are no longer current (confirm on the Kubernetes deprecation guide).
apiVersion: v1
kind: Service
metadata:
  name: postgres
  namespace: production
spec:
  clusterIP: None
  selector:
    app: postgres
  ports:
    - port: 5432
---
apiVersion: apps/v1
kind: StatefulSet
metadata:
  name: postgres
  namespace: production
spec:
  serviceName: postgres
  replicas: 1
  selector:
    matchLabels:
      app: postgres
  template:
    metadata:
      labels:
        app: postgres
    spec:
      containers:
        - name: postgres
          image: postgres:18
          ports:
            - containerPort: 5432
          envFrom:
            - secretRef:
                name: postgres-credentials
          volumeMounts:
            - name: data
              mountPath: /var/lib/postgresql
  volumeClaimTemplates:
    - metadata:
        name: data
      spec:
        accessModes: ["ReadWriteOnce"]
        storageClassName: YOUR_STORAGE_CLASS
        resources:
          requests:
            storage: 20Gi
Step 4. Apply and check
kubectl apply -f postgres.yaml
kubectl -n production get pods -l app=postgres
kubectl -n production exec -it postgres-0 -- psql -U postgres -c "select version();"
Keep the database off public addresses. Avoid a NodePort and avoid allowing connections from 0.0.0.0/0; a ClusterIP or headless Service plus a NetworkPolicy limits access to the applications that need it.
What does a StatefulSet not give you?
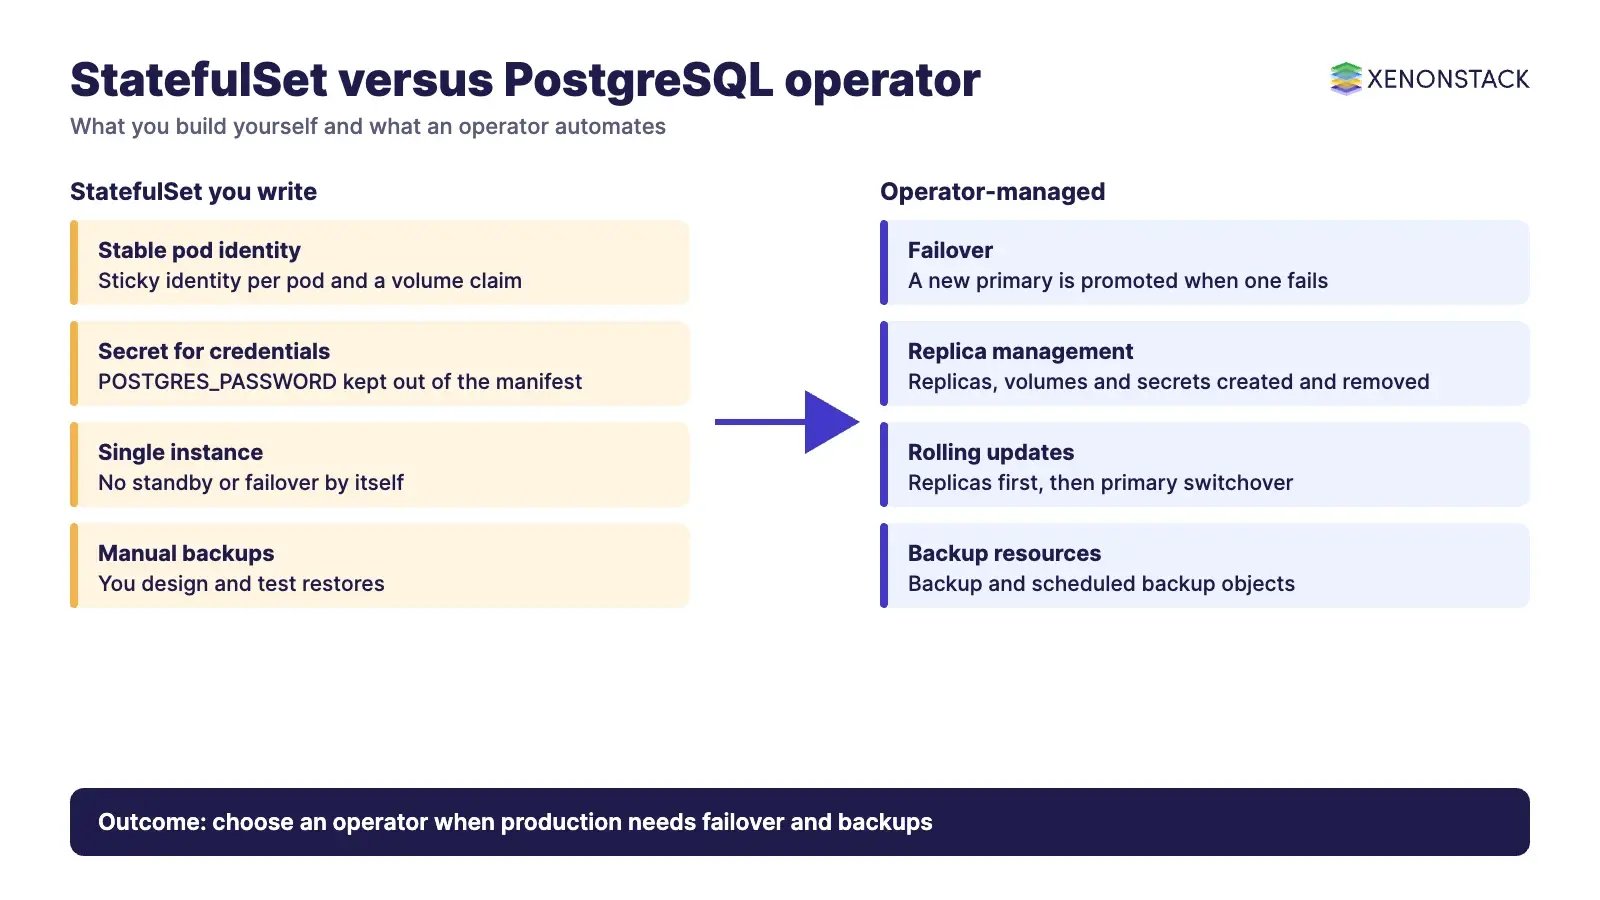
A single StatefulSet replica is one database server. It restarts and reattaches its volume, but it has no standby, no automated failover and no backup schedule. PostgreSQL provides the replication building blocks: according to its high availability documentation, a standby that cannot accept connections until promoted is a warm standby, and one that serves read-only queries is a hot standby, and synchronous and asynchronous replication trade data-loss risk against performance. Wiring these together on Kubernetes, and promoting a standby safely, is the work an operator automates.
For a replicated example of a stateful application on Kubernetes, the Kubernetes tutorial on a replicated MySQL StatefulSet shows the pattern, with the note that it is not a production configuration.
When should you use a PostgreSQL operator?
An operator adds a custom resource and a controller that manage the database lifecycle. According to the CloudNativePG project page, CloudNativePG is an open-source operator for PostgreSQL on Kubernetes, a CNCF Incubating project, dedicated to vanilla Kubernetes and vanilla PostgreSQL. It promotes a new primary when the current one fails, creates and removes replicas with their volumes and secrets, keeps service endpoints current, and runs rolling updates by updating replicas first and then switching over the primary. It also manages backup, scheduled backup and pooler resources. For the pattern behind this, see our guide to Kubernetes operators.
| Option | Fits when | What you own | Current status |
|---|---|---|---|
| Managed database service | You want the least operational work | Schema, queries and access | Vendor service; confirm features on the vendor page |
| StatefulSet you write | Development, tests, single non-critical instance | Backups, failover, upgrades, monitoring | Plain Kubernetes; no HA by itself |
| PostgreSQL operator (for example CloudNativePG) | Production on Kubernetes with a platform team | Storage class, backup target, restore drills, policy | CNCF Incubating project; confirm release and support on its site |
How do blue-green deployments apply to a database?
A blue-green strategy uses two environments, one live, the other receiving the new release, with a switch after verification. This works well for stateless application pods. For a database the hard part is the data. Both environments need compatible schemas, so teams usually make schema changes backward compatible first, deploy the application change next, and remove old columns later. For major PostgreSQL upgrades, test the upgrade and a restore on a copy before switching traffic.
What should you check before going to production?
- Restore a backup into a clean namespace and time it. A backup you have not restored is an assumption.
- Pin the image tag to a supported major and minor version and plan upgrades before the final release date of your version.
- Store credentials in Secrets or an external secret manager, and rotate them.
- Restrict network access with NetworkPolicy and enable TLS between applications and the database.
- Set resource requests and limits, and alert on replication lag, disk use and failed backups.
- Test a primary failure on purpose, in a non-production cluster, and record what happens to open connections.
How does governed context help with database operations?
Database changes made by people and by AI agents need the same controls: who may change a schema, which policy applied, and what trace remains. ElixirData keeps governed context, versioned policy and decision traces in one decision layer above AI agents. If teams use plain-language access to data, AgentAnalyst lets teams ask questions of enterprise data in plain language and get real-time insights. For database choice before deployment, read SQL vs NoSQL vs NewSQL.
To map one database decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
Can you run PostgreSQL in Kubernetes?
Yes. A StatefulSet with persistent volumes runs a single instance, and an operator such as CloudNativePG adds failover, replicas and backups. Whether it is the right choice depends on who owns backup, restore and upgrades.
Should PostgreSQL use a Deployment or a StatefulSet?
A StatefulSet, because according to the Kubernetes documentation it maintains a sticky identity for each pod, which suits applications needing persistent storage or a stable network identity.
Which PostgreSQL version should I deploy?
A supported major version. The PostgreSQL project supports each major version for 5 years after first release; versions 14 to 18 were listed as supported when read on 13 November 2026, and 9.6 is unsupported.
Does a StatefulSet give me high availability?
No. One replica has no standby or automated failover. PostgreSQL replication or an operator provides those.
What does CloudNativePG do?
According to its project page it is an open-source Kubernetes operator that handles failover, replica scaling, rolling updates, service endpoints and backup resources for PostgreSQL.
Where should the database password be stored?
In a Kubernetes Secret or an external secret manager, not in the manifest. The official image requires POSTGRES_PASSWORD to be set.
Related reading: Kubernetes architecture and components, Kubernetes consulting services and Kubernetes deployment.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE