Key takeaway
- DataGovOps puts data governance into DevOps and DataOps pipelines: components, automated controls, adoption steps, trade-offs and what AI agents change.
DataGovOps is the practice of running data governance the way DevOps runs software delivery: policies, quality rules and access controls are written as code, versioned, tested and enforced automatically inside the data pipeline. It combines data governance, DevOps and DataOps into one workflow, so that governance moves at the same speed as data delivery.
For enterprise leaders the point is simple. Manual reviews and policy documents do not keep up with pipelines that change daily, and they leave AI systems consuming data nobody has checked. This guide explains the components, the controls you can automate, an adoption sequence, the trade-offs, and what changes when AI agents act on your data. For the wider planning view, see our guide to data strategy elements.
What is DataGovOps and how does it differ from DataOps and DevOps?
DataGovOps is not a new product category. It is a way of working that joins three disciplines which are usually run by separate teams. Data governance sets the rules for who owns data, who may use it and to what standard. DevOps supplies the automation habits: version control, continuous integration and delivery, and repeatable environments. DataOps applies those habits to data pipelines, with testing and monitoring at every stage. The DataOps Manifesto itself calls for automated detection of abnormalities, continuous monitoring of quality and performance, and versioned, reproducible results. DataGovOps adds governance to that list.
| Discipline | Main question | What it contributes | Gap if used alone |
|---|---|---|---|
| Data governance | Who owns this data and what may be done with it? | Policies, roles, standards, compliance obligations | Rules live in documents and are checked late, by hand |
| DevOps | How do we change systems safely and often? | Version control, CI/CD, automated environments | Built for code, not for data quality or data policy |
| DataOps | Is the pipeline reliable and the data fit for use? | Data tests, orchestration, monitoring, reproducibility | Quality is checked, but ownership and policy are not always enforced |
| DataGovOps | Can we prove each change met policy, automatically? | All of the above, with policy, lineage and audit evidence built in | Needs clear owners and a cultural shift to work |
What are the key components of DataGovOps?
Three components must work together. Remove any one and the others lose most of their value.
Data governance
Governance defines what good looks like: ownership, definitions, quality standards, retention, access rules and the legal obligations the data must meet. In DataGovOps these are written so a machine can test them. Our data governance glossary entry covers the underlying concepts.
DevOps
DevOps practices bring version control, review, automated testing and release pipelines to data assets. Schema changes, policy changes and pipeline changes go through the same pull request and CI/CD path as application code. The same thinking applies to databases, as in our guide to DevOps for databases.
DataOps
DataOps supplies data quality tests, pipeline orchestration, versioning and monitoring. It is the layer that notices when a feed is late, a column drifts or a volume drops. Our article on DataOps architecture on AWS, Azure and GCP shows how this is built on the major clouds.
Which governance controls can you automate in the pipeline?
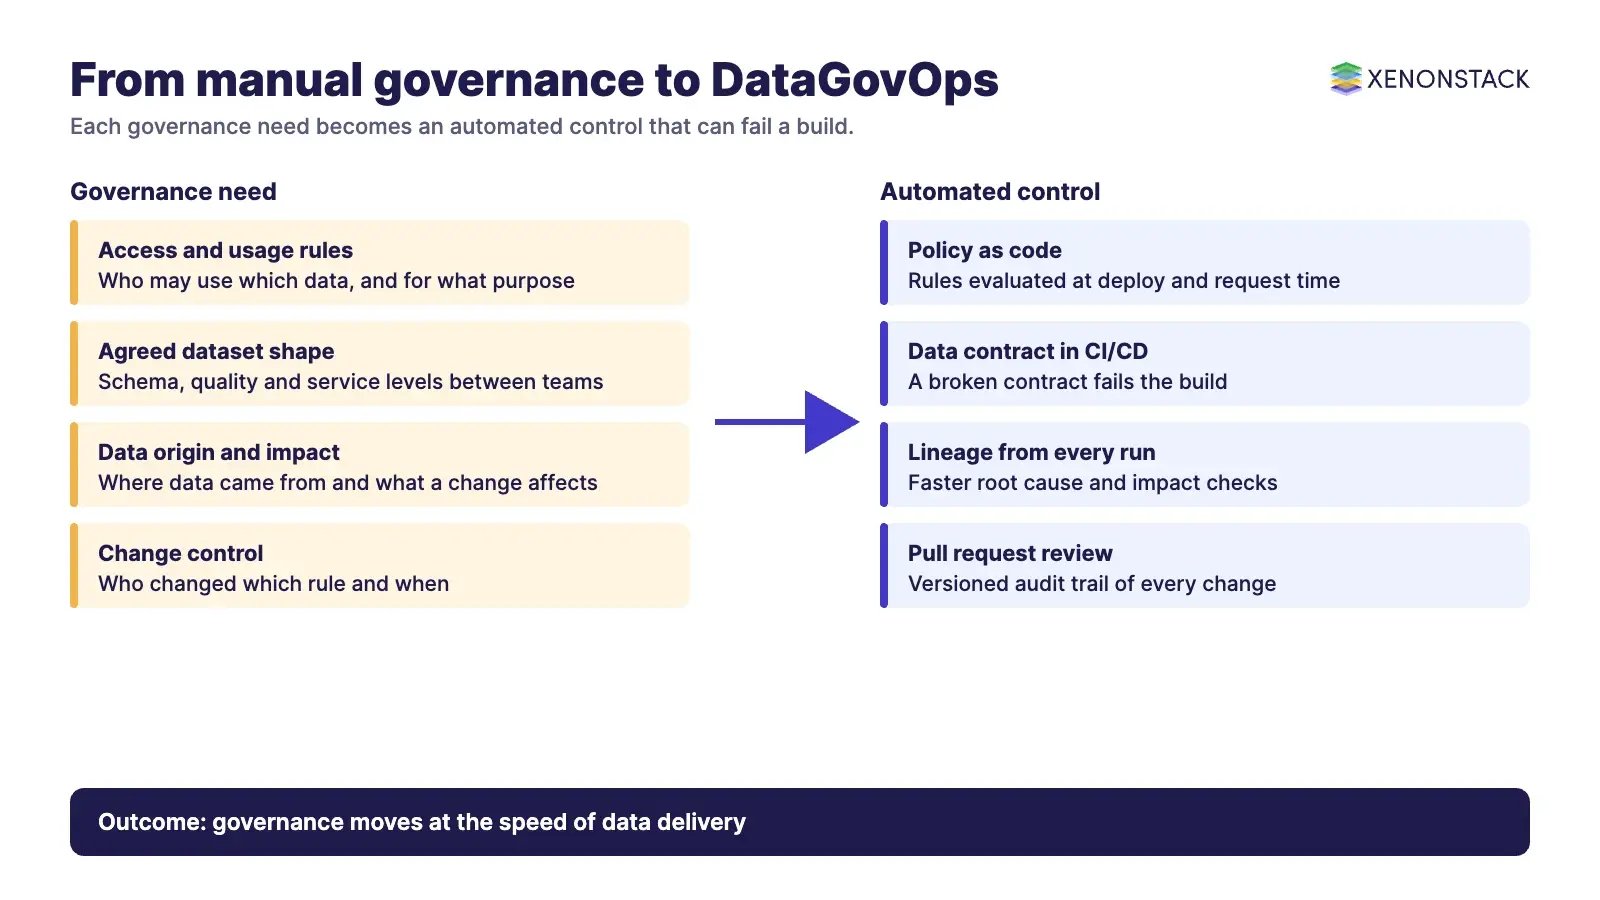
The practical test of DataGovOps is whether a rule can fail a build or block a release. The table below maps common governance needs to an automated control and to an open standard that can support it. These are examples of tool classes, not a required stack.
| Governance need | Automated control | Open standard or approach | What it gives you |
|---|---|---|---|
| Access and usage rules | Policy as code evaluated at deploy time and at request time | Open Policy Agent, a CNCF graduated project that returns decisions from policies written in Rego | Consistent decisions that are versioned and reviewable |
| Agreed shape and quality of a dataset | Data contract checked in CI/CD | Open Data Contract Standard, a YAML specification covering schema, data quality, service levels and ownership | A producer and consumer agreement that can fail a build |
| Knowing where data came from and what it affects | Lineage captured from every run | OpenLineage, an open API for lineage events about datasets, jobs and runs | Faster root-cause analysis and change impact checks |
| Fit for use | Data tests at every stage, with monitoring in production | Practices from the DataOps Manifesto: test early, monitor quality and performance continuously | Problems found before consumers see them |
| Change control | Pull request review and release gates | Version control and CI/CD | An audit trail of who changed which rule and when |
What has changed now that AI agents act on enterprise data?
Earlier DataGovOps programmes mostly served dashboards and reports. A human read the output and could notice something odd. AI agents now retrieve data and take actions, often with no person in the loop for each step. That raises the standard. Governance has to be evaluated at the moment of the decision, not only at the moment data lands in a table.
A catalogue records policy, ownership and lineage, but on its own it does not stop an agent acting outside policy. That needs a runtime layer. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentGRC keeps autonomous agent actions inside policy, with the audit trail risk teams need. The pipeline controls above are what feed that layer with trustworthy, versioned inputs. For teams building and orchestrating agents themselves, ElixirClaw is an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
How do you adopt DataGovOps in the right order?
Adopt it one data product at a time. A programme that tries to cover every domain at once usually stalls on ownership disputes.
1. Pick one high-value data product
Choose a dataset with a clear consumer and a visible cost when it breaks. Name an accountable owner before writing any code.
2. Write the contract and the rules
Record schema, quality thresholds, access rules and retention in a versioned contract that machines can read.
3. Put the rules in the pipeline
Run contract checks and data tests in CI/CD. Fail the build when a rule is broken, and keep exceptions visible.
4. Capture lineage and monitor in production
Emit lineage from every run and monitor quality and freshness, so an incident can be traced and its impact assessed.
5. Review and extend
Measure incidents, time to fix and time to approve a change. Extend to the next domain only when the first one shows improvement.
What are the advantages of DataGovOps?
| Advantage | How it comes about | Who notices first |
|---|---|---|
| Better data quality | Tests and contracts run on every change, so defects stop at the pipeline | Analysts and data scientists |
| Faster, safer change | Governance review is part of the pull request, not a separate queue | Data engineers and platform leads |
| Regulatory readiness | Rules, changes and lineage are recorded, so evidence is produced as work happens | Risk, compliance and audit teams |
| Security and privacy by design | Access and usage policy is enforced in code and applies the same way everywhere | CISOs and privacy officers |
| Better collaboration | Owners, producers and consumers work from one shared contract | Business stakeholders |
| Ready for AI use | Versioned policy and lineage give AI systems and agents governed inputs | Chief data and AI officers |
What are the challenges and when is DataGovOps not the right move?
| Challenge | Why it happens | What helps |
|---|---|---|
| Resistance to change | Governance becomes everyone's daily work, not one team's review | Start small, show a fixed incident, name owners |
| Skills gap | It needs governance, DevOps and DataOps skills together | Pair data engineers with governance leads; train on the pilot |
| Data silos | Data held in separate systems cannot be governed as one | Begin within one domain; use contracts at the boundaries |
| Weak collaboration | Producers and consumers have no shared agreement | Make the data contract the meeting point |
| Security and privacy | Rules differ by data type and jurisdiction | Encode policy centrally and review it with legal |
DataGovOps is a poor fit when the data estate is small and stable, when no one can be named as owner, or when basic pipeline automation does not yet exist. In those cases, fix ownership and build DataOps basics first. Automating a rule nobody agrees on only makes the disagreement faster.
What does it mean for security and cost?
On security, policy as code gives one reviewable source for access rules, which reduces drift between environments. Pair it with the platform-level controls described in our guide to PlatformOps. On cost, the saving comes mainly from fewer incidents and less manual review, but it should be measured on your own pilot rather than assumed. Tooling is not the main cost. Ownership time and training are.
To map one decision your agents should make, and the data, context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is DataGovOps?
DataGovOps applies DevOps and DataOps practices to data governance. Policies, quality rules, access controls and lineage are written down as versioned, testable artefacts and enforced automatically in the data pipeline, instead of being checked by hand after the data has moved.
How is DataGovOps different from DataOps?
DataOps focuses on the delivery and quality of data and analytics through automation, testing and monitoring. DataGovOps keeps those practices and adds governance as a first-class concern: ownership, policy, access rules, lineage and audit evidence are built into the same workflow.
Does DataGovOps need new tools?
Not necessarily. Most teams start with what they have: version control, CI/CD, data tests and a catalogue. Open standards such as Open Policy Agent for policy, the Open Data Contract Standard for contracts and OpenLineage for lineage can fill gaps without locking you into one vendor.
Where should an enterprise start?
Start with one high-value data product. Name an owner, write its contract and quality rules, put them in version control, run them in CI/CD and monitor them in production. Extend to further domains only after the first one shows fewer incidents and faster change.
How does DataGovOps help with AI agents?
Agents act on data at runtime, so a catalogue entry alone does not stop a wrong action. DataGovOps supplies the governed, versioned policy and lineage. A decision layer above the agents, such as ElixirData Context OS, can then check that context before an action and record a decision trace afterwards.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE