Key takeaway
- Generative AI agents can summarise alerts, gather context and draft updates for managed services teams. See where they help, the risks and how to start.
Generative AI agents in managed services are software agents, built on generative models, that read incident data, summarise what is happening, propose or run response steps and keep humans informed, inside the operations of a managed services provider (MSP). They sit on top of monitoring and ticketing tools rather than replacing them.
This guide is for MSP and IT operations leaders who run managed services for several customers and want faster, more consistent incident response. It covers where agents help, how to introduce them in stages, how they compare with rule-based tooling, and where human control must stay.
What do generative agents do in incident response?
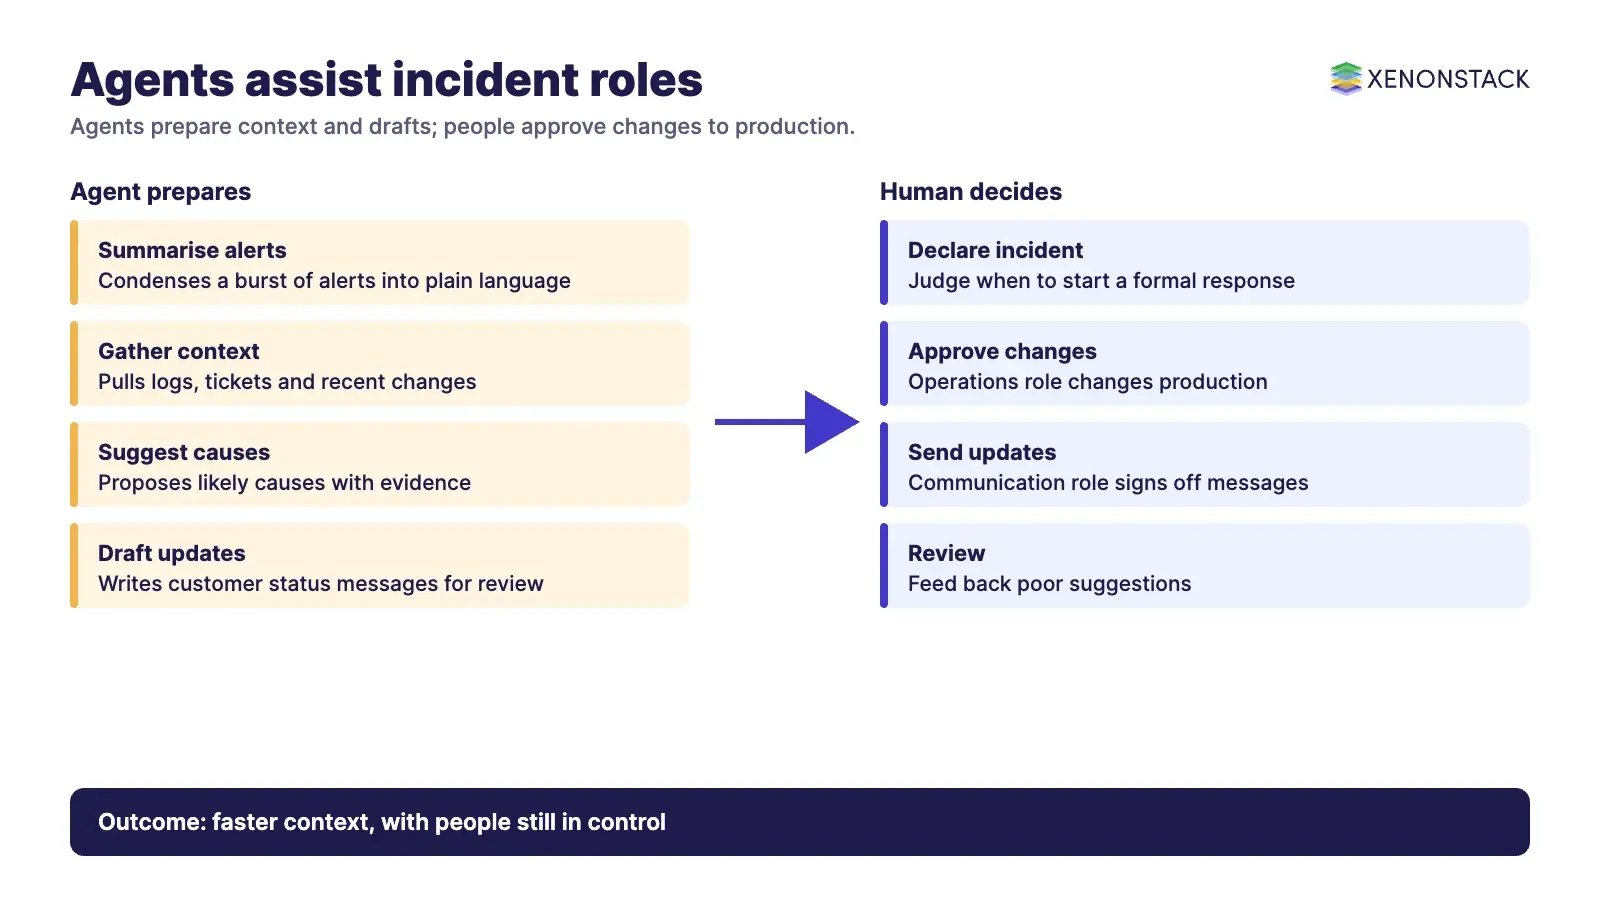
An MSP carries a heavy load: many customers, many tools, and alerts that arrive around the clock. Generative agents are useful where the work is reading and writing. They can condense a burst of alerts into a plain-language summary, pull related logs and recent changes, draft a status update for a customer, suggest likely causes and recommend a next step for a responder to approve. They draw on large volumes of operational and big data, and they speak the language of the people who read their output.
The generative AI part matters most for communication and synthesis. Detection and correlation can still be done by monitoring rules and statistical methods, and many teams keep them that way because they are predictable.
Why do managed service providers need them?
The pressure is practical. The Google SRE book chapter on monitoring says "Every page should be actionable" and warns that "When pages occur too frequently, employees second-guess, skim, or even ignore incoming alerts." Rule-based monitoring raises alerts but does not explain them, so analysts spend time assembling context by hand. Agents aim at that assembly work. The limits are equally real: they can be wrong, they cost money to run, and they need people who can supervise them.
| Need | Rule-based tooling | Generative agents |
|---|---|---|
| Detecting a known condition | Strong: explicit thresholds and rules | Not required; keep rules |
| Summarising a burst of alerts | Limited: lists alerts, little explanation | Strong: writes a readable summary |
| Gathering context | Manual lookups | Can query logs, tickets and change history |
| Customer communication | Templates | Drafts updates for review |
| Predictability and audit | High | Lower: needs logging and review |
How should an MSP introduce agents step by step?
Treat it as an operations change, not a software install. The sequence below follows the incident phases in the NIST incident handling guide, which names "preparation, detection and analysis, containment, eradication and recovery, and post-incident activity". That publication (SP 800-61 Revision 2) has since been withdrawn and superseded by Revision 3 in April 2025, so confirm current NIST guidance when you design your process.
- Assess the current incident process, tools and compliance duties, and record a baseline.
- Define objectives you can measure, such as time to acknowledge or time to resolve.
- Choose a platform that fits your integration, scaling and vendor support needs.
- Run a pilot on one customer or one incident type, with feedback from responders.
- Train the team to supervise, correct and escalate from the agent's output.
- Integrate with existing workflows step by step, so agents assist people rather than replace them.
- Monitor performance after launch and adjust.
- Keep a feedback loop so responders can flag poor suggestions.
What should stay with humans?
The Google SRE chapter on managing incidents describes four roles: incident command, operations, communication and planning. It says "The operations team should be the only group modifying the system during an incident" and that the incident commander holds the high-level state. Agents fit best as assistants to these roles. An agent can draft communication or gather planning notes, but changes to production should go through the operations role with approval. The chapter also gives a rule for when to declare an incident: if a second team is needed, if the outage is visible to customers, or if the issue is unsolved after an hour of concentrated analysis.
What are the strengths and risks?
| Strength | Risk to manage |
|---|---|
| Faster context gathering and summaries | Confident but wrong explanations, so require evidence links |
| Less alert fatigue when noise is grouped | Over-filtering that hides a real signal |
| Scales across customers with shared patterns | Customer data mixing, so enforce tenant separation |
| Consistent communication | Ongoing run cost and staff training needs |
How do AI agents change managed services operations?
Agents shift the MSP's work from handling each alert to supervising a process. People set policy, approve risky actions and handle the exceptions, while agents prepare the ground. This applies well beyond servers: organisations adding IoT devices and wider IoT solutions will see more signal types to triage. The governance questions stay the same: what the agent may do, who approves it and how its reasoning is recorded. ElixirClaw, the AI agents computing platform, is where XenonStack builds and runs agents like these.
What should you do first?
- Pick one incident type with clear steps and a measurable baseline.
- List what an agent may read and what it may never change without approval.
- Pilot with one customer and review every suggestion for the first weeks.
- Log each agent action and the evidence behind it.
- Expand only after responders agree the output is useful.
To map one decision your agents make, and the data and policy it depends on, book a Context Workshop. See what happens in the workshop.
Related reading: XenonStack's managed services provider news, autonomous agents for market research and the power of autonomous agents.
Frequently asked questions
What are generative agents in managed services?
They are software agents built on generative models that read incident data, summarise it, propose or run response steps and keep people informed, inside a managed services provider's operations.
Do generative agents replace monitoring rules?
No. Rules remain the predictable way to detect known conditions, while agents add summaries, context gathering and drafted communication on top of the alerts those rules raise.
Which incident process should an MSP align with?
Many teams use the phases in NIST SP 800-61: preparation, detection and analysis, containment, eradication and recovery, and post-incident activity. Revision 2 has been withdrawn and superseded by Revision 3, so check the current version.
What should agents not do on their own?
The Google SRE book says the operations team should be the only group modifying the system during an incident, so agents should hand changes to that role for approval.
How do you start safely?
Choose one incident type, set clear limits on what the agent may read and change, pilot with one customer, log every action and expand only when responders find the output useful.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE