Key takeaway
- DataFinOps applies FinOps Foundation practice to data platforms. See the Inform, Optimize and Operate phases, team roles, guardrails and when to start.
What is DataFinOps and why does it matter now?
DataFinOps applies the FinOps Foundation approach to data platforms: engineering, finance and business teams share accountability for what data workloads cost and what value they return. The FinOps Foundation defines FinOps as "an operational framework and cultural practice which maximizes the business value of technology". DataFinOps is the same practice pointed at warehouses, lakehouses, pipelines and the clusters beneath them.
The scope has widened. The Foundation now lists data platforms alongside public cloud, SaaS and AI as FinOps scopes, and its 2026 State of FinOps survey of 1,192 practitioners reports that 98% now manage AI spend, up from 63% in 2025 (as reported on data.finops.org). For a CTO or CDO, data spend is no longer a footnote in the cloud bill. Related reading: FinOps for data mesh and data fabric.
How does DataFinOps differ from DataOps and from general FinOps?
DataOps here means the agile, automation-driven way of running data pipelines. FinOps adds the financial discipline. The table shows what each brings and where DataFinOps sits between them.
| Discipline | Main question | What it contributes to DataFinOps |
|---|---|---|
| DataOps | Are data pipelines reliable and delivered quickly? | Pipeline telemetry, automation and self-service habits |
| FinOps | Is technology spend creating business value? | Allocation, forecasting, budgets and shared accountability |
| DataFinOps | What does each data workload cost, and is it worth it? | Cost and performance data read together at job, pipeline and platform level |
The FinOps Foundation framework lists six principles, including "Teams need to collaborate", "Business value drives technology decisions", "Everyone takes ownership for their technology usage" and "FinOps data should be accessible, timely, and accurate" (FinOps Framework). They translate directly to data teams: shared dashboards, named owners for each workload and cost decisions tied to business outcomes.
Who should be on a DataFinOps team?
Organisations split the work differently. Some follow a "you built it, you own it" model, where one team handles data engineering, operations and cost. Others separate the roles. Either way, the team needs these voices:
| Role | Why it is needed |
|---|---|
| Finance | Budgets, forecasts and chargeback or showback rules |
| Data engineering and operations | Pipeline design, job tuning and platform configuration |
| Product owners | Which data products justify their cost |
| Data architects and platform owners | Platform choices, tagging standards and guardrail design |
| Leadership | Priorities and the value test for spend decisions |
What are the Inform, Optimize and Operate phases?
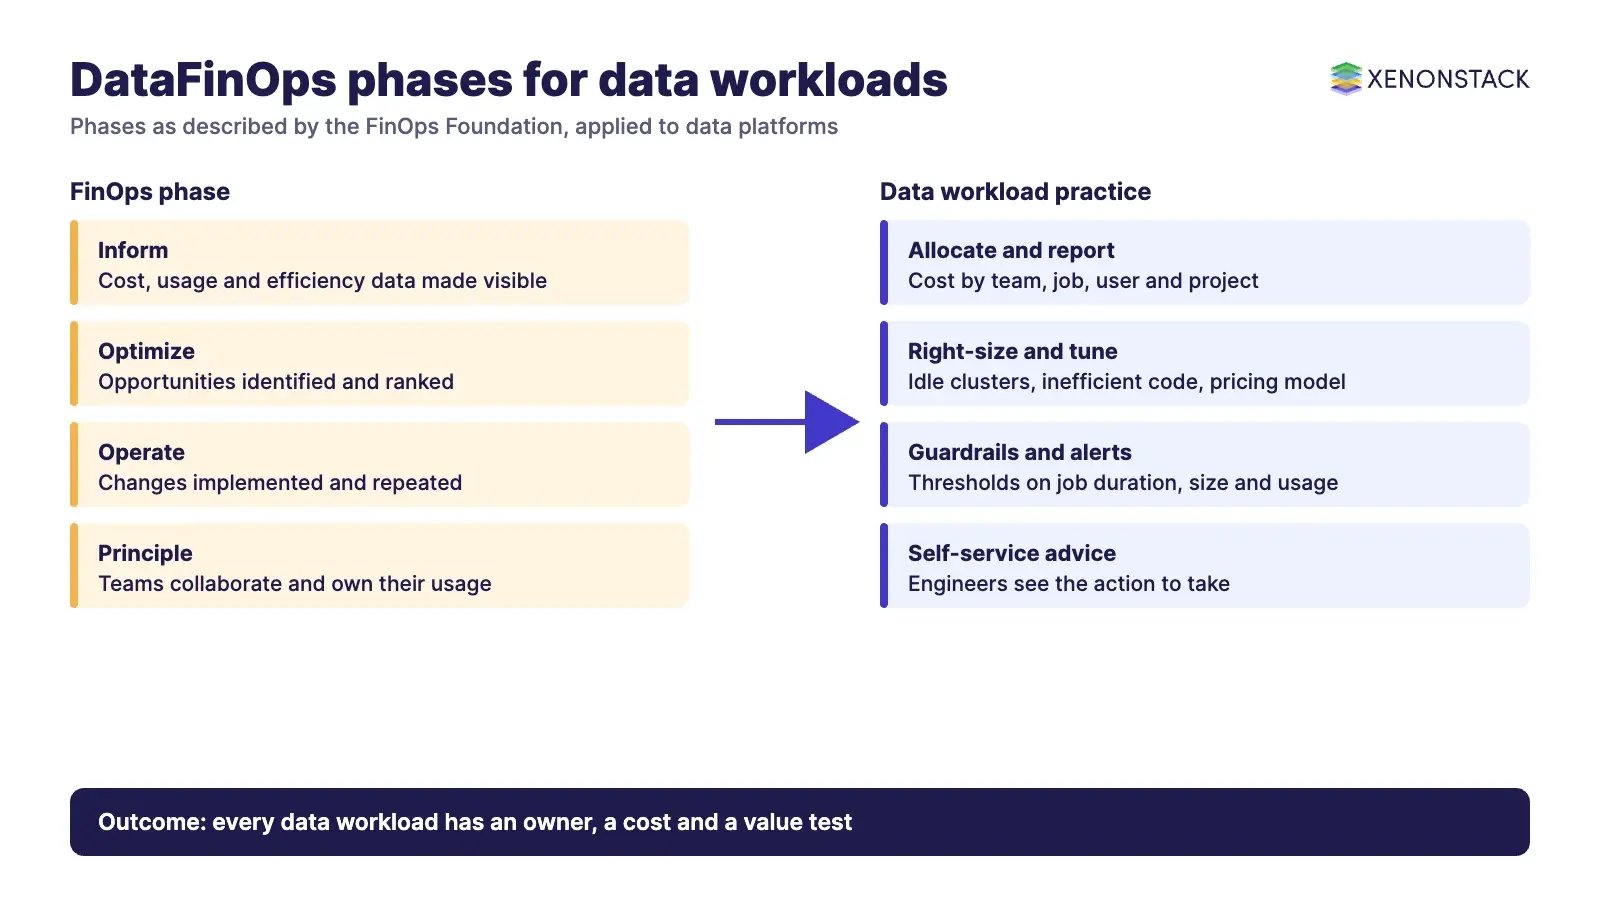
The Foundation describes FinOps as a journey through three phases. Different teams in one organisation are often in different phases at once.
| Phase | FinOps Foundation description | What it looks like for data workloads |
|---|---|---|
| Inform | Examining technology cost, usage and efficiency data to see the business value of current use | Allocate cost by team, job, user and project; build showback reports; track actual spend against budget; forecast |
| Optimize | Identifying opportunities to improve efficiency and value, then ranking them against goals | Shut down idle clusters, right-size jobs, fix inefficient code, choose the right pricing model |
| Operate | Implementing the changes identified in Optimize and returning to earlier phases | Automated guardrails, alerts and self-service recommendations so teams prevent overspend instead of reacting |
Inform: where is the money going?
Cloud data platforms produce very large volumes of billing records. The aim of this phase is to combine financial data with performance data so that every cost can be traced to an owner. Tagging and data observability make it possible to analyse cost by user, job, team and project. Typical outputs are showback or chargeback reports, a list of top spenders, spend against budget and a usage forecast.
Optimize: what can be changed?
Savings sit at several levels, and each needs a different owner:
| Level | What drives cost | Typical action |
|---|---|---|
| Application | Configuration and code of each job | Fix inefficient code, right-size resources |
| User | Individual usage patterns | Feedback and self-service recommendations |
| Pipeline | End-to-end pipeline efficiency | Remove redundant stages and reruns |
| Platform | Choice of Databricks, Snowflake, Amazon EMR, BigQuery or Dataproc | Match workload to platform and pricing model |
| Cluster | Provider charges for compute and storage | Shut down idle clusters, use discounted capacity where the workload tolerates interruption |
Operate: how do teams stop overspend before it happens?
Operating means moving from reactive clean-up to prevention. Define what counts as excessive cost, then enforce it with automated guardrails based on measures such as Databricks units, job duration, job size and resource use. When a guardrail is breached, the response can range from an alert to terminating a job or requesting a configuration change. Alerts must be specific enough to avoid alert fatigue. Self-service recommendations let engineers see the action to take without reading raw billing data.
Why do DevOps cost tools fall short for data workloads?
Teams often reuse the observability and cost tools built for DevOps. Data applications behave differently from web applications, so those tools can miss the signals that matter:
They may not capture the telemetry that modern data stacks produce, including detail on the sub-parts of parallel jobs.
They may not apply the analysis needed for data-specific problems such as degree of parallelism, load imbalance, skew and code execution.
Cloud-provider cost consoles show spend but still leave engineers to work out which job or pipeline caused it.
Standardised billing data helps. The FOCUS specification (FinOps Open Cost and Usage Specification) is an open specification that normalises billing datasets across AI, cloud, SaaS, data centre and other technology vendors, and its current version is 1.4. For the observability side, see full-stack observability and cloud-native observability tools, and for cloud cost levers more broadly, FinOps for Google Cloud cost optimisation.
What should a DataFinOps adoption sequence look like?
Agree ownership. Name an owner for each data platform, pipeline and workload.
Standardise tagging. Without tags, allocation is guesswork.
Join cost and performance data. Cost per job or per data product is more useful than a monthly total.
Rank optimisation options by value and effort, and keep a backlog.
Automate guardrails and alerts once thresholds are agreed.
Agentic systems add a further layer: agents that query data or run jobs also incur cost, so spend limits and decision records belong in the same governance picture. ElixirData Context OS presents itself as the Decision Harness for enterprise AI agents, checking rules and permissions before an agent acts and keeping records of every action, and AgentAnalyst lets teams ask questions of enterprise data in plain English and get trusted insights, charts and SQL.
When is DataFinOps not the right first step?
Spend is small and stable: simple budget alerts may be enough.
No tagging or ownership exists: fix that first, because allocation depends on it.
The aim is purely to cut cost: the FinOps Foundation frames the goal as business value, so cutting a high-value workload to save money can backfire.
To map one cost decision your data and AI agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is DataFinOps?
DataFinOps applies FinOps practice to data platforms and workloads, so engineering, finance and business teams share accountability for data cost and value.
What are the three phases of FinOps?
The FinOps Foundation names them Inform, Optimize and Operate. Inform builds visibility, Optimize finds and ranks improvements, and Operate implements them and returns to earlier phases.
Which FinOps principles matter most for data teams?
Collaboration, business value driving decisions, ownership of usage, and accessible, timely and accurate FinOps data are four of the six Foundation principles that map directly to data work.
What is FOCUS and why does it help?
FOCUS is an open specification for consistent billing datasets across AI, cloud, SaaS, data centre and other vendors. Consistent data makes cost comparison and allocation simpler. Version 1.4 is the current version.
Why not reuse DevOps cost tools?
Data applications run parallel jobs and show problems such as skew and load imbalance that web-application tools may not capture.
Does FinOps cover AI spend?
Yes. The 2026 State of FinOps survey of 1,192 practitioners reports that 98% manage AI spend, and FinOps for AI is the top forward-looking priority.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE