Key takeaway
- AWS Data Catalog explained: how the Glue Data Catalog, crawlers and Lake Formation work, what they cost, and how to govern metadata across accounts.
What is the AWS Data Catalog, and which service should you use?
"AWS Data Catalog" in practice means the AWS Glue Data Catalog: a centralised repository of metadata about your datasets that acts as an index to their location, schema and runtime metrics (AWS Glue documentation). Each AWS account has one catalogue per Region, and Amazon Athena, Amazon Redshift Spectrum and Amazon EMR read it directly. Access is governed through IAM and AWS Lake Formation.
This guide is for CIOs, CDOs, platform leads and data architects who need to decide how much of their AWS data estate the catalogue should cover, who may see what, and where it stops. For the product-neutral view see our data catalog tools and architecture guide, and for the Microsoft equivalent see Azure Data Catalog and Microsoft Purview.
| Option | What it is | When it fits | Current status (AWS docs, 12 Nov 2026) |
|---|---|---|---|
| AWS Glue Data Catalog | Technical metadata store: databases, tables, partitions, connections | Any lake or warehouse workload on Athena, EMR, Redshift Spectrum or Glue ETL | Managed service; described as a drop-in replacement for the Apache Hive Metastore |
| AWS Lake Formation | Permission and sharing layer over the catalogue and the S3 data | You need column, row or tag-based access and cross-account sharing | Managed service; works with IAM, supports hybrid access mode |
| Business context in Glue (glossary terms, custom metadata, semantic search) | Business meaning added to catalogue assets | Business users must find data without knowing table names | Labelled Preview in the Glue documentation |
| Amazon SageMaker Catalog | Business catalogue with inventory, curate and publish steps for a project | Teams working in SageMaker Unified Studio | Documented as a separate catalogue; its page does not state the link to Glue, so confirm before you plan around it |
| Custom metadata index | Your own index built with S3 events, Lambda and DynamoDB | Only where managed services cannot meet a specific need | AWS described the pattern in a 2015 blog post; it is a build and run cost for you |
Older AWS designs built a "comprehensive" catalogue with Lambda, DynamoDB and a search service, next to a Hive-compatible Glue catalogue. The Glue route is now the usual default. AWS published the serverless S3 metadata index pattern on 12 August 2015, so treat it as a legacy design to be reviewed, not a starting point (AWS Big Data Blog).
How does the AWS Glue Data Catalog work?
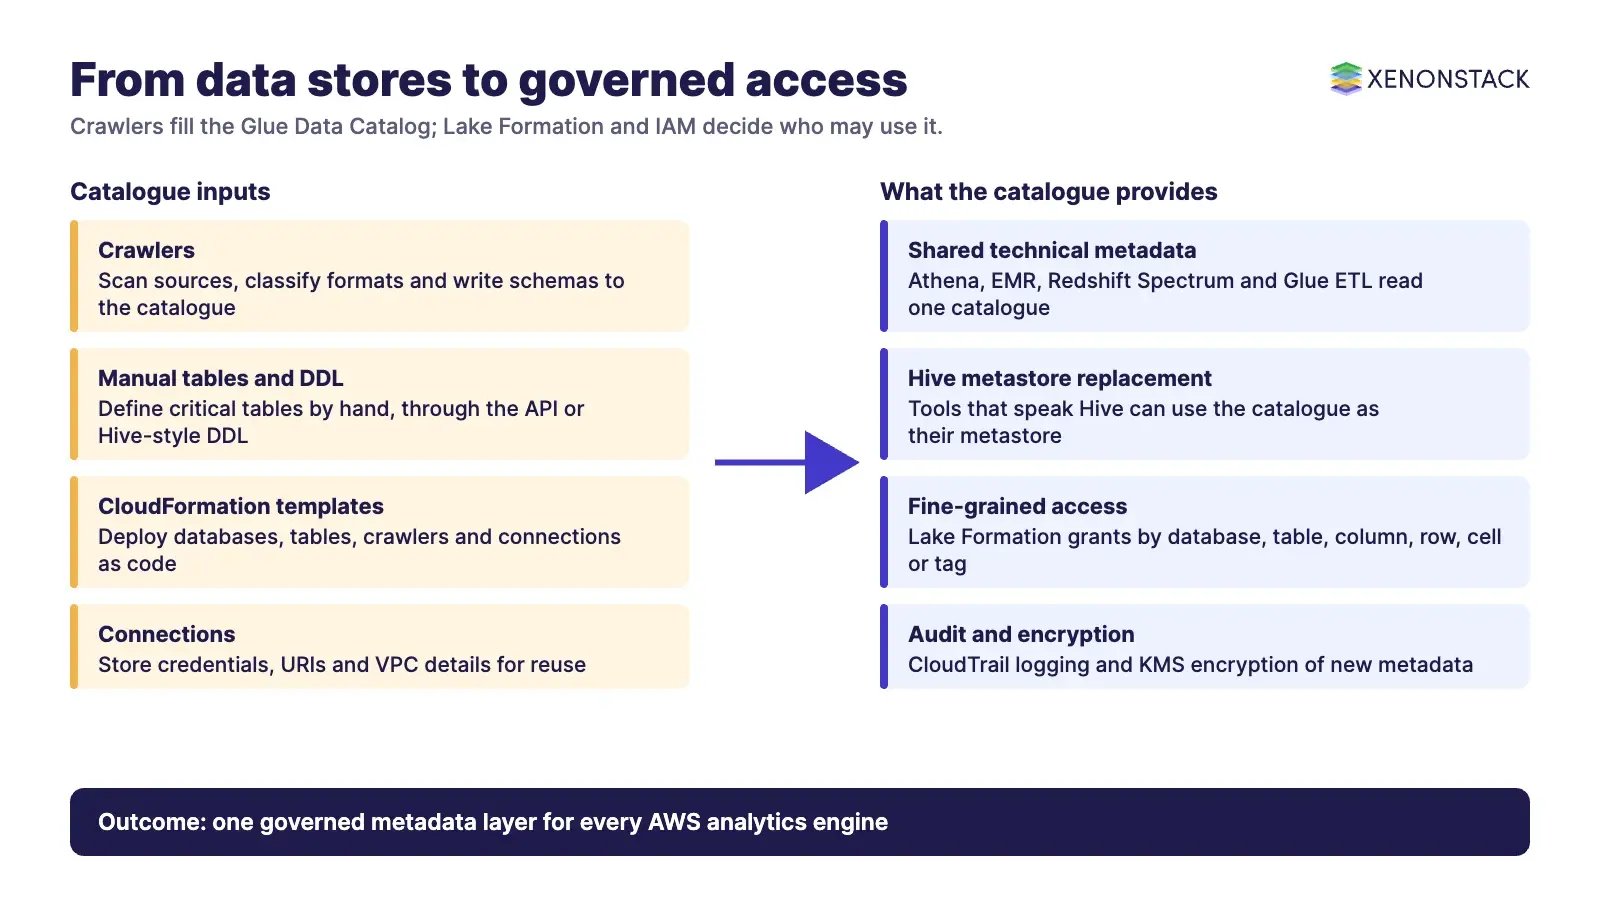
Metadata sits in tables, each representing a single data store, organised into databases much like a relational catalogue. A table can describe objects in Amazon S3 or relational tables in Amazon RDS. The data itself stays where it is.
Databases, tables and partitions
A database is a container for tables. Tables can be created manually in the console, through the API or Hive-style DDL, or by a crawler. Partition keys let query engines skip data they do not need, which is why consistent file schemas and formats inside a partitioned table matter.
Crawlers and classifiers
A crawler scans a data source, classifies it, extracts schema and writes the result to the catalogue. It assumes an IAM role that can read the source and write to the catalogue; AWS recommends starting from the AWSGlueServiceRole managed policy plus a policy for the data source. Classifiers recognise the format. AWS Glue runs your custom classifiers first, in the order you set. If none is certain, built-in classifiers run (including CSV, JSON, Parquet, Avro, ORC and XML), and the format is marked UNKNOWN if nothing scores above zero. Changing a classifier does not reclassify data already crawled; you need a new crawler for that (AWS Glue classifier documentation).
Connections
A connection is a catalogue object that stores credentials, URI strings and VPC information for a data store, so crawlers and jobs can reuse it instead of repeating the details (AWS Glue connections). Treat connection objects as sensitive configuration and give them the same review as secrets.
Hive metastore compatibility
The catalogue can replace a Hive metastore for tools that speak Hive. On Amazon EMR 5.8.0 and later it can serve as a persistent metastore shared across clusters, services and AWS accounts (Amazon EMR documentation). Plan for the stated limits: Hive authorisation is not supported on EMR with Glue (use Glue resource-based policies), tables renamed in Glue are unsupported, and tables without an explicit S3 location default to HDFS, so the data disappears when the cluster ends.
How should you populate and maintain the catalogue?
| Method | Best for | Watch for |
|---|---|---|
| Crawler | Discovering schemas and partitions across many S3 prefixes or databases | Role permissions, classifier order, and crawler cost billed separately from the catalogue |
| Manual table, API or DDL | A small number of critical, stable tables | Drift between the table definition and the files |
| AWS CloudFormation | Repeatable environments; Glue databases, tables, crawlers, classifiers and connections are all CloudFormation resource types | Keeping templates and live catalogue changes in step |
| Hive metastore migration | Moving an existing Hive catalogue into Glue | Unsupported Hive features listed above |
For deployment as code, the CloudFormation reference lists Glue resource types for the catalogue, databases, tables, partitions, crawlers, classifiers and connections (AWS CloudFormation template reference).
Which AWS services read the catalogue?
| Service | How it uses the catalogue | Source |
|---|---|---|
| Amazon Athena | Stores and retrieves table metadata for queries; the catalogue appears as AwsDataCatalog | Athena documentation |
| Amazon EMR | Hive metastore replacement from EMR 5.8.0; cross-account access from EMR 5.16.0 | EMR documentation |
| Amazon Redshift Spectrum | Reads the shared catalogue for external tables | Glue documentation |
| AWS Glue ETL jobs | Use catalogue tables as sources and targets | Glue documentation |
| AWS Lake Formation | Governs access to catalogue metadata and the S3 data | Lake Formation documentation |
How do you govern, secure and cost the catalogue?
Lake Formation permissions augment IAM and can be granted at database, table, column, row and cell level. Tag-based access control lets you attach labels to databases, tables or columns and grant access by label, which AWS says can manage hundreds or thousands of permissions with a few tags. Hybrid access mode lets you adopt Lake Formation one use case at a time, without disrupting existing IAM-based workloads. Sharing across accounts and AWS Organizations is supported for both metadata and data (Lake Formation documentation).
Auditing runs through AWS CloudTrail and Lake Formation, including schema change tracking and data access controls. You can encrypt catalogue metadata at rest with AWS KMS keys, but only new metadata written after you enable it is encrypted; existing metadata stays unencrypted (Glue catalogue encryption).
On cost, AWS lists the first million stored objects and the first million metadata requests each month as free, then US$1.00 per 100,000 objects stored. Crawlers are billed at US$0.44 per DPU-hour, per second. Prices vary by Region, so check the AWS Glue pricing page before budgeting.
What is the recommended adoption sequence?
Name an owner for the catalogue and agree which accounts and Regions are in scope, remembering there is one catalogue per account and Region.
Start with the datasets that feed your highest-value analytics and register them with crawlers or reviewed table definitions.
Set a naming and database convention, then deploy it with CloudFormation so environments match.
Turn on catalogue encryption and CloudTrail logging before sensitive tables arrive.
Introduce Lake Formation in hybrid access mode for one use case, then move to tag-based access for the next.
Add business context (glossary terms and descriptions) for assets business users search for, noting that this feature is in Preview.
Review crawler runs, cost and schema drift monthly, and retire tables nobody uses. See metadata as a product for how to treat metadata as an owned asset.
What are the trade-offs, and where does a catalogue stop?
A catalogue describes data; it does not decide who or what may act on it at the moment of use. Our comparison table puts data catalogues at metadata, lineage, glossary and quality signals, and policy enforcement, authority management and decision traces outside their scope (context layer comparison). For AI agents that retrieve and act on enterprise data, that gap matters. ElixirData Context OS keeps governed context, versioned policy and decision traces in one decision layer above AI agents, and AgentSearch helps people and AI agents find meaningful passages across an organisation's documents and knowledge bases while respecting who is allowed to see them. Where agent actions must stay inside policy with an audit trail, AgentGRC does that for autonomous agents.
| Situation | Better choice |
|---|---|
| Single-account lake on Athena and EMR | Glue Data Catalog alone, with IAM |
| Many accounts, sensitive columns, shared datasets | Glue Data Catalog with Lake Formation |
| Business users must discover data by meaning | Add business context or a business catalogue; plan for Preview status |
| Hive-based tools needing Hive authorisation or transactions | Check the EMR limitations first; use Glue resource-based policies for access |
| Many non-AWS sources and one enterprise view | A cross-platform catalogue; see our data catalog use cases and AWS Glue guides |
To map one data decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is the AWS Data Catalog?
It is the AWS Glue Data Catalog, a centralised metadata repository that indexes the location, schema and runtime metrics of your data. Each AWS account has one per Region.
Is the Glue Data Catalog compatible with Hive?
AWS describes it as a drop-in replacement for the Apache Hive Metastore. On Amazon EMR it is available from release 5.8.0, with documented limits such as no Hive authorisation.
How do crawlers choose a classifier?
Custom classifiers run first in your order, then built-in ones. A result with certainty 1.0 wins; otherwise the highest certainty is used, and UNKNOWN is returned if none scores above zero.
How is catalogue access controlled?
Through IAM and AWS Lake Formation, which can grant access at database, table, column, row and cell level, including by tag, and share across accounts and organisations.
What does the Glue Data Catalog cost?
The first million objects stored and the first million metadata requests each month are free; then US$1.00 per 100,000 objects. Crawlers cost US$0.44 per DPU-hour. Check your Region.
Does a data catalogue govern AI agent actions?
No. A catalogue provides metadata, lineage, glossary and quality signals. Policy enforcement and decision traces sit in a separate layer above it.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Ready to put AI agents to work? Explore ElixirClaw, the agentic OS platform to build, orchestrate and govern AI agents.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE