Key takeaway
- Missing data imputation in Databricks with AI agents: match the method to why values are missing, run it in Spark, validate it and log every filled value.
Missing data imputation in Databricks is a pipeline decision, not a single function call: the method has to match why the values are missing, and every filled value has to stay traceable. An AI agent adds value by profiling each table, choosing a method column by column under rules you set, running it as a Spark job, checking the result and logging what it changed. The statistics themselves still come from standard tools such as the Spark ML Imputer.
This guide is for data platform leads and architects who want imputation to run as a governed step rather than a notebook habit. It covers the missingness types, a method decision table, how to build the agent on Databricks, what to log and when not to impute at all. For the monitoring side, see our post on AI-powered data quality monitoring in Databricks, and for background on the agent pattern, AI agents.
Why do missing values matter, and why not simply drop the rows?
Dropping every row or column that contains a gap is the simplest option, but the scikit-learn documentation notes it comes at the price of losing data that may be valuable even though incomplete. Its recommended alternative is to impute, that is, to infer the missing values from the known part of the data (scikit-learn: imputation of missing values). In regulated sectors such as healthcare and finance, dropped rows can also change who is represented in a model, which is why the choice needs an owner and a record. See how agentic AI addresses healthcare data challenges for the sector context.
Which type of missingness do you have?
The mechanism behind the gaps decides which method is defensible. The Analysis Factor describes three types (The Analysis Factor: missing data mechanism).
| Type | Meaning | What it implies for the agent |
|---|---|---|
| MCAR (missing completely at random) | No relationship between missingness and any values, observed or missing | Simple statistics are least risky; the gap is not systematic |
| MAR (missing at random) | Missingness relates to other observed data, not to the missing value itself | Use methods that condition on other columns, such as KNN or regression-based imputation |
| MNAR (missing not at random) | Missingness depends on the unobserved value itself | No imputation is safe on its own; escalate to a data owner |
The same source cautions that MAR and MNAR cannot be fully separated from the data alone; the only true way to tell them apart is to measure some of the missing data. An agent should therefore flag suspected MNAR columns for human review rather than decide silently.
Which imputation method fits which column?
| Method | When it fits | Current status and limits |
|---|---|---|
Mean, median or mode (Spark ML Imputer) | Numeric columns with low business impact, MCAR gaps, very large tables | Documented in Apache Spark. Input columns should be numeric; categorical features are not supported and may produce incorrect values. Null values in the input columns are treated as missing and imputed (Apache Spark ML features: Imputer) |
| KNN imputation | MAR gaps where similar rows carry the signal | In scikit-learn, each missing feature is filled from the nearest neighbours that have a value, using a distance metric that supports missing values (scikit-learn docs) |
| Iterative (regression-based) imputation | MAR gaps with correlated columns | Models each feature as a function of the others in a round-robin; the scikit-learn docs mark it as experimental, so pin versions |
| Multiple imputation | Inference where uncertainty must be reported | scikit-learn's imputer returns a single imputation, but can be repeated with different seeds to produce several |
| Missing indicator column | Any column where "was missing" may itself be informative | scikit-learn notes that preserving which values were missing can be informative |
Databricks runs SQL, Python, R and Scala on Apache Spark, so each of these can sit in the same pipeline: Spark ML for distributed statistics, and Python libraries for model-based methods on partitions or samples. For adjacent Databricks patterns, see synthetic data with Databricks and generative AI and the XenonStack Databricks practice.
What does an imputation agent actually do on Databricks?
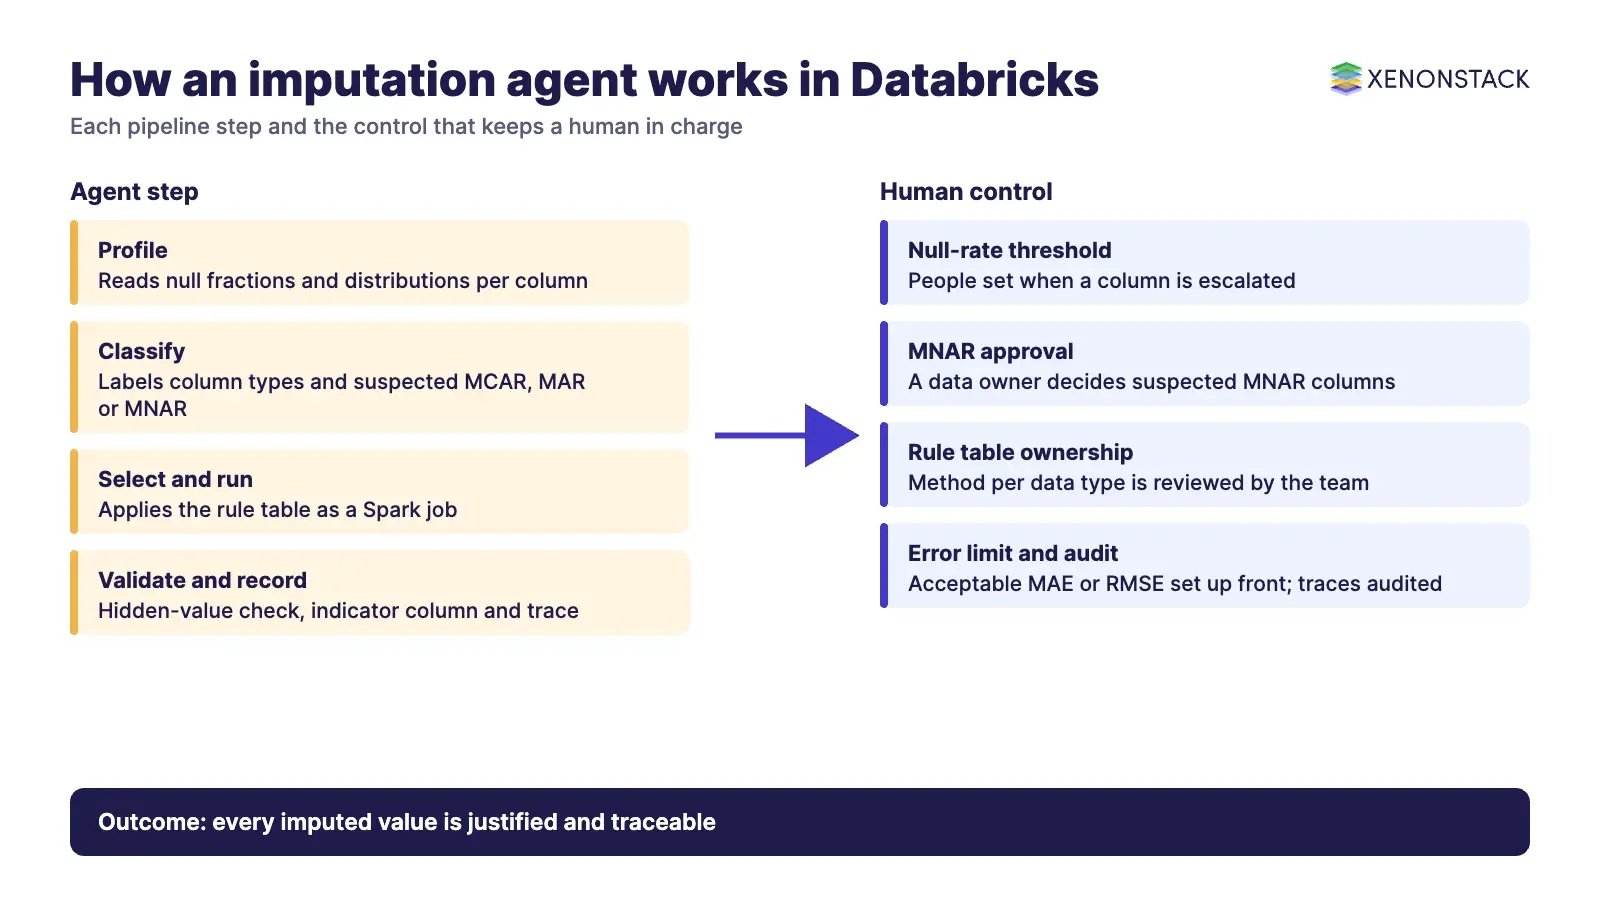
An imputation agent is a controlled loop around the methods above. It does not invent a new statistic; it decides which existing method to apply, applies it, and records the outcome. Databricks describes Agent Bricks as its agent developer platform, with build, deploy and govern stages, evaluation using LLM judges, custom scorers and expert feedback, and MLflow Tracing that records each step an agent takes (Databricks documentation: Agent Bricks).
| Agent step | What happens | Where a human stays in control |
|---|---|---|
| Profile | Reads null fractions and distributions for each column | Sets the null-rate threshold above which a column is escalated |
| Classify | Labels columns as numeric, categorical or time-ordered, and suspected MCAR, MAR or MNAR | Approves MNAR decisions |
| Select | Applies the rule table: statistics for low-impact numeric columns, model-based methods for complex ones | Owns the rule table |
| Run | Executes the chosen method as a Spark job | Reviews the job configuration |
| Validate | Compares imputed values with known values hidden on purpose, using MAE or RMSE | Sets the acceptable error |
| Record | Writes an indicator column, the method used and a trace | Audits the trace |
Databricks documents null fraction and distribution drift as things its data profiling can track over time, which gives the profile step a native source (Databricks documentation: data profiling). For a related practice, read building domain-specific AI models with SAP Databricks.
How should you adopt it, step by step?
- Start with one table. Pick a table where gaps already cause a known problem and measure null fractions per column.
- Write the rule table. Decide per data type which method applies and which columns always go to a human.
- Run in shadow mode. Let the agent write proposed values to a separate table and compare against the current process.
- Validate with hidden values. Hide a sample of known values, impute them, and compute MAE or RMSE against the originals.
- Promote with tracing. Switch to writing imputed values only when the error is acceptable, with a trace for every run.
- Review on a schedule. Re-check error and null rates as the source data changes, and retune the rules.
What do governance, security and cost look like?
Treat an imputed value as a derived fact, not an observed one. Keep the original null, add an indicator column, and store the method and run identifier so any model score can be traced back. Databricks describes Unity Gateway as governing access to models, MCP servers and skills with guardrails, rate limits and usage tracking, which covers the agent's own tool access. On cost, statistical imputation is a single pass over the data, while model-based methods add training time per column, so the rule table also acts as a spending control.
Beyond the Databricks controls, a decision layer such as ElixirData Context OS keeps governed context, versioned policy and decision traces in one place above AI agents, and the ElixirData Audit Agent gathers decision histories, policy versions, approvals and accountability records so compliance teams do not have to rebuild evidence by hand. To orchestrate such agents with humans in control, see ElixirClaw, an agentic OS platform to build, orchestrate and govern AI agents and automation workflows while keeping humans in control.
When should you not impute?
| Situation | Why imputation is risky | Better option |
|---|---|---|
| Suspected MNAR column | The gap depends on the missing value itself, so any estimate is biased | Collect the data, or model the missingness explicitly with a specialist |
Categorical column with the Spark Imputer | Not supported; may produce incorrect values | Use a mode rule in your own step, or add an "unknown" category |
| Legal or audit records | An estimated value can be mistaken for a fact | Leave null and flag it |
| Very high null rate | Little observed signal to infer from | Fix the source or drop the column, with sign-off |
What has changed on Databricks recently?
The documentation now frames agent work around Agent Bricks, with MLflow tracing and evaluation built in, and recommends MLflow ResponsesAgent for authoring agents. Data monitoring is documented under the heading data quality monitoring, with the feature titled data profiling. Check the current pages before you design against older names.
To map one imputation decision your agents should make, and the context and policy it depends on, book a Context Workshop. See what happens in the workshop.
Frequently asked questions
What is missing data imputation?
It is the practice of inferring missing values from the known part of a dataset instead of discarding incomplete rows or columns.
Does the Spark ML Imputer handle categorical columns?
No. The Apache Spark documentation says input columns should be numeric and that categorical features are not supported and may produce incorrect values.
How do I know whether data is MAR or MNAR?
You cannot fully tell from the data alone. The only true way to distinguish them is to measure some of the missing data, so suspected MNAR columns should go to a data owner.
What should an AI agent log when it imputes?
The method, the columns, an indicator showing which values were filled, the validation error and a trace of the run. Databricks MLflow Tracing records each step an agent takes.
Is there a ready-made Databricks agent for imputation?
We found no Databricks documentation page for one. Databricks documents Agent Bricks for building your own agents, so imputation logic is something your team defines and governs.
Follow XenonStack on LinkedIn: XenonStack on LinkedIn for new guides on agentic AI, data and platform engineering.
Explore the XenonStack platform family: ElixirData · ElixirClaw · ElixirHub · NexaStack · MetaSecure · Neural AI · AgentGRC · AgentSRE · AgentAnalyst · AgentInstruct · AgentRAI · AgentScrum · AgentSearch · AgentForce · AI Aviator · SAIF Aviator · CohortIQ · XenonStack AI · XenonStack UAE